mirror of
https://github.com/felt/tippecanoe.git
synced 2026-11-22 16:31:18 +01:00
Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Ryan Clark |
a888304b19 | ||
|
|
4f2621186a | ||
|
Erica FischerandClaude Opus 5
|
63fcac725a | ||
|
Erica FischerandClaude Opus 5
|
734bba7c78 | ||
|
Erica FischerandClaude Opus 5
|
1820630392 | ||
|
Erica FischerandClaude Opus 5
|
905fe84459 | ||
|
Erica FischerandClaude Opus 5
|
ec727172b1 | ||
|
Erica FischerandClaude Opus 5
|
e6e1ec3263 | ||
|
Brandon Keepers
|
1b060b7faf | ||
|
KBS
|
7c80fccdc1 | ||
|
Brandon Keepers
|
0badb242be | ||
|
Brandon Keepers
|
0dc1e00eee | ||
|
Denis Stadnikovanddstadnikov
|
0c650b881a | ||
|
Bas Couwenberg
|
7fc82a1796 | ||
|
Shane Loeffler
|
cb6cacef15 | ||
|
Shane Loeffler
|
eb9acf9d44 | ||
|
Stefan Keimandindus
|
a5805bd809 | ||
|
James Scott-Brown
|
d7b2892f98 | ||
|
Mike Jones
|
c82e4beee3 | ||
|
Erica Fischer
|
9a7ac5733f | ||
|
Erica Fischer
|
533e000faa | ||
|
Erica Fischer
|
68ab8dcc22 | ||
|
Drew Good
|
6dd49be6c9 | ||
|
Drew Good
|
c2a973d8f6 | ||
|
Drew Good
|
8ac730718a | ||
|
Erica Fischer
|
2d548bed06 | ||
|
Erica Fischer
|
94929b048c | ||
|
Erica Fischer
|
bfb62ee2db | ||
|
Robert Martin
|
a0532e73ac | ||
|
Denis Govorkov
|
9d1637f7c1 | ||
|
cbobinec
|
de4e1e478f | ||
|
Erica Fischer
|
423fea1544 | ||
|
Erica Fischer
|
583fc3744a | ||
|
Ryan Mast
|
390c362452 |
@@ -7,7 +7,7 @@ jobs:
|
||||
runs-on: ${{ matrix.os }}
|
||||
strategy:
|
||||
matrix:
|
||||
os: [ubuntu-latest, macos-latest]
|
||||
os: [ubuntu-latest, ubuntu-24.04-arm, macos-latest]
|
||||
version: ['Release', 'Debug']
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
@@ -19,3 +19,20 @@ jobs:
|
||||
run: brew install sqlite3
|
||||
- run: uname -a; BUILDTYPE=${{ matrix.version }} make
|
||||
- run: make test
|
||||
|
||||
docs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
# Pinned, because different go-md2man versions produce different roff
|
||||
# for the same input, which would make this check fail spuriously.
|
||||
- name: Install go-md2man
|
||||
run: go install github.com/cpuguy83/go-md2man/v2@v2.0.7
|
||||
- name: Regenerate the man page
|
||||
run: PATH="$PATH:$(go env GOPATH)/bin" make -B docs
|
||||
- name: Check that the man page is up to date with README.md
|
||||
run: |
|
||||
git diff --exit-code man/tippecanoe.1 || {
|
||||
echo "::error::man/tippecanoe.1 is out of date. Run 'make docs' and commit the result."
|
||||
exit 1
|
||||
}
|
||||
|
||||
@@ -38,6 +38,9 @@ tippecanoe-json-tool
|
||||
tippecanoe-overzoom
|
||||
unit
|
||||
|
||||
# Left behind if man page generation fails
|
||||
man/tippecanoe.1.tmp
|
||||
|
||||
# Tests
|
||||
tests/**/*.mbtiles
|
||||
tests/**/*.check
|
||||
|
||||
-110
@@ -1,110 +0,0 @@
|
||||
language: node_js
|
||||
node_js:
|
||||
- "6"
|
||||
|
||||
sudo: false
|
||||
|
||||
matrix:
|
||||
include:
|
||||
# test on docker+centos7
|
||||
- os: linux
|
||||
compiler: clang
|
||||
services:
|
||||
- docker
|
||||
sudo: true
|
||||
dist: trusty
|
||||
env: DOCKERFILE=Dockerfile.centos7
|
||||
before_install: []
|
||||
install:
|
||||
- docker build -t tippecanoe-image -f ${DOCKERFILE} .
|
||||
script:
|
||||
- docker run -it tippecanoe-image
|
||||
# test on docker+ubuntu
|
||||
- os: linux
|
||||
compiler: clang
|
||||
services:
|
||||
- docker
|
||||
sudo: true
|
||||
dist: trusty
|
||||
env: DOCKERFILE=Dockerfile
|
||||
before_install: []
|
||||
install:
|
||||
- docker build -t tippecanoe-image -f ${DOCKERFILE} .
|
||||
script:
|
||||
- docker run -it tippecanoe-image
|
||||
# debug+integer-santizer build
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Debug CC="clang-3.8" CXX="clang++-3.8" CXXFLAGS="-fsanitize=integer" CFLAGS="-fsanitize=integer" LDFLAGS="-fsanitize=integer"
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# debug+leak+address-sanitizer build
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Debug ASAN_OPTIONS=detect_leaks=1 CC="clang-3.8" CXX="clang++-3.8" CXXFLAGS="-fsanitize=address,undefined" CFLAGS="-fsanitize=address,undefined" LDFLAGS="-fsanitize=address,undefined" FEWER=true
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# coverage+debug build
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Debug CC="clang-3.8" CXX="clang++-3.8" CXXFLAGS="--coverage" CFLAGS="--coverage" LDFLAGS="--coverage"
|
||||
after_script:
|
||||
- mason install llvm-cov 3.9.1
|
||||
- mason link llvm-cov 3.9.1
|
||||
- which llvm-cov
|
||||
- curl -S -f https://codecov.io/bash -o codecov
|
||||
- chmod +x codecov
|
||||
- ./codecov -x "llvm-cov gcov" -Z
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# release+linux+g++
|
||||
- os: linux
|
||||
compiler: gcc
|
||||
env: BUILDTYPE=Release CC="gcc-4.9" CXX="g++-4.9"
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test']
|
||||
packages: [ 'g++-4.9' ]
|
||||
# release+linux+clang++
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Release CC="clang-3.8" CXX="clang++-3.8"
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# release+osx
|
||||
- os: osx
|
||||
compiler: clang
|
||||
env: BUILDTYPE=Release
|
||||
# debug+osx
|
||||
- os: osx
|
||||
compiler: clang
|
||||
env: BUILDTYPE=Debug
|
||||
|
||||
before_install:
|
||||
- DEPS_DIR="${TRAVIS_BUILD_DIR}/deps"
|
||||
- export PATH=${DEPS_DIR}/bin:${PATH} && mkdir -p ${DEPS_DIR}
|
||||
- |
|
||||
if [[ ${CLANG_VERSION:-false} != false ]]; then
|
||||
export CCOMPILER='clang'
|
||||
export CXXCOMPILER='clang++'
|
||||
CLANG_URL="https://mason-binaries.s3.amazonaws.com/${TRAVIS_OS_NAME}-x86_64/clang/${CLANG_VERSION}.tar.gz"
|
||||
travis_retry wget --quiet -O - ${CLANG_URL} | tar --strip-components=1 -xz -C ${DEPS_DIR}
|
||||
fi
|
||||
|
||||
install:
|
||||
- BUILDTYPE=${BUILDTYPE} make -j
|
||||
|
||||
script:
|
||||
- npm install geobuf
|
||||
- if [ -n "${FEWER}" ]; then
|
||||
BUILDTYPE=${BUILDTYPE} make fewer-tests; else
|
||||
BUILDTYPE=${BUILDTYPE} make test geobuf-test;
|
||||
fi
|
||||
+139
@@ -1,3 +1,142 @@
|
||||
# 2.82.0
|
||||
|
||||
* Fix corruption of a JSON array when a non-final element was removed from it.
|
||||
The old `json_free` / `json_disconnect` passed an element count to `memmove`
|
||||
where a byte count was required, so pruning element 0 of an 8-element array
|
||||
left the first two slots pointing at the same node -- a double free at
|
||||
teardown -- and silently dropped the last element. Only reachable through a
|
||||
whole-document tree, because removing the most recently added element made
|
||||
the bad `memmove` a zero-length no-op. (#388)
|
||||
* Rewrite `jsonpull` in C++ with `unique_ptr` ownership, `std::vector` for
|
||||
arrays and hash entries, and `std::string` for string values, replacing the
|
||||
hand-rolled `malloc`/`realloc`/`free` memory management. Value payloads now
|
||||
live in type-tagged subclasses reached through asserting accessors, so
|
||||
reading a hash as a string fails immediately instead of silently returning
|
||||
garbage. (#388)
|
||||
* Fix `tippecanoe-json-tool --extract` crashing on a numeric attribute, which
|
||||
read the number's storage as a string pointer. (#388)
|
||||
* Fix decoding of a `\u` escape sequence in which a high surrogate is followed
|
||||
by a non-surrogate BMP code point, which combined the two into a single
|
||||
wrong code point. (#388)
|
||||
* Fix a `\uFFFF` escape being decoded to the overlong, invalid four-byte
|
||||
UTF-8 sequence `F0 8F BF BF` instead of `EF BF BF`. (#388)
|
||||
* Fix tile-join reading a non-string field type out of a tileset's tilejson.
|
||||
(#388)
|
||||
* Fix `tippecanoe-decode` and tile-join crashing on a directory tileset whose
|
||||
`metadata.json` holds a non-string value, such as a numeric `minzoom` or a
|
||||
nested object. Those entries are now reported and skipped. (#388)
|
||||
* Fix an uninitialized read when a prefilter or postfilter emitted a feature
|
||||
with `"properties": null`. Both filter readers accepted a null `properties`
|
||||
and then read its length as though it were a hash, which was never
|
||||
initialized for a non-container node. (#388)
|
||||
* Fix the include guard in `evaluator.hpp`, which defined `EVALUATOR HPP`
|
||||
instead of `EVALUATOR_HPP` and so never guarded anything. (#388)
|
||||
|
||||
# 2.81.0
|
||||
|
||||
* Add `--drop-by-attribute-as-needed=`*attribute* to drop the features with
|
||||
the lowest values of a numeric attribute from oversized tiles, and
|
||||
`--drop-by-attribute-order=desc` to drop the highest values instead.
|
||||
Features exactly at the threshold are kept rather than dropped. (#384, #385)
|
||||
* Add `--exclude-all-tile-geometries` to tile-join, to produce tiles that
|
||||
carry only attributes. (#382)
|
||||
* Generate each tool's usage message from the same option table that
|
||||
`getopt_long()` reads, so the hand-written lists in tile-join,
|
||||
tippecanoe-overzoom, tippecanoe-json-tool, tippecanoe-decode, and
|
||||
tippecanoe-enumerate can no longer fall behind the options actually
|
||||
accepted. Options previously reachable only by their short names are now
|
||||
listed. tippecanoe-overzoom reports a missing `-o` instead of passing a
|
||||
null pointer to `fopen()`, and tippecanoe prints its usage when run with
|
||||
no arguments. (#409)
|
||||
* Fix the radix sort used by `--prefer-radix-sort`. A bucket written out
|
||||
directly rather than through the merge was written one byte longer than
|
||||
its length prefix claimed, desynchronizing everything read from the
|
||||
geometry after it. Subdividing could also recurse forever once it ran out
|
||||
of files to split with, shifting by the full width of the index and
|
||||
writing past the end of the arrays of buckets. Radix-sorted output is now
|
||||
checked against the in-memory sort rather than against a stored copy. (#404)
|
||||
* Read FlatGeobuf integer and float properties as numbers. They were tagged
|
||||
with types that the rest of tippecanoe does not treat as numeric, so they
|
||||
were reported in tilestats as "mixed", with quoted values and no min or
|
||||
max, and warned when used as a feature ID. ULong properties are now also
|
||||
read as unsigned rather than signed. (#395)
|
||||
* Respect the `-t` temporary directory option in sorting operations, which
|
||||
previously always used the system temporary directory. (#368)
|
||||
* Keep `--generate-variable-depth-tile-pyramid` from silently dropping
|
||||
features whose explicit per-feature `minzoom` is deeper than the zoom at
|
||||
which their region becomes a leaf. Such a feature was excluded from the
|
||||
leaf tile while its children were never generated, so it appeared at no
|
||||
zoom at all. (#397, #399)
|
||||
* Drop a polygon hole that no remaining ring can parent, instead of failing
|
||||
the whole run. Degenerate input could abort tiling over a single
|
||||
unrepresentable sliver. (#401)
|
||||
* Clamp the feature extent to the `long long` range before converting it,
|
||||
at both ends. The previous `extent <= LLONG_MAX` guard was doubly wrong:
|
||||
`LLONG_MAX` is not representable as a double and rounds up, so an extent
|
||||
at the very top of the range overflowed the conversion and came out as the
|
||||
most negative value rather than the largest, and the guard admitted
|
||||
everything below `LLONG_MIN` as well, which overflowed the other way. Areas
|
||||
are signed, so holes that outweigh their rings can reach the low end. (#406)
|
||||
* Initialize the full width of the `mvt_value` numeric union, which left the
|
||||
bytes of the wider unused member indeterminate even though the implicit
|
||||
copy constructor copies the union as a whole. (#406)
|
||||
* Replace all variable-length arrays with `std::vector` and `std::string`,
|
||||
and build with `-Wvla`. VLAs are a compiler extension rather than standard
|
||||
C++, and clang warns about every one of them by default. (#406)
|
||||
* Remove the unused Dockerfiles, Travis configuration, and lambda
|
||||
directory. (#365)
|
||||
* Correct README statements that disagreed with the code. Among them, `-aD`
|
||||
and `-aS` were documented the wrong way round,
|
||||
`--limit-base-zoom-to-maximum-zoom` was given as `-Pb` rather than `-pb`,
|
||||
and the dot-dropping description had both the fraction and the zoom
|
||||
direction backwards: tippecanoe keeps 1/2.5 of the dots at zooms below the
|
||||
base zoom, rather than dropping that share above it. (#410)
|
||||
* Generate `man/tippecanoe.1` with go-md2man rather than md2man-roff, which
|
||||
is packaged only as a Ruby gem and so had let the page drift out of date.
|
||||
The page now has a proper header and a NAME section, so `man -k` and
|
||||
`whatis` can find it, and no longer silently drops or mangles text the old
|
||||
converter mishandled. CI checks it against README.md. (#408)
|
||||
* Documentation fixes: correct three misspellings in the README and man
|
||||
page, repair the dead All Streets link, and tag more README code blocks
|
||||
with their language. (#375, #391, #400)
|
||||
|
||||
# 2.80.0
|
||||
|
||||
* Remove undocumented command-line options
|
||||
|
||||
# 2.79.0
|
||||
|
||||
* When deduplicating features by ID in tippecanoe-overzoom, be careful
|
||||
to track even features that have been clipped away.
|
||||
|
||||
# 2.78.0
|
||||
|
||||
* Fix potential infinite loops in as-needed dropping and coalescing.
|
||||
When the threshold cannot be increased, it is now an error, rather than
|
||||
falling back to trying to lower the detail.
|
||||
* Cleaning of complex polygon geometries now happens in stages
|
||||
to avoid performance problems when there are very large numbers
|
||||
of vertices.
|
||||
* Label point generation happens earlier in tiling, to avoid doing slow
|
||||
operations on polygons that will not be retained anyway.
|
||||
|
||||
# 2.77.0
|
||||
|
||||
* Add --deduplicate-by-id option to tippecanoe-overzoom
|
||||
|
||||
# 2.76.0
|
||||
|
||||
* Add missing case for accumulating the mean of attributes that are inconsistently present
|
||||
* Add --keep-point-cluster-position (#326)
|
||||
|
||||
# 2.75.1
|
||||
|
||||
* Further reduce memory consumption in attribute sorting and tilestats tracking
|
||||
|
||||
# 2.75.0
|
||||
|
||||
* Reduce memory consumption in attribute accumulation and feature sorting
|
||||
|
||||
# 2.74.0
|
||||
|
||||
* Add the option to join attributes from a sqlite database in tile-join
|
||||
|
||||
-20
@@ -1,20 +0,0 @@
|
||||
FROM ubuntu:22.04 AS tippecanoe-builder
|
||||
|
||||
RUN apt-get update \
|
||||
&& apt-get -y install make gcc g++ libsqlite3-dev zlib1g-dev
|
||||
|
||||
COPY . /tmp/tippecanoe-src
|
||||
WORKDIR /tmp/tippecanoe-src
|
||||
|
||||
RUN make
|
||||
|
||||
CMD make test
|
||||
|
||||
# Using multistage build reduces the docker image size by alot by only copying the needed binaries
|
||||
FROM ubuntu:22.04
|
||||
RUN apt-get update \
|
||||
&& apt-get -y install libsqlite3-0 \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
COPY --from=tippecanoe-builder /tmp/tippecanoe-src/tippecanoe* /usr/local/bin/
|
||||
COPY --from=tippecanoe-builder /tmp/tippecanoe-src/tile-join /usr/local/bin/
|
||||
WORKDIR /app
|
||||
@@ -1,15 +0,0 @@
|
||||
FROM centos:centos8
|
||||
|
||||
RUN yum install -y make sqlite-devel zlib-devel bash git gcc-c++
|
||||
|
||||
# Create a directory and copy in all files
|
||||
RUN mkdir -p /tmp/tippecanoe-src
|
||||
WORKDIR /tmp/tippecanoe-src
|
||||
COPY . /tmp/tippecanoe-src
|
||||
|
||||
# Build tippecanoe
|
||||
RUN make \
|
||||
&& make install
|
||||
|
||||
# Run the tests
|
||||
CMD make test
|
||||
+5
-5
@@ -1,19 +1,19 @@
|
||||
## [Visualizing a Month of Lightning](http://rousseau.io/2015/03/23/visualizing-a-month-of-lightning) by Jordan Rousseau
|
||||
## [Visualizing a Month of Lightning](https://medium.com/@jvrousseau/visualizing-a-month-of-lightning-8ab63d040d8c) by Jordan Rousseau
|
||||
|
||||

|
||||
|
||||
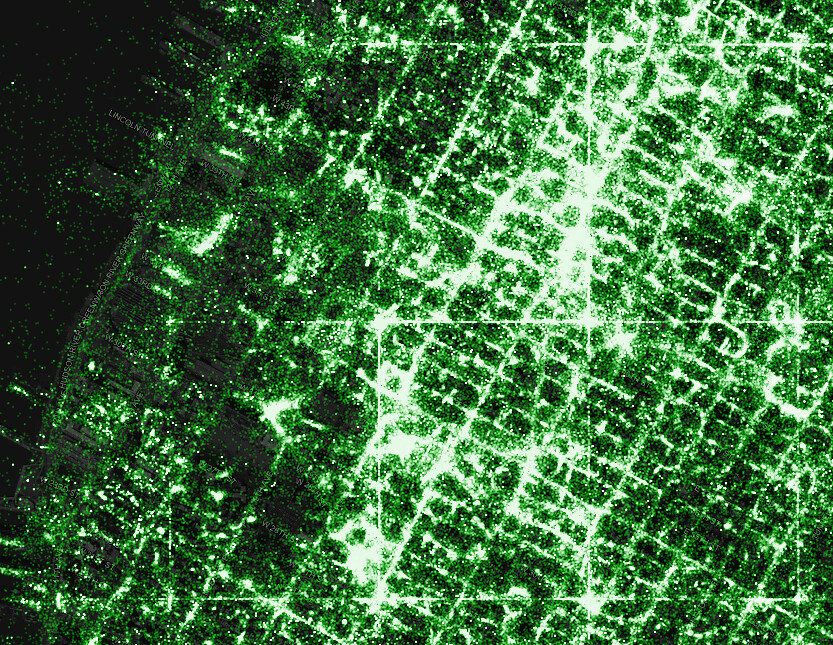
## [Making the most detailed tweet map ever](https://www.mapbox.com/blog/twitter-map-every-tweet/) by Eric Fischer
|
||||
## [Making the most detailed tweet map ever](https://web.archive.org/web/20161220144946/https://www.mapbox.com/blog/twitter-map-every-tweet/) by Eric Fischer
|
||||
|
||||
|
||||
|
||||
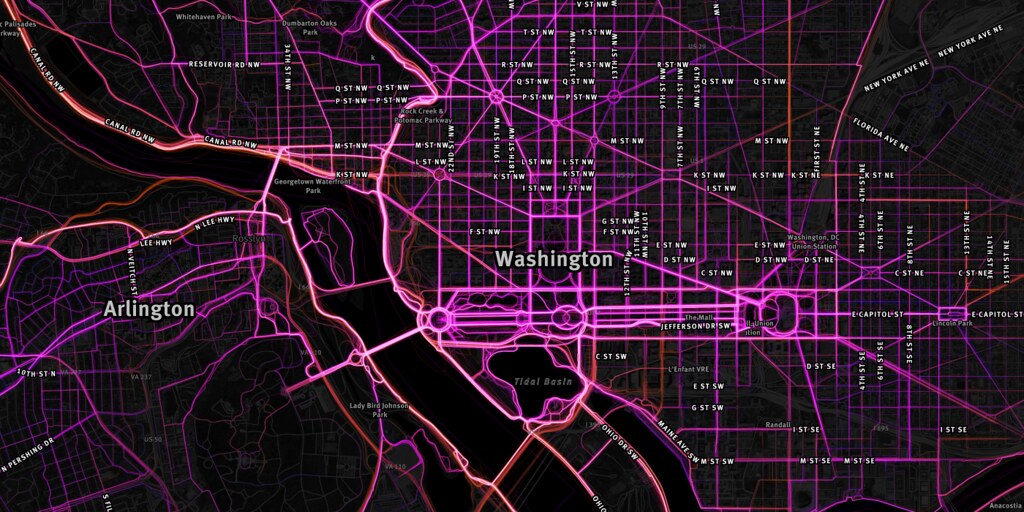
## [Superpowering Runkeeper's 1.5 million walks, runs, and bike rides](https://www.mapbox.com/blog/runkeeper-million-routes/)
|
||||
## [Superpowering Runkeeper's 1.5 million walks, runs, and bike rides](https://web.archive.org/web/20161219225305/https://www.mapbox.com/blog/runkeeper-million-routes/)
|
||||
|
||||
|
||||
|
||||
## [The Geotaggers' World Atlas](https://www.mapbox.com/blog/geotaggers-world-atlas/) by Eric Fischer
|
||||
## [The Geotaggers' World Atlas](https://web.archive.org/web/20170319084321/https://www.mapbox.com/blog/geotaggers-world-atlas/) by Eric Fischer
|
||||
|
||||

|
||||
|
||||
## [Atmospheric River](https://www.mapbox.com/blog/atmospheric-river/)
|
||||
## [Atmospheric River](https://web.archive.org/web/20161011171030/https://www.mapbox.com/blog/atmospheric-river/)
|
||||
|
||||

|
||||
|
||||
@@ -11,7 +11,7 @@ CXX := $(CXX)
|
||||
CFLAGS := $(CFLAGS) -fPIE -DBUILD_INFO=$(BUILD_INFO)
|
||||
CXXFLAGS := $(CXXFLAGS) -std=c++17 -fPIE -DBUILD_INFO=$(BUILD_INFO)
|
||||
LDFLAGS := $(LDFLAGS)
|
||||
WARNING_FLAGS := -Wall -Wshadow -Wsign-compare -Wextra -Wunreachable-code -Wuninitialized -Wshadow
|
||||
WARNING_FLAGS := -Wall -Wshadow -Wsign-compare -Wextra -Wunreachable-code -Wuninitialized -Wshadow -Wvla
|
||||
RELEASE_FLAGS := -O3 -DNDEBUG
|
||||
DEBUG_FLAGS := -O0 -DDEBUG -fno-inline-functions -fno-omit-frame-pointer
|
||||
|
||||
@@ -48,8 +48,44 @@ install: tippecanoe tippecanoe-enumerate tippecanoe-decode tile-join tippecanoe-
|
||||
uninstall:
|
||||
rm $(PREFIX)/bin/tippecanoe $(PREFIX)/bin/tippecanoe-enumerate $(PREFIX)/bin/tippecanoe-decode $(PREFIX)/bin/tile-join $(MANDIR)/tippecanoe.1 $(PREFIX)/bin/tippecanoe-json-tool
|
||||
|
||||
# The man page is generated from README.md by go-md2man, which is packaged for
|
||||
# most systems (`brew install go-md2man`, `apt-get install go-md2man`) or can be
|
||||
# built with `go install github.com/cpuguy83/go-md2man/v2@v2.0.7`. CI checks that
|
||||
# the committed man page matches the README, so you don't have to regenerate it
|
||||
# yourself if you don't have go-md2man installed.
|
||||
#
|
||||
# README.md has no .TH or NAME section of its own, since neither would make sense
|
||||
# on GitHub, so prepend them here. go-md2man reads the leading "%" line as the
|
||||
# man page's title, section, date, and source. The version deliberately doesn't
|
||||
# appear there: it would make this page a build product of version.hpp, so every
|
||||
# release would have to regenerate it just to rewrite that one line, and the docs
|
||||
# CI job would fail on any version bump that forgot to.
|
||||
#
|
||||
# Two fixups on the way out:
|
||||
#
|
||||
# - README.md's own title heading becomes the second .SH, right below the NAME
|
||||
# section added above, which reads as a stray "tippecanoe" section. Rename it
|
||||
# to DESCRIPTION, where the text under it belongs anyway.
|
||||
# - go-md2man separates paragraphs with a blank line in addition to the .PP
|
||||
# macro, and a blank line is itself a break in roff, so the two together
|
||||
# double-space the whole page. Drop them, except within .EX and .TS blocks,
|
||||
# where a blank line is part of the example or table rather than spacing.
|
||||
man/tippecanoe.1: README.md
|
||||
md2man-roff README.md > man/tippecanoe.1
|
||||
{ \
|
||||
echo '% TIPPECANOE 1 "" "tippecanoe"'; \
|
||||
echo; \
|
||||
echo '# NAME'; \
|
||||
echo; \
|
||||
echo 'tippecanoe - build vector tilesets from GeoJSON, FlatGeobuf, or CSV features'; \
|
||||
echo; \
|
||||
cat README.md; \
|
||||
} | go-md2man \
|
||||
| awk ' \
|
||||
/^\.SH / && ++sh == 2 { print ".SH DESCRIPTION"; next } \
|
||||
/^\.(EX|TS)$$/ { lit = 1 } \
|
||||
/^\.(EE|TE)$$/ { lit = 0 } \
|
||||
lit || !/^$$/ \
|
||||
' > $@.tmp && mv $@.tmp $@
|
||||
|
||||
PG=
|
||||
|
||||
@@ -59,25 +95,25 @@ C = $(wildcard *.c) $(wildcard *.cpp)
|
||||
INCLUDES = -I/usr/local/include -I. -Iclipper2/include
|
||||
LIBS = -L/usr/local/lib
|
||||
|
||||
tippecanoe: geojson.o jsonpull/jsonpull.o tile.o pool.o mbtiles.o geometry.o projection.o memfile.o mvt.o serial.o main.o platform.o text.o dirtiles.o pmtiles_file.o plugin.o read_json.o write_json.o geobuf.o flatgeobuf.o evaluator.o geocsv.o csv.o geojson-loop.o json_logger.o visvalingam.o compression.o clip.o sort.o attribute.o thread.o shared_borders.o clipper2/src/clipper.engine.o
|
||||
tippecanoe: geojson.o jsonpull/jsonpull.o tile.o pool.o mbtiles.o geometry.o projection.o memfile.o mvt.o serial.o main.o platform.o text.o dirtiles.o pmtiles_file.o plugin.o read_json.o write_json.o geobuf.o flatgeobuf.o evaluator.o geocsv.o csv.o geojson-loop.o json_logger.o visvalingam.o compression.o clip.o sort.o attribute.o thread.o shared_borders.o usage.o clipper2/src/clipper.engine.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lm -lz -lsqlite3 -lpthread
|
||||
|
||||
tippecanoe-enumerate: enumerate.o
|
||||
tippecanoe-enumerate: enumerate.o usage.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lsqlite3
|
||||
|
||||
tippecanoe-decode: decode.o projection.o mvt.o write_json.o text.o jsonpull/jsonpull.o dirtiles.o pmtiles_file.o
|
||||
tippecanoe-decode: decode.o projection.o mvt.o write_json.o text.o jsonpull/jsonpull.o dirtiles.o pmtiles_file.o usage.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lm -lz -lsqlite3
|
||||
|
||||
tile-join: tile-join.o platform.o projection.o mbtiles.o mvt.o memfile.o dirtiles.o jsonpull/jsonpull.o text.o evaluator.o csv.o write_json.o pmtiles_file.o clip.o attribute.o thread.o read_json.o clipper2/src/clipper.engine.o
|
||||
tile-join: tile-join.o platform.o projection.o mbtiles.o mvt.o memfile.o dirtiles.o jsonpull/jsonpull.o text.o evaluator.o csv.o write_json.o pmtiles_file.o clip.o attribute.o thread.o read_json.o usage.o clipper2/src/clipper.engine.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lm -lz -lsqlite3 -lpthread
|
||||
|
||||
tippecanoe-json-tool: jsontool.o jsonpull/jsonpull.o csv.o text.o geojson-loop.o
|
||||
tippecanoe-json-tool: jsontool.o jsonpull/jsonpull.o csv.o text.o geojson-loop.o usage.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lm -lz -lsqlite3 -lpthread
|
||||
|
||||
unit: unit.o text.o sort.o mvt.o projection.o clip.o attribute.o jsonpull/jsonpull.o evaluator.o read_json.o clipper2/src/clipper.engine.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lm -lz -lsqlite3 -lpthread
|
||||
|
||||
tippecanoe-overzoom: overzoom.o mvt.o clip.o evaluator.o jsonpull/jsonpull.o text.o attribute.o read_json.o projection.o read_json.o clipper2/src/clipper.engine.o
|
||||
tippecanoe-overzoom: overzoom.o mvt.o clip.o evaluator.o jsonpull/jsonpull.o text.o attribute.o read_json.o projection.o read_json.o usage.o clipper2/src/clipper.engine.o
|
||||
$(CXX) $(PG) $(LIBS) $(FINAL_FLAGS) $(CXXFLAGS) -o $@ $^ $(LDFLAGS) -lm -lz -lsqlite3 -lpthread
|
||||
|
||||
-include $(wildcard *.d)
|
||||
@@ -92,12 +128,12 @@ clean:
|
||||
rm -f ./tippecanoe ./tippecanoe-* ./tile-join ./unit *.o *.d */*.o */*.d tests/**/*.mbtiles tests/**/*.check
|
||||
|
||||
indent:
|
||||
clang-format -i -style="{BasedOnStyle: Google, IndentWidth: 8, UseTab: Always, AllowShortIfStatementsOnASingleLine: false, ColumnLimit: 0, ContinuationIndentWidth: 8, SpaceAfterCStyleCast: true, IndentCaseLabels: false, AllowShortBlocksOnASingleLine: false, AllowShortFunctionsOnASingleLine: false, SortIncludes: false}" $(filter-out flatgeobuf.cpp,$(C)) $(H) jsonpull/*.[ch]
|
||||
clang-format -i -style="{BasedOnStyle: Google, IndentWidth: 8, UseTab: Always, AllowShortIfStatementsOnASingleLine: false, ColumnLimit: 0, ContinuationIndentWidth: 8, SpaceAfterCStyleCast: true, IndentCaseLabels: false, AllowShortBlocksOnASingleLine: false, AllowShortFunctionsOnASingleLine: false, SortIncludes: false}" $(filter-out flatgeobuf.cpp,$(C)) $(H) jsonpull/jsonpull.h jsonpull/jsonpull.cpp
|
||||
|
||||
TESTS = $(wildcard tests/*/out/*.json)
|
||||
SPACE = $(NULL) $(NULL)
|
||||
|
||||
test: tippecanoe tippecanoe-decode $(addsuffix .check,$(TESTS)) raw-tiles-test parallel-test pbf-test join-test enumerate-test decode-test join-filter-test unit json-tool-test allow-existing-test csv-test layer-json-test pmtiles-test decode-pmtiles-test overzoom-test accumulate-test
|
||||
test: tippecanoe tippecanoe-decode $(addsuffix .check,$(TESTS)) raw-tiles-test parallel-test radix-sort-test pbf-test join-test enumerate-test decode-test join-filter-test unit json-tool-test allow-existing-test csv-test layer-json-test pmtiles-test decode-pmtiles-test overzoom-test flatgeobuf-test
|
||||
./unit
|
||||
|
||||
suffixes = json json.gz
|
||||
@@ -108,6 +144,7 @@ suffixes = json json.gz
|
||||
# %22 for quoted quote
|
||||
# %2f for /
|
||||
# %3a for :
|
||||
# %3d for =
|
||||
# %5f for _
|
||||
# %7b for {
|
||||
|
||||
@@ -115,10 +152,11 @@ testargs = \
|
||||
$(subst %20,' ',\
|
||||
$(subst %22,'"',\
|
||||
$(subst %3a,:,\
|
||||
$(subst %2f,/,\
|
||||
$(subst %7b,'{',\
|
||||
$(subst %5f,'_',\
|
||||
$(subst _, ,$(1))))))))
|
||||
$(subst %3d,=,\
|
||||
$(subst %2f,/,\
|
||||
$(subst %7b,'{',\
|
||||
$(subst %5f,'_',\
|
||||
$(subst _, ,$(1)))))))))
|
||||
|
||||
%.json.check:
|
||||
./tippecanoe -q -a@ -f -o $@.mbtiles $(call testargs,$(patsubst %.json.check,%,$(word 4,$(subst /, ,$@)))) $(foreach suffix,$(suffixes),$(sort $(wildcard $(subst $(SPACE),/,$(wordlist 1,2,$(subst /, ,$@)))/*.$(suffix)))) < /dev/null
|
||||
@@ -132,7 +170,7 @@ nogeobuf = tests/overflow/out/-z0.json $(wildcard tests/stringid/out/*.json)
|
||||
geobuf-test: tippecanoe-json-tool $(addsuffix .checkbuf,$(filter-out $(nogeobuf),$(TESTS)))
|
||||
|
||||
# For quicker address sanitizer build, hope that regular JSON parsing is tested enough by parallel and join tests
|
||||
fewer-tests: tippecanoe tippecanoe-decode geobuf-test raw-tiles-test parallel-test pbf-test join-test enumerate-test decode-test join-filter-test unit
|
||||
fewer-tests: tippecanoe tippecanoe-decode geobuf-test raw-tiles-test parallel-test radix-sort-test pbf-test join-test enumerate-test decode-test join-filter-test unit
|
||||
|
||||
# XXX Use proper makefile rules instead of a for loop
|
||||
%.json.checkbuf:
|
||||
@@ -143,6 +181,42 @@ fewer-tests: tippecanoe tippecanoe-decode geobuf-test raw-tiles-test parallel-te
|
||||
cmp $@.out $(patsubst %.checkbuf,%,$@)
|
||||
rm $@.out $@.mbtiles
|
||||
|
||||
# The result of the sort must not depend on how the sort was performed, so instead of
|
||||
# checking the sorted output against an expected copy of it, check that sorting by radix
|
||||
# produces the same tiles as sorting in memory. --prefer-radix-sort lowers the memory
|
||||
# limit to 8K, which radix() then halves again, so the radix subdivision has to recurse
|
||||
# until each bucket is under 4K. How deeply that recurses depends on how many files the
|
||||
# machine will let us open at once, but the sorted result is the same either way, so
|
||||
# this comparison doesn't depend on that.
|
||||
#
|
||||
# What sends the sort down its rarely-taken paths is the shape of the input rather than
|
||||
# the size of it: a feature whose geometry alone is bigger than the memory limit is
|
||||
# sorted as a bucket of its own, and features that share a long run of leading index
|
||||
# bits have to be subdivided until there are no bits left. The first two inputs are
|
||||
# each one of those on purpose -- several separated features too big to sort in memory,
|
||||
# and many features at one location -- and the rest are for breadth.
|
||||
radix-sort-test: tippecanoe tippecanoe-decode
|
||||
mkdir -p tests/radix-sort
|
||||
perl -e 'for ($$f = 0; $$f < 8; $$f++) { print "{ \"type\": \"Feature\", \"properties\": { \"f\": $$f }, \"geometry\": { \"type\": \"LineString\", \"coordinates\": ["; for ($$i = 0; $$i < 2000; $$i++) { print "," unless $$i == 0; printf "[%f,%f]", $$f * 40 - 175 + $$i * 0.001, $$i % 2 * 0.5 - 20; } print "] } }\n"; }' > tests/radix-sort/bigfeatures.json
|
||||
perl -e 'for ($$i = 0; $$i < 500; $$i++) { print "{ \"type\": \"Feature\", \"properties\": { \"i\": $$i }, \"geometry\": { \"type\": \"Point\", \"coordinates\": [ 17, 42 ] } }\n"; }' > tests/radix-sort/onelocation.json
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/radix-sort/bigfeatures.json" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/radix-sort/onelocation.json" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/feature-filter/in.json" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/ne_110m_ocean/in.json" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/border/in.json" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/loop/in.json" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/tl_2022_11_tract/in.json.gz" RADIXARGS="-z4"
|
||||
$(MAKE) radix-sort-compare RADIXIN="tests/epsg-3857/in.json" RADIXARGS="-z4 -sEPSG:3857"
|
||||
rm -r tests/radix-sort
|
||||
|
||||
radix-sort-compare:
|
||||
./tippecanoe -q -f $(RADIXARGS) -o tests/radix-sort/memory.mbtiles $(RADIXIN)
|
||||
./tippecanoe -q -f $(RADIXARGS) -aR -o tests/radix-sort/radix.mbtiles $(RADIXIN)
|
||||
./tippecanoe-decode -x generator -x generator_options -x name -x description tests/radix-sort/memory.mbtiles > tests/radix-sort/memory.json
|
||||
./tippecanoe-decode -x generator -x generator_options -x name -x description tests/radix-sort/radix.mbtiles > tests/radix-sort/radix.json
|
||||
cmp tests/radix-sort/memory.json tests/radix-sort/radix.json
|
||||
rm tests/radix-sort/memory.mbtiles tests/radix-sort/radix.mbtiles tests/radix-sort/memory.json tests/radix-sort/radix.json
|
||||
|
||||
parallel-test: $(eval SHELL:=$(ADVSHELL))
|
||||
mkdir -p tests/parallel
|
||||
perl -e 'for ($$i = 0; $$i < 20; $$i++) { $$lon = rand(360) - 180; $$lat = rand(180) - 90; $$k = rand(1); $$v = rand(1); print "{ \"type\": \"Feature\", \"properties\": { \"yes\": \"no\", \"who\": 1, \"$$k\": \"$$v\" }, \"geometry\": { \"type\": \"Point\", \"coordinates\": [ $$lon, $$lat ] } }\n"; }' > tests/parallel/in1.json
|
||||
@@ -187,6 +261,14 @@ raw-tiles-test: tippecanoe tippecanoe-decode tile-join
|
||||
./tippecanoe-decode -x generator tests/raw-tiles/nothing > tests/raw-tiles/nothing.json.check
|
||||
cmp tests/raw-tiles/nothing.json.check tests/raw-tiles/nothing.json
|
||||
rm -r tests/raw-tiles/nothing tests/raw-tiles/nothing.json.check
|
||||
# Test that a non-string value in metadata.json is reported and skipped
|
||||
# instead of being read as a string (which used to crash)
|
||||
./tippecanoe -q -f -e tests/raw-tiles/nonstring tests/raw-tiles/hackspots.geojson
|
||||
sed -i.bak 's/"minzoom": "0"/"minzoom": 0/' tests/raw-tiles/nonstring/metadata.json
|
||||
rm tests/raw-tiles/nonstring/metadata.json.bak
|
||||
grep -q '"minzoom": 0' tests/raw-tiles/nonstring/metadata.json
|
||||
./tippecanoe-decode -x generator tests/raw-tiles/nonstring > /dev/null
|
||||
rm -r tests/raw-tiles/nonstring
|
||||
|
||||
pmtiles-test: tippecanoe tippecanoe-decode tile-join
|
||||
./tippecanoe -q -f -o tests/pmtiles/hackspots.pmtiles -r1 -pC tests/raw-tiles/hackspots.geojson
|
||||
@@ -322,7 +404,7 @@ overzoom-test: tippecanoe-overzoom
|
||||
# Filtering
|
||||
# 243 features in the source tile tests/pbf/0-0-0-pop.pbf
|
||||
# 27 of them match the filter and are retained
|
||||
./tippecanoe-overzoom -y NAME -j'{"*":["SCALERANK","eq",0]}' -o tests/pbf/0-0-0-pop-expr.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-overzoom -y NAME -j'{"*":["==","SCALERANK",0]}' -o tests/pbf/0-0-0-pop-expr.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-expr.pbf 0 0 0 > tests/pbf/0-0-0-pop-expr.pbf.json.check
|
||||
cmp tests/pbf/0-0-0-pop-expr.pbf.json.check tests/pbf/0-0-0-pop-expr.pbf.json
|
||||
rm tests/pbf/0-0-0-pop-expr.pbf tests/pbf/0-0-0-pop-expr.pbf.json.check
|
||||
@@ -334,13 +416,13 @@ overzoom-test: tippecanoe-overzoom
|
||||
# Filtering with multiplier
|
||||
# 243 features in the source tile tests/pbf/0-0-0-pop.pbf
|
||||
# 8 features survive into the output, from 9 clusters of 30
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -j'{"*":["SCALERANK","eq",0]}' -m -o tests/pbf/0-0-0-filter-mult.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -j'{"*":["==","SCALERANK",0]}' -m -o tests/pbf/0-0-0-filter-mult.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-filter-mult.pbf 0 0 0 > tests/pbf/0-0-0-filter-mult.pbf.json.check
|
||||
cmp tests/pbf/0-0-0-filter-mult.pbf.json.check tests/pbf/0-0-0-filter-mult.pbf.json
|
||||
rm tests/pbf/0-0-0-filter-mult.pbf tests/pbf/0-0-0-filter-mult.pbf.json.check
|
||||
# Filtering with multiplier and preserve-input-order
|
||||
# 243 features in the source tile tests/pbf/0-0-0-pop.pbf
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -j'{"*":["NAME","cn","e"]}' -m --preserve-input-order -o tests/pbf/0-0-0-filter-mult-order.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -y LATITUDE -j'{"*":[">","LATITUDE",40]}' -m --preserve-input-order -o tests/pbf/0-0-0-filter-mult-order.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-filter-mult-order.pbf 0 0 0 > tests/pbf/0-0-0-filter-mult-order.pbf.json.check
|
||||
cmp tests/pbf/0-0-0-filter-mult-order.pbf.json.check tests/pbf/0-0-0-filter-mult-order.pbf.json
|
||||
rm tests/pbf/0-0-0-filter-mult-order.pbf tests/pbf/0-0-0-filter-mult-order.pbf.json.check
|
||||
@@ -352,97 +434,21 @@ overzoom-test: tippecanoe-overzoom
|
||||
./tippecanoe-decode tests/muni/out/out.dir/000.pbf 0 0 0 > tests/muni/out/out.dir/overzoomed.json
|
||||
cmp tests/muni/out/out.dir/overzoomed.json tests/muni/out/out.dir/direct.json
|
||||
rm -rf tests/muni/out/out.dir tests/muni/out/out.mbtiles tests/muni/out/out.dir/overzoomed.json tests/muni/out/out.dir/direct.json
|
||||
# Test filter with null attribute
|
||||
./tippecanoe-overzoom -j '{"*":["name","ni",[1,5,6,9]]}' -o tests/pbf/12-2145-1391-filter1.pbf tests/pbf/12-2145-1391.pbf 12/2145/1391 12/2145/1391
|
||||
./tippecanoe-decode tests/pbf/12-2145-1391-filter1.pbf 12 2145 1391 > tests/pbf/12-2145-1391-filter1.pbf.json.check
|
||||
cmp tests/pbf/12-2145-1391-filter1.pbf.json.check tests/pbf/12-2145-1391-filter1.pbf.json
|
||||
rm tests/pbf/12-2145-1391-filter1.pbf.json.check tests/pbf/12-2145-1391-filter1.pbf
|
||||
# Test filter with null attribute in "ni" list
|
||||
./tippecanoe-overzoom -j '{"*":["name","ni",[1,5,6,9,null]]}' -o tests/pbf/12-2145-1391-filter2.pbf tests/pbf/12-2145-1391.pbf 12/2145/1391 12/2145/1391
|
||||
./tippecanoe-decode tests/pbf/12-2145-1391-filter2.pbf 12 2145 1391 > tests/pbf/12-2145-1391-filter2.pbf.json.check
|
||||
cmp tests/pbf/12-2145-1391-filter2.pbf.json.check tests/pbf/12-2145-1391-filter2.pbf.json
|
||||
rm tests/pbf/12-2145-1391-filter2.pbf.json.check tests/pbf/12-2145-1391-filter2.pbf
|
||||
# Tiny polygon reduction
|
||||
./tippecanoe-overzoom --line-simplification=5 --tiny-polygon-size=50 -o tests/pbf/countries-0-0-0.pbf.out tests/pbf/countries-0-0-0.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/countries-0-0-0.pbf.out 0 0 0 > tests/pbf/countries-0-0-0.pbf.out.json.check
|
||||
cmp tests/pbf/countries-0-0-0.pbf.out.json.check tests/pbf/countries-0-0-0.pbf.out.json
|
||||
rm tests/pbf/countries-0-0-0.pbf.out tests/pbf/countries-0-0-0.pbf.out.json.check
|
||||
# Clipping to bounding box
|
||||
./tippecanoe-overzoom --clip-bounding-box 5,5,25.7,50 -o tests/pbf/countries-0-0-0-clip.pbf.out tests/pbf/countries-0-0-0.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/countries-0-0-0-clip.pbf.out 0 0 0 > tests/pbf/countries-0-0-0-clip.pbf.out.json.check
|
||||
cmp tests/pbf/countries-0-0-0-clip.pbf.out.json.check tests/pbf/countries-0-0-0-clip.pbf.out.json
|
||||
rm tests/pbf/countries-0-0-0-clip.pbf.out tests/pbf/countries-0-0-0-clip.pbf.out.json.check
|
||||
# Binning
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791.pbf.out --assign-to-bins tests/pbf/sf-zips.json tests/pbf/muni-11-327-791.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791.pbf.out 11 327 791 > tests/pbf/bin-11-327-791.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791.pbf.out.json.check tests/pbf/bin-11-327-791.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791.pbf.out.json.check tests/pbf/bin-11-327-791.pbf.out
|
||||
# Binning by id
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791-ids.pbf.out --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids.pbf.out.json.check tests/pbf/bin-11-327-791-ids.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids.pbf.out.json.check tests/pbf/bin-11-327-791-ids.pbf.out
|
||||
# Binning by id, clipping by polygon
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791-ids-clip.pbf.out --clip-polygon='{"coordinates":[[[-122.4527379,37.8128815],[-122.4598853,37.7834743],[-122.4280914,37.7959397],[-122.4527379,37.8128815]]],"type":"Polygon"}' --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids-clip.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out
|
||||
# Binning by id, clipping by polygon from file
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791-ids-clip.pbf.out --clip-polygon-file=tests/pbf/clip-poly.json --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids-clip.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out
|
||||
# Binning by id, attribute stripping
|
||||
# Note that it still works even if we exclude the ID that we are binning by
|
||||
./tippecanoe-overzoom -yZCTA5CE10 -ytippecanoe:count -o tests/pbf/bin-11-327-791-ids-zip.pbf.out --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids-zip.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids-zip.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids-zip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-zip.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids-zip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-zip.pbf.out
|
||||
# Binning with longitude wraparound problems
|
||||
./tippecanoe-overzoom -o tests/pbf/0-0-0-pop-2-0-1.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-2-0-1.geojson tests/pbf/0-0-0.pbf 2/0/1 2/0/1
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-2-0-1.pbf.out 2 0 1 > tests/pbf/0-0-0-pop-2-0-1.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-2-0-1.pbf.out.json.check tests/pbf/0-0-0-pop-2-0-1.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-2-0-1.pbf.out tests/pbf/0-0-0-pop-2-0-1.pbf.out.json.check
|
||||
./tippecanoe-overzoom -o tests/pbf/0-0-0-pop-1-1-0.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-1-1-0.geojson tests/pbf/0-0-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-1-1-0.pbf.out 1 1 0 > tests/pbf/0-0-0-pop-1-1-0.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-1-1-0.pbf.out.json.check tests/pbf/0-0-0-pop-1-1-0.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-1-1-0.pbf.out tests/pbf/0-0-0-pop-1-1-0.pbf.out.json.check
|
||||
./tippecanoe-overzoom -o tests/pbf/0-0-0-pop-0-0-0.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-0-0-0.geojson tests/pbf/0-0-0.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-0-0-0.pbf.out 0 0 0 > tests/pbf/0-0-0-pop-0-0-0.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-0-0-0.pbf.out.json.check tests/pbf/0-0-0-pop-0-0-0.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-0-0-0.pbf.out tests/pbf/0-0-0-pop-0-0-0.pbf.out.json.check
|
||||
# Binning, clipping to bounding box
|
||||
./tippecanoe-overzoom --clip-bounding-box 88,67.5,138,78 -o tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-1-1-0.geojson tests/pbf/0-0-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out 1 1 0 > tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json.check tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json.check
|
||||
# Verify fix for crash
|
||||
./tippecanoe-overzoom '-o' tests/10188-crash/out.pbf '-t' '3/2/2' '--assign-to-bins' 'tests/10188-crash/bins.json' '--bin-by-id-list' 'felt:bin_features' '-b5' 'tests/10188-crash/2-0-0.pbf' '2/0/0'
|
||||
rm tests/10188-crash/out.pbf
|
||||
# Polygon clipping
|
||||
./tippecanoe-overzoom -o tests/pbf/countries-1-1-0-clip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/countries-1-1-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/countries-1-1-0-clip.pbf 1 1 0 > tests/pbf/countries-1-1-0-clip.json.check
|
||||
cmp tests/pbf/countries-1-1-0-clip.json.check tests/pbf/countries-1-1-0-clip.json
|
||||
rm tests/pbf/countries-1-1-0-clip.pbf tests/pbf/countries-1-1-0-clip.json.check
|
||||
# LineString clipping
|
||||
./tippecanoe-overzoom -o tests/pbf/roads-1-1-0-clip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/roads-1-1-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/roads-1-1-0-clip.pbf 1 1 0 > tests/pbf/roads-1-1-0-clip.json.check
|
||||
cmp tests/pbf/roads-1-1-0-clip.json.check tests/pbf/roads-1-1-0-clip.json
|
||||
rm tests/pbf/roads-1-1-0-clip.pbf tests/pbf/roads-1-1-0-clip.json.check
|
||||
# Point clipping
|
||||
./tippecanoe-overzoom -o tests/pbf/places-1-1-0-clip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/places-1-1-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/places-1-1-0-clip.pbf 1 1 0 > tests/pbf/places-1-1-0-clip.json.check
|
||||
cmp tests/pbf/places-1-1-0-clip.json.check tests/pbf/places-1-1-0-clip.json
|
||||
rm tests/pbf/places-1-1-0-clip.pbf tests/pbf/places-1-1-0-clip.json.check
|
||||
# Polygon clipping, with excessively large clip region
|
||||
./tippecanoe-overzoom -b10 -o tests/pbf/countries-8-135-86-bigclip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/countries-1-1-0.pbf 1/1/0 8/135/86
|
||||
./tippecanoe-decode tests/pbf/countries-8-135-86-bigclip.pbf 8 135 86 > tests/pbf/countries-8-135-86-bigclip.json.check
|
||||
cmp tests/pbf/countries-8-135-86-bigclip.json.check tests/pbf/countries-8-135-86-bigclip.json
|
||||
rm tests/pbf/countries-8-135-86-bigclip.pbf tests/pbf/countries-8-135-86-bigclip.json.check
|
||||
# Clip region that does not intersect with the tile
|
||||
./tippecanoe-overzoom -o tests/pbf/squirrels-13-2413-3077-clip.pbf --clip-polygon-file tests/pbf/squirrels-clip.json tests/pbf/squirrels-13-2413-3077.pbf 13/2413/3077 13/2413/3077
|
||||
cmp tests/pbf/squirrels-13-2413-3077-clip.pbf /dev/null # clipped away
|
||||
rm tests/pbf/squirrels-13-2413-3077-clip.pbf
|
||||
# Deduplication by feature ID
|
||||
./tippecanoe -z0 -f -e tests/pbf/1.json.dir -l layer tests/pbf/1.json
|
||||
./tippecanoe -z0 -f -e tests/pbf/2.json.dir -l layer tests/pbf/2.json
|
||||
./tippecanoe-overzoom -b0 -o tests/pbf/merged-nodedup.pbf -t 1/1/0 tests/pbf/1.json.dir/0/0/0.pbf 0/0/0 tests/pbf/2.json.dir/0/0/0.pbf 0/0/0
|
||||
./tippecanoe-decode tests/pbf/merged-nodedup.pbf 1 1 0 > tests/pbf/merged-nodedup.pbf.json.check
|
||||
cmp tests/pbf/merged-nodedup.pbf.json.check tests/pbf/merged-nodedup.pbf.json
|
||||
./tippecanoe-overzoom -b0 --deduplicate-by-id -o tests/pbf/merged-dedup.pbf -t 1/1/0 tests/pbf/1.json.dir/0/0/0.pbf 0/0/0 tests/pbf/2.json.dir/0/0/0.pbf 0/0/0
|
||||
./tippecanoe-decode tests/pbf/merged-dedup.pbf 1 1 0 > tests/pbf/merged-dedup.pbf.json.check
|
||||
cmp tests/pbf/merged-dedup.pbf.json.check tests/pbf/merged-dedup.pbf.json
|
||||
rm -r tests/pbf/1.json.dir tests/pbf/2.json.dir tests/pbf/merged-nodedup.pbf tests/pbf/merged-nodedup.pbf.json.check tests/pbf/merged-dedup.pbf tests/pbf/merged-dedup.pbf.json.check
|
||||
|
||||
join-test: tippecanoe tippecanoe-decode tile-join
|
||||
./tippecanoe -q -f -z12 -o tests/join-population/tabblock_06001420.mbtiles -YALAND10:'Land area' -L'{"file": "tests/join-population/tabblock_06001420.json", "description": "population"}'
|
||||
@@ -578,145 +584,6 @@ join-test: tippecanoe tippecanoe-decode tile-join
|
||||
./tippecanoe-decode -x generator tests/ne_110m_ocean/join/joined.mbtiles > tests/ne_110m_ocean/join/joined.mbtiles.json.check
|
||||
cmp tests/ne_110m_ocean/join/joined.mbtiles.json.check tests/ne_110m_ocean/join/joined.mbtiles.json
|
||||
rm -f tests/ne_110m_ocean/join/ocean.mbtiles tests/ne_110m_ocean/join/countries.mbtiles tests/ne_110m_ocean/join/joined.mbtiles tests/ne_110m_ocean/join/joined.mbtiles.json.check
|
||||
#
|
||||
# Test sql join
|
||||
#
|
||||
./tile-join -i -f -o tests/join-sql/countries.pmtiles --join-sqlite tests/join-sql/countries.gpkg --join-table countries --join-tile-attribute ne10-admin0:name_en --join-table-expression 'lower(country)' tests/join-sql/bboxes.pmtiles
|
||||
./tippecanoe-decode -x generator tests/join-sql/countries.pmtiles > tests/join-sql/countries.pmtiles.json.check
|
||||
cmp tests/join-sql/countries.pmtiles.json.check tests/join-sql/countries.pmtiles.json
|
||||
rm -f tests/join-sql/countries.pmtiles tests/join-sql/countries.pmtiles.json.check
|
||||
#
|
||||
# Test sql join with limit
|
||||
#
|
||||
./tile-join --join-count-limit 3 -i -f -o tests/join-sql/countries-limit3.pmtiles --join-sqlite tests/join-sql/countries.gpkg --join-table countries --join-tile-attribute ne10-admin0:name_en --join-table-expression 'lower(country)' tests/join-sql/bboxes.pmtiles
|
||||
./tippecanoe-decode -x generator tests/join-sql/countries-limit3.pmtiles > tests/join-sql/countries-limit3.pmtiles.json.check
|
||||
cmp tests/join-sql/countries-limit3.pmtiles.json.check tests/join-sql/countries-limit3.pmtiles.json
|
||||
rm -f tests/join-sql/countries-limit3.pmtiles tests/join-sql/countries-limit3.pmtiles.json.check
|
||||
|
||||
accumulate-test:
|
||||
# there are 144 features with POP1950 in the original dataset
|
||||
test `grep '"POP1950": [0-9]' tests/ne_110m_populated_places_nulls/in.json | wc -l` == 144
|
||||
# and 99 without it
|
||||
test `grep '"POP1950": null' tests/ne_110m_populated_places_nulls/in.json | wc -l` == 99
|
||||
./tippecanoe -yNAME -yPOP1950 -yclustered:cluster_size -yclustered:unrelated -q -z3 -r1.75 -b0 -f -e tests/pbf/accum.dir --accumulate-numeric-attributes=clustered --set-attribute '{"clustered:cluster_size":1}' --accumulate-attribute '{"clustered:cluster_size":"sum"}' --retain-points-multiplier 3 tests/ne_110m_populated_places_nulls/in.json
|
||||
# at this drop rate, there are 61 points at z0 that have no POP1950s clustered onto them....
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | wc -l` == 61
|
||||
# 26 of which have no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 26
|
||||
# 35 of which do have POP1950
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 35
|
||||
# plus 60 that are clustered
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 60
|
||||
# the 60 clustered POP1950s have a total count of 109
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:count:POP1950' | sed 's/.*"clustered:count:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 109
|
||||
# we have already established that there are 36 bare POP1950s
|
||||
# which makes a total of 144, which is the total count expected
|
||||
#
|
||||
# meanwhile, regular attribute accumulation.
|
||||
# there are 121 features in the z0 tile, and they all have clustered:cluster_size
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:cluster_size' | wc -l` == 121
|
||||
# there are no features that lack it.
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:cluster_size' | wc -l` == 0
|
||||
# they add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# But that we *do* preserve those attributes into the output features:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 61
|
||||
#
|
||||
# on to the sums:
|
||||
# in the original data set, the POP1950s that are present add up to 161590
|
||||
test `grep '"POP1950": [0-9]' tests/ne_110m_populated_places_nulls/in.json | sed 's/.*"POP1950": //' | awk '{sum += $$1} END {print sum}' ` == 161590
|
||||
# in the z0 tile, the clustered POP1950s add up to 116967
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 116967
|
||||
# and the non-clustered ones add up to 44623
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:sum:POP1950' | grep POP1950 | sed 's/.*"POP1950": //' | awk '{sum += $$1} END {print sum}'` == 44623
|
||||
# which is the correct 161590
|
||||
#
|
||||
# OK, so do these still hold after megatile filtering?
|
||||
./tippecanoe-overzoom --accumulate-numeric-attributes=clustered --accumulate-attribute '{"clustered:cluster_size":"sum"}' -m -o tests/pbf/accum-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# Now there are 40 features with POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 40
|
||||
# There are 4 with bare POP1950
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 4
|
||||
# And 2 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 2
|
||||
# (which is the same as you get if you don't use -retain-points-multiplier when creating the tileset)
|
||||
#
|
||||
# the clustered and megatile-filtered POP1950s add up to 146370
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 146370
|
||||
# the non-clustered but megatile-filtered POP1950s add up to 15220
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'clustered:sum:POP1950' | grep POP1950 | sed 's/.*"POP1950": //' | awk '{sum += $$1} END {print sum}'` == 15220
|
||||
# which add up to 161590 so we have the right global total
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# But that we *do* preserve those attributes into the output features:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 22
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
# We actually want to serve point tiles without the numeric accumulations,
|
||||
# but with cluster size, so test that combination:
|
||||
./tippecanoe-overzoom --accumulate-attribute '{"clustered:cluster_size":"sum"}' --exclude-prefix clustered:sum --exclude-prefix clustered:count --exclude-prefix clustered:min --exclude-prefix clustered:max --exclude-prefix clustered:mean -m -o tests/pbf/accum-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# There are no POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 0
|
||||
# But there are still 28 with bare POP1950
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 28
|
||||
# And 18 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 18
|
||||
# which matches the 46 features that you get if you tile without --retain-points-multiplier.
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
# Now on to binning!
|
||||
./tippecanoe-overzoom --assign-to-bins tests/pbf/h3-0-0-0.geojson --accumulate-numeric-attributes=clustered --accumulate-attribute '{"clustered:cluster_size":"sum"}' -o tests/pbf/bins-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# Now there are 30 bins with POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 41
|
||||
# There are none with bare POP1950 (which is expected; we should only have summary statistics)
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 0
|
||||
# And 4 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 3
|
||||
#
|
||||
# the clustered and megatile-filtered and binned POP1950s add up to 161590
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 161590
|
||||
# which is the right global total
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# And those attributes do *not* make it onto the bins
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 0
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
# Binning with attribute stripping
|
||||
./tippecanoe-overzoom -y clustered:count:POP1950 -y clustered:sum:POP1950 -y POP1950 -y clustered:cluster_size --assign-to-bins tests/pbf/h3-0-0-0.geojson --accumulate-numeric-attributes=clustered --accumulate-attribute '{"clustered:cluster_size":"sum"}' -o tests/pbf/bins-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# Now there are 30 bins with POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 41
|
||||
# There are none with bare POP1950 (which is expected; we should only have summary statistics)
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 0
|
||||
# And 4 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 3
|
||||
#
|
||||
# the clustered and megatile-filtered and binned POP1950s add up to 161590
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 161590
|
||||
# which is the right global total
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# And those attributes do *not* make it onto the bins
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 0
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
#
|
||||
# A tile where the counts and means were previously wrong:
|
||||
./tippecanoe-overzoom --accumulate-numeric-attributes=felt -m -o tests/pbf/yearbuilt-accum.pbf tests/pbf/yearbuilt.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/yearbuilt-accum.pbf 0 0 0 > tests/pbf/yearbuilt-accum.pbf.json.check
|
||||
cmp tests/pbf/yearbuilt-accum.pbf.json.check tests/pbf/yearbuilt-accum.pbf.json
|
||||
rm tests/pbf/yearbuilt-accum.pbf tests/pbf/yearbuilt-accum.pbf.json.check
|
||||
# Same tile, with attribute stripping
|
||||
./tippecanoe-overzoom --accumulate-numeric-attributes=felt -y bldgsqft -y felt:sum:bldgsqft -m -o tests/pbf/yearbuilt-accum-bldgsqft.pbf tests/pbf/yearbuilt.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/yearbuilt-accum-bldgsqft.pbf 0 0 0 > tests/pbf/yearbuilt-accum-bldgsqft.pbf.json.check
|
||||
cmp tests/pbf/yearbuilt-accum-bldgsqft.pbf.json.check tests/pbf/yearbuilt-accum-bldgsqft.pbf.json
|
||||
rm tests/pbf/yearbuilt-accum-bldgsqft.pbf tests/pbf/yearbuilt-accum-bldgsqft.pbf.json.check
|
||||
|
||||
join-filter-test: tippecanoe tippecanoe-decode tile-join
|
||||
# Comes out different from the direct tippecanoe run because null attributes are lost
|
||||
@@ -787,6 +654,12 @@ csv-test: tippecanoe tippecanoe-decode
|
||||
cmp tests/csv/out.mbtiles.json.check tests/csv/out.mbtiles.json
|
||||
rm -f tests/csv/out.mbtiles.json.check tests/csv/out.mbtiles
|
||||
|
||||
flatgeobuf-test: tippecanoe tippecanoe-decode
|
||||
./tippecanoe -q -f -z0 -l numeric-properties -o tests/flatgeobuf/numeric-properties.mbtiles tests/flatgeobuf/numeric-properties.fgb
|
||||
./tippecanoe-decode tests/flatgeobuf/numeric-properties.mbtiles 0 0 0 > tests/flatgeobuf/numeric-properties.json.check
|
||||
cmp tests/flatgeobuf/numeric-properties.json.check tests/flatgeobuf/numeric-properties.json
|
||||
rm -f tests/flatgeobuf/numeric-properties.mbtiles tests/flatgeobuf/numeric-properties.json.check
|
||||
|
||||
layer-json-test: tippecanoe tippecanoe-decode
|
||||
# GeoJSON with description and named layer
|
||||
./tippecanoe -q -z0 -r1 -yNAME -f -o tests/layer-json/out.mbtiles -L'{"file":"tests/ne_110m_populated_places/in.json", "description":"World cities", "layer":"places"}'
|
||||
|
||||
@@ -20,11 +20,11 @@ the density and texture of the data rather than a simplification from dropping
|
||||
supposedly unimportant features or clustering or aggregating them.
|
||||
|
||||
If you give it all of OpenStreetMap and zoom out, it should give you back
|
||||
something that looks like "[All Streets](http://benfry.com/allstreets/map5.html)"
|
||||
something that looks like "[All Streets](https://benfry.com/allstreets/)"
|
||||
rather than something that looks like an Interstate road atlas.
|
||||
|
||||
If you give it all the building footprints in Los Angeles and zoom out
|
||||
far enough that most individual buildings are no longer discernable, you
|
||||
far enough that most individual buildings are no longer discernible, you
|
||||
should still be able to see the extent and variety of development in every neighborhood,
|
||||
not just the largest downtown buildings.
|
||||
|
||||
@@ -57,8 +57,8 @@ compiler errors.
|
||||
Usage
|
||||
-----
|
||||
|
||||
```sh
|
||||
$ tippecanoe -o file.mbtiles [options] [file.json file.json.gz file.fgb ...]
|
||||
```
|
||||
$ tippecanoe -o file.mbtiles [options] [file.json file.json.gz file.fgb file.csv ...]
|
||||
```
|
||||
|
||||
If no files are specified, it reads GeoJSON from the standard input.
|
||||
@@ -99,7 +99,7 @@ $ tippecanoe -o alameda.mbtiles -l alameda -n "Alameda County from TIGER" -z13 t
|
||||
Create a tileset of all TIGER roads, at only zoom level 12, but with higher detail than normal,
|
||||
with a custom layer name and description, and leaving out the `LINEARID` and `RTTYP` attributes:
|
||||
|
||||
```
|
||||
```sh
|
||||
$ cat tiger/tl_2014_*_roads.json | tippecanoe -o tiger.mbtiles -l roads -n "All TIGER roads, one zoom" -z12 -Z12 -d14 -x LINEARID -x RTTYP
|
||||
```
|
||||
|
||||
@@ -108,7 +108,7 @@ Cookbook
|
||||
|
||||
### Linear features (world railroads), visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_railroads.zip
|
||||
unzip ne_10m_railroads.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_railroads.geojson ne_10m_railroads.shp
|
||||
@@ -122,7 +122,7 @@ tippecanoe -zg -o ne_10m_railroads.mbtiles --drop-densest-as-needed --extend-zoo
|
||||
|
||||
### Discontinuous polygon features (buildings of Rhode Island), visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://usbuildingdata.blob.core.windows.net/usbuildings-v1-1/RhodeIsland.zip
|
||||
unzip RhodeIsland.zip
|
||||
|
||||
@@ -135,7 +135,7 @@ tippecanoe -zg -o RhodeIsland.mbtiles --drop-densest-as-needed --extend-zooms-if
|
||||
|
||||
### Continuous polygon features (states and provinces), visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_admin_1_states_provinces.zip
|
||||
unzip -o ne_10m_admin_1_states_provinces.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_admin_1_states_provinces.geojson ne_10m_admin_1_states_provinces.shp
|
||||
@@ -149,7 +149,7 @@ tippecanoe -zg -o ne_10m_admin_1_states_provinces.mbtiles --coalesce-densest-as-
|
||||
|
||||
### Large point dataset (GPS bus locations), for visualization at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O ftp://avl-data.sfmta.com/avl_data/avl_raw/sfmtaAVLRawData01012013.csv
|
||||
sed 's/PREDICTABLE.*/PREDICTABLE/' sfmtaAVLRawData01012013.csv > sfmta.csv
|
||||
tippecanoe -zg -o sfmta.mbtiles --drop-densest-as-needed --extend-zooms-if-still-dropping sfmta.csv
|
||||
@@ -163,7 +163,7 @@ tippecanoe -zg -o sfmta.mbtiles --drop-densest-as-needed --extend-zooms-if-still
|
||||
|
||||
### Clustered points (world cities), summing the clustered population, visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_populated_places.zip
|
||||
unzip -o ne_10m_populated_places.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_populated_places.geojson ne_10m_populated_places.shp
|
||||
@@ -178,7 +178,7 @@ tippecanoe -zg -o ne_10m_populated_places.mbtiles -r1 --cluster-distance=10 --ac
|
||||
|
||||
### Show countries at low zoom levels but states at higher zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_admin_0_countries.zip
|
||||
unzip ne_10m_admin_0_countries.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_admin_0_countries.geojson ne_10m_admin_0_countries.shp
|
||||
@@ -206,7 +206,7 @@ States and Provinces:
|
||||
|
||||
### Represent multiple sources (Illinois and Indiana counties) as separate layers
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/COUNTY/2010/tl_2010_17_county10.zip
|
||||
unzip tl_2010_17_county10.zip
|
||||
ogr2ogr -f GeoJSON tl_2010_17_county10.geojson tl_2010_17_county10.shp
|
||||
@@ -224,7 +224,7 @@ tippecanoe -zg -o counties-separate.mbtiles --coalesce-densest-as-needed --exten
|
||||
|
||||
### Merge multiple sources (Illinois and Indiana counties) into the same layer
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/COUNTY/2010/tl_2010_17_county10.zip
|
||||
unzip tl_2010_17_county10.zip
|
||||
ogr2ogr -f GeoJSON tl_2010_17_county10.geojson tl_2010_17_county10.shp
|
||||
@@ -242,7 +242,7 @@ As above, but
|
||||
|
||||
### Selectively remove and replace features (Census tracts) to update a tileset
|
||||
|
||||
```
|
||||
```sh
|
||||
# Retrieve and tile California 2000 Census tracts
|
||||
curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/TRACT/2000/tl_2010_06_tract00.zip
|
||||
unzip tl_2010_06_tract00.zip
|
||||
@@ -291,6 +291,11 @@ If your features have a lot of attributes, use `-y` to keep only the ones you re
|
||||
|
||||
If your input is formatted as newline-delimited GeoJSON, use `-P` to make input parsing a lot faster.
|
||||
|
||||
Many of the options below have a short form beginning with `-a` or `-p`. These are the
|
||||
`-a`_letters_ (`--additional=`_letters_) and `-p`_letters_ (`--prevent=`_letters_) options, and each
|
||||
accepts several letters at once, so for example `-ansd` is the same as `-an -as -ad`
|
||||
and `-pkC` is the same as `-pk -pC`.
|
||||
|
||||
### Output tileset
|
||||
|
||||
* `-o` _file_`.mbtiles`, _file_`.pmtiles` or `--output=`_file_`.mbtiles`: Name the output file.
|
||||
@@ -301,9 +306,9 @@ If your input is formatted as newline-delimited GeoJSON, use `-P` to make input
|
||||
|
||||
### Tileset description and attribution
|
||||
|
||||
* `-n` _name_ or `--name=`_name_: Human-readable name for the tileset (default file.json)
|
||||
* `-n` _name_ or `--name=`_name_: Human-readable name for the tileset (default: the name of the output file or directory)
|
||||
* `-A` _text_ or `--attribution=`_text_: Attribution (HTML) to be shown with maps that use data from this tileset.
|
||||
* `-N` _description_ or `--description=`_description_: Description for the tileset (default file.mbtiles)
|
||||
* `-N` _description_ or `--description=`_description_: Description for the tileset (default: the name of the output file or directory)
|
||||
|
||||
### Input files and layer names
|
||||
|
||||
@@ -316,11 +321,11 @@ If your input is formatted as newline-delimited GeoJSON, use `-P` to make input
|
||||
* `-L` _name_`:`_file.json_ or `--named-layer=`_name_`:`_file.json_: Specify layer names for individual files. If your shell supports it, you can use a subshell redirect like `-L` _name_`:<(cat dir/*.json)` to specify a layer name for the output of streamed input.
|
||||
* `-L{`_layer-json_`}` or `--named-layer={`_layer-json_`}`: Specify an input file and layer options by a JSON object. The JSON object must contain a `"file"` key to specify the filename to read from. (If the `"file"` key is an empty string, it means to read from the standard input stream.) It may also contain a `"layer"` field to specify the name of the layer, and/or a `"description"` field to specify the layer's description in the tileset metadata, and/or a `"format"` field to specify `csv` or `fgb` file format if it is not obvious from the `name`. Example:
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -z5 -o world.mbtiles -L'{"file":"ne_10m_admin_0_countries.json", "layer":"countries", "description":"Natural Earth countries"}'
|
||||
```
|
||||
|
||||
CSV input files currently support only Point geometries, from columns named `latitude`, `longitude`, `lat`, `lon`, `long`, `lng`, `x`, or `y`.
|
||||
CSV input files currently support only Point geometries, from columns named `lat`, `lon`, `long`, `lng`, `x`, or `y`, or from any column whose name contains `latitude` or `longitude`. Column names are matched without regard to case.
|
||||
|
||||
### Parallel processing of input
|
||||
|
||||
@@ -352,7 +357,7 @@ Parallel processing will also be automatic if the input file is in FlatGeobuf fo
|
||||
specified maximum zoom and to any levels added beyond that.
|
||||
* `--extend-zooms-if-still-dropping-maximum=`_count_: Increase the maxzoom if features are still being dropped at that zoom level
|
||||
by up to _count_ zoom levels.
|
||||
* `-at` or `--generate-variable-depth-tile-pyramid`: Don't produce child tiles for any tile that should be sufficient to be overzoomed to any higher zoom level. Such tiles will be produced with maximum detail and no simplification or polygon cleaning. Tiles with point features below the basezoom or where any features have to be dropped dynamically, or which contain too many features or bytes with full detail, will be written out with normal detail and split into child tiles. Tilesets generated with this option are suitable for use only with tile servers that will find the appropriate tile to overzoom from and will simplify and clean the geometries appropriately before serving the tile.
|
||||
* `-at` or `--generate-variable-depth-tile-pyramid`: Don't produce child tiles for any tile that should be sufficient to be overzoomed to any higher zoom level. Such tiles will be produced with maximum detail, retaining every vertex that is not collinear with its neighbors, but their polygons are still cleaned so that overlapping areas are merged rather than left stacked. Tiles with point features below the basezoom, or which contain too many features or bytes with full detail, will be written out with normal detail and split into child tiles. If any features have to be dropped dynamically at a zoom level, no tile in that zoom level is truncated, so that the whole zoom level is reduced consistently; any tile that was already being skipped because an ancestor had been truncated is written out after all. Tilesets generated with this option are suitable for use only with tile servers that will find the appropriate tile to overzoom from and will simplify the geometries appropriately before serving the tile.
|
||||
* `-R` _zoom_`/`_x_`/`_y_ or `--one-tile=`_zoom_`/`_x_`/`_y_: Set the minzoom and maxzoom to _zoom_ and produce only
|
||||
the single specified tile at that zoom level.
|
||||
|
||||
@@ -415,11 +420,12 @@ be reduced to the maximum that can be used with the specified _maxzoom_.
|
||||
* `-Y`_attribute_`:`_description_ or `--attribute-description=`_attribute_`:`_description_: Set the `description` for the specified attribute in the tileset metadata to _description_ instead of the usual `String`, `Number`, or `Boolean`.
|
||||
* `-E`_attribute_`:`_operation_ or `--accumulate-attribute=`_attribute_`:`_operation_: Preserve the named _attribute_ from features
|
||||
that are dropped, coalesced-as-needed, or clustered. The _operation_ may be
|
||||
`sum`, `product`, `mean`, `max`, `min`, `concat`, or `comma`
|
||||
`sum`, `product`, `mean`, `max`, `min`, `concat`, `comma`, or `count`
|
||||
to specify how the named _attribute_ is accumulated onto the attribute of the same name in a feature that does survive.
|
||||
The attributes and operations may also be specified as JSON keys and values: `--accumulate-attribute='{"attr": "operation", "attr2", "operation2"}'`.
|
||||
(The `count` operation replaces the attribute with the number of features, including the survivor, that carried it.)
|
||||
The attributes and operations may also be specified as JSON keys and values: `--accumulate-attribute='{"attr": "operation", "attr2": "operation2"}'`.
|
||||
* `--set-attribute` _attribute_`:`_value_: Set the value of the specified _attribute_ in each feature to the specified _value_. This is mostly useful to give an attribute in each feature an initial value for `--accumulate-attribute`.
|
||||
The attributes and values may also be specified as JSON keys and values: `--set-attribute='{"attr": value, "attr2", value}'`.
|
||||
The attributes and values may also be specified as JSON keys and values: `--set-attribute='{"attr": value, "attr2": value}'`.
|
||||
* `-pe` or `--empty-csv-columns-are-null`: Treat empty CSV columns as nulls rather than as empty strings.
|
||||
* `-aI` or `--convert-stringified-ids-to-numbers`: If a feature ID is the string representation of a number, convert it to a plain number to use as the feature ID.
|
||||
* `--use-attribute-for-id=`*name*: Use the attribute with the specified *name* as if it were specified as the feature ID. (If this attribute is a stringified number, you must also use `-aI` to convert it to a number.)
|
||||
@@ -433,20 +439,20 @@ be reduced to the maximum that can be used with the specified _maxzoom_.
|
||||
|
||||
Example: to find the Natural Earth countries with low `scalerank` but high `LABELRANK`:
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -z5 -o filtered.mbtiles -j '{ "ne_10m_admin_0_countries": [ "all", [ "<", "scalerank", 3 ], [ ">", "LABELRANK", 5 ] ] }' ne_10m_admin_0_countries.geojson
|
||||
```
|
||||
|
||||
Example: to retain only major TIGER roads at low zoom levels:
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o roads.mbtiles -j '{ "*": [ "any", [ ">=", "$zoom", 11 ], [ "in", "MTFCC", "S1100", "S1200" ] ] }' tl_2015_06001_roads.json
|
||||
```
|
||||
|
||||
Tippecanoe also accepts expressions of the form `[ "attribute-filter", name, expression ]`, to filter individual feature attributes
|
||||
instead of entire features. For example, you can exclude the road names at low zoom levels by doing
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o roads.mbtiles -j '{ "*": [ "attribute-filter", "FULLNAME", [ ">=", "$zoom", 9 ] ] }' tl_2015_06001_roads.json
|
||||
```
|
||||
|
||||
@@ -466,31 +472,34 @@ the same layer, enclose them in an `all` expression so they will all be evaluate
|
||||
If you use `-Bg`, it will guess a zoom level that will keep at most 50,000 features in the densest tile.
|
||||
You can also specify a marker-width with `-Bg`*width* to allow fewer features in the densest tile to
|
||||
compensate for the larger marker, or `-Bf`*number* to allow at most *number* features in the densest tile.
|
||||
* `--retain-points-multiplier=`_multiple_: Retain the specified multiple of points instead of just the number of points that would ordinarily be retained by the drop rate. These can be thinned out later with the `-m` option to `tippecanoe-overzoom`. The start of each cluster is marked in the feature sequence by the `tippecanoe:retain_points_multiplier_first` attribute. The `--tile-size-limit` will also be extended at low zoom levels to allow for the multiplied features.
|
||||
* `--retain-points-multiplier=`_multiple_: Retain the specified multiple of points instead of just the number of points that would ordinarily be retained by the drop rate. These can be thinned out later with the `-m` option to `tippecanoe-overzoom`. The start of each cluster is marked in the feature sequence by the `tippecanoe:retain_points_multiplier_first` attribute. The maximum tile size (`--maximum-tile-bytes`) will also be extended at low zoom levels to allow for the multiplied features.
|
||||
* `--drop-denser=`_percentage_: When dropping dots at zoom levels below the base zoom, give the specified _percentage_
|
||||
preference to retaining points in sparse areas and dropping points in dense areas.
|
||||
* `--limit-base-zoom-to-maximum-zoom` or `-Pb`: Limit the guessed base zoom not to exceed the maxzoom, even if this would put more than the requested number of features in a base zoom tile.
|
||||
* `--limit-base-zoom-to-maximum-zoom` or `-pb`: Limit the guessed base zoom not to exceed the maxzoom, even if this would put more than the requested number of features in a base zoom tile.
|
||||
* `-al` or `--drop-lines`: Let "dot" dropping at lower zooms apply to lines too
|
||||
* `-ap` or `--drop-polygons`: Let "dot" dropping at lower zooms apply to polygons too
|
||||
* `-K` _distance_ or `--cluster-distance=`_distance_: Cluster points (as with `--cluster-densest-as-needed`, but without the experimental discovery process) that are approximately within _distance_ of each other. The units are tile coordinates within a nominally 256-pixel tile, so the maximum value of 255 allows only one feature per tile. Values around 10 are probably appropriate for typical marker sizes. See `--cluster-densest-as-needed` below for behavior.
|
||||
* `-k` _zoom_ or `--cluster-maxzoom=`_zoom_: Max zoom on which to cluster points if clustering is enabled.
|
||||
* `-kg` or `--cluster-maxzoom=g`: Set `--cluster-maxzoom=` to `maxzoom - 1` so that all features are visible at the maximum zoom level.
|
||||
* `--preserve-point-density-threshold=`_level_: At the low zoom levels, do not reduce point density below the specified _level_, even if the specfied drop rate would normally call for it, so that low-density areas of the map do not appear blank. The unit is the distance between preserved points, as a fraction of the size of a tile. Values of 32 or 64 are probably appropriate for typical marker sizes.
|
||||
* `--preserve-point-density-threshold=`_level_: At the low zoom levels, do not reduce point density below the specified _level_, even if the specified drop rate would normally call for it, so that low-density areas of the map do not appear blank. The unit is the distance between preserved points, as a fraction of the size of a tile. Values of 32 or 64 are probably appropriate for typical marker sizes.
|
||||
* `--preserve-multiplier-density-threshold=`_level_: As with `--preserve-point-density-threshold`, but for the additional features retained by `--retain-points-multiplier`: features that would otherwise be dropped are instead added to the multiplier cluster if they are farther than the specified _level_ from the previous retained feature, so that sparse areas still have features available to be thinned to. The unit is the same as for `--preserve-point-density-threshold`.
|
||||
|
||||
### Dropping a fraction of features to keep under tile size limits
|
||||
|
||||
* `-as` or `--drop-densest-as-needed`: If a tile is too large, try to reduce it to under 500K by increasing the minimum spacing between features. The discovered spacing applies to the entire zoom level.
|
||||
* `-ad` or `--drop-fraction-as-needed`: Dynamically drop some fraction of features from each zoom level to keep large tiles under the 500K size limit. (This is like `-pd` but applies to the entire zoom level, not to each tile.)
|
||||
* `-an` or `--drop-smallest-as-needed`: Dynamically drop the smallest features (physically smallest: the shortest lines or the smallest polygons) from each zoom level to keep large tiles under the 500K size limit.
|
||||
* `--drop-by-attribute-as-needed=`_attribute_: Dynamically drop features with the lowest values of the specified numeric _attribute_ from each zoom level to keep large tiles under the 500K size limit. Use `--drop-by-attribute-order=desc` to instead drop features with the highest values.
|
||||
* `-aN` or `--coalesce-smallest-as-needed`: Dynamically combine the smallest features (physically smallest: the shortest lines or the smallest polygons or the densest points) from each zoom level into other nearby features to keep large tiles under the 500K size limit. This option will probably not help very much with LineStrings. It is mostly intended for polygons, to maintain the full original area covered by polygons while still reducing the feature count somehow. The attributes of the small polygons are *not* preserved into the combined features (except through `--accumulate-attribute`), only their geometry. Furthermore, the polygons to which nested polygons are coalesced may not necessarily be the immediately enclosing features.
|
||||
* `-aD` or `--coalesce-densest-as-needed`: Dynamically combine the densest features from each zoom level into other nearby features to keep large tiles under the 500K size limit. (Again, mostly useful for polygons.)
|
||||
* `-aS` or `--coalesce-fraction-as-needed`: Dynamically combine a fraction of features from each zoom level into other nearby features to keep large tiles under the 500K size limit. (Again, mostly useful for polygons.)
|
||||
* `-aS` or `--coalesce-densest-as-needed`: Dynamically combine the densest features from each zoom level into other nearby features to keep large tiles under the 500K size limit. (Again, mostly useful for polygons.)
|
||||
* `-aD` or `--coalesce-fraction-as-needed`: Dynamically combine a fraction of features from each zoom level into other nearby features to keep large tiles under the 500K size limit. (Again, mostly useful for polygons.)
|
||||
* `-pd` or `--force-feature-limit`: Dynamically drop some fraction of features from large tiles to keep them under the 500K size limit. It will probably look ugly at the tile boundaries. (This is like `-ad` but applies to each tile individually, not to the entire zoom level.) You probably don't want to use this.
|
||||
* `-aC` or `--cluster-densest-as-needed`: If a tile is too large, try to reduce its size by increasing the minimum spacing between features, and leaving one placeholder feature from each group. The remaining feature will be given a `"clustered": true` attribute to indicate that it represents a cluster, a `"point_count"` attribute to indicate the number of features that were clustered into it, and a `"sqrt_point_count"` attribute to indicate the relative width of a feature to represent the cluster. If the features being clustered are points, the representative feature will be located at the average of the original points' locations; otherwise, one of the original features will be left as the representative.
|
||||
* `-aC` or `--cluster-densest-as-needed`: If a tile is too large, try to reduce its size by increasing the minimum spacing between features, and leaving one placeholder feature from each group. The remaining feature will be given a `"clustered": true` attribute to indicate that it represents a cluster, a `"point_count"` attribute to indicate the number of features that were clustered into it, a `"point_count_abbreviated"` attribute containing that count abbreviated for display (for example `1.2k` or `15k`), and a `"sqrt_point_count"` attribute to indicate the relative width of a feature to represent the cluster. If the features being clustered are points, the representative feature will be located at the average of the original points' locations (unless you use `--keep-point-cluster-position`); otherwise, one of the original features will be left as the representative.
|
||||
* `-aa` or `--keep-point-cluster-position`: When clustering points, leave the representative feature at the location of the first point of the cluster instead of moving it to the average of the clustered points' locations.
|
||||
|
||||
### Dropping tightly overlapping features
|
||||
|
||||
* `-g` _gamma_ or `--gamma=_gamma`_: Rate at which especially dense dots are dropped (default 0, for no effect). A gamma of 2 reduces the number of dots less than a pixel apart to the square root of their original number.
|
||||
* `-g` _gamma_ or `--gamma=`_gamma_: Rate at which especially dense dots are dropped (default 0, for no effect). A gamma of 2 reduces the number of dots less than a pixel apart to the square root of their original number.
|
||||
* `-aG` or `--increase-gamma-as-needed`: If a tile is too large, try to reduce it to under 500K by increasing the `-g` gamma. The discovered gamma applies to the entire zoom level. You probably want to use `--drop-densest-as-needed` instead.
|
||||
|
||||
### Line and polygon simplification
|
||||
@@ -508,7 +517,7 @@ the same layer, enclose them in an `all` expression so they will all be evaluate
|
||||
|
||||
### Attempts to improve shared polygon boundaries
|
||||
|
||||
* `-ab` or `--detect-shared-borders`: DEPRECATED. In the manner of [TopoJSON](https://github.com/mbostock/topojson/wiki/Introduction), detect borders that are shared between multiple polygons and simplify them identically in each polygon. This takes more time and memory than considering each polygon individually. Use `no-simplification-of-shared-nodes` instead, which is faster and more correct.
|
||||
* `-ab` or `--detect-shared-borders`: DEPRECATED. In the manner of [TopoJSON](https://github.com/mbostock/topojson/wiki/Introduction), detect borders that are shared between multiple polygons and simplify them identically in each polygon. This takes more time and memory than considering each polygon individually. Use `--no-simplification-of-shared-nodes` instead, which is faster and more correct.
|
||||
* `-aL` or `--grid-low-zooms`: At all zoom levels below _maxzoom_, snap all lines and polygons to a stairstep grid instead of allowing diagonals. You will also want to specify a tile resolution, probably `-D8`. This option provides a way to display continuous parcel, gridded, or binned data at low zooms without overwhelming the tiles with tiny polygons, since features will either get stretched out to the grid unit or lost entirely, depending on how they happened to be aligned in the original data. You probably don't want to use this.
|
||||
|
||||
### Controlling clipping to tile boundaries
|
||||
@@ -567,9 +576,16 @@ the same layer, enclose them in an `all` expression so they will all be evaluate
|
||||
* `-q` or `--quiet`: Work quietly instead of reporting progress or warning messages
|
||||
* `-Q` or `--no-progress-indicator`: Don't report progress, but still give warnings
|
||||
* `-U` _seconds_ or `--progress-interval=`_seconds_: Don't report progress more often than the specified number of _seconds_.
|
||||
* `-u` or `--json-progress`: like `-quiet` but logs progress as a JSON object. Use in combination with `-U`.
|
||||
* `-u` or `--json-progress`: like `--quiet` but logs progress as a JSON object. Use in combination with `-U`.
|
||||
|
||||
### Version
|
||||
|
||||
* `-v` or `--version`: Report Tippecanoe's version number
|
||||
|
||||
### Help
|
||||
|
||||
* `-H` or `--help`: List the available options and exit
|
||||
|
||||
### Filters
|
||||
|
||||
* `-C` _command_ or `--prefilter=`_command_: Specify a shell filter command to be run at the start of assembling each tile
|
||||
@@ -597,7 +613,7 @@ contain `index`, `sequence`, `extent`, and `dropped`, elements, which must be pa
|
||||
* Make a tileset of the Natural Earth countries to zoom level 5, and also copy the GeoJSON features
|
||||
to files in a `tiles/z/x/y.geojson` directory hierarchy.
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o countries.mbtiles -z5 -C 'mkdir -p tiles/$1/$2; tee tiles/$1/$2/$3.geojson' ne_10m_admin_0_countries.json
|
||||
```
|
||||
|
||||
@@ -605,13 +621,13 @@ tippecanoe -o countries.mbtiles -z5 -C 'mkdir -p tiles/$1/$2; tee tiles/$1/$2/$3
|
||||
intersect the [bounding box of Germany](https://www.flickr.com/places/info/23424829).
|
||||
(The `limit-tiles-to-bbox` script is [in the Tippecanoe source directory](filters/limit-tiles-to-bbox).)
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o countries.mbtiles -z5 -C './filters/limit-tiles-to-bbox 5.8662 47.2702 15.0421 55.0581 $*' ne_10m_admin_0_countries.json
|
||||
```
|
||||
|
||||
* Make a tileset of TIGER roads in Tippecanoe County, leaving out all but primary and secondary roads (as [classified by TIGER](https://www.census.gov/geo/reference/mtfcc.html)) below zoom level 11.
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o roads.mbtiles -c 'if [ $1 -lt 11 ]; then grep "\"MTFCC\": \"S1[12]00\""; else cat; fi' tl_2016_18157_roads.json
|
||||
```
|
||||
|
||||
@@ -628,7 +644,7 @@ Tippecanoe defines a GeoJSON extension that you can use to specify the minimum a
|
||||
at which an individual feature will be included in the vector tileset being produced.
|
||||
If you have a feature like this:
|
||||
|
||||
```
|
||||
```json
|
||||
{
|
||||
"type" : "Feature",
|
||||
"tippecanoe" : { "maxzoom" : 9, "minzoom" : 4 },
|
||||
@@ -640,7 +656,7 @@ If you have a feature like this:
|
||||
}
|
||||
```
|
||||
|
||||
with a `tippecanoe` object specifiying a `maxzoom` of 9 and a `minzoom` of 4, the feature
|
||||
with a `tippecanoe` object specifying a `maxzoom` of 9 and a `minzoom` of 4, the feature
|
||||
will only appear in the vector tiles for zoom levels 4 through 9. Note that the `tippecanoe`
|
||||
object belongs to the Feature, not to its `properties`. If you specify a `minzoom` for a feature,
|
||||
it will be preserved down to that zoom level even if dot-dropping with `-r` would otherwise have
|
||||
@@ -649,7 +665,7 @@ dropped it.
|
||||
You can also specify a layer name in the `tippecanoe` object, which will take precedence over
|
||||
the filename or name specified using `--layer`, like this:
|
||||
|
||||
```
|
||||
```json
|
||||
{
|
||||
"type" : "Feature",
|
||||
"tippecanoe" : { "layer" : "streets" },
|
||||
@@ -673,11 +689,11 @@ Geometric simplifications
|
||||
At every zoom level, line and polygon features are subjected to Douglas-Peucker
|
||||
simplification to the resolution of the tile.
|
||||
|
||||
For point features, it drops 1/2.5 of the dots for each zoom level above the
|
||||
For point features, it keeps only 1/2.5 of the dots for each zoom level below the
|
||||
point base zoom (which is normally the same as the `-z` max zoom, but can be
|
||||
a different zoom specified with `-B` if you have precise but sparse data).
|
||||
I don't know why 2.5 is the appropriate number, but the densities of many different
|
||||
data sets fall off at about this same rate. You can use -r to specify a different rate.
|
||||
data sets fall off at about this same rate. You can use `-r` to specify a different rate.
|
||||
|
||||
You can use the gamma option to thin out especially dense clusters of points.
|
||||
For any area where dots are closer than one pixel together (at whatever zoom level),
|
||||
@@ -703,8 +719,13 @@ lower resolutions before failing if it still doesn't fit.
|
||||
Development
|
||||
-----------
|
||||
|
||||
Requires sqlite3 and zlib (should already be installed on MacOS). Rebuilding the manpage
|
||||
uses md2man (`gem install md2man`).
|
||||
Requires sqlite3 and zlib (should already be installed on MacOS).
|
||||
|
||||
The manpage is generated from this README by `make docs`, which uses
|
||||
[go-md2man](https://github.com/cpuguy83/go-md2man) (`brew install go-md2man` or
|
||||
`apt-get install go-md2man`). You don't have to run it yourself: CI regenerates the
|
||||
manpage and fails if the committed copy doesn't match, so it will tell you if an
|
||||
edit here needs `make docs` run against it.
|
||||
|
||||
Linux:
|
||||
|
||||
@@ -718,15 +739,16 @@ and perhaps
|
||||
|
||||
make install
|
||||
|
||||
Tippecanoe now requires features from the 2011 C++ standard. If your compiler is older than
|
||||
that, you will need to install a newer one. On MacOS, updating to the lastest XCode should
|
||||
get you a new enough version of `clang++`. On Linux, you should be able to upgrade `g++` with
|
||||
Tippecanoe requires features from the 2017 C++ standard (it is built with `-std=c++17`).
|
||||
If your compiler is older than that, you will need to install a newer one. On MacOS, updating
|
||||
to the latest XCode should get you a new enough version of `clang++`. On Linux, you should be
|
||||
able to upgrade `g++` with
|
||||
|
||||
```
|
||||
```sh
|
||||
sudo add-apt-repository -y ppa:ubuntu-toolchain-r/test
|
||||
sudo apt-get update -y
|
||||
sudo apt-get install -y g++-5
|
||||
export CXX=g++-5
|
||||
sudo apt-get install -y g++-9
|
||||
export CXX=g++-9
|
||||
```
|
||||
|
||||
Docker Image
|
||||
@@ -779,11 +801,14 @@ The options are:
|
||||
* `-o` *out.mbtiles*, *out.pmtiles* or `--output=`*out.mbtiles*: Write the new tiles to the specified .mbtiles file.
|
||||
* `-e` *directory* or `--output-to-directory=`*directory*: Write the new tiles to the specified directory instead of to an mbtiles file.
|
||||
* `-f` or `--force`: Remove *out.mbtiles* if it already exists.
|
||||
* `-r` or `--read-from`: list of input mbtiles to read from.
|
||||
|
||||
### Input tilesets
|
||||
|
||||
* `-r` *file* or `--read-from=`*file*: Read the list of input tilesets from the named *file*, one filename per line, instead of naming them all on the command line.
|
||||
|
||||
### Overzooming
|
||||
|
||||
* `--overzoom`: If one of the source tilesets has a larger maxzoom than the others, scale up tiles from the tilesets with the lower maxzooms so they will all have the same maxzoom in the output tileset.
|
||||
* `-O` or `--overzoom`: If one of the source tilesets has a larger maxzoom than the others, scale up tiles from the tilesets with the lower maxzooms so they will all have the same maxzoom in the output tileset.
|
||||
* `--buffer=`_pixels_ or `-b` _pixels_: Set the size of the tile buffer in the overzoomed tiles.
|
||||
|
||||
### Tileset description and attribution
|
||||
@@ -812,6 +837,8 @@ The options are:
|
||||
* `-x` *key* or `--exclude=`*key*: Remove attributes named *key* from the output. You can use this to remove the field you are matching against if you no longer need it after joining, or to remove any other attributes you don't want. You can use multiple `-x` options to remove multiple attributes.
|
||||
* `-X` or `--exclude-all`: Remove all attributes from the output.
|
||||
* `-y` *key* or `--include=`*key*: Remove all attributes except for those named *key* from the output. You can use multiple `-y` options to retain multiple attributes.
|
||||
* `--exclude-all-tile-attributes`: Remove the attributes that were already present in the source tiles, keeping only any that are joined from a CSV with `-c`.
|
||||
* `--exclude-all-tile-geometries`: Copy the features' attributes but not their geometries, so the output tiles describe the features without locating them.
|
||||
* `-i` or `--if-matched`: Only include features that matched the CSV.
|
||||
* `-j` *filter* or `--feature-filter`=*filter*: Check features against a per-layer filter (as defined in the [Mapbox GL Style Specification](https://docs.mapbox.com/mapbox-gl-js/style-spec/#other-filter)) and only include those that match. Any features in layers that have no filter specified will be passed through. Filters for the layer `"*"` apply to all layers.
|
||||
* `-J` *filter-file* or `--feature-filter-file`=*filter-file*: Like `-j`, but read the filter from a file.
|
||||
@@ -826,6 +853,10 @@ The options are:
|
||||
* `--tile-stats-sample-values-limit=`*count*: Calculate `tilestats` attribute statistics based on *count* values instead of the default 1000.
|
||||
* `--tile-stats-values-limit=`*count*: Report *count* unique attribute values in `tilestats` instead of the default 100.
|
||||
|
||||
### Progress indicator
|
||||
|
||||
* `-q` or `--quiet`: Work quietly instead of reporting progress
|
||||
|
||||
Because tile-join just copies the geometries to the new .mbtiles without processing them
|
||||
(except to rescale the extents if necessary),
|
||||
it doesn't have any of tippecanoe's recourses if the new tiles are bigger than the 500K tile limit.
|
||||
@@ -858,7 +889,7 @@ awk 'BEGIN {
|
||||
|
||||
which looks like this:
|
||||
|
||||
```
|
||||
```csv
|
||||
GEOID10,population
|
||||
"060014277003018",0
|
||||
"060014283014046",0
|
||||
@@ -916,8 +947,10 @@ resolutions.
|
||||
* `-c` or `--tag-layer-and-zoom`: Include each feature's layer and zoom level as part of its `tippecanoe` object rather than as a FeatureCollection wrapper
|
||||
* `-S` or `--stats`: Just report statistics about each tile's size and the number of features in it, as a JSON structure.
|
||||
* `-f` or `--force`: Decode tiles even if polygon ring order or closure problems are detected
|
||||
* `-I` or `--integer`: Report coordinates in integer tile coordinates
|
||||
* `-F` or `--fraction`: Report coordinates as a fraction of the tile extent
|
||||
* `-I` or `--integer-coordinates`: Report coordinates in integer tile coordinates
|
||||
* `-F` or `--fractional-coordinates`: Report coordinates as a fraction of the tile extent
|
||||
* `-y` _attribute_ or `--include=`*attribute*: Include only the named attributes in the decoded features, excluding all those not explicitly named. (Multiple `-y` options can be specified.)
|
||||
* `-x` _name_ or `--exclude-metadata-row=`*name*: Omit the named row from the tileset metadata in the output. (Multiple `-x` options can be specified.)
|
||||
|
||||
tippecanoe-json-tool
|
||||
====================
|
||||
@@ -956,7 +989,7 @@ for Tippecanoe County, Indiana.
|
||||
|
||||
Download Census block geometry, and convert to GeoJSON:
|
||||
|
||||
```
|
||||
```sh
|
||||
$ curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/TABBLOCK/2010/tl_2010_18157_tabblock10.zip
|
||||
$ unzip tl_2010_18157_tabblock10.zip
|
||||
$ ogr2ogr -f GeoJSON tl_2010_18157_tabblock10.json tl_2010_18157_tabblock10.shp
|
||||
@@ -964,7 +997,7 @@ $ ogr2ogr -f GeoJSON tl_2010_18157_tabblock10.json tl_2010_18157_tabblock10.shp
|
||||
|
||||
Download Indiana employment data, and fix name of join key in header
|
||||
|
||||
```
|
||||
```sh
|
||||
$ curl -L -O https://lehd.ces.census.gov/data/lodes/LODES7/in/wac/in_wac_S000_JT00_2015.csv.gz
|
||||
$ gzip -dc in_wac_S000_JT00_2015.csv.gz | sed '1s/w_geocode/GEOID10/' > in_wac_S000_JT00_2015.csv
|
||||
```
|
||||
@@ -972,13 +1005,13 @@ $ gzip -dc in_wac_S000_JT00_2015.csv.gz | sed '1s/w_geocode/GEOID10/' > in_wac_S
|
||||
Sort GeoJSON block geometry so it is ordered by block ID. If you don't do this, you will get a
|
||||
"GeoJSON file is out of sort" error.
|
||||
|
||||
```
|
||||
```sh
|
||||
$ tippecanoe-json-tool -e GEOID10 tl_2010_18157_tabblock10.json | LC_ALL=C sort > tl_2010_18157_tabblock10.sort.json
|
||||
```
|
||||
|
||||
Join block geometries to employment attributes:
|
||||
|
||||
```
|
||||
```sh
|
||||
$ tippecanoe-json-tool -c in_wac_S000_JT00_2015.csv tl_2010_18157_tabblock10.sort.json > blocks-wac.json
|
||||
```
|
||||
|
||||
@@ -1004,10 +1037,19 @@ and produces tile `outz/outx/outy` of `out.mvt.gz` from them.
|
||||
|
||||
### Options
|
||||
|
||||
* `-b` *buffer*: Set the tile buffer in the output tile (default 5)
|
||||
* `-d` *detail*: Set the detail of the output tile (default 12)
|
||||
* `-y` *attribute*: Retain the specified *attribute* in the output features. All attributes that are not named in a `-y` option will be removed.
|
||||
* `-j` *filter*: Filter features using the same expression syntax as in tippecanoe.
|
||||
* `-m`: If a tile was created with the `--retain-points-multiplier` option, thin the tile back down to its normal feature count during overzooming. The first feature from each cluster will be retained, unless `-j` is used to specify a filter, in which case the first matching filter from each cluster will be retained instead.
|
||||
* `-o` *file* or `--output=`*file*: Write the output tile to the named *file*.
|
||||
* `-t` _zoom_`/`_x_`/`_y_ or `--source-tile=`_zoom_`/`_x_`/`_y_: Specify the coordinates of the tile to produce, so that several input tiles, each followed by its own _zoom_`/`_x_`/`_y_, can be combined into it, as in the second example above.
|
||||
* `-b` *buffer* or `--buffer=`*buffer*: Set the tile buffer in the output tile (default 5)
|
||||
* `-d` *detail* or `--full-detail=`*detail*: Set the detail of the output tile (default 12)
|
||||
* `-y` *attribute* or `--include=`*attribute*: Retain the specified *attribute* in the output features. All attributes that are not named in a `-y` option will be removed.
|
||||
* `-x` *attribute* or `--exclude=`*attribute*: Remove the specified *attribute* from the output features.
|
||||
* `--exclude-prefix=`*prefix*: Remove any attribute whose name begins with the specified *prefix* from the output features.
|
||||
* `-j` *filter* or `--feature-filter=`*filter*: Filter features using the same expression syntax as in tippecanoe.
|
||||
* `-J` *filter-file* or `--feature-filter-file=`*filter-file*: Like `-j`, but read the filter from a file.
|
||||
* `-m` or `--filter-points-multiplier`: If a tile was created with the `--retain-points-multiplier` option, thin the tile back down to its normal feature count during overzooming. The first feature from each cluster will be retained, unless `-j` is used to specify a filter, in which case the first matching filter from each cluster will be retained instead.
|
||||
* `-S` *scale* or `--line-simplification=`*scale*: Simplify lines and polygons in the output tile, multiplying the standard tolerance by *scale*. The default of 0 means not to simplify at all.
|
||||
* `--tiny-polygon-size=`*size*: Combine the area of very small polygons into small squares of the specified *size* that represent their combined area, as `tippecanoe` does. The default of 0 means not to do tiny polygon reduction at all.
|
||||
* `--deduplicate-by-id`: When several input tiles are combined, include only the first feature with any given feature ID within each layer, so that features that appear in more than one input tile are not duplicated in the output.
|
||||
* `--preserve-input-order`: Restore a set of filtered features to its original input order
|
||||
* `--accumulate-attribute`: Behaves as in `tippecanoe` to sum attributes from the features of a multiplier cluster that are not included in the final output. The attributes from features that are filtered away with `-j` are *not* accumulated onto the output feature.
|
||||
* `-E` *attribute*`:`*operation* or `--accumulate-attribute=`*attribute*`:`*operation*: Behaves as in `tippecanoe` to sum attributes from the features of a multiplier cluster that are not included in the final output. The attributes from features that are filtered away with `-j` are *not* accumulated onto the output feature.
|
||||
* `--no-tile-compression`: Don't compress the PBF vector tile data in the output tile.
|
||||
|
||||
+29
-50
@@ -42,10 +42,10 @@ void set_attribute_accum(std::unordered_map<std::string, attribute_op> &attribut
|
||||
|
||||
void set_attribute_accum(std::unordered_map<std::string, attribute_op> &attribute_accum, const char *arg, char **argv) {
|
||||
if (*arg == '{') {
|
||||
json_pull *jp = json_begin_string(arg);
|
||||
json_object *o = json_read_tree(jp);
|
||||
json_pull_ptr jp = json_begin_string(arg);
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
if (o == NULL) {
|
||||
if (o == nullptr) {
|
||||
fprintf(stderr, "%s: -E%s: %s\n", *argv, arg, jp->error);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
@@ -55,24 +55,21 @@ void set_attribute_accum(std::unordered_map<std::string, attribute_op> &attribut
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
for (size_t i = 0; i < o->value.object.length; i++) {
|
||||
json_object *k = o->value.object.keys[i];
|
||||
json_object *v = o->value.object.values[i];
|
||||
for (size_t i = 0; i < o->entries().size(); i++) {
|
||||
const auto &e = o->entries()[i];
|
||||
|
||||
if (k->type != JSON_STRING) {
|
||||
if (e.key->type != JSON_STRING) {
|
||||
fprintf(stderr, "%s: -E%s: key %zu not a string\n", *argv, arg, i);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
if (v->type != JSON_STRING) {
|
||||
if (e.value->type != JSON_STRING) {
|
||||
fprintf(stderr, "%s: -E%s: value %zu not a string\n", *argv, arg, i);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
set_attribute_accum(attribute_accum, k->value.string.string, v->value.string.string);
|
||||
set_attribute_accum(attribute_accum, e.key->string(), e.value->string());
|
||||
}
|
||||
|
||||
json_free(o);
|
||||
json_end(jp);
|
||||
return;
|
||||
}
|
||||
|
||||
@@ -89,7 +86,7 @@ void set_attribute_accum(std::unordered_map<std::string, attribute_op> &attribut
|
||||
}
|
||||
|
||||
template <class T>
|
||||
static void preserve_attribute1(attribute_op const &op, std::string const &key, T const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<T> &full_values, std::unordered_map<std::string, accum_state> &attribute_accum_state, key_pool &key_pool) {
|
||||
static void preserve_attribute1(attribute_op const &op, std::string const &key, T const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<T> &full_values, key_pool &key_pool) {
|
||||
for (size_t i = 0; i < full_keys.size(); i++) {
|
||||
if (key == *full_keys[i]) {
|
||||
switch (op) {
|
||||
@@ -120,19 +117,13 @@ static void preserve_attribute1(attribute_op const &op, std::string const &key,
|
||||
}
|
||||
|
||||
case op_mean: {
|
||||
auto state = attribute_accum_state.find(key);
|
||||
if (state == attribute_accum_state.end()) {
|
||||
accum_state s;
|
||||
s.sum = full_values[i].to_double() + val.to_double();
|
||||
s.count = 2;
|
||||
attribute_accum_state.insert(std::pair<std::string, accum_state>(key, s));
|
||||
|
||||
full_values[i] = (s.sum / s.count);
|
||||
size_t count = full_values[i].get_count();
|
||||
if (count <= 1) {
|
||||
full_values[i].set_double_count((full_values[i].to_double() + val.to_double()) / 2, 2);
|
||||
} else {
|
||||
state->second.sum += val.to_double();
|
||||
state->second.count += 1;
|
||||
|
||||
full_values[i] = (state->second.sum / state->second.count);
|
||||
double sum = full_values[i].to_double() * count + val.to_double();
|
||||
count++;
|
||||
full_values[i].set_double_count(sum / count, count);
|
||||
}
|
||||
return;
|
||||
}
|
||||
@@ -146,16 +137,11 @@ static void preserve_attribute1(attribute_op const &op, std::string const &key,
|
||||
return;
|
||||
|
||||
case op_count: {
|
||||
auto state = attribute_accum_state.find(key);
|
||||
if (state == attribute_accum_state.end()) { // not already present
|
||||
accum_state s;
|
||||
s.count = 2;
|
||||
attribute_accum_state.insert(std::pair<std::string, accum_state>(key, s));
|
||||
|
||||
full_values[i] = (s.count);
|
||||
} else { // already present, incrementing
|
||||
state->second.count += 1;
|
||||
full_values[i] = (state->second.count);
|
||||
size_t count = full_values[i].get_count();
|
||||
if (count <= 1) {
|
||||
full_values[i].set_double_count(2, 2);
|
||||
} else {
|
||||
full_values[i].set_double_count(count + 1, count + 1);
|
||||
}
|
||||
return;
|
||||
}
|
||||
@@ -173,20 +159,13 @@ static void preserve_attribute1(attribute_op const &op, std::string const &key,
|
||||
v = val;
|
||||
break;
|
||||
|
||||
case op_count: {
|
||||
auto state = attribute_accum_state.find(key);
|
||||
if (state == attribute_accum_state.end()) { // not already present
|
||||
accum_state s;
|
||||
s.count = 1;
|
||||
attribute_accum_state.insert(std::pair<std::string, accum_state>(key, s));
|
||||
case op_count:
|
||||
v.set_double_count(1, 1);
|
||||
break;
|
||||
|
||||
v = (s.count);
|
||||
} else { // already present, incrementing
|
||||
fprintf(stderr, "preserve_attribute: can't happen (count)\n");
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
case op_mean:
|
||||
v.set_double_count(val.to_double(), 1);
|
||||
break;
|
||||
}
|
||||
|
||||
default:
|
||||
fprintf(stderr, "can't happen: operation that isn't used by --accumulate-numeric-attributes\n");
|
||||
@@ -197,10 +176,10 @@ static void preserve_attribute1(attribute_op const &op, std::string const &key,
|
||||
full_values.push_back(v);
|
||||
}
|
||||
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, mvt_value const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<mvt_value> &full_values, std::unordered_map<std::string, accum_state> &attribute_accum_state, key_pool &key_pool) {
|
||||
preserve_attribute1(op, key, val, full_keys, full_values, attribute_accum_state, key_pool);
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, mvt_value const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<mvt_value> &full_values, key_pool &key_pool) {
|
||||
preserve_attribute1(op, key, val, full_keys, full_values, key_pool);
|
||||
}
|
||||
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, serial_val const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<serial_val> &full_values, std::unordered_map<std::string, accum_state> &attribute_accum_state, key_pool &key_pool) {
|
||||
preserve_attribute1(op, key, val, full_keys, full_values, attribute_accum_state, key_pool);
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, serial_val const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<serial_val> &full_values, key_pool &key_pool) {
|
||||
preserve_attribute1(op, key, val, full_keys, full_values, key_pool);
|
||||
}
|
||||
|
||||
+2
-7
@@ -19,19 +19,14 @@ enum attribute_op {
|
||||
op_count,
|
||||
};
|
||||
|
||||
struct accum_state {
|
||||
double sum = 0;
|
||||
double count = 0;
|
||||
};
|
||||
|
||||
struct serial_val;
|
||||
struct key_pool;
|
||||
|
||||
void set_attribute_accum(std::unordered_map<std::string, attribute_op> &attribute_accum, std::string name, std::string type);
|
||||
void set_attribute_accum(std::unordered_map<std::string, attribute_op> &attribute_accum, const char *arg, char **argv);
|
||||
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, serial_val const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<serial_val> &full_values, std::unordered_map<std::string, accum_state> &attribute_accum_state, key_pool &key_pool);
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, mvt_value const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<mvt_value> &full_values, std::unordered_map<std::string, accum_state> &attribute_accum_state, key_pool &key_pool);
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, serial_val const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<serial_val> &full_values, key_pool &key_pool);
|
||||
void preserve_attribute(attribute_op const &op, std::string const &key, mvt_value const &val, std::vector<std::shared_ptr<std::string>> &full_keys, std::vector<mvt_value> &full_values, key_pool &key_pool);
|
||||
|
||||
extern std::map<std::string, attribute_op> numeric_operations;
|
||||
|
||||
|
||||
@@ -571,8 +571,7 @@ drawvec remove_noop(drawvec geom, int type, int shift) {
|
||||
}
|
||||
|
||||
if (geom[i + 1].op == VT_CLOSEPATH) {
|
||||
// followed by closepath: not possible
|
||||
fprintf(stderr, "Shouldn't happen\n");
|
||||
// followed by closepath: only possible after close_poly()
|
||||
i++; // also remove unused closepath
|
||||
continue;
|
||||
}
|
||||
@@ -1215,47 +1214,6 @@ bool pnpoly_mp(drawvec const &geom, long long x, long long y) {
|
||||
return found;
|
||||
}
|
||||
|
||||
clipbbox parse_clip_poly(std::string arg) {
|
||||
json_pull *jp = json_begin_string(arg.c_str());
|
||||
json_object *j = json_read_tree(jp);
|
||||
if (j == NULL) {
|
||||
fprintf(stderr, "Expected JSON object, not %s\n", arg.c_str());
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
if (j->type != JSON_HASH) {
|
||||
fprintf(stderr, "Expected JSON geometry object, not %s\n", arg.c_str());
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
std::pair<int, drawvec> parsed_geometry = parse_geometry(j, jp, j, 0, 0, 0, 1LL << 32, false, false);
|
||||
json_end(jp);
|
||||
|
||||
clipbbox out;
|
||||
out.minx = LLONG_MAX;
|
||||
out.miny = LLONG_MAX;
|
||||
out.maxx = LLONG_MIN;
|
||||
out.maxy = LLONG_MIN;
|
||||
for (auto const &d : parsed_geometry.second) {
|
||||
if (d.op == VT_MOVETO || d.op == VT_LINETO) {
|
||||
if (d.x < out.minx) {
|
||||
out.minx = d.x;
|
||||
}
|
||||
if (d.y < out.miny) {
|
||||
out.miny = d.y;
|
||||
}
|
||||
if (d.x > out.maxx) {
|
||||
out.maxx = d.x;
|
||||
}
|
||||
if (d.y > out.maxy) {
|
||||
out.maxy = d.y;
|
||||
}
|
||||
}
|
||||
}
|
||||
out.dv = std::move(parsed_geometry.second);
|
||||
|
||||
return out;
|
||||
}
|
||||
|
||||
std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int ny,
|
||||
int detail_or_unspecified, int buffer,
|
||||
std::set<std::string> const &keep,
|
||||
@@ -1267,9 +1225,10 @@ std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int n
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::vector<std::string> const &unidecode_data, double simplification,
|
||||
double tiny_polygon_size,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
std::string const &accumulate_numeric, size_t feature_limit,
|
||||
std::vector<clipbbox> const &clipbboxes) {
|
||||
std::vector<mvt_layer> const &unused2, std::string const &unused3,
|
||||
std::string const &unused, size_t feature_limit,
|
||||
std::vector<clipbbox> const &unused4,
|
||||
bool deduplicate_by_id) {
|
||||
std::vector<source_tile> decoded;
|
||||
|
||||
for (auto const &t : tiles) {
|
||||
@@ -1295,7 +1254,7 @@ std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int n
|
||||
decoded.push_back(out);
|
||||
}
|
||||
|
||||
return overzoom(decoded, nz, nx, ny, detail_or_unspecified, buffer, keep, exclude, exclude_prefix, do_compress, next_overzoomed_tiles, demultiply, filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, bins, bin_by_id_list, accumulate_numeric, feature_limit, clipbboxes);
|
||||
return overzoom(decoded, nz, nx, ny, detail_or_unspecified, buffer, keep, exclude, exclude_prefix, do_compress, next_overzoomed_tiles, demultiply, filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, unused2, unused3, unused, feature_limit, unused4, deduplicate_by_id);
|
||||
}
|
||||
|
||||
// like a minimal serial_feature, but with mvt_feature-style attributes
|
||||
@@ -1330,153 +1289,6 @@ static bool should_keep(std::string const &key,
|
||||
return false;
|
||||
}
|
||||
|
||||
static void add_mean(mvt_feature &feature, mvt_layer &layer, std::string const &accumulate_numeric,
|
||||
std::set<std::string> const &keep, std::set<std::string> const &exclude,
|
||||
std::vector<std::string> const &exclude_prefix) {
|
||||
std::string accumulate_numeric_colon = accumulate_numeric + ":";
|
||||
|
||||
std::unordered_map<std::string, size_t> attributes;
|
||||
for (size_t i = 0; i + 1 < feature.tags.size(); i += 2) {
|
||||
std::string const &key = layer.keys[feature.tags[i]];
|
||||
if (starts_with(key, accumulate_numeric_colon)) {
|
||||
attributes.emplace(key, i);
|
||||
}
|
||||
}
|
||||
|
||||
for (size_t i = 0; i + 1 < feature.tags.size(); i += 2) {
|
||||
std::string accumulate_numeric_sum_colon = accumulate_numeric + ":sum:";
|
||||
|
||||
std::string const &key = layer.keys[feature.tags[i]];
|
||||
if (starts_with(key, accumulate_numeric_sum_colon)) {
|
||||
std::string trunc = key.substr(accumulate_numeric_sum_colon.size());
|
||||
auto const f = attributes.find(accumulate_numeric + ":count:" + trunc);
|
||||
if (f != attributes.end()) {
|
||||
mvt_value const &sum = layer.values[feature.tags[i + 1]];
|
||||
mvt_value const &count = layer.values[feature.tags[f->second + 1]];
|
||||
double count_val = mvt_value_to_double(count);
|
||||
if (count_val <= 0) {
|
||||
fprintf(stderr, "can't happen: count is %s (type %d)\n", count.toString().c_str(), count.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
mvt_value mean;
|
||||
mean.type = mvt_double;
|
||||
mean.numeric_value.double_value = mvt_value_to_double(sum) / count_val;
|
||||
|
||||
if (should_keep(key, keep, exclude, exclude_prefix)) {
|
||||
layer.tag(feature, accumulate_numeric + ":mean:" + trunc, mean);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
// accumulate :sum:, :min:, :max:, and :count: versions of the specified attribute
|
||||
static void preserve_numeric(const std::string &key, const mvt_value &val, // numeric attribute being accumulated
|
||||
std::vector<std::shared_ptr<std::string>> &full_keys, // keys of feature being accumulated onto
|
||||
std::vector<mvt_value> &full_values, // values of features being accumulated onto
|
||||
const std::string &accumulate_numeric, // prefix of accumulations
|
||||
std::set<std::string> &keys, // key presence in the source feature
|
||||
std::map<std::string, size_t> &numeric_out_field, // key index in the output feature
|
||||
std::unordered_map<std::string, accum_state> &attribute_accum_state, // accumulation state for preserve_attribute()
|
||||
key_pool &key_pool,
|
||||
std::set<std::string> const &keep, std::set<std::string> const &exclude,
|
||||
std::vector<std::string> const &exclude_prefix) {
|
||||
// If this is a numeric attribute, but there is also a prefix:sum (etc.) for the
|
||||
// same attribute, we want to use that one instead of this one.
|
||||
|
||||
for (auto const &op : numeric_operations) {
|
||||
std::string compound_key = accumulate_numeric + ":" + op.first + ":" + key;
|
||||
auto compound_found = keys.find(compound_key);
|
||||
if (compound_found != keys.end()) {
|
||||
// found, so skip this one
|
||||
} else {
|
||||
// not found, so accumulate this one
|
||||
|
||||
// if this is already prefixed, strip off the prefix
|
||||
// if it is the right one, and skip the attribute if
|
||||
// it is the wrong one.
|
||||
|
||||
std::string outkey = key;
|
||||
bool starting_from_accumulation;
|
||||
|
||||
if (starts_with(outkey, accumulate_numeric + ":")) {
|
||||
std::string prefix = accumulate_numeric + ":" + op.first + ":";
|
||||
if (starts_with(outkey, prefix)) {
|
||||
outkey = outkey.substr(prefix.size());
|
||||
starting_from_accumulation = true; // from a subaccumulation
|
||||
} else {
|
||||
continue; // to next operation
|
||||
}
|
||||
} else {
|
||||
starting_from_accumulation = false; // from a plain value
|
||||
}
|
||||
// and then put it back on for the output field
|
||||
std::string prefixed = accumulate_numeric + ":" + op.first + ":" + outkey;
|
||||
|
||||
if (!should_keep(prefixed, keep, exclude, exclude_prefix)) {
|
||||
continue;
|
||||
}
|
||||
|
||||
// Does it exist in the output feature already?
|
||||
|
||||
auto prefixed_attr = numeric_out_field.find(prefixed);
|
||||
if (prefixed_attr == numeric_out_field.end()) {
|
||||
// No? Does it exist unprefixed in the output feature already?
|
||||
|
||||
auto out_attr = numeric_out_field.find(outkey);
|
||||
if (out_attr == numeric_out_field.end()) {
|
||||
// not present at all, so copy our value to the prefixed output
|
||||
numeric_out_field.emplace(prefixed, full_keys.size());
|
||||
full_keys.push_back(key_pool.pool(prefixed));
|
||||
|
||||
if (op.second == op_count) {
|
||||
if (starting_from_accumulation) {
|
||||
// copy our count
|
||||
full_values.push_back(val);
|
||||
} else {
|
||||
// new count of 1
|
||||
full_values.push_back(mvt_value(1));
|
||||
}
|
||||
} else {
|
||||
full_values.push_back(val);
|
||||
}
|
||||
} else {
|
||||
// exists unprefixed, so copy it, and then accumulate on our value
|
||||
numeric_out_field.emplace(prefixed, full_keys.size());
|
||||
full_keys.push_back(key_pool.pool(prefixed));
|
||||
|
||||
if (op.second == op_count) {
|
||||
mvt_value v;
|
||||
if (starting_from_accumulation) {
|
||||
// sum our count onto the existing 1
|
||||
v = mvt_value(1 + mvt_value_to_long_long(val));
|
||||
} else {
|
||||
// sum our 1 onto the existing 1
|
||||
v = mvt_value(2);
|
||||
}
|
||||
full_values.push_back(v);
|
||||
} else {
|
||||
full_values.push_back(full_values[out_attr->second]);
|
||||
preserve_attribute(op.second, prefixed, val, full_keys, full_values, attribute_accum_state, key_pool);
|
||||
}
|
||||
}
|
||||
} else {
|
||||
// exists, so accumulate on our value
|
||||
if (op.second == op_count) {
|
||||
if (starting_from_accumulation) {
|
||||
// sum our count onto the existing count
|
||||
full_values[prefixed_attr->second] = mvt_value(mvt_value_to_long_long(full_values[prefixed_attr->second]) + mvt_value_to_long_long(val));
|
||||
} else {
|
||||
full_values[prefixed_attr->second] = mvt_value(mvt_value_to_long_long(full_values[prefixed_attr->second]) + 1);
|
||||
}
|
||||
} else {
|
||||
preserve_attribute(op.second, prefixed, val, full_keys, full_values, attribute_accum_state, key_pool);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
static void handle_closepath_from_mvt(drawvec &geom) {
|
||||
// mvt geometries close polygons with a mvt_closepath operation
|
||||
// tippecanoe-internal geometries close polygons with a lineto to the initial point
|
||||
@@ -1498,16 +1310,17 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
std::set<std::string> const &exclude,
|
||||
std::vector<std::string> const &exclude_prefix,
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::string const &accumulate_numeric,
|
||||
std::string const &,
|
||||
key_pool &key_pool, int buffer, bool include_nonaggregate,
|
||||
std::vector<clipbbox> const &clipbboxes, int nz, int nx, int ny) {
|
||||
std::vector<clipbbox> const &, int, int, int,
|
||||
std::set<unsigned long long> *deduplicate_ids) {
|
||||
// Add geometry to output feature
|
||||
|
||||
drawvec geom = features[0].geom;
|
||||
int t = features[0].t;
|
||||
|
||||
bool fix_polygons = false;
|
||||
if ((buffer >= 0 || clipbboxes.size() > 0) && t == VT_POLYGON) {
|
||||
if ((buffer >= 0) && t == VT_POLYGON) {
|
||||
fix_polygons = true;
|
||||
}
|
||||
|
||||
@@ -1528,48 +1341,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
geom = remove_noop(geom, t, 0);
|
||||
}
|
||||
|
||||
if (clipbboxes.size() != 0) {
|
||||
// bounding box is in world coordinates at world scale
|
||||
// feature is in local coordinates at tile scale
|
||||
|
||||
long long dx = (long long) nx << (32 - nz);
|
||||
long long dy = (long long) ny << (32 - nz);
|
||||
double scale = (double) outlayer.extent / (1LL << (32 - nz));
|
||||
|
||||
for (auto const &c_world : clipbboxes) {
|
||||
clipbbox c = c_world;
|
||||
|
||||
c.minx = std::llround((c_world.minx - dx) * scale);
|
||||
c.miny = std::llround((c_world.miny - dy) * scale);
|
||||
c.maxx = std::llround((c_world.maxx - dx) * scale);
|
||||
c.maxy = std::llround((c_world.maxy - dy) * scale);
|
||||
|
||||
for (auto &p : c.dv) {
|
||||
p.x = std::llround((p.x - dx) * scale);
|
||||
p.y = std::llround((p.y - dy) * scale);
|
||||
}
|
||||
|
||||
if (t == VT_POLYGON) {
|
||||
geom = simple_clip_poly(geom, c.minx, c.miny, c.maxx, c.maxy, false);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_poly_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_LINE) {
|
||||
geom = clip_lines(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_lines_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_POINT) {
|
||||
geom = clip_point(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_point_poly(geom, c.dv);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
geom = remove_noop(geom, t, 0);
|
||||
}
|
||||
|
||||
if (fix_polygons) {
|
||||
geom = clean_or_clip_poly(geom, 0, 0, false, false);
|
||||
geom = close_poly(geom);
|
||||
@@ -1583,6 +1354,14 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
|
||||
// ID and attributes, if it didn't get clipped away
|
||||
|
||||
if (features[0].has_id && deduplicate_ids != NULL) {
|
||||
if (deduplicate_ids->find(features[0].id) != deduplicate_ids->end()) {
|
||||
outfeature.geometry.clear();
|
||||
} else {
|
||||
deduplicate_ids->insert(features[0].id);
|
||||
}
|
||||
}
|
||||
|
||||
if (outfeature.geometry.size() > 0) {
|
||||
if (features[0].has_id) {
|
||||
outfeature.has_id = true;
|
||||
@@ -1591,13 +1370,12 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
|
||||
outfeature.seq = features[0].seq;
|
||||
|
||||
if (attribute_accum.size() > 0 || accumulate_numeric.size() > 0) {
|
||||
if (attribute_accum.size() > 0) {
|
||||
// convert the attributes of the output feature
|
||||
// from layer references to a vector so they can have
|
||||
// attributes from the other features of the
|
||||
// multiplier cluster accumulated onto them
|
||||
|
||||
std::unordered_map<std::string, accum_state> attribute_accum_state;
|
||||
std::vector<std::shared_ptr<std::string>> full_keys;
|
||||
std::vector<mvt_value> full_values;
|
||||
std::map<std::string, size_t> numeric_out_field;
|
||||
@@ -1610,11 +1388,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
// this attribute has an accumulator, so convert it
|
||||
full_keys.push_back(key_pool.pool(f.layer->keys[f.tags[i]]));
|
||||
full_values.push_back(f.layer->values[f.tags[i + 1]]);
|
||||
} else if (accumulate_numeric.size() > 0 && f.layer->values[f.tags[i + 1]].is_numeric()) {
|
||||
// convert numeric for accumulation
|
||||
numeric_out_field.emplace(key, full_keys.size());
|
||||
full_keys.push_back(key_pool.pool(key));
|
||||
full_values.push_back(f.layer->values[f.tags[i + 1]]);
|
||||
} else if (include_nonaggregate) {
|
||||
// otherwise just tag it directly onto the output feature
|
||||
outlayer.tag(outfeature, f.layer->keys[f.tags[i]], f.layer->values[f.tags[i + 1]]);
|
||||
@@ -1642,15 +1415,7 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
auto found = attribute_accum.find(key);
|
||||
if (found != attribute_accum.end()) {
|
||||
mvt_value val = features[i].layer->values[features[i].tags[j + 1]];
|
||||
preserve_attribute(found->second, key, val, full_keys, full_values, attribute_accum_state, key_pool);
|
||||
} else if (accumulate_numeric.size() > 0) {
|
||||
const mvt_value &val = features[i].layer->values[features[i].tags[j + 1]];
|
||||
if (val.is_numeric()) {
|
||||
preserve_numeric(key, val, full_keys, full_values,
|
||||
accumulate_numeric,
|
||||
keys, numeric_out_field, attribute_accum_state, key_pool,
|
||||
keep, exclude, exclude_prefix);
|
||||
}
|
||||
preserve_attribute(found->second, key, val, full_keys, full_values, key_pool);
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1664,10 +1429,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
outlayer.tag(outfeature, *full_keys[i], full_values[i]);
|
||||
}
|
||||
}
|
||||
|
||||
if (accumulate_numeric.size() > 0) {
|
||||
add_mean(outfeature, outlayer, accumulate_numeric, keep, exclude, exclude_prefix);
|
||||
}
|
||||
} else if (include_nonaggregate) {
|
||||
for (size_t i = 0; i + 1 < features[0].tags.size(); i += 2) {
|
||||
if (should_keep(features[0].layer->keys[features[0].tags[i]], keep, exclude, exclude_prefix)) {
|
||||
@@ -1689,316 +1450,6 @@ static struct preservecmp {
|
||||
}
|
||||
} preservecmp;
|
||||
|
||||
struct index_event {
|
||||
unsigned long long where;
|
||||
enum index_event_kind {
|
||||
ENTER = 0, // new bin in is now active
|
||||
CHECK, // point needs to be checked against active bins
|
||||
EXIT // bin has ceased to be active
|
||||
} kind;
|
||||
size_t layer;
|
||||
size_t feature;
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
|
||||
index_event(unsigned long long where_, index_event_kind kind_, size_t layer_, size_t feature_,
|
||||
long long xmin_, long long ymin_, long long xmax_, long long ymax_)
|
||||
: where(where_), kind(kind_), layer(layer_), feature(feature_), xmin(xmin_), ymin(ymin_), xmax(xmax_), ymax(ymax_) {
|
||||
}
|
||||
|
||||
bool operator<(const index_event &ie) const {
|
||||
if (where < ie.where) {
|
||||
return true;
|
||||
} else if (where == ie.where) {
|
||||
if (kind < ie.kind) {
|
||||
return true;
|
||||
} else if (kind == ie.kind) {
|
||||
if (layer < ie.layer) {
|
||||
return true;
|
||||
} else if (layer == ie.layer) {
|
||||
if (feature < ie.feature) {
|
||||
return true;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return false;
|
||||
}
|
||||
};
|
||||
|
||||
struct active_bin {
|
||||
size_t layer;
|
||||
size_t feature;
|
||||
|
||||
active_bin(size_t layer_, size_t feature_)
|
||||
: layer(layer_), feature(feature_) {
|
||||
}
|
||||
|
||||
bool operator<(const active_bin &o) const {
|
||||
if (layer < o.layer) {
|
||||
return true;
|
||||
} else if (layer == o.layer) {
|
||||
if (feature < o.feature) {
|
||||
return true;
|
||||
}
|
||||
}
|
||||
|
||||
return false;
|
||||
}
|
||||
|
||||
size_t outfeature;
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
size_t counter = 0;
|
||||
};
|
||||
|
||||
void get_quadkey_bounds(long long xmin, long long ymin, long long xmax, long long ymax,
|
||||
unsigned long long *start, unsigned long long *end) {
|
||||
if (xmin < 0 || ymin < 0 || xmax >= 1LL << 32 || ymax >= 1LL << 32) {
|
||||
*start = 0;
|
||||
*end = ULLONG_MAX;
|
||||
return;
|
||||
}
|
||||
|
||||
*start = encode_quadkey(xmin, ymin);
|
||||
*end = encode_quadkey(xmax, ymax);
|
||||
|
||||
for (ssize_t i = 62; i >= 0; i -= 2) {
|
||||
if ((*start & (3LL << i)) != (*end & (3LL << i))) {
|
||||
for (; i >= 0; i -= 2) {
|
||||
*start &= ~(3LL << i);
|
||||
*end |= 3LL << i;
|
||||
}
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
static bool bbox_intersects(long long x1min, long long y1min, long long x1max, long long y1max,
|
||||
long long x2min, long long y2min, long long x2max, long long y2max) {
|
||||
if (x1max < x2min) {
|
||||
return false;
|
||||
}
|
||||
if (x2max < x1min) {
|
||||
return false;
|
||||
}
|
||||
if (y1max < y2min) {
|
||||
return false;
|
||||
}
|
||||
if (y2max < y1min) {
|
||||
return false;
|
||||
}
|
||||
return true;
|
||||
}
|
||||
|
||||
static std::vector<size_t> parse_ids_string(mvt_value const &v) {
|
||||
std::vector<size_t> out;
|
||||
std::string s = v.toString();
|
||||
|
||||
for (size_t i = 0; i < s.size(); i++) {
|
||||
if (i == 0 || s[i - 1] == ',') {
|
||||
out.push_back(atoll(s.c_str() + i));
|
||||
}
|
||||
}
|
||||
|
||||
return out;
|
||||
}
|
||||
|
||||
mvt_tile assign_to_bins(mvt_tile &features,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
int z, int x, int y,
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::string const &accumulate_numeric,
|
||||
std::set<std::string> keep,
|
||||
std::set<std::string> exclude,
|
||||
std::vector<std::string> exclude_prefix,
|
||||
int buffer, std::vector<clipbbox> const &clipbboxes) {
|
||||
std::vector<index_event> events;
|
||||
key_pool key_pool;
|
||||
|
||||
if (bins.size() == 0) {
|
||||
return mvt_tile();
|
||||
}
|
||||
|
||||
// Index bins
|
||||
for (size_t i = 0; i < bins.size(); i++) {
|
||||
for (size_t j = 0; j < bins[i].features.size(); j++) {
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
unsigned long long start, end;
|
||||
|
||||
get_bbox(bins[i].features[j].geometry, &xmin, &ymin, &xmax, &ymax, z, x, y, bins[i].detail());
|
||||
get_quadkey_bounds(xmin, ymin, xmax, ymax, &start, &end);
|
||||
events.emplace_back(start, index_event::ENTER, i, j, xmin, ymin, xmax, ymax);
|
||||
events.emplace_back(end, index_event::EXIT, i, j, xmin, ymin, xmax, ymax);
|
||||
}
|
||||
}
|
||||
|
||||
std::map<unsigned long long, std::pair<size_t, size_t>> fid_to_feature;
|
||||
|
||||
// Index points
|
||||
for (size_t i = 0; i < features.layers.size(); i++) {
|
||||
for (size_t j = 0; j < features.layers[i].features.size(); j++) {
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
unsigned long long start, end;
|
||||
|
||||
if (features.layers[i].features[j].geometry.size() > 0) {
|
||||
if (features.layers[i].features[j].has_id) {
|
||||
fid_to_feature.emplace(features.layers[i].features[j].id, std::make_pair(i, j));
|
||||
}
|
||||
|
||||
get_bbox(features.layers[i].features[j].geometry, &xmin, &ymin, &xmax, &ymax, z, x, y, features.layers[i].detail());
|
||||
get_quadkey_bounds(xmin, ymin, xmax, ymax, &start, &end);
|
||||
events.emplace_back(start, index_event::CHECK, i, j, xmin, ymin, xmax, ymax);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
std::sort(events.begin(), events.end());
|
||||
std::set<active_bin> active;
|
||||
|
||||
mvt_layer outlayer;
|
||||
outlayer.extent = bins[0].extent;
|
||||
outlayer.version = 2;
|
||||
outlayer.name = features.layers[0].name;
|
||||
|
||||
std::vector<std::vector<tile_feature>> outfeatures;
|
||||
|
||||
for (auto &e : events) {
|
||||
if (e.kind == index_event::ENTER) {
|
||||
active_bin a(e.layer, e.feature);
|
||||
a.xmin = e.xmin;
|
||||
a.ymin = e.ymin;
|
||||
a.xmax = e.xmax;
|
||||
a.ymax = e.ymax;
|
||||
|
||||
const mvt_feature &bin = bins[e.layer].features[e.feature];
|
||||
|
||||
{
|
||||
tile_feature outfeature;
|
||||
for (auto const &g : bin.geometry) {
|
||||
outfeature.geom.emplace_back(g.op, g.x, g.y);
|
||||
}
|
||||
outfeature.t = bin.type;
|
||||
outfeature.has_id = bin.has_id;
|
||||
outfeature.id = bin.id;
|
||||
outfeature.tags = bin.tags;
|
||||
outfeature.layer = &bins[e.layer];
|
||||
outfeature.seq = e.feature;
|
||||
|
||||
a.outfeature = outfeatures.size();
|
||||
outfeatures.push_back({std::move(outfeature)});
|
||||
}
|
||||
|
||||
if (bin_by_id_list.size() > 0) {
|
||||
for (size_t k = 0; k < bin.tags.size(); k += 2) {
|
||||
if (bins[e.layer].keys[bin.tags[k]] == bin_by_id_list) {
|
||||
std::vector<size_t> ids = parse_ids_string(bins[e.layer].values[bin.tags[k + 1]]);
|
||||
for (auto &id : ids) {
|
||||
auto f = fid_to_feature.find(id);
|
||||
if (f != fid_to_feature.end()) {
|
||||
mvt_feature &feature = features.layers[f->second.first].features[f->second.second];
|
||||
if (feature.geometry.size() > 0) {
|
||||
tile_feature outfeature;
|
||||
for (auto const &g : feature.geometry) {
|
||||
outfeature.geom.emplace_back(g.op, g.x, g.y);
|
||||
}
|
||||
feature.geometry.clear();
|
||||
outfeature.t = feature.type;
|
||||
outfeature.has_id = feature.has_id;
|
||||
outfeature.id = feature.id;
|
||||
outfeature.tags = feature.tags;
|
||||
outfeature.layer = &features.layers[e.layer];
|
||||
outfeature.seq = e.feature;
|
||||
outfeatures.back().push_back(std::move(outfeature));
|
||||
}
|
||||
}
|
||||
}
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
active.insert(std::move(a));
|
||||
} else if (e.kind == index_event::CHECK) {
|
||||
if (bin_by_id_list.size() > 0) {
|
||||
continue; // only bin by id, not geometrically
|
||||
}
|
||||
|
||||
auto const &feature = features.layers[e.layer].features[e.feature];
|
||||
|
||||
if (feature.geometry.size() == 0) {
|
||||
// already assigned by ID
|
||||
continue;
|
||||
}
|
||||
|
||||
// if we can't find a real match,
|
||||
// assign points to the most nearby bin
|
||||
ssize_t which_outfeature = outfeatures.size() - 1;
|
||||
|
||||
for (auto const &a : active) {
|
||||
auto const &bin = bins[a.layer].features[a.feature];
|
||||
|
||||
if (bbox_intersects(e.xmin, e.ymin, e.xmax, e.ymax,
|
||||
a.xmin, a.ymin, a.xmax, a.ymax)) {
|
||||
if (pnpoly_mp(bin.geometry, feature.geometry[0].x, feature.geometry[0].y)) {
|
||||
which_outfeature = a.outfeature;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (which_outfeature >= 0) {
|
||||
tile_feature outfeature;
|
||||
for (auto const &g : feature.geometry) {
|
||||
outfeature.geom.emplace_back(g.op, g.x, g.y);
|
||||
}
|
||||
outfeature.t = feature.type;
|
||||
outfeature.has_id = feature.has_id;
|
||||
outfeature.id = feature.id;
|
||||
outfeature.tags = feature.tags;
|
||||
outfeature.layer = &features.layers[e.layer];
|
||||
outfeature.seq = e.feature;
|
||||
outfeatures[which_outfeature].push_back(std::move(outfeature));
|
||||
}
|
||||
} else /* EXIT */ {
|
||||
auto const &found = active.find({e.layer, e.feature});
|
||||
if (found != active.end()) {
|
||||
active.erase(found);
|
||||
} else {
|
||||
fprintf(stderr, "event mismatch: can't happen\n");
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
for (size_t i = 0; i < outfeatures.size(); i++) {
|
||||
if (outfeatures[i].size() > 1) {
|
||||
if (feature_out(outfeatures[i], outlayer,
|
||||
keep, exclude, exclude_prefix, attribute_accum,
|
||||
accumulate_numeric, key_pool, buffer, true,
|
||||
clipbboxes, z, x, y)) {
|
||||
mvt_feature &nfeature = outlayer.features.back();
|
||||
mvt_value val;
|
||||
val.type = mvt_uint;
|
||||
val.numeric_value.uint_value = outfeatures[i].size() - 1;
|
||||
|
||||
std::string attrname;
|
||||
if (accumulate_numeric.size() == 0) {
|
||||
attrname = "tippecanoe:count";
|
||||
} else {
|
||||
attrname = accumulate_numeric + ":count";
|
||||
}
|
||||
if (should_keep(attrname, keep, exclude, exclude_prefix)) {
|
||||
outlayer.tag(nfeature, attrname, val);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
mvt_tile ret;
|
||||
ret.layers.push_back(outlayer);
|
||||
return ret;
|
||||
}
|
||||
|
||||
std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int ny,
|
||||
int detail_or_unspecified, int buffer,
|
||||
std::set<std::string> const &keep,
|
||||
@@ -2010,12 +1461,16 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::vector<std::string> const &unidecode_data, double simplification,
|
||||
double tiny_polygon_size,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
std::string const &accumulate_numeric, size_t feature_limit,
|
||||
std::vector<clipbbox> const &clipbboxes) {
|
||||
std::vector<mvt_layer> const &unused2, std::string const &unused3,
|
||||
std::string const &unused, size_t feature_limit,
|
||||
std::vector<clipbbox> const &unused4,
|
||||
bool deduplicate_by_id) {
|
||||
mvt_tile outtile;
|
||||
key_pool key_pool;
|
||||
|
||||
// map from layer name to ids used in that layer
|
||||
std::map<std::string, std::set<unsigned long long>> deduplicate_ids;
|
||||
|
||||
for (auto const &tile : tiles) {
|
||||
for (auto const &layer : tile.tile.layers) {
|
||||
mvt_layer *outlayer = NULL;
|
||||
@@ -2042,6 +1497,16 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
outlayer = &outtile.layers.back();
|
||||
}
|
||||
|
||||
std::set<unsigned long long> *deduplicate_by_id_set = NULL;
|
||||
if (deduplicate_by_id) {
|
||||
auto layer_deduplicate_ids = deduplicate_ids.find(layer.name);
|
||||
if (layer_deduplicate_ids == deduplicate_ids.end()) {
|
||||
deduplicate_ids.emplace(layer.name, std::set<unsigned long long>());
|
||||
layer_deduplicate_ids = deduplicate_ids.find(layer.name);
|
||||
}
|
||||
deduplicate_by_id_set = &layer_deduplicate_ids->second;
|
||||
}
|
||||
|
||||
std::vector<tile_feature> pending_tile_features;
|
||||
double accum_area = 0;
|
||||
|
||||
@@ -2072,30 +1537,6 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
}
|
||||
}
|
||||
|
||||
// Clip to user-specified bounding boxes.
|
||||
// Bounding box clip first, to reduce complexity of the full clip.
|
||||
// But don't clip here if we are binning, because we need to bin points in the buffer
|
||||
if (bins.size() == 0) {
|
||||
for (auto &c : clipbboxes) {
|
||||
if (t == VT_POLYGON) {
|
||||
geom = simple_clip_poly(geom, c.minx, c.miny, c.maxx, c.maxy, false);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_poly_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_LINE) {
|
||||
geom = clip_lines(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_lines_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_POINT) {
|
||||
geom = clip_point(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_point_poly(geom, c.dv);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Now offset from world coordinates to output tile coordinates,
|
||||
// but retain world scale, because that is what tippecanoe zoom-oriented clipping expects
|
||||
|
||||
@@ -2105,8 +1546,7 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
g.y -= ny * outtilesize;
|
||||
}
|
||||
|
||||
// Don't clip here if we are binning, because we need to bin points in the buffer
|
||||
if (bins.size() == 0) {
|
||||
{
|
||||
// Clip to output tile
|
||||
|
||||
long long xmin = LLONG_MAX;
|
||||
@@ -2124,6 +1564,9 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
long long b = outtilesize * buffer / 256;
|
||||
if (xmax < -b || ymax < -b || xmin > outtilesize + b || ymin > outtilesize + b) {
|
||||
// quick exclusion by bounding box
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -2139,6 +1582,9 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
|
||||
if (geom.size() == 0) {
|
||||
// clipped away
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -2163,7 +1609,7 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
|
||||
if (flush_multiplier_cluster) {
|
||||
if (pending_tile_features.size() > 0) {
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, accumulate_numeric, key_pool, -1, bins.size() == 0, std::vector<clipbbox>(), nz, nx, ny);
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, unused, key_pool, -1, true, std::vector<clipbbox>(), nz, nx, ny, deduplicate_by_id_set);
|
||||
if (outlayer->features.size() >= feature_limit) {
|
||||
break;
|
||||
}
|
||||
@@ -2173,6 +1619,10 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
|
||||
std::set<std::string> exclude_attributes;
|
||||
if (filter != NULL && !evaluate(feature, layer, filter, exclude_attributes, nz, unidecode_data)) {
|
||||
// filtered away
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -2210,6 +1660,14 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
geom = close_poly(geom);
|
||||
}
|
||||
|
||||
if (geom.size() == 0) {
|
||||
// simplified away
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
tile_feature tf;
|
||||
tf.geom = std::move(geom);
|
||||
tf.t = t;
|
||||
@@ -2223,7 +1681,7 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
}
|
||||
|
||||
if (pending_tile_features.size() > 0) {
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, accumulate_numeric, key_pool, -1, bins.size() == 0, std::vector<clipbbox>(), nz, nx, ny);
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, unused, key_pool, -1, true, std::vector<clipbbox>(), nz, nx, ny, deduplicate_by_id_set);
|
||||
pending_tile_features.clear();
|
||||
if (outlayer->features.size() >= feature_limit) {
|
||||
break;
|
||||
@@ -2262,8 +1720,8 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
nz + 1, nx * 2 + x, ny * 2 + y,
|
||||
detail_or_unspecified, buffer, keep, exclude, exclude_prefix, false, NULL,
|
||||
demultiply, filter, preserve_input_order, attribute_accum, unidecode_data,
|
||||
simplification, tiny_polygon_size, bins, bin_by_id_list, accumulate_numeric,
|
||||
1, clipbboxes);
|
||||
simplification, tiny_polygon_size, unused2, unused3, unused,
|
||||
1, unused4, deduplicate_by_id);
|
||||
if (child.size() > 0) {
|
||||
next_overzoomed_tiles->emplace_back(nx * 2 + x, ny * 2 + y);
|
||||
}
|
||||
@@ -2272,12 +1730,6 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
}
|
||||
}
|
||||
|
||||
if (bins.size() > 0) {
|
||||
outtile = assign_to_bins(outtile, bins, bin_by_id_list, nz, nx, ny,
|
||||
attribute_accum, accumulate_numeric,
|
||||
keep, exclude, exclude_prefix, buffer, clipbboxes);
|
||||
}
|
||||
|
||||
for (ssize_t i = outtile.layers.size() - 1; i >= 0; i--) {
|
||||
if (outtile.layers[i].features.size() == 0) {
|
||||
outtile.layers.erase(outtile.layers.begin() + i);
|
||||
@@ -2447,3 +1899,88 @@ drawvec fix_polygon(const drawvec &geom, bool use_winding, bool reverse_winding)
|
||||
|
||||
return out;
|
||||
}
|
||||
|
||||
bool line_is_too_small(drawvec const &geometry, int z, int detail) {
|
||||
if (geometry.size() == 0) {
|
||||
return true;
|
||||
}
|
||||
|
||||
long long x = 0, y = 0;
|
||||
for (auto &g : geometry) {
|
||||
if (g.op == VT_MOVETO) {
|
||||
x = std::llround((double) g.x / (1LL << (32 - detail - z)));
|
||||
y = std::llround((double) g.y / (1LL << (32 - detail - z)));
|
||||
} else {
|
||||
long long xx = std::llround((double) g.x / (1LL << (32 - detail - z)));
|
||||
long long yy = std::llround((double) g.y / (1LL << (32 - detail - z)));
|
||||
|
||||
if (xx != x || yy != y) {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return true;
|
||||
}
|
||||
|
||||
void coalesce_polygon(drawvec &geom, bool scale_up) {
|
||||
// wagyu should be able to straightforwardly handle
|
||||
// anything under a few hundred thousand vertices
|
||||
if (geom.size() < 100000) {
|
||||
geom = clean_or_clip_poly(geom, 0, 0, false, scale_up);
|
||||
return;
|
||||
}
|
||||
|
||||
// These geometries were assembled in geometric order,
|
||||
// so sub-batches of them should hopefully union into
|
||||
// reasonable sets.
|
||||
//
|
||||
// Find the first outer ring after halfway point.
|
||||
|
||||
for (size_t i = geom.size() / 2; i < geom.size(); i++) {
|
||||
if (geom[i].op == VT_MOVETO) {
|
||||
size_t j;
|
||||
for (j = i + 1; j < geom.size(); j++) {
|
||||
if (geom[j].op != VT_LINETO) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
if (get_area(geom, i, j) > 0) {
|
||||
// If we have an outer ring, split there
|
||||
// and coalesce the two halves
|
||||
|
||||
// Copy second half to new vector
|
||||
std::vector<draw> geom2;
|
||||
geom2.resize(geom.size() - i);
|
||||
for (size_t k = i; k < geom.size(); k++) {
|
||||
geom2[k - i] = geom[k];
|
||||
}
|
||||
|
||||
// Resize vector to include only first half
|
||||
geom.resize(i);
|
||||
|
||||
// Clean each half individually
|
||||
coalesce_polygon(geom, scale_up);
|
||||
coalesce_polygon(geom2, scale_up);
|
||||
|
||||
// Copy second half back with first
|
||||
size_t brk = geom.size();
|
||||
geom.resize(brk + geom2.size());
|
||||
for (size_t k = 0; k < geom2.size(); k++) {
|
||||
geom[brk + k] = geom2[k];
|
||||
}
|
||||
geom2.clear();
|
||||
|
||||
// Clean the combined geometry
|
||||
geom = clean_or_clip_poly(geom, 0, 0, false, scale_up);
|
||||
return;
|
||||
}
|
||||
|
||||
i = j - 1;
|
||||
}
|
||||
}
|
||||
|
||||
// Can't find a breakpoint; take what we can get.
|
||||
geom = clean_or_clip_poly(geom, 0, 0, false, scale_up);
|
||||
}
|
||||
|
||||
+39
-27
@@ -24,6 +24,7 @@
|
||||
#include "dirtiles.hpp"
|
||||
#include "pmtiles_file.hpp"
|
||||
#include "errors.hpp"
|
||||
#include "usage.hpp"
|
||||
|
||||
int minzoom = 0;
|
||||
int maxzoom = 32;
|
||||
@@ -549,8 +550,42 @@ void decode(char *fname, int z, unsigned x, unsigned y, std::set<std::string> co
|
||||
}
|
||||
}
|
||||
|
||||
static const struct option long_options[] = {
|
||||
{"Tiles to decode", 0, 0, 0},
|
||||
{"minimum-zoom", required_argument, 0, 'Z'},
|
||||
{"maximum-zoom", required_argument, 0, 'z'},
|
||||
{"layer", required_argument, 0, 'l'},
|
||||
|
||||
{"Output format", 0, 0, 0},
|
||||
{"projection", required_argument, 0, 's'},
|
||||
{"fractional-coordinates", no_argument, 0, 'F'},
|
||||
{"integer-coordinates", no_argument, 0, 'I'},
|
||||
{"tag-layer-and-zoom", no_argument, 0, 'c'},
|
||||
{"stats", no_argument, 0, 'S'},
|
||||
|
||||
{"Filtering the output", 0, 0, 0},
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{"exclude-metadata-row", required_argument, 0, 'x'},
|
||||
|
||||
{"Ignoring errors in the input", 0, 0, 0},
|
||||
{"force", no_argument, 0, 'f'},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
// the options above, with the usage message headings removed
|
||||
static struct option real_long_options[sizeof(long_options) / sizeof(long_options[0])];
|
||||
|
||||
void usage(char **argv) {
|
||||
fprintf(stderr, "Usage: %s [-s projection] [-Z minzoom] [-z maxzoom] [-l layer ...] file.mbtiles [zoom x y]\n", argv[0]);
|
||||
static const char *const forms[] = {
|
||||
"[options] tileset",
|
||||
"[options] tileset zoom x y",
|
||||
NULL,
|
||||
};
|
||||
|
||||
print_usage(stderr, argv[0], forms, long_options, NULL);
|
||||
fprintf(stderr, "\nThe tileset can be an .mbtiles or .pmtiles file or a directory of tiles,\n");
|
||||
fprintf(stderr, "or, if zoom/x/y is specified, a single .pbf tile.\n");
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
@@ -564,33 +599,10 @@ int main(int argc, char **argv) {
|
||||
std::set<std::string> exclude_meta;
|
||||
int coordinate_mode = 0;
|
||||
|
||||
struct option long_options[] = {
|
||||
{"projection", required_argument, 0, 's'},
|
||||
{"fractional-coordinates", no_argument, 0, 'F'},
|
||||
{"integer-coordinates", no_argument, 0, 'I'},
|
||||
{"maximum-zoom", required_argument, 0, 'z'},
|
||||
{"minimum-zoom", required_argument, 0, 'Z'},
|
||||
{"layer", required_argument, 0, 'l'},
|
||||
{"tag-layer-and-zoom", no_argument, 0, 'c'},
|
||||
{"stats", no_argument, 0, 'S'},
|
||||
{"force", no_argument, 0, 'f'},
|
||||
{"exclude-metadata-row", required_argument, 0, 'x'},
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
strip_usage_headings(long_options, real_long_options);
|
||||
std::string getopt_str = getopt_string(real_long_options);
|
||||
|
||||
std::string getopt_str;
|
||||
for (size_t lo = 0; long_options[lo].name != NULL; lo++) {
|
||||
if (long_options[lo].val > ' ') {
|
||||
getopt_str.push_back(long_options[lo].val);
|
||||
|
||||
if (long_options[lo].has_arg == required_argument) {
|
||||
getopt_str.push_back(':');
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), long_options, NULL)) != -1) {
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), real_long_options, NULL)) != -1) {
|
||||
switch (i) {
|
||||
case 0:
|
||||
break;
|
||||
|
||||
+11
-8
@@ -248,9 +248,9 @@ sqlite3 *dirmeta2tmp(const char *fname) {
|
||||
if (f == NULL) {
|
||||
perror(name.c_str());
|
||||
} else {
|
||||
json_pull *jp = json_begin_file(f);
|
||||
json_object *o = json_read_tree(jp);
|
||||
if (o == NULL) {
|
||||
json_pull_ptr jp = json_begin_file(f);
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
if (o == nullptr) {
|
||||
fprintf(stderr, "%s: metadata parsing error: %s\n", name.c_str(), jp->error);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
@@ -260,19 +260,22 @@ sqlite3 *dirmeta2tmp(const char *fname) {
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
for (size_t i = 0; i < o->value.object.length; i++) {
|
||||
if (o->value.object.keys[i]->type != JSON_STRING || o->value.object.values[i]->type != JSON_STRING) {
|
||||
for (const auto &e : o->entries()) {
|
||||
// Skip, not just warn: a metadata.json from another tool may
|
||||
// have a numeric minzoom or a nested object, and string()
|
||||
// asserts on the type.
|
||||
if (e.key->type != JSON_STRING || e.value->type != JSON_STRING) {
|
||||
fprintf(stderr, "%s: non-string in metadata\n", name.c_str());
|
||||
continue;
|
||||
}
|
||||
|
||||
char *sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES (%Q, %Q);", o->value.object.keys[i]->value.string.string, o->value.object.values[i]->value.string.string);
|
||||
char *sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES (%Q, %Q);", e.key->string().c_str(), e.value->string().c_str());
|
||||
if (sqlite3_exec(db, sql, NULL, NULL, &err) != SQLITE_OK) {
|
||||
fprintf(stderr, "set %s in metadata: %s\n", o->value.object.keys[i]->value.string.string, err);
|
||||
fprintf(stderr, "set %s in metadata: %s\n", e.key->string().c_str(), err);
|
||||
}
|
||||
sqlite3_free(sql);
|
||||
}
|
||||
|
||||
json_end(jp);
|
||||
fclose(f);
|
||||
}
|
||||
|
||||
|
||||
+19
-2
@@ -1,8 +1,11 @@
|
||||
#include <stdio.h>
|
||||
#include <stdlib.h>
|
||||
#include <unistd.h>
|
||||
#include <getopt.h>
|
||||
#include <string>
|
||||
#include <sqlite3.h>
|
||||
#include "errors.hpp"
|
||||
#include "usage.hpp"
|
||||
|
||||
void enumerate(char *fname) {
|
||||
sqlite3 *db;
|
||||
@@ -48,8 +51,20 @@ void enumerate(char *fname) {
|
||||
}
|
||||
}
|
||||
|
||||
// there are no options, but the table is still what the usage message
|
||||
// and the getopt string are derived from, so that they will keep up
|
||||
// with any options that are added later
|
||||
static const struct option long_options[] = {
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
void usage(char **argv) {
|
||||
fprintf(stderr, "Usage: %s file.mbtiles ...\n", argv[0]);
|
||||
static const char *const forms[] = {
|
||||
"file.mbtiles ...",
|
||||
NULL,
|
||||
};
|
||||
|
||||
print_usage(stderr, argv[0], forms, long_options, NULL);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
@@ -58,7 +73,9 @@ int main(int argc, char **argv) {
|
||||
// extern char *optarg;
|
||||
int i;
|
||||
|
||||
while ((i = getopt(argc, argv, "")) != -1) {
|
||||
std::string getopt_str = getopt_string(long_options);
|
||||
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), long_options, NULL)) != -1) {
|
||||
usage(argv);
|
||||
}
|
||||
|
||||
|
||||
+91
-422
@@ -9,170 +9,6 @@
|
||||
#include "milo/dtoa_milo.h"
|
||||
#include "text.hpp"
|
||||
|
||||
static std::string mvt_value_to_string(mvt_value const &one, bool &fail, std::vector<std::string> const &unidecode_data) {
|
||||
switch (one.type) {
|
||||
case mvt_string:
|
||||
if (unidecode_data.size() > 0) {
|
||||
return unidecode_smash(unidecode_data, one.c_str());
|
||||
} else {
|
||||
return one.get_string_value();
|
||||
}
|
||||
case mvt_float:
|
||||
return milo::dtoa_milo(one.numeric_value.float_value);
|
||||
case mvt_double:
|
||||
return milo::dtoa_milo(one.numeric_value.double_value);
|
||||
case mvt_int:
|
||||
return std::to_string(one.numeric_value.int_value);
|
||||
case mvt_uint:
|
||||
return std::to_string(one.numeric_value.uint_value);
|
||||
case mvt_sint:
|
||||
return std::to_string(one.numeric_value.sint_value);
|
||||
case mvt_bool:
|
||||
return one.numeric_value.bool_value ? "true" : "false";
|
||||
case mvt_null:
|
||||
fail = true; // null op string => null
|
||||
return "";
|
||||
case mvt_no_such_key:
|
||||
default:
|
||||
fprintf(stderr, "unhandled mvt_type %d\n", one.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
}
|
||||
|
||||
// Alter the JSON parse tree in place to replace the original match string
|
||||
// with its unidecode-smashed version.
|
||||
//
|
||||
// To avoid repeated re-smashings of the same JSON object, objects that have
|
||||
// already been smashed are marked by setting their refcon to the unidecode data.
|
||||
static void smash(std::vector<std::string> const &unidecode_data, json_object *j) {
|
||||
if (j->value.string.refcon == (void *) &unidecode_data) {
|
||||
return;
|
||||
}
|
||||
|
||||
std::string s = unidecode_smash(unidecode_data, j->value.string.string);
|
||||
j->value.string.string = (char *) realloc(j->value.string.string, s.size() + 1);
|
||||
if (j->value.string.string == NULL) {
|
||||
perror("realloc for unidecode_smash");
|
||||
exit(EXIT_MEMORY);
|
||||
}
|
||||
strcpy(j->value.string.string, s.c_str());
|
||||
j->value.string.refcon = (void *) &unidecode_data;
|
||||
}
|
||||
|
||||
int compare_fsl(mvt_value const &one, json_object *two, bool &fail, std::vector<std::string> const &unidecode_data) {
|
||||
// In FSL expressions, the attribute value is coerced to the type
|
||||
// of the JSON literal value it is being compared to.
|
||||
//
|
||||
// If it cannot be converted, the comparison returns null
|
||||
// (which is distinct from true and false but is falsy if
|
||||
// it is the final output value).
|
||||
|
||||
if (two->type == JSON_NULL) {
|
||||
fail = true; // anything op null => null
|
||||
return 0;
|
||||
}
|
||||
|
||||
if (two->type == JSON_NUMBER) {
|
||||
double lhs;
|
||||
|
||||
switch (one.type) {
|
||||
case mvt_string: {
|
||||
char *endptr = NULL;
|
||||
const char *s = one.c_str();
|
||||
lhs = strtod(s, &endptr);
|
||||
if (endptr == s) {
|
||||
fail = true; // non-numeric-string op number => null
|
||||
return 0;
|
||||
}
|
||||
} break;
|
||||
case mvt_float:
|
||||
lhs = one.numeric_value.float_value;
|
||||
break;
|
||||
case mvt_double:
|
||||
lhs = one.numeric_value.double_value;
|
||||
break;
|
||||
case mvt_int:
|
||||
lhs = one.numeric_value.int_value;
|
||||
break;
|
||||
case mvt_uint:
|
||||
lhs = one.numeric_value.uint_value;
|
||||
break;
|
||||
case mvt_sint:
|
||||
lhs = one.numeric_value.sint_value;
|
||||
break;
|
||||
case mvt_bool:
|
||||
lhs = one.numeric_value.bool_value;
|
||||
break;
|
||||
case mvt_null:
|
||||
fail = true; // null op number => null
|
||||
return 0;
|
||||
default:
|
||||
fprintf(stderr, "unhandled mvt_type %d\n", one.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
if (lhs < two->value.number.number) {
|
||||
return -1;
|
||||
} else if (lhs > two->value.number.number) {
|
||||
return 1;
|
||||
} else {
|
||||
return 0;
|
||||
}
|
||||
}
|
||||
|
||||
if (two->type == JSON_STRING) {
|
||||
std::string lhs = mvt_value_to_string(one, fail, unidecode_data);
|
||||
|
||||
if (unidecode_data.size() > 0) {
|
||||
smash(unidecode_data, two);
|
||||
}
|
||||
|
||||
return strcmp(lhs.c_str(), two->value.string.string);
|
||||
}
|
||||
|
||||
if (two->type == JSON_TRUE || two->type == JSON_FALSE) {
|
||||
bool lhs;
|
||||
|
||||
switch (one.type) {
|
||||
case mvt_string:
|
||||
lhs = one.get_string_view().size() > 0;
|
||||
break;
|
||||
case mvt_float:
|
||||
lhs = one.numeric_value.float_value != 0;
|
||||
break;
|
||||
case mvt_double:
|
||||
lhs = one.numeric_value.double_value != 0;
|
||||
break;
|
||||
case mvt_int:
|
||||
lhs = one.numeric_value.int_value != 0;
|
||||
break;
|
||||
case mvt_uint:
|
||||
lhs = one.numeric_value.uint_value != 0;
|
||||
break;
|
||||
case mvt_sint:
|
||||
lhs = one.numeric_value.sint_value != 0;
|
||||
break;
|
||||
case mvt_bool:
|
||||
lhs = one.numeric_value.bool_value;
|
||||
break;
|
||||
case mvt_null:
|
||||
fail = true; // null op bool => null
|
||||
return 0;
|
||||
|
||||
case mvt_no_such_key:
|
||||
default:
|
||||
fprintf(stderr, "unhandled mvt_type %d\n", one.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
bool rhs = two->type == JSON_TRUE;
|
||||
return lhs - rhs;
|
||||
}
|
||||
|
||||
fprintf(stderr, "unhandled JSON type %d\n", two->type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
int compare(mvt_value const &one, json_object *two, bool &fail) {
|
||||
switch (one.type) {
|
||||
case mvt_string:
|
||||
@@ -181,7 +17,7 @@ int compare(mvt_value const &one, json_object *two, bool &fail) {
|
||||
return false; // string vs non-string
|
||||
}
|
||||
|
||||
return strcmp(one.c_str(), two->value.string.string);
|
||||
return strcmp(one.c_str(), two->string().c_str());
|
||||
|
||||
case mvt_double:
|
||||
case mvt_float:
|
||||
@@ -216,9 +52,9 @@ int compare(mvt_value const &one, json_object *two, bool &fail) {
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
if (v < two->value.number.number) {
|
||||
if (v < two->number()) {
|
||||
return -1;
|
||||
} else if (v > two->value.number.number) {
|
||||
} else if (v > two->number()) {
|
||||
return 1;
|
||||
} else {
|
||||
return 0;
|
||||
@@ -256,7 +92,7 @@ int compare(mvt_value const &one, json_object *two, bool &fail) {
|
||||
// 1: true
|
||||
// -1: incomparable (sql null), treated as false in final output
|
||||
static int eval(std::function<mvt_value(std::string const &)> feature, json_object *f, std::set<std::string> &exclude_attributes, std::vector<std::string> const &unidecode_data) {
|
||||
if (f != NULL) {
|
||||
if (f != nullptr) {
|
||||
if (f->type == JSON_TRUE) {
|
||||
return 1;
|
||||
} else if (f->type == JSON_FALSE) {
|
||||
@@ -266,7 +102,7 @@ static int eval(std::function<mvt_value(std::string const &)> feature, json_obje
|
||||
}
|
||||
|
||||
if (f->type == JSON_NUMBER) {
|
||||
if (f->value.number.number == 0) {
|
||||
if (f->number() == 0) {
|
||||
return 0;
|
||||
} else {
|
||||
return 1;
|
||||
@@ -274,7 +110,7 @@ static int eval(std::function<mvt_value(std::string const &)> feature, json_obje
|
||||
}
|
||||
|
||||
if (f->type == JSON_STRING) {
|
||||
if (f->value.string.string[0] == '\0') {
|
||||
if (f->string().empty()) {
|
||||
return 0;
|
||||
} else {
|
||||
return 1;
|
||||
@@ -282,288 +118,129 @@ static int eval(std::function<mvt_value(std::string const &)> feature, json_obje
|
||||
}
|
||||
}
|
||||
|
||||
if (f == NULL || f->type != JSON_ARRAY) {
|
||||
fprintf(stderr, "Filter is not an array: %s\n", json_stringify(f));
|
||||
if (f == nullptr || f->type != JSON_ARRAY) {
|
||||
fprintf(stderr, "Filter is not an array: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
if (f->value.array.length < 1) {
|
||||
fprintf(stderr, "Array too small in filter: %s\n", json_stringify(f));
|
||||
if (f->array().size() < 1) {
|
||||
fprintf(stderr, "Array too small in filter: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
// FSL conjunctions
|
||||
if (f->value.array.length == 3 &&
|
||||
f->value.array.array[1]->type == JSON_STRING &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "or") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "and") == 0)) {
|
||||
int lhs;
|
||||
|
||||
if (f->value.array.array[0]->type == JSON_STRING) {
|
||||
// if LHS of a boolean conjunction is a string, it is an attribute reference
|
||||
mvt_value ff = feature(std::string(f->value.array.array[0]->value.string.string));
|
||||
if (ff.type != mvt_no_such_key) {
|
||||
if (ff.type == mvt_bool) {
|
||||
lhs = ff.numeric_value.bool_value;
|
||||
} else {
|
||||
lhs = -1; // not boolean: null
|
||||
}
|
||||
} else {
|
||||
lhs = -1; // not found: null
|
||||
}
|
||||
} else {
|
||||
lhs = eval(feature, f->value.array.array[0], exclude_attributes, unidecode_data);
|
||||
}
|
||||
|
||||
int rhs = eval(feature, f->value.array.array[2], exclude_attributes, unidecode_data);
|
||||
if (lhs < 0 && rhs < 0) {
|
||||
return -1; // null op null => null
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "or") == 0) {
|
||||
return (lhs > 0) || (rhs > 0);
|
||||
} else {
|
||||
return (lhs > 0) && (rhs > 0);
|
||||
}
|
||||
}
|
||||
|
||||
// FSL comparators
|
||||
if (f->value.array.length == 3 &&
|
||||
f->value.array.array[0]->type == JSON_STRING &&
|
||||
f->value.array.array[1]->type == JSON_STRING &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "lt") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "gt") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "le") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ge") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "eq") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ne") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "cn") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "nc") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "in") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ni") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "is") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "isnt") == 0 ||
|
||||
false)) {
|
||||
mvt_value lhs = feature(std::string(f->value.array.array[0]->value.string.string));
|
||||
if (lhs.type == mvt_no_such_key) {
|
||||
lhs.type = mvt_null;
|
||||
}
|
||||
|
||||
if (f->value.array.array[2]->type == JSON_NULL && strcmp(f->value.array.array[1]->value.string.string, "is") == 0) {
|
||||
return lhs.type == mvt_null; // null is null => true, anything is null => false
|
||||
}
|
||||
if (f->value.array.array[2]->type == JSON_NULL && strcmp(f->value.array.array[1]->value.string.string, "isnt") == 0) {
|
||||
return lhs.type != mvt_null; // null isnt null => false, anything isnt null => true
|
||||
}
|
||||
|
||||
bool fail = false;
|
||||
|
||||
if (f->value.array.array[2]->type == JSON_STRING &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "cn") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "nc") == 0)) {
|
||||
if (lhs.type == mvt_null) {
|
||||
return -1; // null cn/nc anything => null
|
||||
}
|
||||
|
||||
std::string s = mvt_value_to_string(lhs, fail, unidecode_data);
|
||||
if (fail) {
|
||||
return -1; // null cn anything => false
|
||||
}
|
||||
|
||||
bool contains;
|
||||
if (unidecode_data.size() > 0) {
|
||||
smash(unidecode_data, f->value.array.array[2]);
|
||||
}
|
||||
contains = strstr(s.c_str(), f->value.array.array[2]->value.string.string);
|
||||
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "cn") == 0) {
|
||||
return contains;
|
||||
} else {
|
||||
return !contains;
|
||||
}
|
||||
}
|
||||
|
||||
if (f->value.array.array[2]->type == JSON_ARRAY &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "in") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ni") == 0)) {
|
||||
// no null check here, since null can be in or not in
|
||||
|
||||
bool contains = false;
|
||||
for (size_t i = 0; i < f->value.array.array[2]->value.array.length; i++) {
|
||||
if (lhs.type == mvt_null) {
|
||||
if (f->value.array.array[2]->value.array.array[i]->type == JSON_NULL) {
|
||||
contains = true; // null is null
|
||||
break;
|
||||
} else {
|
||||
contains = false; // null isnt non-null
|
||||
}
|
||||
} else {
|
||||
fail = false;
|
||||
static std::vector<std::string> no_unidecode_data;
|
||||
int cmp = compare_fsl(lhs, f->value.array.array[2]->value.array.array[i], fail, no_unidecode_data);
|
||||
|
||||
if (fail) {
|
||||
contains = false; // non-null isnt null
|
||||
} else if (cmp == 0) {
|
||||
contains = true;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "in") == 0) {
|
||||
return contains;
|
||||
} else {
|
||||
return !contains;
|
||||
}
|
||||
}
|
||||
|
||||
if (lhs.type == mvt_null) {
|
||||
return -1; // null compared to anything => null
|
||||
}
|
||||
|
||||
int cmp = compare_fsl(lhs, f->value.array.array[2], fail, unidecode_data);
|
||||
if (fail) {
|
||||
return -1; // null
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "eq") == 0) {
|
||||
return cmp == 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "ne") == 0) {
|
||||
return cmp != 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "gt") == 0) {
|
||||
return cmp > 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "ge") == 0) {
|
||||
return cmp >= 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "lt") == 0) {
|
||||
return cmp < 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "le") == 0) {
|
||||
return cmp <= 0;
|
||||
}
|
||||
|
||||
fprintf(stderr, "expression fsl comparison: can't happen %s\n", f->value.array.array[1]->value.string.string);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
if (f->value.array.array[0]->type != JSON_STRING) {
|
||||
fprintf(stderr, "Filter operation is not a string: %s\n", json_stringify(f));
|
||||
if (f->array()[0]->type != JSON_STRING) {
|
||||
fprintf(stderr, "Filter operation is not a string: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "has") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "!has") == 0) {
|
||||
if (f->value.array.length != 2) {
|
||||
fprintf(stderr, "Wrong number of array elements in filter: %s\n", json_stringify(f));
|
||||
const std::string &op = f->array()[0]->string();
|
||||
|
||||
if (op == "has" ||
|
||||
op == "!has") {
|
||||
if (f->array().size() != 2) {
|
||||
fprintf(stderr, "Wrong number of array elements in filter: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "has") == 0) {
|
||||
if (f->value.array.array[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"has\" key is not a string: %s\n", json_stringify(f));
|
||||
if (op == "has") {
|
||||
if (f->array()[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"has\" key is not a string: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
return feature(std::string(f->value.array.array[1]->value.string.string)).type != mvt_no_such_key;
|
||||
return feature(f->array()[1]->string()).type != mvt_no_such_key;
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "!has") == 0) {
|
||||
if (f->value.array.array[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"!has\" key is not a string: %s\n", json_stringify(f));
|
||||
if (op == "!has") {
|
||||
if (f->array()[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"!has\" key is not a string: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
return feature(std::string(f->value.array.array[1]->value.string.string)).type == mvt_no_such_key;
|
||||
return feature(f->array()[1]->string()).type == mvt_no_such_key;
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "==") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "!=") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, ">") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, ">=") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "<") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "<=") == 0) {
|
||||
if (f->value.array.length != 3) {
|
||||
fprintf(stderr, "Wrong number of array elements in filter: %s\n", json_stringify(f));
|
||||
if (op == "==" ||
|
||||
op == "!=" ||
|
||||
op == ">" ||
|
||||
op == ">=" ||
|
||||
op == "<" ||
|
||||
op == "<=") {
|
||||
if (f->array().size() != 3) {
|
||||
fprintf(stderr, "Wrong number of array elements in filter: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
if (f->value.array.array[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "comparison key is not a string: %s\n", json_stringify(f));
|
||||
if (f->array()[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "comparison key is not a string: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
mvt_value ff = feature(std::string(f->value.array.array[1]->value.string.string));
|
||||
mvt_value ff = feature(f->array()[1]->string());
|
||||
if (ff.type == mvt_no_such_key) {
|
||||
static bool warned = false;
|
||||
if (!warned) {
|
||||
const char *s = json_stringify(f);
|
||||
fprintf(stderr, "Warning: attribute not found for comparison: %s\n", s);
|
||||
free((void *) s);
|
||||
fprintf(stderr, "Warning: attribute not found for comparison: %s\n", json_stringify(f).c_str());
|
||||
warned = true;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "!=") == 0) {
|
||||
if (op == "!=") {
|
||||
return true; // attributes that aren't found are not equal
|
||||
}
|
||||
return false; // not found: comparison is false
|
||||
}
|
||||
|
||||
bool fail = false;
|
||||
int cmp = compare(ff, f->value.array.array[2], fail);
|
||||
int cmp = compare(ff, f->array()[2].get(), fail);
|
||||
|
||||
if (fail) {
|
||||
static bool warned = false;
|
||||
if (!warned) {
|
||||
const char *s = json_stringify(f);
|
||||
fprintf(stderr, "Warning: mismatched type in comparison: %s\n", s);
|
||||
free((void *) s);
|
||||
fprintf(stderr, "Warning: mismatched type in comparison: %s\n", json_stringify(f).c_str());
|
||||
warned = true;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "!=") == 0) {
|
||||
if (op == "!=") {
|
||||
return true; // mismatched types are not equal
|
||||
}
|
||||
return false;
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "==") == 0) {
|
||||
if (op == "==") {
|
||||
return cmp == 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "!=") == 0) {
|
||||
if (op == "!=") {
|
||||
return cmp != 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, ">") == 0) {
|
||||
if (op == ">") {
|
||||
return cmp > 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, ">=") == 0) {
|
||||
if (op == ">=") {
|
||||
return cmp >= 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "<") == 0) {
|
||||
if (op == "<") {
|
||||
return cmp < 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "<=") == 0) {
|
||||
if (op == "<=") {
|
||||
return cmp <= 0;
|
||||
}
|
||||
|
||||
fprintf(stderr, "Internal error: can't happen: %s\n", json_stringify(f));
|
||||
fprintf(stderr, "Internal error: can't happen: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "all") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "any") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "none") == 0) {
|
||||
if (op == "all" ||
|
||||
op == "any" ||
|
||||
op == "none") {
|
||||
bool v;
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "all") == 0) {
|
||||
if (op == "all") {
|
||||
v = true;
|
||||
} else {
|
||||
v = false;
|
||||
}
|
||||
|
||||
for (size_t i = 1; i < f->value.array.length; i++) {
|
||||
int out = eval(feature, f->value.array.array[i], exclude_attributes, unidecode_data);
|
||||
for (size_t i = 1; i < f->array().size(); i++) {
|
||||
int out = eval(feature, f->array()[i].get(), exclude_attributes, unidecode_data);
|
||||
|
||||
if (out >= 0) { // nulls are ignored in boolean and/or expressions
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "all") == 0) {
|
||||
if (op == "all") {
|
||||
v = v && out;
|
||||
if (!v) {
|
||||
break;
|
||||
@@ -577,51 +254,47 @@ static int eval(std::function<mvt_value(std::string const &)> feature, json_obje
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "none") == 0) {
|
||||
if (op == "none") {
|
||||
return !v;
|
||||
} else {
|
||||
return v;
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "in") == 0 ||
|
||||
strcmp(f->value.array.array[0]->value.string.string, "!in") == 0) {
|
||||
if (f->value.array.length < 2) {
|
||||
fprintf(stderr, "Array too small in filter: %s\n", json_stringify(f));
|
||||
if (op == "in" ||
|
||||
op == "!in") {
|
||||
if (f->array().size() < 2) {
|
||||
fprintf(stderr, "Array too small in filter: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
if (f->value.array.array[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"!in\" key is not a string: %s\n", json_stringify(f));
|
||||
if (f->array()[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"!in\" key is not a string: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
mvt_value ff = feature(std::string(f->value.array.array[1]->value.string.string));
|
||||
mvt_value ff = feature(f->array()[1]->string());
|
||||
if (ff.type == mvt_no_such_key) {
|
||||
static bool warned = false;
|
||||
if (!warned) {
|
||||
const char *s = json_stringify(f);
|
||||
fprintf(stderr, "Warning: attribute not found for comparison: %s\n", s);
|
||||
free((void *) s);
|
||||
fprintf(stderr, "Warning: attribute not found for comparison: %s\n", json_stringify(f).c_str());
|
||||
warned = true;
|
||||
}
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "!in") == 0) {
|
||||
if (op == "!in") {
|
||||
return true; // attributes that aren't found are not in
|
||||
}
|
||||
return false; // not found: comparison is false
|
||||
}
|
||||
|
||||
bool found = false;
|
||||
for (size_t i = 2; i < f->value.array.length; i++) {
|
||||
for (size_t i = 2; i < f->array().size(); i++) {
|
||||
bool fail = false;
|
||||
int cmp = compare(ff, f->value.array.array[i], fail);
|
||||
int cmp = compare(ff, f->array()[i].get(), fail);
|
||||
|
||||
if (fail) {
|
||||
static bool warned = false;
|
||||
if (!warned) {
|
||||
const char *s = json_stringify(f);
|
||||
fprintf(stderr, "Warning: mismatched type in comparison: %s\n", s);
|
||||
free((void *) s);
|
||||
fprintf(stderr, "Warning: mismatched type in comparison: %s\n", json_stringify(f).c_str());
|
||||
warned = true;
|
||||
}
|
||||
cmp = 1;
|
||||
@@ -633,39 +306,39 @@ static int eval(std::function<mvt_value(std::string const &)> feature, json_obje
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "in") == 0) {
|
||||
if (op == "in") {
|
||||
return found;
|
||||
} else {
|
||||
return !found;
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[0]->value.string.string, "attribute-filter") == 0) {
|
||||
if (f->value.array.length != 3) {
|
||||
fprintf(stderr, "Wrong number of array elements in filter: %s\n", json_stringify(f));
|
||||
if (op == "attribute-filter") {
|
||||
if (f->array().size() != 3) {
|
||||
fprintf(stderr, "Wrong number of array elements in filter: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
if (f->value.array.array[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"attribute-filter\" key is not a string: %s\n", json_stringify(f));
|
||||
if (f->array()[1]->type != JSON_STRING) {
|
||||
fprintf(stderr, "\"attribute-filter\" key is not a string: %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
bool ok = eval(feature, f->value.array.array[2], exclude_attributes, unidecode_data) > 0;
|
||||
bool ok = eval(feature, f->array()[2].get(), exclude_attributes, unidecode_data) > 0;
|
||||
if (!ok) {
|
||||
exclude_attributes.insert(f->value.array.array[1]->value.string.string);
|
||||
exclude_attributes.insert(f->array()[1]->string());
|
||||
}
|
||||
|
||||
return true;
|
||||
}
|
||||
|
||||
fprintf(stderr, "Unknown filter %s\n", json_stringify(f));
|
||||
fprintf(stderr, "Unknown filter %s\n", json_stringify(f).c_str());
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
bool evaluate(std::function<mvt_value(std::string const &)> feature, std::string const &layer, json_object *filter, std::set<std::string> &exclude_attributes, std::vector<std::string> const &unidecode_data) {
|
||||
if (filter == NULL || filter->type != JSON_HASH) {
|
||||
fprintf(stderr, "Error: filter is not a hash: %s\n", json_stringify(filter));
|
||||
static bool evaluate(std::function<mvt_value(std::string const &)> feature, std::string const &layer, json_object *filter, std::set<std::string> &exclude_attributes, std::vector<std::string> const &unidecode_data) {
|
||||
if (filter == nullptr || filter->type != JSON_HASH) {
|
||||
fprintf(stderr, "Error: filter is not a hash: %s\n", json_stringify(filter).c_str());
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
@@ -673,47 +346,43 @@ bool evaluate(std::function<mvt_value(std::string const &)> feature, std::string
|
||||
json_object *f;
|
||||
|
||||
f = json_hash_get(filter, layer.c_str());
|
||||
if (ok && f != NULL) {
|
||||
if (ok && f != nullptr) {
|
||||
ok = eval(feature, f, exclude_attributes, unidecode_data) > 0;
|
||||
}
|
||||
|
||||
f = json_hash_get(filter, "*");
|
||||
if (ok && f != NULL) {
|
||||
if (ok && f != nullptr) {
|
||||
ok = eval(feature, f, exclude_attributes, unidecode_data) > 0;
|
||||
}
|
||||
|
||||
return ok;
|
||||
}
|
||||
|
||||
json_object *read_filter(const char *fname) {
|
||||
json_object_ptr read_filter(const char *fname) {
|
||||
FILE *fp = fopen(fname, "r");
|
||||
if (fp == NULL) {
|
||||
perror(fname);
|
||||
exit(EXIT_OPEN);
|
||||
}
|
||||
|
||||
json_pull *jp = json_begin_file(fp);
|
||||
json_object *filter = json_read_tree(jp);
|
||||
if (filter == NULL) {
|
||||
json_pull_ptr jp = json_begin_file(fp);
|
||||
json_object_ptr filter = json_read_tree(jp);
|
||||
if (filter == nullptr) {
|
||||
fprintf(stderr, "%s: %s\n", fname, jp->error);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
json_disconnect(filter);
|
||||
json_end(jp);
|
||||
fclose(fp);
|
||||
return filter;
|
||||
}
|
||||
|
||||
json_object *parse_filter(const char *s) {
|
||||
json_pull *jp = json_begin_string(s);
|
||||
json_object *filter = json_read_tree(jp);
|
||||
if (filter == NULL) {
|
||||
json_object_ptr parse_filter(const char *s) {
|
||||
json_pull_ptr jp = json_begin_string(s);
|
||||
json_object_ptr filter = json_read_tree(jp);
|
||||
if (filter == nullptr) {
|
||||
fprintf(stderr, "Could not parse filter %s\n", s);
|
||||
fprintf(stderr, "%s\n", jp->error);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
json_disconnect(filter);
|
||||
json_end(jp);
|
||||
return filter;
|
||||
}
|
||||
|
||||
|
||||
+7
-3
@@ -1,5 +1,5 @@
|
||||
#ifndef EVALUATOR_HPP
|
||||
#define EVALUATOR HPP
|
||||
#define EVALUATOR_HPP
|
||||
|
||||
#include <unordered_map>
|
||||
#include <string>
|
||||
@@ -7,9 +7,13 @@
|
||||
#include "jsonpull/jsonpull.h"
|
||||
#include "mvt.hpp"
|
||||
|
||||
// The `filter` parameters take a borrowed pointer; the caller (in
|
||||
// main.cpp, tile-join, overzoom) keeps the json_object_ptr alive
|
||||
// across every per-feature evaluate() call. A raw pointer avoids
|
||||
// touching unique_ptr at all on this hot path.
|
||||
bool evaluate(std::unordered_map<std::string, mvt_value> const &feature, std::string const &layer, json_object *filter, std::set<std::string> &exclude_attributes, std::vector<std::string> const &unidecode_data);
|
||||
json_object *parse_filter(const char *s);
|
||||
json_object *read_filter(const char *fname);
|
||||
json_object_ptr parse_filter(const char *s);
|
||||
json_object_ptr read_filter(const char *fname);
|
||||
|
||||
bool evaluate(mvt_feature const &feat, mvt_layer const &layer, json_object *filter, std::set<std::string> &exclude_attributes, int z, std::vector<std::string> const &unidecode_data);
|
||||
|
||||
|
||||
+10
-10
@@ -163,13 +163,13 @@ void readFeature(const FlatGeobuf::Feature *feature, long long feature_sequence_
|
||||
|
||||
serial_val sv;
|
||||
if (col_type == FlatGeobuf::ColumnType_Byte) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int8_t byte_val;
|
||||
memcpy(&byte_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(byte_val));
|
||||
sv.s = std::to_string(byte_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(byte_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_UByte) {
|
||||
sv.type = mvt_uint;
|
||||
sv.type = mvt_double;
|
||||
uint8_t ubyte_val;
|
||||
memcpy(&ubyte_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(ubyte_val));
|
||||
sv.s = std::to_string(ubyte_val);
|
||||
@@ -185,43 +185,43 @@ void readFeature(const FlatGeobuf::Feature *feature, long long feature_sequence_
|
||||
}
|
||||
p_pos += sizeof(uint16_t) + sizeof(bool_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Short) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int16_t short_val;
|
||||
memcpy(&short_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(short_val));
|
||||
sv.s = std::to_string(short_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(short_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_UShort) {
|
||||
sv.type = mvt_uint;
|
||||
sv.type = mvt_double;
|
||||
uint16_t ushort_val;
|
||||
memcpy(&ushort_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(ushort_val));
|
||||
sv.s = std::to_string(ushort_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(ushort_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Int) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int32_t int_val;
|
||||
memcpy(&int_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(int_val));
|
||||
sv.s = std::to_string(int_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(int_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_UInt) {
|
||||
sv.type = mvt_uint;
|
||||
sv.type = mvt_double;
|
||||
uint32_t uint_val;
|
||||
memcpy(&uint_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(uint_val));
|
||||
sv.s = std::to_string(uint_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(uint_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Long) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int64_t long_val;
|
||||
memcpy(&long_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(long_val));
|
||||
sv.s = std::to_string(long_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(long_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_ULong) {
|
||||
sv.type = mvt_uint;
|
||||
int64_t ulong_val;
|
||||
sv.type = mvt_double;
|
||||
uint64_t ulong_val;
|
||||
memcpy(&ulong_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(ulong_val));
|
||||
sv.s = std::to_string(ulong_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(ulong_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Float) {
|
||||
sv.type = mvt_float;
|
||||
sv.type = mvt_double;
|
||||
float float_val;
|
||||
memcpy(&float_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(float_val));
|
||||
sv.s = milo::dtoa_milo(float_val);
|
||||
|
||||
+9
-12
@@ -394,28 +394,25 @@ void readFeature(protozero::pbf_reader &pbf, size_t dim, double e, std::vector<s
|
||||
|
||||
auto tip = other.find("tippecanoe");
|
||||
if (tip != other.end()) {
|
||||
json_pull *jp = json_begin_string(tip->second.s.c_str());
|
||||
json_object *o = json_read_tree(jp);
|
||||
json_pull_ptr jp = json_begin_string(tip->second.s.c_str());
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
if (o != NULL) {
|
||||
if (o != nullptr) {
|
||||
json_object *min = json_hash_get(o, "minzoom");
|
||||
if (min != NULL && (min->type == JSON_NUMBER)) {
|
||||
sf.tippecanoe_minzoom = integer_zoom(sst->fname, milo::dtoa_milo(min->value.number.number));
|
||||
if (min != nullptr && (min->type == JSON_NUMBER)) {
|
||||
sf.tippecanoe_minzoom = integer_zoom(sst->fname, milo::dtoa_milo(min->number()));
|
||||
}
|
||||
|
||||
json_object *max = json_hash_get(o, "maxzoom");
|
||||
if (max != NULL && (max->type == JSON_NUMBER)) {
|
||||
sf.tippecanoe_maxzoom = integer_zoom(sst->fname, milo::dtoa_milo(max->value.number.number));
|
||||
if (max != nullptr && (max->type == JSON_NUMBER)) {
|
||||
sf.tippecanoe_maxzoom = integer_zoom(sst->fname, milo::dtoa_milo(max->number()));
|
||||
}
|
||||
|
||||
json_object *tlayer = json_hash_get(o, "layer");
|
||||
if (tlayer != NULL && (tlayer->type == JSON_STRING)) {
|
||||
layername = tlayer->value.string.string;
|
||||
if (tlayer != nullptr && (tlayer->type == JSON_STRING)) {
|
||||
layername = tlayer->string();
|
||||
}
|
||||
}
|
||||
|
||||
json_free(o);
|
||||
json_end(jp);
|
||||
}
|
||||
|
||||
serialize_feature(sst, sf, layername);
|
||||
|
||||
+28
-27
@@ -12,6 +12,7 @@
|
||||
#include <errno.h>
|
||||
#include "geojson-loop.hpp"
|
||||
#include "jsonpull/jsonpull.h"
|
||||
#include "text.hpp"
|
||||
|
||||
// XXX duplicated
|
||||
#define GEOM_TYPES 6
|
||||
@@ -26,34 +27,34 @@ static const char *geometry_names[GEOM_TYPES] = {
|
||||
|
||||
// XXX duplicated
|
||||
static void json_context(json_object *j) {
|
||||
char *s = json_stringify(j);
|
||||
std::string s = json_stringify(j);
|
||||
|
||||
if (strlen(s) >= 500) {
|
||||
snprintf(s + 497, strlen(s) + 1 - 497, "...");
|
||||
if (s.size() >= 500) {
|
||||
s = truncate_string(s, 497);
|
||||
s.append("...");
|
||||
}
|
||||
|
||||
fprintf(stderr, "in JSON object %s\n", s);
|
||||
free(s); // stringify
|
||||
fprintf(stderr, "in JSON object %s\n", s.c_str());
|
||||
}
|
||||
|
||||
void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
void parse_json(json_feature_action *jfa, json_pull_ptr &jp) {
|
||||
long long found_hashes = 0;
|
||||
long long found_features = 0;
|
||||
long long found_geometries = 0;
|
||||
|
||||
while (1) {
|
||||
json_object *j = json_read(jp);
|
||||
if (j == NULL) {
|
||||
if (jp->error != NULL) {
|
||||
if (j == nullptr) {
|
||||
if (jp->error != nullptr) {
|
||||
fprintf(stderr, "%s:%d: %s: ", jfa->fname.c_str(), jp->line, jp->error);
|
||||
if (jp->root != NULL) {
|
||||
json_context(jp->root);
|
||||
if (jp->root != nullptr) {
|
||||
json_context(jp->root.get());
|
||||
} else {
|
||||
fprintf(stderr, "\n");
|
||||
}
|
||||
}
|
||||
|
||||
json_free(jp->root);
|
||||
jp->root.reset();
|
||||
break;
|
||||
}
|
||||
|
||||
@@ -66,7 +67,7 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
}
|
||||
|
||||
json_object *type = json_hash_get(j, "type");
|
||||
if (type == NULL || type->type != JSON_STRING) {
|
||||
if (type == nullptr || type->type != JSON_STRING) {
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -74,25 +75,25 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
int i;
|
||||
int is_geometry = 0;
|
||||
for (i = 0; i < GEOM_TYPES; i++) {
|
||||
if (strcmp(type->value.string.string, geometry_names[i]) == 0) {
|
||||
if (type->string() == geometry_names[i]) {
|
||||
is_geometry = 1;
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
if (is_geometry) {
|
||||
if (j->parent != NULL) {
|
||||
if (j->parent->type == JSON_ARRAY && j->parent->parent != NULL) {
|
||||
if (j->parent != nullptr) {
|
||||
if (j->parent->type == JSON_ARRAY && j->parent->parent != nullptr) {
|
||||
if (j->parent->parent->type == JSON_HASH) {
|
||||
json_object *geometries = json_hash_get(j->parent->parent, "geometries");
|
||||
if (geometries != NULL) {
|
||||
if (geometries != nullptr) {
|
||||
// Parent of Parent must be a GeometryCollection
|
||||
is_geometry = 0;
|
||||
}
|
||||
}
|
||||
} else if (j->parent->type == JSON_HASH) {
|
||||
json_object *geometry = json_hash_get(j->parent, "geometry");
|
||||
if (geometry != NULL) {
|
||||
if (geometry != nullptr) {
|
||||
// Parent must be a Feature
|
||||
is_geometry = 0;
|
||||
}
|
||||
@@ -102,8 +103,8 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
|
||||
if (is_geometry) {
|
||||
json_object *jo = j;
|
||||
while (jo != NULL) {
|
||||
if (jo->parent != NULL && jo->parent->type == JSON_HASH) {
|
||||
while (jo != nullptr) {
|
||||
if (jo->parent != nullptr && jo->parent->type == JSON_HASH) {
|
||||
if (json_hash_get(jo->parent, "properties") == jo) {
|
||||
// Ancestor is the value corresponding to a properties key
|
||||
is_geometry = 0;
|
||||
@@ -120,14 +121,14 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
}
|
||||
found_geometries++;
|
||||
|
||||
jfa->add_feature(j, false, NULL, NULL, NULL, j);
|
||||
jfa->add_feature(j, false, nullptr, nullptr, nullptr, j);
|
||||
json_free(j);
|
||||
continue;
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(type->value.string.string, "Feature") != 0) {
|
||||
if (strcmp(type->value.string.string, "FeatureCollection") == 0) {
|
||||
if (type->string() != "Feature") {
|
||||
if (type->string() == "FeatureCollection") {
|
||||
jfa->check_crs(j);
|
||||
json_free(j);
|
||||
}
|
||||
@@ -141,7 +142,7 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
found_features++;
|
||||
|
||||
json_object *geometry = json_hash_get(j, "geometry");
|
||||
if (geometry == NULL) {
|
||||
if (geometry == nullptr) {
|
||||
fprintf(stderr, "%s:%d: feature with no geometry: ", jfa->fname.c_str(), jp->line);
|
||||
json_context(j);
|
||||
json_free(j);
|
||||
@@ -149,7 +150,7 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
}
|
||||
|
||||
json_object *properties = json_hash_get(j, "properties");
|
||||
if (properties == NULL || (properties->type != JSON_HASH && properties->type != JSON_NULL)) {
|
||||
if (properties == nullptr || (properties->type != JSON_HASH && properties->type != JSON_NULL)) {
|
||||
fprintf(stderr, "%s:%d: feature without properties hash: ", jfa->fname.c_str(), jp->line);
|
||||
json_context(j);
|
||||
json_free(j);
|
||||
@@ -159,8 +160,8 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
bool is_feature = true;
|
||||
{
|
||||
json_object *jo = j;
|
||||
while (jo != NULL) {
|
||||
if (jo->parent != NULL && jo->parent->type == JSON_HASH) {
|
||||
while (jo != nullptr) {
|
||||
if (jo->parent != nullptr && jo->parent->type == JSON_HASH) {
|
||||
if (json_hash_get(jo->parent, "properties") == jo) {
|
||||
// Ancestor is the value corresponding to a properties key
|
||||
is_feature = false;
|
||||
@@ -178,7 +179,7 @@ void parse_json(json_feature_action *jfa, json_pull *jp) {
|
||||
json_object *id = json_hash_get(j, "id");
|
||||
|
||||
json_object *geometries = json_hash_get(geometry, "geometries");
|
||||
if (geometries != NULL && geometries->type == JSON_ARRAY) {
|
||||
if (geometries != nullptr && geometries->type == JSON_ARRAY) {
|
||||
jfa->add_feature(geometries, true, properties, id, tippecanoe, j);
|
||||
} else {
|
||||
jfa->add_feature(geometry, false, properties, id, tippecanoe, j);
|
||||
|
||||
+1
-1
@@ -8,4 +8,4 @@ struct json_feature_action {
|
||||
virtual void check_crs(json_object *j) = 0;
|
||||
};
|
||||
|
||||
void parse_json(json_feature_action *action, json_pull *jp);
|
||||
void parse_json(json_feature_action *action, json_pull_ptr &jp);
|
||||
|
||||
+52
-50
@@ -42,7 +42,7 @@
|
||||
|
||||
int serialize_geojson_feature(struct serialization_state *sst, json_object *geometry, json_object *properties, json_object *id, int layer, json_object *tippecanoe, json_object *feature, std::string const &layername) {
|
||||
json_object *geometry_type = json_hash_get(geometry, "type");
|
||||
if (geometry_type == NULL) {
|
||||
if (geometry_type == nullptr) {
|
||||
static int warned = 0;
|
||||
if (!warned) {
|
||||
fprintf(stderr, "%s:%d: null geometry (additional not reported): ", sst->fname, sst->line);
|
||||
@@ -60,7 +60,7 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
}
|
||||
|
||||
json_object *coordinates = json_hash_get(geometry, "coordinates");
|
||||
if (coordinates == NULL || coordinates->type != JSON_ARRAY) {
|
||||
if (coordinates == nullptr || coordinates->type != JSON_ARRAY) {
|
||||
fprintf(stderr, "%s:%d: feature without coordinates array: ", sst->fname, sst->line);
|
||||
json_context(feature);
|
||||
return 0;
|
||||
@@ -68,12 +68,12 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
|
||||
int t;
|
||||
for (t = 0; t < GEOM_TYPES; t++) {
|
||||
if (strcmp(geometry_type->value.string.string, geometry_names[t]) == 0) {
|
||||
if (geometry_type->string() == geometry_names[t]) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
if (t >= GEOM_TYPES) {
|
||||
fprintf(stderr, "%s:%d: Can't handle geometry type %s: ", sst->fname, sst->line, geometry_type->value.string.string);
|
||||
fprintf(stderr, "%s:%d: Can't handle geometry type %s: ", sst->fname, sst->line, geometry_type->string().c_str());
|
||||
json_context(feature);
|
||||
return 0;
|
||||
}
|
||||
@@ -82,48 +82,48 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
int tippecanoe_maxzoom = -1;
|
||||
std::string tippecanoe_layername = layername;
|
||||
|
||||
if (tippecanoe != NULL) {
|
||||
if (tippecanoe != nullptr) {
|
||||
json_object *min = json_hash_get(tippecanoe, "minzoom");
|
||||
if (min != NULL && (min->type == JSON_NUMBER)) {
|
||||
tippecanoe_minzoom = integer_zoom(sst->fname, milo::dtoa_milo(min->value.number.number));
|
||||
if (min != nullptr && (min->type == JSON_NUMBER)) {
|
||||
tippecanoe_minzoom = integer_zoom(sst->fname, milo::dtoa_milo(min->number()));
|
||||
}
|
||||
|
||||
json_object *max = json_hash_get(tippecanoe, "maxzoom");
|
||||
if (max != NULL && (max->type == JSON_NUMBER)) {
|
||||
tippecanoe_maxzoom = integer_zoom(sst->fname, milo::dtoa_milo(max->value.number.number));
|
||||
if (max != nullptr && (max->type == JSON_NUMBER)) {
|
||||
tippecanoe_maxzoom = integer_zoom(sst->fname, milo::dtoa_milo(max->number()));
|
||||
}
|
||||
|
||||
json_object *ln = json_hash_get(tippecanoe, "layer");
|
||||
if (ln != NULL && (ln->type == JSON_STRING)) {
|
||||
tippecanoe_layername = std::string(ln->value.string.string);
|
||||
if (ln != nullptr && (ln->type == JSON_STRING)) {
|
||||
tippecanoe_layername = ln->string();
|
||||
}
|
||||
}
|
||||
|
||||
bool has_id = false;
|
||||
unsigned long long id_value = 0;
|
||||
if (id != NULL) {
|
||||
if (id != nullptr) {
|
||||
if (id->type == JSON_NUMBER) {
|
||||
if (id->value.number.number >= 0) {
|
||||
if (id->number() >= 0) {
|
||||
char *err = NULL;
|
||||
std::string id_number = milo::dtoa_milo(id->value.number.number);
|
||||
std::string id_number = milo::dtoa_milo(id->number());
|
||||
id_value = strtoull(id_number.c_str(), &err, 10);
|
||||
|
||||
if (id->value.number.large_unsigned != 0) {
|
||||
id_value = id->value.number.large_unsigned;
|
||||
if (id->large_unsigned() != 0) {
|
||||
id_value = id->large_unsigned();
|
||||
}
|
||||
|
||||
if (err != NULL && *err != '\0') {
|
||||
static bool warned_frac = false;
|
||||
|
||||
if (!warned_frac) {
|
||||
fprintf(stderr, "Warning: Can't represent non-integer feature ID %s\n", milo::dtoa_milo(id->value.number.number).c_str());
|
||||
fprintf(stderr, "Warning: Can't represent non-integer feature ID %s\n", milo::dtoa_milo(id->number()).c_str());
|
||||
warned_frac = true;
|
||||
}
|
||||
} else if (id->value.number.large_unsigned == 0 && std::to_string(id_value) != milo::dtoa_milo(id->value.number.number)) {
|
||||
} else if (id->large_unsigned() == 0 && std::to_string(id_value) != milo::dtoa_milo(id->number())) {
|
||||
static bool warned = false;
|
||||
|
||||
if (!warned) {
|
||||
fprintf(stderr, "Warning: Can't represent too-large feature ID %s\n", milo::dtoa_milo(id->value.number.number).c_str());
|
||||
fprintf(stderr, "Warning: Can't represent too-large feature ID %s\n", milo::dtoa_milo(id->number()).c_str());
|
||||
warned = true;
|
||||
}
|
||||
} else {
|
||||
@@ -133,7 +133,7 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
static bool warned_neg = false;
|
||||
|
||||
if (!warned_neg) {
|
||||
fprintf(stderr, "Warning: Can't represent negative feature ID %s\n", milo::dtoa_milo(id->value.number.number).c_str());
|
||||
fprintf(stderr, "Warning: Can't represent negative feature ID %s\n", milo::dtoa_milo(id->number()).c_str());
|
||||
warned_neg = true;
|
||||
}
|
||||
}
|
||||
@@ -142,20 +142,20 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
|
||||
if (additional[A_CONVERT_NUMERIC_IDS] && id->type == JSON_STRING) {
|
||||
char *err = NULL;
|
||||
id_value = strtoull(id->value.string.string, &err, 10);
|
||||
id_value = strtoull(id->string().c_str(), &err, 10);
|
||||
|
||||
if (err != NULL && *err != '\0') {
|
||||
static bool warned_frac = false;
|
||||
|
||||
if (!warned_frac) {
|
||||
fprintf(stderr, "Warning: Can't represent non-integer feature ID %s\n", id->value.string.string);
|
||||
fprintf(stderr, "Warning: Can't represent non-integer feature ID %s\n", id->string().c_str());
|
||||
warned_frac = true;
|
||||
}
|
||||
} else if (std::to_string(id_value) != id->value.string.string) {
|
||||
} else if (std::to_string(id_value) != id->string()) {
|
||||
static bool warned = false;
|
||||
|
||||
if (!warned) {
|
||||
fprintf(stderr, "Warning: Can't represent too-large feature ID %s\n", id->value.string.string);
|
||||
fprintf(stderr, "Warning: Can't represent too-large feature ID %s\n", id->string().c_str());
|
||||
warned = true;
|
||||
}
|
||||
} else {
|
||||
@@ -168,33 +168,29 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
static bool warned_nan = false;
|
||||
|
||||
if (!warned_nan) {
|
||||
char *s = json_stringify(id);
|
||||
fprintf(stderr, "Warning: Can't represent non-numeric feature ID %s\n", s);
|
||||
free(s); // stringify
|
||||
fprintf(stderr, "Warning: Can't represent non-numeric feature ID %s\n", json_stringify(id).c_str());
|
||||
warned_nan = true;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
size_t nprop = 0;
|
||||
if (properties != NULL && properties->type == JSON_HASH) {
|
||||
nprop = properties->value.object.length;
|
||||
}
|
||||
|
||||
std::vector<std::shared_ptr<std::string>> full_keys;
|
||||
std::vector<serial_val> values;
|
||||
|
||||
full_keys.reserve(nprop);
|
||||
values.reserve(nprop);
|
||||
key_pool key_pool;
|
||||
|
||||
for (size_t i = 0; i < nprop; i++) {
|
||||
if (properties->value.object.keys[i]->type == JSON_STRING) {
|
||||
serial_val sv = stringify_value(properties->value.object.values[i], sst->fname, sst->line, feature);
|
||||
if (properties != nullptr && properties->type == JSON_HASH) {
|
||||
const auto &entries = properties->entries();
|
||||
full_keys.reserve(entries.size());
|
||||
values.reserve(entries.size());
|
||||
|
||||
full_keys.emplace_back(key_pool.pool(properties->value.object.keys[i]->value.string.string));
|
||||
values.push_back(std::move(sv));
|
||||
for (const auto &e : entries) {
|
||||
if (e.key->type == JSON_STRING) {
|
||||
serial_val sv = stringify_value(e.value.get(), sst->fname, sst->line, feature);
|
||||
|
||||
full_keys.emplace_back(key_pool.pool(e.key->string()));
|
||||
values.push_back(std::move(sv));
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -220,14 +216,14 @@ int serialize_geojson_feature(struct serialization_state *sst, json_object *geom
|
||||
|
||||
void check_crs(json_object *j, const char *reading) {
|
||||
json_object *crs = json_hash_get(j, "crs");
|
||||
if (crs != NULL) {
|
||||
if (crs != nullptr) {
|
||||
json_object *properties = json_hash_get(crs, "properties");
|
||||
if (properties != NULL) {
|
||||
if (properties != nullptr) {
|
||||
json_object *name = json_hash_get(properties, "name");
|
||||
if (name != NULL && name->type == JSON_STRING) {
|
||||
if (strcmp(name->value.string.string, projection->alias) != 0) {
|
||||
if (name != nullptr && name->type == JSON_STRING) {
|
||||
if (name->string() != projection->alias) {
|
||||
if (!quiet) {
|
||||
fprintf(stderr, "%s: Warning: GeoJSON specified projection \"%s\", not the expected \"%s\".\n", reading, name->value.string.string, projection->alias);
|
||||
fprintf(stderr, "%s: Warning: GeoJSON specified projection \"%s\", not the expected \"%s\".\n", reading, name->string().c_str(), projection->alias);
|
||||
fprintf(stderr, "%s: If \"%s\" is not the expected projection, use -s to specify the right one.\n", reading, projection->alias);
|
||||
}
|
||||
}
|
||||
@@ -242,11 +238,13 @@ struct json_serialize_action : json_feature_action {
|
||||
std::string layername;
|
||||
|
||||
int add_feature(json_object *geometry, bool geometrycollection, json_object *properties, json_object *id, json_object *tippecanoe, json_object *feature) {
|
||||
// Only json_read results reach this; a detached tree has no parser.
|
||||
assert(geometry->parser != nullptr);
|
||||
sst->line = geometry->parser->line;
|
||||
if (geometrycollection) {
|
||||
int ret = 1;
|
||||
for (size_t g = 0; g < geometry->value.array.length; g++) {
|
||||
ret &= serialize_geojson_feature(sst, geometry->value.array.array[g], properties, id, layer, tippecanoe, feature, layername);
|
||||
for (size_t g = 0; g < geometry->array().size(); g++) {
|
||||
ret &= serialize_geojson_feature(sst, geometry->array()[g].get(), properties, id, layer, tippecanoe, feature, layername);
|
||||
}
|
||||
return ret;
|
||||
} else {
|
||||
@@ -259,7 +257,7 @@ struct json_serialize_action : json_feature_action {
|
||||
}
|
||||
};
|
||||
|
||||
void parse_json(struct serialization_state *sst, json_pull *jp, int layer, std::string layername) {
|
||||
void parse_json(struct serialization_state *sst, json_pull_ptr &jp, int layer, std::string layername) {
|
||||
json_serialize_action jsa;
|
||||
jsa.fname = sst->fname;
|
||||
jsa.sst = sst;
|
||||
@@ -296,7 +294,7 @@ ssize_t json_map_read(struct json_pull *jp, char *buffer, size_t n) {
|
||||
return n;
|
||||
}
|
||||
|
||||
struct json_pull *json_begin_map(char *map, long long len) {
|
||||
json_pull_ptr json_begin_map(char *map, long long len) {
|
||||
struct jsonmap *jm = new jsonmap;
|
||||
if (jm == NULL) {
|
||||
perror("Out of memory");
|
||||
@@ -310,7 +308,11 @@ struct json_pull *json_begin_map(char *map, long long len) {
|
||||
return json_begin(json_map_read, jm);
|
||||
}
|
||||
|
||||
void json_end_map(struct json_pull *jp) {
|
||||
void json_end_map(json_pull_ptr &jp) {
|
||||
if (jp == nullptr) {
|
||||
return;
|
||||
}
|
||||
delete (struct jsonmap *) jp->source;
|
||||
jp->source = nullptr;
|
||||
json_end(jp);
|
||||
}
|
||||
|
||||
+6
-6
@@ -10,21 +10,21 @@
|
||||
#include "serial.hpp"
|
||||
|
||||
struct parse_json_args {
|
||||
json_pull *jp;
|
||||
json_pull_ptr jp;
|
||||
int layer;
|
||||
std::string *layername;
|
||||
|
||||
struct serialization_state *sst;
|
||||
|
||||
parse_json_args(json_pull *jp1, int layer1, std::string *layername1, struct serialization_state *sst1)
|
||||
: jp(jp1), layer(layer1), layername(layername1), sst(sst1) {
|
||||
parse_json_args(json_pull_ptr jp1, int layer1, std::string *layername1, struct serialization_state *sst1)
|
||||
: jp(std::move(jp1)), layer(layer1), layername(layername1), sst(sst1) {
|
||||
}
|
||||
};
|
||||
|
||||
struct json_pull *json_begin_map(char *map, long long len);
|
||||
void json_end_map(struct json_pull *jp);
|
||||
json_pull_ptr json_begin_map(char *map, long long len);
|
||||
void json_end_map(json_pull_ptr &jp);
|
||||
|
||||
void parse_json(struct serialization_state *sst, json_pull *jp, int layer, std::string layername);
|
||||
void parse_json(struct serialization_state *sst, json_pull_ptr &jp, int layer, std::string layername);
|
||||
void *run_parse_json(void *v);
|
||||
|
||||
#endif
|
||||
|
||||
+7
-2
@@ -147,7 +147,8 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
double tiny_polygon_size,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
std::string const &accumulate_numeric, size_t feature_limit,
|
||||
std::vector<clipbbox> const &clipbboxes);
|
||||
std::vector<clipbbox> const &clipbboxes,
|
||||
bool deduplicate_by_id);
|
||||
|
||||
std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int ny,
|
||||
int detail, int buffer,
|
||||
@@ -162,7 +163,8 @@ std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int n
|
||||
double tiny_polygon_size,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
std::string const &accumulate_numeric, size_t feature_limit,
|
||||
std::vector<clipbbox> const &clipbboxes);
|
||||
std::vector<clipbbox> const &clipbboxes,
|
||||
bool deduplicate_by_id);
|
||||
|
||||
draw center_of_mass_mp(const drawvec &dv);
|
||||
|
||||
@@ -171,4 +173,7 @@ void get_quadkey_bounds(long long xmin, long long ymin, long long xmax, long lon
|
||||
|
||||
clipbbox parse_clip_poly(std::string arg);
|
||||
|
||||
bool line_is_too_small(drawvec const &geometry, int z, int detail);
|
||||
void coalesce_polygon(drawvec &geom, bool scale_up);
|
||||
|
||||
#endif
|
||||
|
||||
@@ -1,996 +0,0 @@
|
||||
#define _GNU_SOURCE // for asprintf()
|
||||
#include <stdio.h>
|
||||
#include <stdlib.h>
|
||||
#include <ctype.h>
|
||||
#include <string.h>
|
||||
#include <stdarg.h>
|
||||
#include <errno.h>
|
||||
#include "jsonpull.h"
|
||||
#include "../milo/milo.h"
|
||||
|
||||
#define BUFFER 10000
|
||||
|
||||
struct string {
|
||||
char *buf;
|
||||
size_t n;
|
||||
size_t nalloc;
|
||||
};
|
||||
|
||||
static void string_init(struct string *s);
|
||||
static void string_free(struct string *s);
|
||||
|
||||
json_pull *json_begin(ssize_t (*read)(struct json_pull *, char *buffer, size_t n), void *source) {
|
||||
json_pull *j = malloc(sizeof(json_pull));
|
||||
if (j == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
|
||||
j->error = NULL;
|
||||
j->line = 1;
|
||||
j->container = NULL;
|
||||
j->root = NULL;
|
||||
|
||||
j->read = read;
|
||||
j->source = source;
|
||||
j->buffer_head = 0;
|
||||
j->buffer_tail = 0;
|
||||
|
||||
j->buffer = malloc(BUFFER);
|
||||
if (j->buffer == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
|
||||
j->number_buffer = malloc(sizeof(struct string));
|
||||
if (j->number_buffer == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
string_init(j->number_buffer);
|
||||
|
||||
return j;
|
||||
}
|
||||
|
||||
static inline int peek(json_pull *j) {
|
||||
if (j->buffer_head < j->buffer_tail) {
|
||||
return (unsigned char) j->buffer[j->buffer_head];
|
||||
} else {
|
||||
j->buffer_head = 0;
|
||||
j->buffer_tail = j->read(j, j->buffer, BUFFER);
|
||||
if (j->buffer_head >= j->buffer_tail) {
|
||||
return EOF;
|
||||
}
|
||||
return (unsigned char) j->buffer[j->buffer_head];
|
||||
}
|
||||
}
|
||||
|
||||
static inline int next(json_pull *j) {
|
||||
if (j->buffer_head < j->buffer_tail) {
|
||||
return (unsigned char) j->buffer[j->buffer_head++];
|
||||
} else {
|
||||
j->buffer_head = 0;
|
||||
j->buffer_tail = j->read(j, j->buffer, BUFFER);
|
||||
if (j->buffer_head >= j->buffer_tail) {
|
||||
return EOF;
|
||||
}
|
||||
return (unsigned char) j->buffer[j->buffer_head++];
|
||||
}
|
||||
}
|
||||
|
||||
static ssize_t read_file(json_pull *j, char *buffer, size_t n) {
|
||||
return fread(buffer, 1, n, j->source);
|
||||
}
|
||||
|
||||
json_pull *json_begin_file(FILE *f) {
|
||||
return json_begin(read_file, f);
|
||||
}
|
||||
|
||||
static ssize_t read_string(json_pull *j, char *buffer, size_t n) {
|
||||
const char *cp = j->source;
|
||||
size_t out = 0;
|
||||
|
||||
while (out < n && cp[out] != '\0') {
|
||||
buffer[out] = cp[out];
|
||||
out++;
|
||||
}
|
||||
|
||||
j->source = (void *) (cp + out);
|
||||
return out;
|
||||
}
|
||||
|
||||
json_pull *json_begin_string(const char *s) {
|
||||
return json_begin(read_string, (void *) s);
|
||||
}
|
||||
|
||||
void json_end(json_pull *p) {
|
||||
string_free(p->number_buffer);
|
||||
free(p->number_buffer);
|
||||
|
||||
json_free(p->root);
|
||||
free(p->buffer);
|
||||
free(p);
|
||||
}
|
||||
|
||||
static inline int read_wrap(json_pull *j) {
|
||||
int c = next(j);
|
||||
|
||||
if (c == '\n') {
|
||||
j->line++;
|
||||
}
|
||||
|
||||
return c;
|
||||
}
|
||||
|
||||
#define SIZE_FOR(i, size) ((size_t) ((((i) + 7) & ~7) * size))
|
||||
|
||||
static json_object *fabricate_object(json_pull *jp, json_object *parent, json_type type) {
|
||||
json_object *o = malloc(sizeof(struct json_object));
|
||||
if (o == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
o->type = type;
|
||||
o->parent = parent;
|
||||
o->parser = jp;
|
||||
|
||||
if (type == JSON_ARRAY) {
|
||||
o->value.array.array = NULL;
|
||||
o->value.array.length = 0;
|
||||
} else if (type == JSON_HASH) {
|
||||
o->value.object.keys = NULL;
|
||||
o->value.object.values = NULL;
|
||||
o->value.object.length = 0;
|
||||
}
|
||||
|
||||
return o;
|
||||
}
|
||||
|
||||
static json_object *add_object(json_pull *j, json_type type) {
|
||||
json_object *c = j->container;
|
||||
json_object *o = fabricate_object(j, c, type);
|
||||
|
||||
if (c != NULL) {
|
||||
if (c->type == JSON_ARRAY) {
|
||||
if (c->expect == JSON_ITEM) {
|
||||
if (SIZE_FOR(c->value.array.length + 1, sizeof(json_object *)) != SIZE_FOR(c->value.array.length, sizeof(json_object *))) {
|
||||
if (SIZE_FOR(c->value.array.length + 1, sizeof(json_object *)) < SIZE_FOR(c->value.array.length, sizeof(json_object *))) {
|
||||
fprintf(stderr, "Array size overflow\n");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
c->value.array.array = realloc(c->value.array.array, SIZE_FOR(c->value.array.length + 1, sizeof(json_object *)));
|
||||
if (c->value.array.array == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
}
|
||||
|
||||
c->value.array.array[c->value.array.length++] = o;
|
||||
c->expect = JSON_COMMA;
|
||||
} else {
|
||||
j->error = "Expected a comma, not a list item";
|
||||
free(o);
|
||||
return NULL;
|
||||
}
|
||||
} else if (c->type == JSON_HASH) {
|
||||
if (c->expect == JSON_VALUE) {
|
||||
c->value.object.values[c->value.object.length - 1] = o;
|
||||
c->expect = JSON_COMMA;
|
||||
} else if (c->expect == JSON_KEY) {
|
||||
if (type != JSON_STRING) {
|
||||
j->error = "Hash key is not a string";
|
||||
free(o);
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (SIZE_FOR(c->value.object.length + 1, sizeof(json_object *)) != SIZE_FOR(c->value.object.length, sizeof(json_object *))) {
|
||||
if (SIZE_FOR(c->value.object.length + 1, sizeof(json_object *)) < SIZE_FOR(c->value.object.length, sizeof(json_object *))) {
|
||||
fprintf(stderr, "Hash size overflow\n");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
c->value.object.keys = realloc(c->value.object.keys, SIZE_FOR(c->value.object.length + 1, sizeof(json_object *)));
|
||||
c->value.object.values = realloc(c->value.object.values, SIZE_FOR(c->value.object.length + 1, sizeof(json_object *)));
|
||||
if (c->value.object.keys == NULL || c->value.object.values == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
}
|
||||
|
||||
c->value.object.keys[c->value.object.length] = o;
|
||||
c->value.object.values[c->value.object.length] = NULL;
|
||||
c->value.object.length++;
|
||||
c->expect = JSON_COLON;
|
||||
} else {
|
||||
j->error = "Expected a comma or colon";
|
||||
free(o);
|
||||
return NULL;
|
||||
}
|
||||
}
|
||||
} else {
|
||||
if (j->root != NULL) {
|
||||
json_free(j->root);
|
||||
}
|
||||
|
||||
j->root = o;
|
||||
}
|
||||
|
||||
return o;
|
||||
}
|
||||
|
||||
json_object *json_hash_get(json_object *o, const char *s) {
|
||||
if (o == NULL || o->type != JSON_HASH) {
|
||||
return NULL;
|
||||
}
|
||||
|
||||
size_t i;
|
||||
for (i = 0; i < o->value.object.length; i++) {
|
||||
if (o->value.object.keys[i] != NULL && o->value.object.keys[i]->type == JSON_STRING) {
|
||||
if (strcmp(o->value.object.keys[i]->value.string.string, s) == 0) {
|
||||
return o->value.object.values[i];
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return NULL;
|
||||
}
|
||||
|
||||
static void string_init(struct string *s) {
|
||||
s->nalloc = 500;
|
||||
s->buf = malloc(s->nalloc);
|
||||
if (s->buf == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
s->n = 0;
|
||||
s->buf[0] = '\0';
|
||||
}
|
||||
|
||||
static void string_append(struct string *s, char c) {
|
||||
if (s->n + 2 >= s->nalloc) {
|
||||
size_t prev = s->nalloc;
|
||||
s->nalloc += 500;
|
||||
if (s->nalloc <= prev) {
|
||||
fprintf(stderr, "String size overflowed\n");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
s->buf = realloc(s->buf, s->nalloc);
|
||||
if (s->buf == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
}
|
||||
|
||||
s->buf[s->n++] = c;
|
||||
s->buf[s->n] = '\0';
|
||||
}
|
||||
|
||||
static void string_append_string(struct string *s, char *add) {
|
||||
size_t len = strlen(add);
|
||||
|
||||
if (s->n + len + 1 >= s->nalloc) {
|
||||
size_t prev = s->nalloc;
|
||||
s->nalloc += 500 + len;
|
||||
if (s->nalloc <= prev) {
|
||||
fprintf(stderr, "String size overflowed\n");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
s->buf = realloc(s->buf, s->nalloc);
|
||||
if (s->buf == NULL) {
|
||||
perror("Out of memory");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
}
|
||||
|
||||
for (; *add != '\0'; add++) {
|
||||
s->buf[s->n++] = *add;
|
||||
}
|
||||
|
||||
s->buf[s->n] = '\0';
|
||||
}
|
||||
|
||||
static void string_free(struct string *s) {
|
||||
free(s->buf);
|
||||
}
|
||||
|
||||
json_object *json_read_separators(json_pull *j, json_separator_callback cb, void *state) {
|
||||
int c;
|
||||
|
||||
// In case there is an error at the top level
|
||||
if (j->container == NULL) {
|
||||
if (j->root != NULL) {
|
||||
json_free(j->root);
|
||||
}
|
||||
|
||||
j->root = NULL;
|
||||
}
|
||||
|
||||
again:
|
||||
c = read_wrap(j);
|
||||
if (c == EOF) {
|
||||
if (j->container != NULL) {
|
||||
j->error = "Reached EOF without all containers being closed";
|
||||
}
|
||||
|
||||
return NULL;
|
||||
}
|
||||
|
||||
switch (c) {
|
||||
/////////////////////////// Byte order mark
|
||||
|
||||
case 0xEF: {
|
||||
int c2 = peek(j);
|
||||
if (c2 == 0xBB) {
|
||||
c2 = read_wrap(j);
|
||||
c2 = peek(j);
|
||||
if (c2 == 0xBF) {
|
||||
c2 = read_wrap(j);
|
||||
c = ' ';
|
||||
goto again;
|
||||
}
|
||||
}
|
||||
j->error = "Corrupt byte-order mark found";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
/////////////////////////// Whitespace
|
||||
|
||||
case ' ':
|
||||
case '\t':
|
||||
case '\r':
|
||||
case '\n':
|
||||
case 0x1E:
|
||||
goto again;
|
||||
|
||||
/////////////////////////// Arrays
|
||||
|
||||
case '[': {
|
||||
json_object *o = add_object(j, JSON_ARRAY);
|
||||
if (o == NULL) {
|
||||
return NULL;
|
||||
}
|
||||
j->container = o;
|
||||
j->container->expect = JSON_ITEM;
|
||||
|
||||
if (cb != NULL) {
|
||||
cb(JSON_ARRAY, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
case ']': {
|
||||
if (j->container == NULL) {
|
||||
j->error = "Found ] at top level";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (j->container->type != JSON_ARRAY) {
|
||||
j->error = "Found ] not in an array";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (j->container->expect != JSON_COMMA) {
|
||||
if (!(j->container->expect == JSON_ITEM && j->container->value.array.length == 0)) {
|
||||
j->error = "Found ] without final element";
|
||||
return NULL;
|
||||
}
|
||||
}
|
||||
|
||||
json_object *ret = j->container;
|
||||
j->container = ret->parent;
|
||||
return ret;
|
||||
}
|
||||
|
||||
/////////////////////////// Hashes
|
||||
|
||||
case '{': {
|
||||
json_object *o = add_object(j, JSON_HASH);
|
||||
if (o == NULL) {
|
||||
return NULL;
|
||||
}
|
||||
j->container = o;
|
||||
j->container->expect = JSON_KEY;
|
||||
|
||||
if (cb != NULL) {
|
||||
cb(JSON_HASH, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
case '}': {
|
||||
if (j->container == NULL) {
|
||||
j->error = "Found } at top level";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (j->container->type != JSON_HASH) {
|
||||
j->error = "Found } not in a hash";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (j->container->expect != JSON_COMMA) {
|
||||
if (!(j->container->expect == JSON_KEY && j->container->value.object.length == 0)) {
|
||||
j->error = "Found } without final element";
|
||||
return NULL;
|
||||
}
|
||||
}
|
||||
|
||||
json_object *ret = j->container;
|
||||
j->container = ret->parent;
|
||||
return ret;
|
||||
}
|
||||
|
||||
/////////////////////////// Null
|
||||
|
||||
case 'n': {
|
||||
if (read_wrap(j) != 'u' || read_wrap(j) != 'l' || read_wrap(j) != 'l') {
|
||||
j->error = "Found misspelling of null";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
return add_object(j, JSON_NULL);
|
||||
}
|
||||
|
||||
/////////////////////////// NaN
|
||||
|
||||
case 'N': {
|
||||
if (read_wrap(j) != 'a' || read_wrap(j) != 'N') {
|
||||
j->error = "Found misspelling of NaN";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
j->error = "JSON does not allow NaN";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
/////////////////////////// Infinity
|
||||
|
||||
case 'I': {
|
||||
if (read_wrap(j) != 'n' || read_wrap(j) != 'f' || read_wrap(j) != 'i' ||
|
||||
read_wrap(j) != 'n' || read_wrap(j) != 'i' || read_wrap(j) != 't' ||
|
||||
read_wrap(j) != 'y') {
|
||||
j->error = "Found misspelling of Infinity";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
j->error = "JSON does not allow Infinity";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
/////////////////////////// True
|
||||
|
||||
case 't': {
|
||||
if (read_wrap(j) != 'r' || read_wrap(j) != 'u' || read_wrap(j) != 'e') {
|
||||
j->error = "Found misspelling of true";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
return add_object(j, JSON_TRUE);
|
||||
}
|
||||
|
||||
/////////////////////////// False
|
||||
|
||||
case 'f': {
|
||||
if (read_wrap(j) != 'a' || read_wrap(j) != 'l' || read_wrap(j) != 's' || read_wrap(j) != 'e') {
|
||||
j->error = "Found misspelling of false";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
return add_object(j, JSON_FALSE);
|
||||
}
|
||||
|
||||
/////////////////////////// Comma
|
||||
|
||||
case ',': {
|
||||
if (j->container != NULL) {
|
||||
if (j->container->expect != JSON_COMMA) {
|
||||
j->error = "Found unexpected comma";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (j->container->type == JSON_HASH) {
|
||||
j->container->expect = JSON_KEY;
|
||||
} else {
|
||||
j->container->expect = JSON_ITEM;
|
||||
}
|
||||
}
|
||||
|
||||
if (cb != NULL) {
|
||||
cb(JSON_COMMA, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
/////////////////////////// Colon
|
||||
|
||||
case ':': {
|
||||
if (j->container == NULL) {
|
||||
j->error = "Found colon at top level";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
if (j->container->expect != JSON_COLON) {
|
||||
j->error = "Found unexpected colon";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
j->container->expect = JSON_VALUE;
|
||||
|
||||
if (cb != NULL) {
|
||||
cb(JSON_COLON, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
/////////////////////////// Numbers
|
||||
|
||||
case '-':
|
||||
case '0':
|
||||
case '1':
|
||||
case '2':
|
||||
case '3':
|
||||
case '4':
|
||||
case '5':
|
||||
case '6':
|
||||
case '7':
|
||||
case '8':
|
||||
case '9': {
|
||||
j->number_buffer->n = 0;
|
||||
int decimal = 0;
|
||||
|
||||
if (c == '-') {
|
||||
string_append(j->number_buffer, c);
|
||||
c = read_wrap(j);
|
||||
}
|
||||
|
||||
if (c == '0') {
|
||||
string_append(j->number_buffer, c);
|
||||
} else if (c >= '1' && c <= '9') {
|
||||
string_append(j->number_buffer, c);
|
||||
c = peek(j);
|
||||
|
||||
while (c >= '0' && c <= '9') {
|
||||
string_append(j->number_buffer, read_wrap(j));
|
||||
c = peek(j);
|
||||
}
|
||||
}
|
||||
|
||||
if (peek(j) == '.') {
|
||||
string_append(j->number_buffer, read_wrap(j));
|
||||
decimal = 1;
|
||||
|
||||
c = peek(j);
|
||||
if (c < '0' || c > '9') {
|
||||
j->error = "Decimal point without digits";
|
||||
string_free(j->number_buffer);
|
||||
return NULL;
|
||||
}
|
||||
while (c >= '0' && c <= '9') {
|
||||
string_append(j->number_buffer, read_wrap(j));
|
||||
c = peek(j);
|
||||
}
|
||||
}
|
||||
|
||||
c = peek(j);
|
||||
if (c == 'e' || c == 'E') {
|
||||
string_append(j->number_buffer, read_wrap(j));
|
||||
decimal = 1;
|
||||
|
||||
c = peek(j);
|
||||
if (c == '+' || c == '-') {
|
||||
string_append(j->number_buffer, read_wrap(j));
|
||||
}
|
||||
|
||||
c = peek(j);
|
||||
if (c < '0' || c > '9') {
|
||||
j->error = "Exponent without digits";
|
||||
string_free(j->number_buffer);
|
||||
return NULL;
|
||||
}
|
||||
while (c >= '0' && c <= '9') {
|
||||
string_append(j->number_buffer, read_wrap(j));
|
||||
c = peek(j);
|
||||
}
|
||||
}
|
||||
|
||||
json_object *n = add_object(j, JSON_NUMBER);
|
||||
if (n != NULL) {
|
||||
n->value.number.number = atof(j->number_buffer->buf);
|
||||
n->value.number.large_signed = 0;
|
||||
n->value.number.large_unsigned = 0;
|
||||
|
||||
#define MAX_SAFE_INTEGER 9007199254740991.0
|
||||
#define MIN_SAFE_INTEGER -9007199254740991.0
|
||||
|
||||
if (!decimal && n->value.number.number > MAX_SAFE_INTEGER) {
|
||||
errno = 0;
|
||||
char *err = NULL;
|
||||
unsigned long long ull = strtoull(j->number_buffer->buf, &err, 10);
|
||||
if (errno == 0 && (err == NULL || *err == '\0')) {
|
||||
n->value.number.large_unsigned = ull;
|
||||
}
|
||||
}
|
||||
if (!decimal && n->value.number.number < MIN_SAFE_INTEGER) {
|
||||
errno = 0;
|
||||
char *err = NULL;
|
||||
long long ll = strtoll(j->number_buffer->buf, &err, 10);
|
||||
if (errno == 0 && (err == NULL || *err == '\0')) {
|
||||
n->value.number.large_signed = ll;
|
||||
}
|
||||
}
|
||||
}
|
||||
return n;
|
||||
}
|
||||
|
||||
/////////////////////////// Strings
|
||||
|
||||
case '"': {
|
||||
struct string val;
|
||||
string_init(&val);
|
||||
|
||||
int surrogate = -1;
|
||||
while ((c = read_wrap(j)) != EOF) {
|
||||
if (c == '"') {
|
||||
if (surrogate >= 0) {
|
||||
string_append(&val, 0xE0 | (surrogate >> 12));
|
||||
string_append(&val, 0x80 | ((surrogate >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
break;
|
||||
} else if (c == '\\') {
|
||||
c = read_wrap(j);
|
||||
|
||||
if (c == 'u') {
|
||||
char hex[5] = "aaaa";
|
||||
int i;
|
||||
for (i = 0; i < 4; i++) {
|
||||
hex[i] = read_wrap(j);
|
||||
if (hex[i] < '0' || (hex[i] > '9' && hex[i] < 'A') || (hex[i] > 'F' && hex[i] < 'a') || hex[i] > 'f') {
|
||||
j->error = "Invalid \\u hex character";
|
||||
string_free(&val);
|
||||
return NULL;
|
||||
}
|
||||
}
|
||||
|
||||
unsigned long ch = strtoul(hex, NULL, 16);
|
||||
if (ch >= 0xd800 && ch <= 0xdbff) {
|
||||
if (surrogate < 0) {
|
||||
surrogate = ch;
|
||||
} else {
|
||||
// Impossible surrogate, so output the first half,
|
||||
// keep what might be a legitimate new first half.
|
||||
string_append(&val, 0xE0 | (surrogate >> 12));
|
||||
string_append(&val, 0x80 | ((surrogate >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (surrogate & 0x3F));
|
||||
surrogate = ch;
|
||||
}
|
||||
continue;
|
||||
} else if (ch >= 0xdc00 && c <= 0xdfff) {
|
||||
if (surrogate >= 0) {
|
||||
long c1 = surrogate - 0xd800;
|
||||
long c2 = ch - 0xdc00;
|
||||
ch = ((c1 << 10) | c2) + 0x010000;
|
||||
surrogate = -1;
|
||||
}
|
||||
}
|
||||
|
||||
if (surrogate >= 0) {
|
||||
string_append(&val, 0xE0 | (surrogate >> 12));
|
||||
string_append(&val, 0x80 | ((surrogate >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
if (ch <= 0x7F) {
|
||||
string_append(&val, ch);
|
||||
} else if (ch <= 0x7FF) {
|
||||
string_append(&val, 0xC0 | (ch >> 6));
|
||||
string_append(&val, 0x80 | (ch & 0x3F));
|
||||
} else if (ch < 0xFFFF) {
|
||||
string_append(&val, 0xE0 | (ch >> 12));
|
||||
string_append(&val, 0x80 | ((ch >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (ch & 0x3F));
|
||||
} else {
|
||||
string_append(&val, 0xF0 | (ch >> 18));
|
||||
string_append(&val, 0x80 | ((ch >> 12) & 0x3F));
|
||||
string_append(&val, 0x80 | ((ch >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (ch & 0x3F));
|
||||
}
|
||||
} else {
|
||||
if (surrogate >= 0) {
|
||||
string_append(&val, 0xE0 | (surrogate >> 12));
|
||||
string_append(&val, 0x80 | ((surrogate >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
if (c == '"') {
|
||||
string_append(&val, '"');
|
||||
} else if (c == '\\') {
|
||||
string_append(&val, '\\');
|
||||
} else if (c == '/') {
|
||||
string_append(&val, '/');
|
||||
} else if (c == 'b') {
|
||||
string_append(&val, '\b');
|
||||
} else if (c == 'f') {
|
||||
string_append(&val, '\f');
|
||||
} else if (c == 'n') {
|
||||
string_append(&val, '\n');
|
||||
} else if (c == 'r') {
|
||||
string_append(&val, '\r');
|
||||
} else if (c == 't') {
|
||||
string_append(&val, '\t');
|
||||
} else {
|
||||
j->error = "Found backslash followed by unknown character";
|
||||
string_free(&val);
|
||||
return NULL;
|
||||
}
|
||||
}
|
||||
} else if (c < ' ') {
|
||||
j->error = "Found control character in string";
|
||||
string_free(&val);
|
||||
return NULL;
|
||||
} else {
|
||||
if (surrogate >= 0) {
|
||||
string_append(&val, 0xE0 | (surrogate >> 12));
|
||||
string_append(&val, 0x80 | ((surrogate >> 6) & 0x3F));
|
||||
string_append(&val, 0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
string_append(&val, c);
|
||||
}
|
||||
}
|
||||
if (c == EOF) {
|
||||
j->error = "String without closing quote mark";
|
||||
string_free(&val);
|
||||
return NULL;
|
||||
}
|
||||
|
||||
json_object *s = add_object(j, JSON_STRING);
|
||||
if (s != NULL) {
|
||||
s->value.string.string = val.buf;
|
||||
s->value.string.refcon = NULL;
|
||||
} else {
|
||||
string_free(&val);
|
||||
}
|
||||
return s;
|
||||
}
|
||||
}
|
||||
|
||||
j->error = "Found unexpected character";
|
||||
return NULL;
|
||||
}
|
||||
|
||||
json_object *json_read(json_pull *j) {
|
||||
return json_read_separators(j, NULL, NULL);
|
||||
}
|
||||
|
||||
json_object *json_read_tree(json_pull *p) {
|
||||
json_object *j;
|
||||
|
||||
while ((j = json_read(p)) != NULL) {
|
||||
if (j->parent == NULL) {
|
||||
return j;
|
||||
}
|
||||
}
|
||||
|
||||
return NULL;
|
||||
}
|
||||
|
||||
void json_free(json_object *o) {
|
||||
size_t i;
|
||||
|
||||
if (o == NULL) {
|
||||
return;
|
||||
}
|
||||
|
||||
// Free any data linked from here
|
||||
|
||||
if (o->type == JSON_ARRAY) {
|
||||
json_object **a = o->value.array.array;
|
||||
size_t n = o->value.array.length;
|
||||
|
||||
o->value.array.array = NULL;
|
||||
o->value.array.length = 0;
|
||||
|
||||
for (i = 0; i < n; i++) {
|
||||
json_free(a[i]);
|
||||
}
|
||||
|
||||
free(a);
|
||||
} else if (o->type == JSON_HASH) {
|
||||
json_object **k = o->value.object.keys;
|
||||
json_object **v = o->value.object.values;
|
||||
size_t n = o->value.object.length;
|
||||
|
||||
o->value.object.keys = NULL;
|
||||
o->value.object.values = NULL;
|
||||
o->value.object.length = 0;
|
||||
|
||||
for (i = 0; i < n; i++) {
|
||||
json_free(k[i]);
|
||||
json_free(v[i]);
|
||||
}
|
||||
|
||||
free(k);
|
||||
free(v);
|
||||
} else if (o->type == JSON_STRING) {
|
||||
free(o->value.string.string);
|
||||
} else if (o->type == JSON_NUMBER) {
|
||||
;
|
||||
}
|
||||
|
||||
json_disconnect(o);
|
||||
|
||||
free(o);
|
||||
}
|
||||
|
||||
static void json_disconnect_parser(json_object *o) {
|
||||
if (o->type == JSON_HASH) {
|
||||
size_t i;
|
||||
for (i = 0; i < o->value.object.length; i++) {
|
||||
json_disconnect_parser(o->value.object.keys[i]);
|
||||
json_disconnect_parser(o->value.object.values[i]);
|
||||
}
|
||||
} else if (o->type == JSON_ARRAY) {
|
||||
size_t i;
|
||||
for (i = 0; i < o->value.array.length; i++) {
|
||||
json_disconnect_parser(o->value.array.array[i]);
|
||||
}
|
||||
}
|
||||
|
||||
o->parser = NULL;
|
||||
}
|
||||
|
||||
void json_disconnect(json_object *o) {
|
||||
// Expunge references to this as an array element
|
||||
// or a hash key or value.
|
||||
|
||||
if (o->parent != NULL) {
|
||||
if (o->parent->type == JSON_ARRAY) {
|
||||
size_t i;
|
||||
|
||||
for (i = 0; i < o->parent->value.array.length; i++) {
|
||||
if (o->parent->value.array.array[i] == o) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
if (i < o->parent->value.array.length) {
|
||||
memmove(o->parent->value.array.array + i, o->parent->value.array.array + i + 1, o->parent->value.array.length - i - 1);
|
||||
o->parent->value.array.length--;
|
||||
}
|
||||
}
|
||||
|
||||
if (o->parent->type == JSON_HASH) {
|
||||
size_t i;
|
||||
|
||||
for (i = 0; i < o->parent->value.object.length; i++) {
|
||||
if (o->parent->value.object.keys[i] == o) {
|
||||
o->parent->value.object.keys[i] = fabricate_object(o->parser, o->parent, JSON_NULL);
|
||||
break;
|
||||
}
|
||||
if (o->parent->value.object.values[i] == o) {
|
||||
o->parent->value.object.values[i] = fabricate_object(o->parser, o->parent, JSON_NULL);
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
if (i < o->parent->value.object.length) {
|
||||
if (o->parent->value.object.keys[i] != NULL && o->parent->value.object.keys[i]->type == JSON_NULL) {
|
||||
if (o->parent->value.object.values[i] != NULL && o->parent->value.object.values[i]->type == JSON_NULL) {
|
||||
free(o->parent->value.object.keys[i]);
|
||||
free(o->parent->value.object.values[i]);
|
||||
|
||||
memmove(o->parent->value.object.keys + i, o->parent->value.object.keys + i + 1, o->parent->value.object.length - i - 1);
|
||||
memmove(o->parent->value.object.values + i, o->parent->value.object.values + i + 1, o->parent->value.object.length - i - 1);
|
||||
o->parent->value.object.length--;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (o->parser != NULL && o->parser->root == o) {
|
||||
o->parser->root = NULL;
|
||||
}
|
||||
|
||||
json_disconnect_parser(o);
|
||||
o->parent = NULL;
|
||||
}
|
||||
|
||||
static void json_print_one(struct string *val, json_object *o) {
|
||||
if (o == NULL) {
|
||||
string_append_string(val, "...");
|
||||
} else if (o->type == JSON_STRING) {
|
||||
string_append(val, '\"');
|
||||
|
||||
char *cp;
|
||||
for (cp = o->value.string.string; *cp != '\0'; cp++) {
|
||||
if (*cp == '\\' || *cp == '"') {
|
||||
string_append(val, '\\');
|
||||
string_append(val, *cp);
|
||||
} else if (*cp >= 0 && *cp < ' ') {
|
||||
char *s;
|
||||
if (asprintf(&s, "\\u%04x", *cp) >= 0) {
|
||||
string_append_string(val, s);
|
||||
free(s);
|
||||
}
|
||||
} else {
|
||||
string_append(val, *cp);
|
||||
}
|
||||
}
|
||||
|
||||
string_append(val, '\"');
|
||||
} else if (o->type == JSON_NUMBER) {
|
||||
if (o->value.number.large_signed != 0) {
|
||||
char s[65];
|
||||
sprintf(s, "%lld", o->value.number.large_signed);
|
||||
string_append_string(val, s);
|
||||
} else if (o->value.number.large_unsigned != 0) {
|
||||
char s[65];
|
||||
sprintf(s, "%llu", o->value.number.large_unsigned);
|
||||
string_append_string(val, s);
|
||||
} else {
|
||||
char *s = dtoa_milo(o->value.number.number);
|
||||
string_append_string(val, s);
|
||||
free(s);
|
||||
}
|
||||
} else if (o->type == JSON_NULL) {
|
||||
string_append_string(val, "null");
|
||||
} else if (o->type == JSON_TRUE) {
|
||||
string_append_string(val, "true");
|
||||
} else if (o->type == JSON_FALSE) {
|
||||
string_append_string(val, "false");
|
||||
} else if (o->type == JSON_HASH) {
|
||||
string_append(val, '}');
|
||||
} else if (o->type == JSON_ARRAY) {
|
||||
string_append(val, ']');
|
||||
}
|
||||
}
|
||||
|
||||
static void json_print(struct string *val, json_object *o) {
|
||||
if (o == NULL) {
|
||||
// Hash value in incompletely read hash
|
||||
string_append_string(val, "...");
|
||||
} else if (o->type == JSON_HASH) {
|
||||
string_append(val, '{');
|
||||
|
||||
size_t i;
|
||||
for (i = 0; i < o->value.object.length; i++) {
|
||||
json_print(val, o->value.object.keys[i]);
|
||||
string_append(val, ':');
|
||||
json_print(val, o->value.object.values[i]);
|
||||
if (i + 1 < o->value.object.length) {
|
||||
string_append(val, ',');
|
||||
}
|
||||
}
|
||||
string_append(val, '}');
|
||||
} else if (o->type == JSON_ARRAY) {
|
||||
string_append(val, '[');
|
||||
size_t i;
|
||||
for (i = 0; i < o->value.array.length; i++) {
|
||||
json_print(val, o->value.array.array[i]);
|
||||
if (i + 1 < o->value.array.length) {
|
||||
string_append(val, ',');
|
||||
}
|
||||
}
|
||||
string_append(val, ']');
|
||||
} else {
|
||||
json_print_one(val, o);
|
||||
}
|
||||
}
|
||||
|
||||
char *json_stringify(json_object *o) {
|
||||
struct string val;
|
||||
string_init(&val);
|
||||
json_print(&val, o);
|
||||
|
||||
return val.buf;
|
||||
}
|
||||
@@ -0,0 +1,857 @@
|
||||
#ifndef _GNU_SOURCE
|
||||
#define _GNU_SOURCE // for asprintf()
|
||||
#endif
|
||||
#include <stdio.h>
|
||||
#include <stdlib.h>
|
||||
#include <ctype.h>
|
||||
#include <string.h>
|
||||
#include <stdarg.h>
|
||||
#include <errno.h>
|
||||
#include <memory>
|
||||
#include <string>
|
||||
#include <vector>
|
||||
#include "jsonpull.h"
|
||||
#include "../milo/milo.h"
|
||||
|
||||
#define BUFFER 10000
|
||||
|
||||
json_pull_ptr json_begin(ssize_t (*read)(struct json_pull *, char *buffer, size_t n), void *source) {
|
||||
auto j = std::make_shared<json_pull>();
|
||||
j->read = read;
|
||||
j->source = source;
|
||||
j->buffer.resize(BUFFER);
|
||||
return j;
|
||||
}
|
||||
|
||||
static inline int peek(json_pull *j) {
|
||||
if (j->buffer_head < j->buffer_tail) {
|
||||
return (unsigned char) j->buffer[j->buffer_head];
|
||||
} else {
|
||||
j->buffer_head = 0;
|
||||
j->buffer_tail = j->read(j, j->buffer.data(), BUFFER);
|
||||
if (j->buffer_head >= j->buffer_tail) {
|
||||
return EOF;
|
||||
}
|
||||
return (unsigned char) j->buffer[j->buffer_head];
|
||||
}
|
||||
}
|
||||
|
||||
static inline int next(json_pull *j) {
|
||||
if (j->buffer_head < j->buffer_tail) {
|
||||
return (unsigned char) j->buffer[j->buffer_head++];
|
||||
} else {
|
||||
j->buffer_head = 0;
|
||||
j->buffer_tail = j->read(j, j->buffer.data(), BUFFER);
|
||||
if (j->buffer_head >= j->buffer_tail) {
|
||||
return EOF;
|
||||
}
|
||||
return (unsigned char) j->buffer[j->buffer_head++];
|
||||
}
|
||||
}
|
||||
|
||||
static ssize_t read_file(json_pull *j, char *buffer, size_t n) {
|
||||
return fread(buffer, 1, n, (FILE *) j->source);
|
||||
}
|
||||
|
||||
json_pull_ptr json_begin_file(FILE *f) {
|
||||
return json_begin(read_file, f);
|
||||
}
|
||||
|
||||
static ssize_t read_string(json_pull *j, char *buffer, size_t n) {
|
||||
const char *cp = (const char *) j->source;
|
||||
size_t out = 0;
|
||||
|
||||
while (out < n && cp[out] != '\0') {
|
||||
buffer[out] = cp[out];
|
||||
out++;
|
||||
}
|
||||
|
||||
j->source = (void *) (cp + out);
|
||||
return out;
|
||||
}
|
||||
|
||||
json_pull_ptr json_begin_string(const char *s) {
|
||||
return json_begin(read_string, (void *) s);
|
||||
}
|
||||
|
||||
void json_end(json_pull_ptr &p) {
|
||||
p.reset();
|
||||
}
|
||||
|
||||
static inline int read_wrap(json_pull *j) {
|
||||
int c = next(j);
|
||||
|
||||
if (c == '\n') {
|
||||
j->line++;
|
||||
}
|
||||
|
||||
return c;
|
||||
}
|
||||
|
||||
// JSON_TRUE / JSON_FALSE / JSON_NULL and the parse-token types are bare
|
||||
// json_objects; the value-bearing types each get their own subclass.
|
||||
static json_object_ptr make_object(json_type type, json_object *parent, json_pull *jp) {
|
||||
switch (type) {
|
||||
case JSON_NUMBER:
|
||||
return json_object_ptr(new json_number(parent, jp));
|
||||
case JSON_STRING:
|
||||
return json_object_ptr(new json_string(parent, jp));
|
||||
case JSON_ARRAY:
|
||||
return json_object_ptr(new json_array(parent, jp));
|
||||
case JSON_HASH:
|
||||
return json_object_ptr(new json_hash(parent, jp));
|
||||
default:
|
||||
return json_object_ptr(new json_object(type, parent, jp));
|
||||
}
|
||||
}
|
||||
|
||||
static inline json_pull::parse_frame *current_frame(json_pull *j) {
|
||||
return j->container_stack.empty() ? nullptr : &j->container_stack.back();
|
||||
}
|
||||
|
||||
// Install a new node of `type` in the current container, or as the parser's
|
||||
// root if the stack is empty. Returns it borrowed, or nullptr after setting
|
||||
// j->error.
|
||||
static json_object *add_object(json_pull *j, json_type type) {
|
||||
json_pull::parse_frame *f = current_frame(j);
|
||||
json_object *c = f ? f->container : nullptr;
|
||||
json_object_ptr o = make_object(type, c, j);
|
||||
json_object *raw = o.get();
|
||||
|
||||
if (f != nullptr) {
|
||||
if (c->type == JSON_ARRAY) {
|
||||
if (f->expect == JSON_ITEM) {
|
||||
c->array().push_back(std::move(o));
|
||||
f->expect = JSON_COMMA;
|
||||
} else {
|
||||
j->error = "Expected a comma, not a list item";
|
||||
return nullptr;
|
||||
}
|
||||
} else if (c->type == JSON_HASH) {
|
||||
if (f->expect == JSON_VALUE) {
|
||||
// A colon is the only thing that sets JSON_VALUE, and it
|
||||
// requires a key already pushed.
|
||||
assert(!c->entries().empty());
|
||||
c->entries().back().value = std::move(o);
|
||||
f->expect = JSON_COMMA;
|
||||
} else if (f->expect == JSON_KEY) {
|
||||
if (type != JSON_STRING) {
|
||||
j->error = "Hash key is not a string";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
c->entries().push_back({std::move(o), nullptr});
|
||||
f->expect = JSON_COLON;
|
||||
} else {
|
||||
j->error = "Expected a comma or colon";
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
} else {
|
||||
// Replacing the parser's root destroys the previous top-level
|
||||
// value (if no one called json_disconnect / json_read_tree to
|
||||
// take ownership of it).
|
||||
j->root = std::move(o);
|
||||
}
|
||||
|
||||
return raw;
|
||||
}
|
||||
|
||||
json_object *json_hash_get(json_object *o, const char *s) {
|
||||
if (o == nullptr || o->type != JSON_HASH) {
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
for (const auto &e : o->entries()) {
|
||||
if (e.key != nullptr && e.key->type == JSON_STRING && e.key->string() == s) {
|
||||
return e.value.get();
|
||||
}
|
||||
}
|
||||
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
json_object *json_hash_get(const json_object_ptr &o, const char *s) {
|
||||
return json_hash_get(o.get(), s);
|
||||
}
|
||||
|
||||
json_object *json_read_separators(json_pull_ptr &jp, json_separator_callback cb, void *state) {
|
||||
int c;
|
||||
json_pull *j = jp.get();
|
||||
|
||||
// In case there is an error at the top level
|
||||
if (j->container_stack.empty()) {
|
||||
j->root.reset();
|
||||
}
|
||||
|
||||
again:
|
||||
c = read_wrap(j);
|
||||
if (c == EOF) {
|
||||
if (!j->container_stack.empty()) {
|
||||
j->error = "Reached EOF without all containers being closed";
|
||||
}
|
||||
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
switch (c) {
|
||||
/////////////////////////// Byte order mark
|
||||
|
||||
case 0xEF: {
|
||||
int c2 = peek(j);
|
||||
if (c2 == 0xBB) {
|
||||
c2 = read_wrap(j);
|
||||
c2 = peek(j);
|
||||
if (c2 == 0xBF) {
|
||||
c2 = read_wrap(j);
|
||||
c = ' ';
|
||||
goto again;
|
||||
}
|
||||
}
|
||||
j->error = "Corrupt byte-order mark found";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
/////////////////////////// Whitespace
|
||||
|
||||
case ' ':
|
||||
case '\t':
|
||||
case '\r':
|
||||
case '\n':
|
||||
case 0x1E:
|
||||
goto again;
|
||||
|
||||
/////////////////////////// Arrays
|
||||
|
||||
case '[': {
|
||||
json_object *o = add_object(j, JSON_ARRAY);
|
||||
if (o == nullptr) {
|
||||
return nullptr;
|
||||
}
|
||||
j->container_stack.push_back({o, JSON_ITEM});
|
||||
|
||||
if (cb != nullptr) {
|
||||
cb(JSON_ARRAY, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
case ']': {
|
||||
json_pull::parse_frame *f = current_frame(j);
|
||||
if (f == nullptr) {
|
||||
j->error = "Found ] at top level";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
json_object *cc = f->container;
|
||||
if (cc->type != JSON_ARRAY) {
|
||||
j->error = "Found ] not in an array";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
if (f->expect != JSON_COMMA) {
|
||||
if (!(f->expect == JSON_ITEM && cc->array().size() == 0)) {
|
||||
j->error = "Found ] without final element";
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
|
||||
j->container_stack.pop_back();
|
||||
return cc;
|
||||
}
|
||||
|
||||
/////////////////////////// Hashes
|
||||
|
||||
case '{': {
|
||||
json_object *o = add_object(j, JSON_HASH);
|
||||
if (o == nullptr) {
|
||||
return nullptr;
|
||||
}
|
||||
j->container_stack.push_back({o, JSON_KEY});
|
||||
|
||||
if (cb != nullptr) {
|
||||
cb(JSON_HASH, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
case '}': {
|
||||
json_pull::parse_frame *f = current_frame(j);
|
||||
if (f == nullptr) {
|
||||
j->error = "Found } at top level";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
json_object *cc = f->container;
|
||||
if (cc->type != JSON_HASH) {
|
||||
j->error = "Found } not in a hash";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
if (f->expect != JSON_COMMA) {
|
||||
if (!(f->expect == JSON_KEY && cc->entries().size() == 0)) {
|
||||
j->error = "Found } without final element";
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
|
||||
j->container_stack.pop_back();
|
||||
return cc;
|
||||
}
|
||||
|
||||
/////////////////////////// Null
|
||||
|
||||
case 'n': {
|
||||
if (read_wrap(j) != 'u' || read_wrap(j) != 'l' || read_wrap(j) != 'l') {
|
||||
j->error = "Found misspelling of null";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
return add_object(j, JSON_NULL);
|
||||
}
|
||||
|
||||
/////////////////////////// NaN
|
||||
|
||||
case 'N': {
|
||||
if (read_wrap(j) != 'a' || read_wrap(j) != 'N') {
|
||||
j->error = "Found misspelling of NaN";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
j->error = "JSON does not allow NaN";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
/////////////////////////// Infinity
|
||||
|
||||
case 'I': {
|
||||
if (read_wrap(j) != 'n' || read_wrap(j) != 'f' || read_wrap(j) != 'i' ||
|
||||
read_wrap(j) != 'n' || read_wrap(j) != 'i' || read_wrap(j) != 't' ||
|
||||
read_wrap(j) != 'y') {
|
||||
j->error = "Found misspelling of Infinity";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
j->error = "JSON does not allow Infinity";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
/////////////////////////// True
|
||||
|
||||
case 't': {
|
||||
if (read_wrap(j) != 'r' || read_wrap(j) != 'u' || read_wrap(j) != 'e') {
|
||||
j->error = "Found misspelling of true";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
return add_object(j, JSON_TRUE);
|
||||
}
|
||||
|
||||
/////////////////////////// False
|
||||
|
||||
case 'f': {
|
||||
if (read_wrap(j) != 'a' || read_wrap(j) != 'l' || read_wrap(j) != 's' || read_wrap(j) != 'e') {
|
||||
j->error = "Found misspelling of false";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
return add_object(j, JSON_FALSE);
|
||||
}
|
||||
|
||||
/////////////////////////// Comma
|
||||
|
||||
case ',': {
|
||||
json_pull::parse_frame *f = current_frame(j);
|
||||
if (f != nullptr) {
|
||||
if (f->expect != JSON_COMMA) {
|
||||
j->error = "Found unexpected comma";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
if (f->container->type == JSON_HASH) {
|
||||
f->expect = JSON_KEY;
|
||||
} else {
|
||||
f->expect = JSON_ITEM;
|
||||
}
|
||||
}
|
||||
|
||||
if (cb != nullptr) {
|
||||
cb(JSON_COMMA, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
/////////////////////////// Colon
|
||||
|
||||
case ':': {
|
||||
json_pull::parse_frame *f = current_frame(j);
|
||||
if (f == nullptr) {
|
||||
j->error = "Found colon at top level";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
if (f->expect != JSON_COLON) {
|
||||
j->error = "Found unexpected colon";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
f->expect = JSON_VALUE;
|
||||
|
||||
if (cb != nullptr) {
|
||||
cb(JSON_COLON, j, state);
|
||||
}
|
||||
|
||||
goto again;
|
||||
}
|
||||
|
||||
/////////////////////////// Numbers
|
||||
|
||||
case '-':
|
||||
case '0':
|
||||
case '1':
|
||||
case '2':
|
||||
case '3':
|
||||
case '4':
|
||||
case '5':
|
||||
case '6':
|
||||
case '7':
|
||||
case '8':
|
||||
case '9': {
|
||||
j->number_buffer.clear();
|
||||
int decimal = 0;
|
||||
|
||||
if (c == '-') {
|
||||
j->number_buffer.push_back(c);
|
||||
c = read_wrap(j);
|
||||
}
|
||||
|
||||
if (c == '0') {
|
||||
j->number_buffer.push_back(c);
|
||||
} else if (c >= '1' && c <= '9') {
|
||||
j->number_buffer.push_back(c);
|
||||
c = peek(j);
|
||||
|
||||
while (c >= '0' && c <= '9') {
|
||||
j->number_buffer.push_back(read_wrap(j));
|
||||
c = peek(j);
|
||||
}
|
||||
}
|
||||
|
||||
if (peek(j) == '.') {
|
||||
j->number_buffer.push_back(read_wrap(j));
|
||||
decimal = 1;
|
||||
|
||||
c = peek(j);
|
||||
if (c < '0' || c > '9') {
|
||||
j->error = "Decimal point without digits";
|
||||
return nullptr;
|
||||
}
|
||||
while (c >= '0' && c <= '9') {
|
||||
j->number_buffer.push_back(read_wrap(j));
|
||||
c = peek(j);
|
||||
}
|
||||
}
|
||||
|
||||
c = peek(j);
|
||||
if (c == 'e' || c == 'E') {
|
||||
j->number_buffer.push_back(read_wrap(j));
|
||||
decimal = 1;
|
||||
|
||||
c = peek(j);
|
||||
if (c == '+' || c == '-') {
|
||||
j->number_buffer.push_back(read_wrap(j));
|
||||
}
|
||||
|
||||
c = peek(j);
|
||||
if (c < '0' || c > '9') {
|
||||
j->error = "Exponent without digits";
|
||||
return nullptr;
|
||||
}
|
||||
while (c >= '0' && c <= '9') {
|
||||
j->number_buffer.push_back(read_wrap(j));
|
||||
c = peek(j);
|
||||
}
|
||||
}
|
||||
|
||||
json_object *n = add_object(j, JSON_NUMBER);
|
||||
if (n != nullptr) {
|
||||
double d = atof(j->number_buffer.c_str());
|
||||
n->set_number(d);
|
||||
|
||||
#define MAX_SAFE_INTEGER 9007199254740991.0
|
||||
#define MIN_SAFE_INTEGER -9007199254740991.0
|
||||
|
||||
if (!decimal && d > MAX_SAFE_INTEGER) {
|
||||
errno = 0;
|
||||
char *err = nullptr;
|
||||
unsigned long long ull = strtoull(j->number_buffer.c_str(), &err, 10);
|
||||
if (errno == 0 && (err == nullptr || *err == '\0')) {
|
||||
n->set_large_unsigned(ull);
|
||||
}
|
||||
}
|
||||
if (!decimal && d < MIN_SAFE_INTEGER) {
|
||||
errno = 0;
|
||||
char *err = nullptr;
|
||||
long long ll = strtoll(j->number_buffer.c_str(), &err, 10);
|
||||
if (errno == 0 && (err == nullptr || *err == '\0')) {
|
||||
n->set_large_signed(ll);
|
||||
}
|
||||
}
|
||||
}
|
||||
return n;
|
||||
}
|
||||
|
||||
/////////////////////////// Strings
|
||||
|
||||
case '"': {
|
||||
// Reused across tokens; see json_pull::string_buffer.
|
||||
std::string &val = j->string_buffer;
|
||||
val.clear();
|
||||
|
||||
int surrogate = -1;
|
||||
while ((c = read_wrap(j)) != EOF) {
|
||||
if (c == '"') {
|
||||
if (surrogate >= 0) {
|
||||
val.push_back(0xE0 | (surrogate >> 12));
|
||||
val.push_back(0x80 | ((surrogate >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
break;
|
||||
} else if (c == '\\') {
|
||||
c = read_wrap(j);
|
||||
|
||||
if (c == 'u') {
|
||||
char hex[5] = "aaaa";
|
||||
int i;
|
||||
for (i = 0; i < 4; i++) {
|
||||
hex[i] = read_wrap(j);
|
||||
if (hex[i] < '0' || (hex[i] > '9' && hex[i] < 'A') || (hex[i] > 'F' && hex[i] < 'a') || hex[i] > 'f') {
|
||||
j->error = "Invalid \\u hex character";
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
|
||||
unsigned long ch = strtoul(hex, nullptr, 16);
|
||||
if (ch >= 0xd800 && ch <= 0xdbff) {
|
||||
if (surrogate < 0) {
|
||||
surrogate = ch;
|
||||
} else {
|
||||
// Impossible surrogate, so output the first half,
|
||||
// keep what might be a legitimate new first half.
|
||||
val.push_back(0xE0 | (surrogate >> 12));
|
||||
val.push_back(0x80 | ((surrogate >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (surrogate & 0x3F));
|
||||
surrogate = ch;
|
||||
}
|
||||
continue;
|
||||
} else if (ch >= 0xdc00 && ch <= 0xdfff) {
|
||||
if (surrogate >= 0) {
|
||||
long c1 = surrogate - 0xd800;
|
||||
long c2 = ch - 0xdc00;
|
||||
ch = ((c1 << 10) | c2) + 0x010000;
|
||||
surrogate = -1;
|
||||
}
|
||||
}
|
||||
|
||||
if (surrogate >= 0) {
|
||||
val.push_back(0xE0 | (surrogate >> 12));
|
||||
val.push_back(0x80 | ((surrogate >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
if (ch <= 0x7F) {
|
||||
val.push_back(ch);
|
||||
} else if (ch <= 0x7FF) {
|
||||
val.push_back(0xC0 | (ch >> 6));
|
||||
val.push_back(0x80 | (ch & 0x3F));
|
||||
} else if (ch <= 0xFFFF) {
|
||||
val.push_back(0xE0 | (ch >> 12));
|
||||
val.push_back(0x80 | ((ch >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (ch & 0x3F));
|
||||
} else {
|
||||
// Only reachable for a code point assembled from a
|
||||
// surrogate pair above, since `ch` on its own comes
|
||||
// from four hex digits and so cannot exceed 0xFFFF.
|
||||
val.push_back(0xF0 | (ch >> 18));
|
||||
val.push_back(0x80 | ((ch >> 12) & 0x3F));
|
||||
val.push_back(0x80 | ((ch >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (ch & 0x3F));
|
||||
}
|
||||
} else {
|
||||
if (surrogate >= 0) {
|
||||
val.push_back(0xE0 | (surrogate >> 12));
|
||||
val.push_back(0x80 | ((surrogate >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
if (c == '"') {
|
||||
val.push_back('"');
|
||||
} else if (c == '\\') {
|
||||
val.push_back('\\');
|
||||
} else if (c == '/') {
|
||||
val.push_back('/');
|
||||
} else if (c == 'b') {
|
||||
val.push_back('\b');
|
||||
} else if (c == 'f') {
|
||||
val.push_back('\f');
|
||||
} else if (c == 'n') {
|
||||
val.push_back('\n');
|
||||
} else if (c == 'r') {
|
||||
val.push_back('\r');
|
||||
} else if (c == 't') {
|
||||
val.push_back('\t');
|
||||
} else {
|
||||
j->error = "Found backslash followed by unknown character";
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
} else if (c < ' ') {
|
||||
j->error = "Found control character in string";
|
||||
return nullptr;
|
||||
} else {
|
||||
if (surrogate >= 0) {
|
||||
val.push_back(0xE0 | (surrogate >> 12));
|
||||
val.push_back(0x80 | ((surrogate >> 6) & 0x3F));
|
||||
val.push_back(0x80 | (surrogate & 0x3F));
|
||||
surrogate = -1;
|
||||
}
|
||||
|
||||
val.push_back(c);
|
||||
}
|
||||
}
|
||||
if (c == EOF) {
|
||||
j->error = "String without closing quote mark";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
json_object *s = add_object(j, JSON_STRING);
|
||||
if (s != nullptr) {
|
||||
// Copy, not move, so the buffer keeps its capacity.
|
||||
s->string() = val;
|
||||
}
|
||||
return s;
|
||||
}
|
||||
}
|
||||
|
||||
j->error = "Found unexpected character";
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
json_object *json_read(json_pull_ptr &j) {
|
||||
return json_read_separators(j, nullptr, nullptr);
|
||||
}
|
||||
|
||||
static void detach_subtree(json_object *o);
|
||||
|
||||
json_object_ptr json_read_tree(json_pull_ptr &p) {
|
||||
json_object *j;
|
||||
|
||||
while ((j = json_read(p)) != nullptr) {
|
||||
if (j->parent == nullptr) {
|
||||
json_object_ptr tree = std::move(p->root);
|
||||
detach_subtree(tree.get());
|
||||
return tree;
|
||||
}
|
||||
}
|
||||
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
// Move the owning json_object_ptr out of whatever vector slot or hash entry
|
||||
// holds `o`. Empty if nothing tracked owns it -- already detached, or borrowed
|
||||
// from elsewhere.
|
||||
//
|
||||
// Detaching one half of a hash entry would disturb the surrounding key/value
|
||||
// pairing, so the extracted half is replaced by a JSON_NULL placeholder and the
|
||||
// entry is erased only once both halves are gone.
|
||||
static json_object_ptr take_from_owner(json_object *o) {
|
||||
if (o == nullptr) {
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
json_object *parent = o->parent;
|
||||
if (parent == nullptr) {
|
||||
// Top-level value: the parser owns it via root, unless the
|
||||
// caller already moved it out.
|
||||
json_pull *parser = o->parser;
|
||||
if (parser != nullptr && parser->root.get() == o) {
|
||||
return std::move(parser->root);
|
||||
}
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
if (parent->type == JSON_ARRAY) {
|
||||
auto &arr = parent->array();
|
||||
for (size_t i = 0; i < arr.size(); i++) {
|
||||
if (arr[i].get() == o) {
|
||||
json_object_ptr taken = std::move(arr[i]);
|
||||
arr.erase(arr.begin() + i);
|
||||
return taken;
|
||||
}
|
||||
}
|
||||
} else if (parent->type == JSON_HASH) {
|
||||
auto &entries = parent->entries();
|
||||
for (size_t i = 0; i < entries.size(); i++) {
|
||||
auto &e = entries[i];
|
||||
if (e.key.get() == o) {
|
||||
json_object_ptr taken = std::move(e.key);
|
||||
e.key = make_object(JSON_NULL, parent, parent->parser);
|
||||
if (e.value != nullptr && e.value->type == JSON_NULL && e.key->type == JSON_NULL) {
|
||||
entries.erase(entries.begin() + i);
|
||||
}
|
||||
return taken;
|
||||
}
|
||||
if (e.value.get() == o) {
|
||||
json_object_ptr taken = std::move(e.value);
|
||||
e.value = make_object(JSON_NULL, parent, parent->parser);
|
||||
if (e.key != nullptr && e.key->type == JSON_NULL && e.value->type == JSON_NULL) {
|
||||
entries.erase(entries.begin() + i);
|
||||
}
|
||||
return taken;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return nullptr;
|
||||
}
|
||||
|
||||
// Splice `o` out of its owner and destroy it; `o` dangles afterwards. No need
|
||||
// to clear back-pointers, since nothing will observe them again.
|
||||
void json_free(json_object *o) {
|
||||
(void) take_from_owner(o);
|
||||
}
|
||||
|
||||
// See Ownership model in jsonpull.h for why only `parser` is cleared here.
|
||||
static void clear_parser_pointers(json_object *o) {
|
||||
if (o == nullptr) {
|
||||
return;
|
||||
}
|
||||
|
||||
if (o->type == JSON_HASH) {
|
||||
for (const auto &e : o->entries()) {
|
||||
clear_parser_pointers(e.key.get());
|
||||
clear_parser_pointers(e.value.get());
|
||||
}
|
||||
} else if (o->type == JSON_ARRAY) {
|
||||
const auto &arr = o->array();
|
||||
for (size_t i = 0; i < arr.size(); i++) {
|
||||
clear_parser_pointers(arr[i].get());
|
||||
}
|
||||
}
|
||||
|
||||
o->parser = nullptr;
|
||||
}
|
||||
|
||||
// The root's `parent` pointed out of the subtree, at a node the parser still
|
||||
// owns; leaving it set would make a later json_free look for this node in a
|
||||
// container that no longer holds it.
|
||||
static void detach_subtree(json_object *o) {
|
||||
if (o == nullptr) {
|
||||
return;
|
||||
}
|
||||
|
||||
clear_parser_pointers(o);
|
||||
o->parent = nullptr;
|
||||
}
|
||||
|
||||
json_object_ptr json_disconnect(json_object *o) {
|
||||
json_object_ptr taken = take_from_owner(o);
|
||||
if (taken != nullptr) {
|
||||
detach_subtree(taken.get());
|
||||
}
|
||||
return taken;
|
||||
}
|
||||
|
||||
static void json_print_one(std::string &val, const json_object *o) {
|
||||
if (o == nullptr) {
|
||||
val.append("...");
|
||||
} else if (o->type == JSON_STRING) {
|
||||
val.push_back('\"');
|
||||
|
||||
// Range, not c_str(): the value may contain an embedded NUL, which the
|
||||
// control-character branch below escapes like any other.
|
||||
for (char c : o->string()) {
|
||||
if (c == '\\' || c == '"') {
|
||||
val.push_back('\\');
|
||||
val.push_back(c);
|
||||
} else if (c >= 0 && c < ' ') {
|
||||
char *s;
|
||||
if (asprintf(&s, "\\u%04x", c) >= 0) {
|
||||
val.append(s);
|
||||
free(s);
|
||||
}
|
||||
} else {
|
||||
val.push_back(c);
|
||||
}
|
||||
}
|
||||
|
||||
val.push_back('\"');
|
||||
} else if (o->type == JSON_NUMBER) {
|
||||
if (o->large_signed() != 0) {
|
||||
char s[65];
|
||||
snprintf(s, sizeof(s), "%lld", o->large_signed());
|
||||
val.append(s);
|
||||
} else if (o->large_unsigned() != 0) {
|
||||
char s[65];
|
||||
snprintf(s, sizeof(s), "%llu", o->large_unsigned());
|
||||
val.append(s);
|
||||
} else {
|
||||
char *s = dtoa_milo(o->number());
|
||||
val.append(s);
|
||||
free(s);
|
||||
}
|
||||
} else if (o->type == JSON_NULL) {
|
||||
val.append("null");
|
||||
} else if (o->type == JSON_TRUE) {
|
||||
val.append("true");
|
||||
} else if (o->type == JSON_FALSE) {
|
||||
val.append("false");
|
||||
}
|
||||
// JSON_HASH and JSON_ARRAY never reach here: json_print handles both
|
||||
// itself and only delegates to json_print_one for the scalar types.
|
||||
}
|
||||
|
||||
static void json_print(std::string &val, const json_object *o) {
|
||||
if (o == nullptr) {
|
||||
// Hash value in incompletely read hash
|
||||
val.append("...");
|
||||
} else if (o->type == JSON_HASH) {
|
||||
val.push_back('{');
|
||||
|
||||
const auto &entries = o->entries();
|
||||
for (size_t i = 0; i < entries.size(); i++) {
|
||||
json_print(val, entries[i].key.get());
|
||||
val.push_back(':');
|
||||
json_print(val, entries[i].value.get());
|
||||
if (i + 1 < entries.size()) {
|
||||
val.push_back(',');
|
||||
}
|
||||
}
|
||||
val.push_back('}');
|
||||
} else if (o->type == JSON_ARRAY) {
|
||||
val.push_back('[');
|
||||
const auto &arr = o->array();
|
||||
for (size_t i = 0; i < arr.size(); i++) {
|
||||
json_print(val, arr[i].get());
|
||||
if (i + 1 < arr.size()) {
|
||||
val.push_back(',');
|
||||
}
|
||||
}
|
||||
val.push_back(']');
|
||||
} else {
|
||||
json_print_one(val, o);
|
||||
}
|
||||
}
|
||||
|
||||
std::string json_stringify(const json_object *o) {
|
||||
std::string val;
|
||||
json_print(val, o);
|
||||
return val;
|
||||
}
|
||||
+281
-54
@@ -1,9 +1,12 @@
|
||||
#ifndef JSONPULL_H
|
||||
#define JSONPULL_H
|
||||
|
||||
#ifdef __cplusplus
|
||||
extern "C" {
|
||||
#endif
|
||||
#include <stdio.h>
|
||||
#include <sys/types.h>
|
||||
#include <cassert>
|
||||
#include <memory>
|
||||
#include <string>
|
||||
#include <vector>
|
||||
|
||||
typedef enum json_type {
|
||||
// These types can be returned by json_read()
|
||||
@@ -25,74 +28,298 @@ typedef enum json_type {
|
||||
JSON_VALUE,
|
||||
} json_type;
|
||||
|
||||
typedef struct json_object {
|
||||
struct json_object *parent;
|
||||
struct json_pull *parser;
|
||||
struct json_object;
|
||||
struct json_pull;
|
||||
|
||||
union {
|
||||
struct {
|
||||
double number;
|
||||
unsigned long long large_unsigned;
|
||||
long long large_signed;
|
||||
} number;
|
||||
// Ownership model
|
||||
//
|
||||
// Every node has exactly one owner: its parent (a json_object_ptr in the
|
||||
// parent's vector or hash entry), the parser (jp->root) for a top-level value,
|
||||
// or the caller once json_read_tree / json_disconnect hands the tree over.
|
||||
// json_read and json_hash_get return borrowed pointers, valid while the owning
|
||||
// container is intact.
|
||||
//
|
||||
// `parent` and `parser` are non-owning, so they cannot form a cycle. Detaching
|
||||
// clears every `parser` in the subtree, since the json_pull may die first, and
|
||||
// clears `parent` only on the detached root, which pointed out of the subtree.
|
||||
// Interior `parent` links stay, so a detached tree is still walkable upwards
|
||||
// and json_free / json_disconnect still work inside it -- both find a node's
|
||||
// owner through `parent`.
|
||||
//
|
||||
// json_object has no vptr; json_object_deleter switches on `type` and
|
||||
// static_casts so the right subclass destructor runs. Payloads live in those
|
||||
// subclasses rather than one wide struct, and the accessors assert on `type`
|
||||
// before downcasting.
|
||||
//
|
||||
// json_pull_ptr is a shared_ptr: a parser is created and freed once.
|
||||
|
||||
struct {
|
||||
char *string;
|
||||
void *refcon; // reference constant for caller's use
|
||||
} string;
|
||||
// Stateless, so json_object_ptr stays one pointer wide. See Ownership model.
|
||||
struct json_object_deleter {
|
||||
void operator()(json_object *p) const noexcept;
|
||||
};
|
||||
|
||||
struct {
|
||||
struct json_object **array;
|
||||
size_t length;
|
||||
} array;
|
||||
typedef std::unique_ptr<json_object, json_object_deleter> json_object_ptr;
|
||||
typedef std::shared_ptr<json_pull> json_pull_ptr;
|
||||
|
||||
struct {
|
||||
struct json_object **keys;
|
||||
struct json_object **values;
|
||||
size_t length;
|
||||
} object;
|
||||
} value;
|
||||
// One key/value pair in a JSON_HASH, held in source order.
|
||||
struct json_entry {
|
||||
json_object_ptr key;
|
||||
json_object_ptr value;
|
||||
};
|
||||
|
||||
struct json_object {
|
||||
json_object *parent = nullptr;
|
||||
json_pull *parser = nullptr;
|
||||
|
||||
json_type type;
|
||||
int expect;
|
||||
} json_object;
|
||||
|
||||
typedef struct json_pull {
|
||||
char *error;
|
||||
int line;
|
||||
json_object(json_type t)
|
||||
: type(t) {
|
||||
}
|
||||
json_object(json_type t, json_object *p, json_pull *pl)
|
||||
: parent(p), parser(pl), type(t) {
|
||||
}
|
||||
|
||||
ssize_t (*read)(struct json_pull *, char *buf, size_t n);
|
||||
void *source;
|
||||
char *buffer;
|
||||
ssize_t buffer_tail;
|
||||
ssize_t buffer_head;
|
||||
inline std::string &string();
|
||||
inline const std::string &string() const;
|
||||
|
||||
json_object *container;
|
||||
json_object *root;
|
||||
// large_unsigned() / large_signed() return 0 when the number is not
|
||||
// held in that representation, the convention callers already expect.
|
||||
inline double number() const;
|
||||
inline unsigned long long large_unsigned() const;
|
||||
inline long long large_signed() const;
|
||||
inline void set_number(double d);
|
||||
inline void set_large_unsigned(unsigned long long u);
|
||||
inline void set_large_signed(long long s);
|
||||
|
||||
struct string *number_buffer;
|
||||
} json_pull;
|
||||
inline std::vector<json_object_ptr> &array();
|
||||
inline const std::vector<json_object_ptr> &array() const;
|
||||
|
||||
json_pull *json_begin_file(FILE *f);
|
||||
json_pull *json_begin_string(const char *s);
|
||||
inline std::vector<json_entry> &entries();
|
||||
inline const std::vector<json_entry> &entries() const;
|
||||
};
|
||||
|
||||
json_pull *json_begin(ssize_t (*read)(struct json_pull *, char *buffer, size_t n), void *source);
|
||||
void json_end(json_pull *p);
|
||||
struct json_number : json_object {
|
||||
enum repr_t { REPR_DOUBLE,
|
||||
REPR_LARGE_UNSIGNED,
|
||||
REPR_LARGE_SIGNED };
|
||||
|
||||
repr_t repr = REPR_DOUBLE;
|
||||
union value_t {
|
||||
double d;
|
||||
unsigned long long u;
|
||||
long long s;
|
||||
value_t()
|
||||
: d(0) {
|
||||
}
|
||||
} value;
|
||||
|
||||
json_number()
|
||||
: json_object(JSON_NUMBER) {
|
||||
}
|
||||
json_number(json_object *p, json_pull *pl)
|
||||
: json_object(JSON_NUMBER, p, pl) {
|
||||
}
|
||||
};
|
||||
|
||||
struct json_string : json_object {
|
||||
std::string string_value;
|
||||
|
||||
json_string()
|
||||
: json_object(JSON_STRING) {
|
||||
}
|
||||
json_string(json_object *p, json_pull *pl)
|
||||
: json_object(JSON_STRING, p, pl) {
|
||||
}
|
||||
};
|
||||
|
||||
struct json_array : json_object {
|
||||
std::vector<json_object_ptr> array_value;
|
||||
|
||||
// 2 slots: coordinate pairs dominate the parse workload.
|
||||
json_array()
|
||||
: json_object(JSON_ARRAY) {
|
||||
array_value.reserve(2);
|
||||
}
|
||||
json_array(json_object *p, json_pull *pl)
|
||||
: json_object(JSON_ARRAY, p, pl) {
|
||||
array_value.reserve(2);
|
||||
}
|
||||
};
|
||||
|
||||
struct json_hash : json_object {
|
||||
std::vector<json_entry> entries_value;
|
||||
|
||||
// 4 slots: the typical GeoJSON property hash.
|
||||
json_hash()
|
||||
: json_object(JSON_HASH) {
|
||||
entries_value.reserve(4);
|
||||
}
|
||||
json_hash(json_object *p, json_pull *pl)
|
||||
: json_object(JSON_HASH, p, pl) {
|
||||
entries_value.reserve(4);
|
||||
}
|
||||
};
|
||||
|
||||
inline std::string &json_object::string() {
|
||||
assert(type == JSON_STRING);
|
||||
return static_cast<json_string *>(this)->string_value;
|
||||
}
|
||||
inline const std::string &json_object::string() const {
|
||||
assert(type == JSON_STRING);
|
||||
return static_cast<const json_string *>(this)->string_value;
|
||||
}
|
||||
|
||||
inline double json_object::number() const {
|
||||
assert(type == JSON_NUMBER);
|
||||
auto *n = static_cast<const json_number *>(this);
|
||||
switch (n->repr) {
|
||||
case json_number::REPR_LARGE_UNSIGNED:
|
||||
return static_cast<double>(n->value.u);
|
||||
case json_number::REPR_LARGE_SIGNED:
|
||||
return static_cast<double>(n->value.s);
|
||||
case json_number::REPR_DOUBLE:
|
||||
default:
|
||||
return n->value.d;
|
||||
}
|
||||
}
|
||||
inline unsigned long long json_object::large_unsigned() const {
|
||||
assert(type == JSON_NUMBER);
|
||||
auto *n = static_cast<const json_number *>(this);
|
||||
return n->repr == json_number::REPR_LARGE_UNSIGNED ? n->value.u : 0;
|
||||
}
|
||||
inline long long json_object::large_signed() const {
|
||||
assert(type == JSON_NUMBER);
|
||||
auto *n = static_cast<const json_number *>(this);
|
||||
return n->repr == json_number::REPR_LARGE_SIGNED ? n->value.s : 0;
|
||||
}
|
||||
inline void json_object::set_number(double d) {
|
||||
assert(type == JSON_NUMBER);
|
||||
auto *n = static_cast<json_number *>(this);
|
||||
n->repr = json_number::REPR_DOUBLE;
|
||||
n->value.d = d;
|
||||
}
|
||||
inline void json_object::set_large_unsigned(unsigned long long u) {
|
||||
assert(type == JSON_NUMBER);
|
||||
auto *n = static_cast<json_number *>(this);
|
||||
n->repr = json_number::REPR_LARGE_UNSIGNED;
|
||||
n->value.u = u;
|
||||
}
|
||||
inline void json_object::set_large_signed(long long s) {
|
||||
assert(type == JSON_NUMBER);
|
||||
auto *n = static_cast<json_number *>(this);
|
||||
n->repr = json_number::REPR_LARGE_SIGNED;
|
||||
n->value.s = s;
|
||||
}
|
||||
|
||||
inline std::vector<json_object_ptr> &json_object::array() {
|
||||
assert(type == JSON_ARRAY);
|
||||
return static_cast<json_array *>(this)->array_value;
|
||||
}
|
||||
inline const std::vector<json_object_ptr> &json_object::array() const {
|
||||
assert(type == JSON_ARRAY);
|
||||
return static_cast<const json_array *>(this)->array_value;
|
||||
}
|
||||
|
||||
inline std::vector<json_entry> &json_object::entries() {
|
||||
assert(type == JSON_HASH);
|
||||
return static_cast<json_hash *>(this)->entries_value;
|
||||
}
|
||||
inline const std::vector<json_entry> &json_object::entries() const {
|
||||
assert(type == JSON_HASH);
|
||||
return static_cast<const json_hash *>(this)->entries_value;
|
||||
}
|
||||
|
||||
inline void json_object_deleter::operator()(json_object *p) const noexcept {
|
||||
if (p == nullptr) {
|
||||
return;
|
||||
}
|
||||
switch (p->type) {
|
||||
case JSON_NUMBER:
|
||||
delete static_cast<json_number *>(p);
|
||||
break;
|
||||
case JSON_STRING:
|
||||
delete static_cast<json_string *>(p);
|
||||
break;
|
||||
case JSON_ARRAY:
|
||||
delete static_cast<json_array *>(p);
|
||||
break;
|
||||
case JSON_HASH:
|
||||
delete static_cast<json_hash *>(p);
|
||||
break;
|
||||
default:
|
||||
// JSON_TRUE / JSON_FALSE / JSON_NULL: no extra fields.
|
||||
delete p;
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
struct json_pull {
|
||||
const char *error = nullptr; // points at a string literal; no allocation
|
||||
int line = 1;
|
||||
|
||||
ssize_t (*read)(struct json_pull *, char *buf, size_t n) = nullptr;
|
||||
void *source = nullptr;
|
||||
std::vector<char> buffer;
|
||||
ssize_t buffer_tail = 0;
|
||||
ssize_t buffer_head = 0;
|
||||
|
||||
// Currently-open containers, innermost last, each with the token it
|
||||
// expects next. `container` is borrowed; the owner is the surrounding
|
||||
// container, or `root` for the outermost.
|
||||
struct parse_frame {
|
||||
json_object *container;
|
||||
json_type expect;
|
||||
};
|
||||
std::vector<parse_frame> container_stack;
|
||||
|
||||
// Most recently completed top-level value, owned until the next one
|
||||
// starts parsing or the caller takes it.
|
||||
json_object_ptr root;
|
||||
|
||||
// Reused across tokens, cleared but not shrunk, so they stop
|
||||
// reallocating once grown to the largest token seen.
|
||||
std::string number_buffer;
|
||||
std::string string_buffer;
|
||||
};
|
||||
|
||||
json_pull_ptr json_begin_file(FILE *f);
|
||||
json_pull_ptr json_begin_string(const char *s);
|
||||
|
||||
json_pull_ptr json_begin(ssize_t (*read)(struct json_pull *, char *buffer, size_t n), void *source);
|
||||
|
||||
// Resets the caller's pointer. Optional: the parser frees itself when the
|
||||
// last json_pull_ptr to it goes away.
|
||||
void json_end(json_pull_ptr &p);
|
||||
|
||||
typedef void (*json_separator_callback)(json_type type, json_pull *j, void *state);
|
||||
|
||||
json_object *json_read_tree(json_pull *j);
|
||||
json_object *json_read(json_pull *j);
|
||||
json_object *json_read_separators(json_pull *j, json_separator_callback cb, void *state);
|
||||
void json_free(json_object *j);
|
||||
void json_disconnect(json_object *j);
|
||||
// The next completed node, borrowed. Valid until the next call that extends
|
||||
// or trims the parser's tree. nullptr at end of input or on error.
|
||||
json_object *json_read(json_pull_ptr &j);
|
||||
json_object *json_read_separators(json_pull_ptr &j, json_separator_callback cb, void *state);
|
||||
|
||||
// Drains the next top-level value out of the parser and hands it over. The
|
||||
// returned tree can outlive the json_pull. See Ownership model for what the
|
||||
// detach does and does not clear.
|
||||
json_object_ptr json_read_tree(json_pull_ptr &j);
|
||||
|
||||
// json_free splices `o` out of its parent (if any), or clears the
|
||||
// parser's root if `o` is the parser's current top-level value, and
|
||||
// destroys the subtree. After this call, `o` is a dangling pointer
|
||||
// that must not be used. Safe to call with nullptr.
|
||||
void json_free(json_object *o);
|
||||
|
||||
// Splices `o` out of whatever owns it and hands it over, same detach as
|
||||
// json_read_tree. See Ownership model.
|
||||
json_object_ptr json_disconnect(json_object *o);
|
||||
|
||||
// Borrowed value for `s`. nullptr if `o` is not a hash, `s` is absent, or the
|
||||
// hash is mid-parse with that value slot unfilled -- a JSON `null` is none of
|
||||
// those, and comes back as a JSON_NULL node.
|
||||
json_object *json_hash_get(const json_object_ptr &o, const char *s);
|
||||
json_object *json_hash_get(json_object *o, const char *s);
|
||||
|
||||
char *json_stringify(json_object *o);
|
||||
|
||||
#ifdef __cplusplus
|
||||
}
|
||||
#endif
|
||||
std::string json_stringify(const json_object *o);
|
||||
|
||||
#endif
|
||||
|
||||
+60
-89
@@ -13,6 +13,7 @@
|
||||
#include "geojson-loop.hpp"
|
||||
#include "milo/dtoa_milo.h"
|
||||
#include "errors.hpp"
|
||||
#include "usage.hpp"
|
||||
|
||||
int fail = EXIT_SUCCESS;
|
||||
bool wrap = false;
|
||||
@@ -146,17 +147,16 @@ void out(std::string const &s, int type, json_object *properties) {
|
||||
bool found = false;
|
||||
|
||||
json_object *o = json_hash_get(properties, extract);
|
||||
if (o != NULL) {
|
||||
if (o != nullptr) {
|
||||
found = true;
|
||||
if (o->type == JSON_STRING || o->type == JSON_NUMBER) {
|
||||
extracted = sort_quote(o->value.string.string);
|
||||
if (o->type == JSON_STRING) {
|
||||
extracted = sort_quote(o->string().c_str());
|
||||
} else {
|
||||
// Don't really know what to do about sort quoting
|
||||
// for arbitrary objects
|
||||
|
||||
const char *out = json_stringify(o);
|
||||
extracted = sort_quote(out);
|
||||
free((void *) out);
|
||||
// Numbers, booleans, null, and any other non-string
|
||||
// values are rendered via json_stringify(); calling
|
||||
// o->string() here would assert because the type-tagged
|
||||
// accessor requires JSON_STRING.
|
||||
extracted = sort_quote(json_stringify(o).c_str());
|
||||
}
|
||||
}
|
||||
|
||||
@@ -232,13 +232,13 @@ void join_csv(json_object *j) {
|
||||
}
|
||||
|
||||
json_object *properties = json_hash_get(j, "properties");
|
||||
json_object *key = NULL;
|
||||
json_object *key = nullptr;
|
||||
|
||||
if (properties != NULL) {
|
||||
if (properties != nullptr) {
|
||||
key = json_hash_get(properties, header[0].c_str());
|
||||
}
|
||||
|
||||
if (key == NULL) {
|
||||
if (key == nullptr) {
|
||||
static bool warned = false;
|
||||
if (!warned) {
|
||||
fprintf(stderr, "Warning: couldn't find CSV key \"%s\" in JSON\n", header[0].c_str());
|
||||
@@ -249,13 +249,11 @@ void join_csv(json_object *j) {
|
||||
|
||||
std::string joinkey;
|
||||
if (key->type == JSON_STRING) {
|
||||
joinkey = key->value.string.string;
|
||||
joinkey = key->string();
|
||||
} else if (key->type == JSON_NUMBER) {
|
||||
joinkey = milo::dtoa_milo(key->value.number.number);
|
||||
joinkey = milo::dtoa_milo(key->number());
|
||||
} else {
|
||||
const char *s = json_stringify(key);
|
||||
joinkey = s;
|
||||
free((void *) s);
|
||||
joinkey = json_stringify(key);
|
||||
}
|
||||
|
||||
if (joinkey < prev_joinkey) {
|
||||
@@ -305,14 +303,7 @@ void join_csv(json_object *j) {
|
||||
}
|
||||
|
||||
if (fields.size() > 0 && joinkey == fields[0]) {
|
||||
// This knows more about the structure of JSON objects than it ought to
|
||||
// The 8 is to round up at least as much as SIZE_FOR in json_pull.c
|
||||
properties->value.object.keys = (json_object **) realloc((void *) properties->value.object.keys, (properties->value.object.length + 8 + fields.size()) * sizeof(json_object *));
|
||||
properties->value.object.values = (json_object **) realloc((void *) properties->value.object.values, (properties->value.object.length + 8 + fields.size()) * sizeof(json_object *));
|
||||
if (properties->value.object.keys == NULL || properties->value.object.values == NULL) {
|
||||
perror("realloc");
|
||||
exit(EXIT_MEMORY);
|
||||
}
|
||||
properties->entries().reserve(properties->entries().size() + fields.size());
|
||||
|
||||
for (size_t i = 1; i < fields.size(); i++) {
|
||||
std::string k = header[i];
|
||||
@@ -330,46 +321,21 @@ void join_csv(json_object *j) {
|
||||
}
|
||||
|
||||
if (attr_type != JSON_NULL) {
|
||||
// This knows more about the structure of JSON objects than it ought to
|
||||
|
||||
json_object *ko = (json_object *) malloc(sizeof(json_object));
|
||||
json_object *vo = (json_object *) malloc(sizeof(json_object));
|
||||
if (ko == NULL || vo == NULL) {
|
||||
perror("malloc");
|
||||
exit(EXIT_MEMORY);
|
||||
}
|
||||
|
||||
ko->type = JSON_STRING;
|
||||
ko->parent = properties;
|
||||
ko->parser = properties->parser;
|
||||
|
||||
ko->value.string.string = strdup(k.c_str());
|
||||
if (ko->value.string.string == NULL) {
|
||||
perror("strdup");
|
||||
exit(EXIT_MEMORY);
|
||||
}
|
||||
|
||||
vo->type = attr_type;
|
||||
vo->parent = properties;
|
||||
vo->parser = properties->parser;
|
||||
json_object_ptr ko(new json_string(properties, properties->parser));
|
||||
ko->string() = k;
|
||||
|
||||
json_object_ptr vo;
|
||||
if (attr_type == JSON_STRING) {
|
||||
vo->value.string.string = strdup(v.c_str());
|
||||
if (vo->value.string.string == NULL) {
|
||||
perror("strdup");
|
||||
exit(EXIT_MEMORY);
|
||||
}
|
||||
vo = json_object_ptr(new json_string(properties, properties->parser));
|
||||
vo->string() = v;
|
||||
} else if (attr_type == JSON_NUMBER) {
|
||||
vo->value.number.number = atof(v.c_str());
|
||||
vo->value.number.large_unsigned = 0;
|
||||
vo->value.number.large_signed = 0;
|
||||
vo = json_object_ptr(new json_number(properties, properties->parser));
|
||||
vo->set_number(atof(v.c_str()));
|
||||
} else {
|
||||
abort();
|
||||
}
|
||||
|
||||
properties->value.object.keys[properties->value.object.length] = ko;
|
||||
properties->value.object.values[properties->value.object.length] = vo;
|
||||
properties->value.object.length++;
|
||||
properties->entries().push_back({std::move(ko), std::move(vo)});
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -382,13 +348,9 @@ struct json_join_action : json_feature_action {
|
||||
join_csv(feature);
|
||||
}
|
||||
|
||||
char *s = json_stringify(feature);
|
||||
out(s, 1, json_hash_get(feature, "properties"));
|
||||
free(s);
|
||||
out(json_stringify(feature), 1, json_hash_get(feature, "properties"));
|
||||
} else {
|
||||
char *s = json_stringify(geometry);
|
||||
out(s, 2, NULL);
|
||||
free(s);
|
||||
out(json_stringify(geometry), 2, nullptr);
|
||||
}
|
||||
|
||||
return 1;
|
||||
@@ -399,42 +361,52 @@ struct json_join_action : json_feature_action {
|
||||
};
|
||||
|
||||
void process(FILE *fp, const char *fname) {
|
||||
json_pull *jp = json_begin_file(fp);
|
||||
json_pull_ptr jp = json_begin_file(fp);
|
||||
|
||||
json_join_action jja;
|
||||
jja.fname = fname;
|
||||
parse_json(&jja, jp);
|
||||
json_end(jp);
|
||||
}
|
||||
|
||||
static const struct option long_options[] = {
|
||||
{"Wrapping the output", 0, 0, 0},
|
||||
{"wrap", no_argument, 0, 'w'},
|
||||
|
||||
{"Sorting and joining", 0, 0, 0},
|
||||
{"extract", required_argument, 0, 'e'},
|
||||
{"csv", required_argument, 0, 'c'},
|
||||
{"empty-csv-columns-are-null", no_argument, &pe, 1},
|
||||
|
||||
{"", 0, 0, 0},
|
||||
{"prevent", required_argument, 0, 'p'},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
// the options above, with the usage message headings removed
|
||||
static struct option real_long_options[sizeof(long_options) / sizeof(long_options[0])];
|
||||
|
||||
void usage(char **argv) {
|
||||
static const char *const forms[] = {
|
||||
"[options] [file.json ...]",
|
||||
NULL,
|
||||
};
|
||||
|
||||
print_usage(stderr, argv[0], forms, long_options, NULL);
|
||||
fprintf(stderr, "\nIf no files are named, the JSON is read from the standard input.\n");
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
int main(int argc, char **argv) {
|
||||
const char *csv = NULL;
|
||||
|
||||
struct option long_options[] = {
|
||||
{"wrap", no_argument, 0, 'w'},
|
||||
{"extract", required_argument, 0, 'e'},
|
||||
{"csv", required_argument, 0, 'c'},
|
||||
{"empty-csv-columns-are-null", no_argument, &pe, 1},
|
||||
{"prevent", required_argument, 0, 'p'},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
std::string getopt_str;
|
||||
for (size_t lo = 0; long_options[lo].name != NULL; lo++) {
|
||||
if (long_options[lo].val > ' ') {
|
||||
getopt_str.push_back(long_options[lo].val);
|
||||
|
||||
if (long_options[lo].has_arg == required_argument) {
|
||||
getopt_str.push_back(':');
|
||||
}
|
||||
}
|
||||
}
|
||||
strip_usage_headings(long_options, real_long_options);
|
||||
std::string getopt_str = getopt_string(real_long_options);
|
||||
|
||||
extern int optind;
|
||||
int i;
|
||||
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), long_options, NULL)) != -1) {
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), real_long_options, NULL)) != -1) {
|
||||
switch (i) {
|
||||
case 0:
|
||||
break;
|
||||
@@ -461,8 +433,7 @@ int main(int argc, char **argv) {
|
||||
break;
|
||||
|
||||
default:
|
||||
fprintf(stderr, "Unexpected option -%c\n", i);
|
||||
exit(EXIT_ARGS);
|
||||
usage(argv);
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
@@ -1,2 +0,0 @@
|
||||
*.zip
|
||||
tmp/*
|
||||
@@ -1,34 +0,0 @@
|
||||
# Build the tippecanoe layer (binary)
|
||||
|
||||
1. On an AWS Linux 2 instance or image:
|
||||
|
||||
sudo yum update
|
||||
sudo yum install git clang sqlite-devel zlib-devel
|
||||
|
||||
2. Create a ZIP archive with the `tippecanoe` binary at `bin/tippecanoe` and upload as a Lambda layer
|
||||
3. Copy [lambda_function.py](lambda_function.py) (python 3.9 runtime)
|
||||
4. set the environment variable `OUTPUT_BUCKET` to your output bucket; give lambda IAM role access to input/output buckets
|
||||
5. Enable ACLs on the output bucket
|
||||
|
||||
```json
|
||||
{
|
||||
"Version": "2012-10-17",
|
||||
"Statement": [
|
||||
{
|
||||
"Sid": "AllowGet",
|
||||
"Effect": "Allow",
|
||||
"Action": "s3:GetObject",
|
||||
"Resource": "arn:aws:s3:::protomaps-tippecanoe-test/*"
|
||||
},
|
||||
{
|
||||
"Sid": "AllowPut",
|
||||
"Effect": "Allow",
|
||||
"Action": [
|
||||
"s3:PutObject",
|
||||
"s3:PutObjectAcl"
|
||||
],
|
||||
"Resource": "arn:aws:s3:::protomaps-tippecanoe-test-output/*"
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
@@ -1,2 +0,0 @@
|
||||
boto3==1.20.32
|
||||
botocore==1.23.32
|
||||
@@ -1,49 +0,0 @@
|
||||
import os
|
||||
import json
|
||||
import subprocess
|
||||
import sys
|
||||
import boto3
|
||||
from botocore import UNSIGNED
|
||||
from botocore.config import Config
|
||||
|
||||
# if the input bucket is publicly readable
|
||||
#s3 = boto3.client('s3',config=Config(signature_version=UNSIGNED))
|
||||
|
||||
def lambda_handler(event, context):
|
||||
bucket_name = event['Records'][0]['s3']['bucket']['name']
|
||||
input_key = event['Records'][0]['s3']['object']['key']
|
||||
tmpdir = '/tmp'
|
||||
run_tippecanoe('tippecanoe',tmpdir,bucket_name, input_key)
|
||||
return {
|
||||
'statusCode': 200,
|
||||
'body': json.dumps('Done!')
|
||||
}
|
||||
|
||||
# input formats: "geojsonseq", "fgb", "geobuf", "geojson", "csv"
|
||||
def split_key(key):
|
||||
if key.endswith(".gz"):
|
||||
root, ext = os.path.splitext(key[0:-3])
|
||||
return root, ext + ".gz"
|
||||
else:
|
||||
return os.path.splitext(key)
|
||||
|
||||
def run_tippecanoe(executable, tmpdir, bucket_name, input_key):
|
||||
s3 = boto3.client('s3')
|
||||
root, ext = split_key(input_key)
|
||||
input_path = os.path.join(tmpdir,'input' + ext)
|
||||
output_path = os.path.join(tmpdir,'output.mbtiles')
|
||||
s3.download_file(bucket_name,input_key,input_path)
|
||||
p = subprocess.Popen([executable,'-o',output_path,input_path,'--force','-u','-U','5'],stderr=subprocess.PIPE)
|
||||
for line in p.stderr:
|
||||
try:
|
||||
j = json.loads(line)
|
||||
s3.put_object(Body=json.dumps(j),Bucket=os.environ['OUTPUT_BUCKET'],Key=root + ".progress",ACL="public-read",ContentType="application/json",ContentDisposition="inline")
|
||||
except json.decoder.JSONDecodeError:
|
||||
pass
|
||||
s3.upload_file(output_path,os.environ['OUTPUT_BUCKET'],root + ".mbtiles")
|
||||
|
||||
if __name__ == "__main__":
|
||||
tmpdir = 'tmp'
|
||||
bucket_name = sys.argv[1]
|
||||
input_key = sys.argv[2]
|
||||
run_tippecanoe('../tippecanoe', tmpdir, bucket_name, input_key)
|
||||
@@ -1,26 +0,0 @@
|
||||
from tippecanoe import split_key
|
||||
import unittest
|
||||
|
||||
class TestTippecanoe(unittest.TestCase):
|
||||
def test_basic(self):
|
||||
root, ext = split_key("file.json")
|
||||
self.assertEqual(root,"file")
|
||||
self.assertEqual(ext,".json")
|
||||
|
||||
def test_basic_gz(self):
|
||||
root, ext = split_key("file.csv.gz")
|
||||
self.assertEqual(root,"file")
|
||||
self.assertEqual(ext,".csv.gz")
|
||||
|
||||
def test_nested_key(self):
|
||||
root, ext = split_key("dir/file.fgb")
|
||||
self.assertEqual(root,"dir/file")
|
||||
self.assertEqual(ext,".fgb")
|
||||
|
||||
def test_nested_key_gz(self):
|
||||
root, ext = split_key("dir/file.geojsonseq.gz")
|
||||
self.assertEqual(root,"dir/file")
|
||||
self.assertEqual(ext,".geojsonseq.gz")
|
||||
|
||||
if __name__ == '__main__':
|
||||
unittest.main()
|
||||
@@ -52,7 +52,6 @@ extern std::map<std::string, serial_val> set_attributes;
|
||||
extern long long extend_zooms_max;
|
||||
extern int retain_points_multiplier;
|
||||
extern size_t maximum_string_attribute_length;
|
||||
extern std::string accumulate_numeric;
|
||||
extern unsigned long long preserve_multiplier_density_threshold;
|
||||
|
||||
struct order_field {
|
||||
|
||||
+586
-769
File diff suppressed because it is too large
Load Diff
@@ -1296,7 +1296,10 @@ void correct_tree(ring_manager<T>& manager) {
|
||||
}
|
||||
if (!found) {
|
||||
if ((*itr)->is_hole()) {
|
||||
throw std::runtime_error("Could not properly place hole to a parent.");
|
||||
// No remaining ring contains this hole (degenerate input, e.g. stacked
|
||||
// duplicate rings from coalesced tiny-polygon placeholders); drop it
|
||||
// rather than fail the entire tiling run.
|
||||
remove_ring_and_points(*itr, manager, false);
|
||||
} else {
|
||||
// Assign to base of tree by passing nullptr
|
||||
reassign_as_child(*itr, static_cast<ring_ptr<T>>(nullptr), manager);
|
||||
|
||||
+4
-1
@@ -701,7 +701,10 @@ metadata make_metadata(const char *fname, int minzoom, int maxzoom, double minla
|
||||
m.strategies_json = stringify_strategies(strategies);
|
||||
|
||||
if (std::isinf(droprate)) {
|
||||
droprate = LLONG_MAX;
|
||||
// JSON has no representation for infinity, so substitute a huge
|
||||
// finite value. The cast is explicit because LLONG_MAX itself is
|
||||
// not representable as a double and rounds up to 2^63.
|
||||
droprate = (double) LLONG_MAX;
|
||||
}
|
||||
if (basezoom != maxzoom || droprate != 2.5 || retain_points_multiplier != 1) {
|
||||
m.decisions_json = std::string("{") +
|
||||
|
||||
@@ -316,6 +316,10 @@ struct sorted_value {
|
||||
|
||||
return false;
|
||||
}
|
||||
|
||||
bool operator()(const std::shared_ptr<sorted_value> &a, const std::shared_ptr<sorted_value> &b) {
|
||||
return *a < *b;
|
||||
}
|
||||
};
|
||||
|
||||
std::string mvt_tile::encode() {
|
||||
@@ -334,7 +338,7 @@ std::string mvt_tile::encode() {
|
||||
layer_writer.add_string(3, layers[i].keys[j]); /* key */
|
||||
}
|
||||
|
||||
std::vector<sorted_value> sorted_values;
|
||||
std::vector<std::shared_ptr<sorted_value>> sorted_values;
|
||||
|
||||
for (size_t v = 0; v < layers[i].values.size(); v++) {
|
||||
std::string value_string;
|
||||
@@ -371,35 +375,40 @@ std::string mvt_tile::encode() {
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
sorted_value sv;
|
||||
sv.val = std::move(value_string);
|
||||
sv.orig = v;
|
||||
std::shared_ptr<sorted_value> sv = std::make_shared<sorted_value>();
|
||||
sv->val = std::move(value_string);
|
||||
sv->orig = v;
|
||||
sorted_values.push_back(std::move(sv));
|
||||
}
|
||||
|
||||
std::stable_sort(sorted_values.begin(), sorted_values.end());
|
||||
std::stable_sort(sorted_values.begin(), sorted_values.end(), sorted_value());
|
||||
std::vector<size_t> mapping;
|
||||
mapping.resize(sorted_values.size());
|
||||
|
||||
size_t value_index = 0;
|
||||
for (size_t v = 0; v < sorted_values.size(); v++) {
|
||||
mapping[sorted_values[v].orig] = value_index;
|
||||
layer_writer.add_message(4, sorted_values[v].val);
|
||||
mapping[sorted_values[v]->orig] = value_index;
|
||||
layer_writer.add_message(4, sorted_values[v]->val);
|
||||
|
||||
// crunch out duplicates that were missed by the hashing
|
||||
while (v + 1 < sorted_values.size() && sorted_values[v].val == sorted_values[v + 1].val) {
|
||||
mapping[sorted_values[v + 1].orig] = value_index;
|
||||
while (v + 1 < sorted_values.size() && sorted_values[v]->val == sorted_values[v + 1]->val) {
|
||||
sorted_values[v]->val.clear();
|
||||
mapping[sorted_values[v + 1]->orig] = value_index;
|
||||
v++;
|
||||
}
|
||||
|
||||
sorted_values[v]->val.clear();
|
||||
value_index++;
|
||||
}
|
||||
|
||||
sorted_values.clear();
|
||||
|
||||
for (size_t f = 0; f < layers[i].features.size(); f++) {
|
||||
std::string feature_string;
|
||||
protozero::pbf_writer feature_writer(feature_string);
|
||||
|
||||
feature_writer.add_enum(3, layers[i].features[f].type);
|
||||
if (layers[i].features[f].type >= 0)
|
||||
feature_writer.add_enum(3, layers[i].features[f].type);
|
||||
|
||||
std::vector<unsigned> sorted_tags = layers[i].features[f].tags;
|
||||
for (size_t v = 1; v < sorted_tags.size(); v += 2) {
|
||||
|
||||
@@ -81,7 +81,8 @@ struct mvt_value;
|
||||
double mvt_value_to_double(mvt_value const &v);
|
||||
|
||||
struct mvt_value {
|
||||
mvt_value_type type;
|
||||
long /* mvt_value_type */ type : 5;
|
||||
long count : 64 - 5;
|
||||
std::shared_ptr<std::string> s;
|
||||
|
||||
union {
|
||||
@@ -92,12 +93,21 @@ struct mvt_value {
|
||||
long long sint_value;
|
||||
bool bool_value;
|
||||
int null_value;
|
||||
// Initializing string_value initializes the union's full width, which
|
||||
// the static_assert below checks. Setting only a narrower member (a
|
||||
// double, say) would leave the remaining bytes indeterminate, and the
|
||||
// implicit copy constructor copies the union as a whole, so those
|
||||
// bytes get read even when they aren't the member in use.
|
||||
struct {
|
||||
size_t off;
|
||||
size_t len;
|
||||
} string_value;
|
||||
} string_value = {0, 0};
|
||||
} numeric_value;
|
||||
|
||||
static_assert(sizeof(numeric_value) == sizeof(numeric_value.string_value),
|
||||
"string_value must span the whole union, since its default member "
|
||||
"initializer is what initializes the union");
|
||||
|
||||
std::string get_string_value() const {
|
||||
if (type == mvt_string) {
|
||||
return std::string(*s, numeric_value.string_value.off, numeric_value.string_value.len);
|
||||
@@ -138,6 +148,10 @@ struct mvt_value {
|
||||
return mvt_value_to_double(*this);
|
||||
}
|
||||
|
||||
size_t get_count() const {
|
||||
return count;
|
||||
}
|
||||
|
||||
bool operator<(const mvt_value &o) const;
|
||||
bool operator==(const mvt_value &o) const;
|
||||
std::string toString() const;
|
||||
@@ -145,11 +159,19 @@ struct mvt_value {
|
||||
mvt_value() {
|
||||
this->type = mvt_double;
|
||||
this->numeric_value.double_value = 0;
|
||||
this->count = 0;
|
||||
}
|
||||
|
||||
mvt_value(double v) {
|
||||
this->type = mvt_double;
|
||||
this->numeric_value.double_value = v;
|
||||
this->count = 0;
|
||||
}
|
||||
|
||||
void set_double_count(double v, size_t c) {
|
||||
this->type = mvt_double;
|
||||
this->numeric_value.double_value = v;
|
||||
this->count = c;
|
||||
}
|
||||
};
|
||||
|
||||
|
||||
@@ -28,6 +28,8 @@
|
||||
#define A_VARIABLE_DEPTH_PYRAMID ((int) 't')
|
||||
#define A_VISVALINGAM ((int) 'v')
|
||||
#define A_DETECT_WRAPAROUND ((int) 'w')
|
||||
#define A_KEEP_POINT_CLUSTER_POSITION ((int) 'a')
|
||||
#define A_DROP_BY_ATTRIBUTE_AS_NEEDED ((int) 'A')
|
||||
|
||||
#define P_TILE_COMPRESSION ((int) 'C')
|
||||
#define P_DUPLICATION ((int) 'D')
|
||||
|
||||
+68
-133
@@ -11,6 +11,7 @@
|
||||
#include "text.hpp"
|
||||
#include "read_json.hpp"
|
||||
#include "projection.hpp"
|
||||
#include "usage.hpp"
|
||||
|
||||
extern char *optarg;
|
||||
extern int optind;
|
||||
@@ -19,24 +20,71 @@ int detail = 12; // tippecanoe-style: mvt extent == 1 << detail
|
||||
int buffer = 5; // tippecanoe-style: mvt buffer == extent * buffer / 256;
|
||||
bool demultiply = false;
|
||||
bool do_compress = true;
|
||||
bool deduplicate_by_id = false;
|
||||
|
||||
std::string filter;
|
||||
bool preserve_input_order = false;
|
||||
std::unordered_map<std::string, attribute_op> attribute_accum;
|
||||
std::vector<std::string> unidecode_data;
|
||||
std::vector<mvt_layer> bins;
|
||||
std::string accumulate_numeric;
|
||||
|
||||
std::set<std::string> keep;
|
||||
std::set<std::string> exclude;
|
||||
std::vector<std::string> exclude_prefix;
|
||||
std::vector<clipbbox> clipbboxes;
|
||||
|
||||
static const struct option long_options[] = {
|
||||
{"Output tile", 0, 0, 0},
|
||||
{"output", required_argument, 0, 'o'},
|
||||
{"source-tile", required_argument, 0, 't'},
|
||||
{"no-tile-compression", no_argument, 0, 'd' & 0x1F},
|
||||
|
||||
{"Tile resolution", 0, 0, 0},
|
||||
{"full-detail", required_argument, 0, 'd'},
|
||||
{"buffer", required_argument, 0, 'b'},
|
||||
|
||||
{"Filtering feature attributes", 0, 0, 0},
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{"exclude", required_argument, 0, 'x'},
|
||||
{"exclude-prefix", required_argument, 0, 'x' & 0x1F},
|
||||
|
||||
{"Modifying feature attributes", 0, 0, 0},
|
||||
{"accumulate-attribute", required_argument, 0, 'E'},
|
||||
|
||||
{"Filtering features", 0, 0, 0},
|
||||
{"feature-filter", required_argument, 0, 'j'},
|
||||
{"feature-filter-file", required_argument, 0, 'J'},
|
||||
{"filter-points-multiplier", no_argument, 0, 'm'},
|
||||
{"deduplicate-by-id", no_argument, 0, 'i' & 0x1F},
|
||||
|
||||
{"Line and polygon simplification", 0, 0, 0},
|
||||
{"line-simplification", required_argument, 0, 'S'},
|
||||
{"tiny-polygon-size", required_argument, 0, 's' & 0x1F},
|
||||
|
||||
{"Reordering features within the tile", 0, 0, 0},
|
||||
{"preserve-input-order", no_argument, 0, 'o' & 0x1F},
|
||||
|
||||
{"", 0, 0, 0},
|
||||
{"unidecode-data", required_argument, 0, 'u' & 0x1F},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
// the options above, with the usage message headings removed
|
||||
static struct option real_long_options[sizeof(long_options) / sizeof(long_options[0])];
|
||||
|
||||
void usage(char **argv) {
|
||||
fprintf(stderr, "Usage: %s -o newtile.pbf.gz tile.pbf.gz oz/ox/oy nz/nx/ny\n", argv[0]);
|
||||
fprintf(stderr, "to create tile nz/nx/ny from tile oz/ox/oy\n");
|
||||
fprintf(stderr, "Usage: %s -o newtile.pbf.gz -t nz/nx/ny tile.pbf.gz oz/ox/oy tile2.pbf.gz oz2/ox2/oy2\n", argv[0]);
|
||||
fprintf(stderr, "to create tile nz/nx/ny from tiles oz/ox/oy and oz2/ox2/oy2\n");
|
||||
static const char *const forms[] = {
|
||||
"[options] tile.pbf.gz oz/ox/oy nz/nx/ny",
|
||||
"[options] --source-tile=nz/nx/ny tile.pbf.gz oz/ox/oy ...",
|
||||
NULL,
|
||||
};
|
||||
static const struct usage_required_option required[] = {
|
||||
{"output", "newtile.pbf.gz", 0},
|
||||
{NULL, NULL, 0},
|
||||
};
|
||||
|
||||
print_usage(stderr, argv[0], forms, long_options, required);
|
||||
fprintf(stderr, "\nThe tile nz/nx/ny is created from the tile or tiles oz/ox/oy that contain it.\n");
|
||||
fprintf(stderr, "In the second form, each source tile is named by a file name and a z/x/y pair.\n");
|
||||
exit(EXIT_FAILURE);
|
||||
}
|
||||
|
||||
@@ -66,51 +114,14 @@ int main(int argc, char **argv) {
|
||||
const char *outfile = NULL;
|
||||
double simplification = 0;
|
||||
double tiny_polygon_size = 0;
|
||||
std::string assign_to_bins;
|
||||
std::string bin_by_id_list;
|
||||
|
||||
std::vector<input_tile> sources;
|
||||
|
||||
struct option long_options[] = {
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{"exclude", required_argument, 0, 'x'},
|
||||
{"exclude-prefix", required_argument, 0, 'x' & 0x1F},
|
||||
{"full-detail", required_argument, 0, 'd'},
|
||||
{"buffer", required_argument, 0, 'b'},
|
||||
{"output", required_argument, 0, 'o'},
|
||||
{"filter-points-multiplier", no_argument, 0, 'm'},
|
||||
{"feature-filter", required_argument, 0, 'j'},
|
||||
{"feature-filter-file", required_argument, 0, 'J'},
|
||||
{"preserve-input-order", no_argument, 0, 'o' & 0x1F},
|
||||
{"accumulate-attribute", required_argument, 0, 'E'},
|
||||
{"unidecode-data", required_argument, 0, 'u' & 0x1F},
|
||||
{"line-simplification", required_argument, 0, 'S'},
|
||||
{"tiny-polygon-size", required_argument, 0, 's' & 0x1F},
|
||||
{"source-tile", required_argument, 0, 't'},
|
||||
{"assign-to-bins", required_argument, 0, 'b' & 0x1F},
|
||||
{"bin-by-id-list", required_argument, 0, 'c' & 0x1F},
|
||||
{"accumulate-numeric-attributes", required_argument, 0, 'a' & 0x1F},
|
||||
{"no-tile-compression", no_argument, 0, 'd' & 0x1F},
|
||||
{"clip-bounding-box", required_argument, 0, 'k' & 0x1F},
|
||||
{"clip-polygon", required_argument, 0, 'l' & 0x1F},
|
||||
{"clip-polygon-file", required_argument, 0, 'm' & 0x1F},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
std::string getopt_str;
|
||||
for (size_t lo = 0; long_options[lo].name != NULL; lo++) {
|
||||
if (long_options[lo].val > ' ') {
|
||||
getopt_str.push_back(long_options[lo].val);
|
||||
|
||||
if (long_options[lo].has_arg == required_argument) {
|
||||
getopt_str.push_back(':');
|
||||
}
|
||||
}
|
||||
}
|
||||
strip_usage_headings(long_options, real_long_options);
|
||||
std::string getopt_str = getopt_string(real_long_options);
|
||||
|
||||
int option_index = 0;
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), long_options, &option_index)) != -1) {
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), real_long_options, &option_index)) != -1) {
|
||||
switch (i) {
|
||||
case 'y':
|
||||
keep.insert(optarg);
|
||||
@@ -172,44 +183,12 @@ int main(int argc, char **argv) {
|
||||
simplification = atof(optarg);
|
||||
break;
|
||||
|
||||
case 'b' & 0x1F:
|
||||
assign_to_bins = optarg;
|
||||
break;
|
||||
|
||||
case 'c' & 0x1F:
|
||||
bin_by_id_list = optarg;
|
||||
break;
|
||||
|
||||
case 'a' & 0x1F:
|
||||
accumulate_numeric = optarg;
|
||||
break;
|
||||
|
||||
case 'd' & 0x1F:
|
||||
do_compress = false;
|
||||
break;
|
||||
|
||||
case 'k' & 0x1F: {
|
||||
clipbbox clip;
|
||||
if (sscanf(optarg, "%lf,%lf,%lf,%lf", &clip.lon1, &clip.lat1, &clip.lon2, &clip.lat2) == 4) {
|
||||
projection->project(clip.lon1, clip.lat1, 32, &clip.minx, &clip.maxy);
|
||||
projection->project(clip.lon2, clip.lat2, 32, &clip.maxx, &clip.miny);
|
||||
clipbboxes.push_back(clip);
|
||||
} else {
|
||||
fprintf(stderr, "%s: Can't parse bounding box --clip-bounding-box=%s\n", argv[0], optarg);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
break;
|
||||
}
|
||||
|
||||
case 'l' & 0x1F: {
|
||||
clipbbox clip = parse_clip_poly(optarg);
|
||||
clipbboxes.push_back(clip);
|
||||
break;
|
||||
}
|
||||
|
||||
case 'm' & 0x1F: {
|
||||
clipbbox clip = parse_clip_poly(read_json_file(optarg));
|
||||
clipbboxes.push_back(clip);
|
||||
case 'i' & 0x1F: {
|
||||
deduplicate_by_id = true;
|
||||
break;
|
||||
}
|
||||
|
||||
@@ -222,6 +201,11 @@ int main(int argc, char **argv) {
|
||||
std::vector<input_tile> its;
|
||||
int nz, nx, ny;
|
||||
|
||||
if (outfile == NULL) {
|
||||
fprintf(stderr, "%s: must specify -o newtile.pbf.gz\n", argv[0]);
|
||||
usage(argv);
|
||||
}
|
||||
|
||||
if (outtile == NULL) { // single input
|
||||
if (argc - optind != 3) {
|
||||
fprintf(stderr, "Wrong number of arguments\n");
|
||||
@@ -276,59 +260,10 @@ int main(int argc, char **argv) {
|
||||
}
|
||||
}
|
||||
|
||||
if (assign_to_bins.size() != 0) {
|
||||
FILE *f = fopen(assign_to_bins.c_str(), "r");
|
||||
if (f == NULL) {
|
||||
perror(assign_to_bins.c_str());
|
||||
exit(EXIT_OPEN);
|
||||
}
|
||||
|
||||
int det = detail;
|
||||
if (det < 0) {
|
||||
det = 12;
|
||||
}
|
||||
bins = parse_layers(f, nz, nx, ny, 1LL << det, true);
|
||||
fclose(f);
|
||||
}
|
||||
|
||||
// clip the clip polygons, if any, to the tile bounds,
|
||||
// to reduce their complexity
|
||||
|
||||
bool clipped_to_nothing = false;
|
||||
if (clipbboxes.size() > 0) {
|
||||
long long wx1 = (nx - buffer / 256.0) * (1LL << (32 - nz));
|
||||
long long wy1 = (ny - buffer / 256.0) * (1LL << (32 - nz));
|
||||
long long wx2 = (nx + 1 + buffer / 256.0) * (1LL << (32 - nz));
|
||||
long long wy2 = (ny + 1 + buffer / 256.0) * (1LL << (32 - nz));
|
||||
|
||||
drawvec tile_bounds;
|
||||
tile_bounds.emplace_back(VT_MOVETO, wx1, wy1);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx2, wy1);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx2, wy2);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx1, wy2);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx1, wy1);
|
||||
|
||||
for (auto &c : clipbboxes) {
|
||||
c.minx = std::max(c.minx, wx1);
|
||||
c.miny = std::max(c.miny, wy1);
|
||||
c.maxx = std::min(c.maxx, wx2);
|
||||
c.maxy = std::min(c.maxy, wy2);
|
||||
|
||||
if (c.dv.size() > 0) {
|
||||
c.dv = clip_poly_poly(c.dv, tile_bounds);
|
||||
|
||||
if (c.dv.size() == 0) {
|
||||
clipped_to_nothing = true;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
std::string out;
|
||||
|
||||
if (!clipped_to_nothing) {
|
||||
json_object *json_filter = NULL;
|
||||
{
|
||||
json_object_ptr json_filter;
|
||||
if (filter.size() > 0) {
|
||||
json_filter = parse_filter(filter.c_str());
|
||||
}
|
||||
@@ -354,7 +289,7 @@ int main(int argc, char **argv) {
|
||||
its.push_back(std::move(t));
|
||||
}
|
||||
|
||||
out = overzoom(its, nz, nx, ny, detail, buffer, keep, exclude, exclude_prefix, do_compress, NULL, demultiply, json_filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, bins, bin_by_id_list, accumulate_numeric, SIZE_MAX, clipbboxes);
|
||||
out = overzoom(its, nz, nx, ny, detail, buffer, keep, exclude, exclude_prefix, do_compress, NULL, demultiply, json_filter.get(), preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, std::vector<mvt_layer>(), "", "", SIZE_MAX, std::vector<clipbbox>(), deduplicate_by_id);
|
||||
}
|
||||
|
||||
FILE *f = fopen(outfile, "wb");
|
||||
|
||||
+43
-41
@@ -27,9 +27,7 @@
|
||||
#include "errors.hpp"
|
||||
#include "thread.hpp"
|
||||
|
||||
extern "C" {
|
||||
#include "jsonpull/jsonpull.h"
|
||||
}
|
||||
|
||||
#include "plugin.hpp"
|
||||
#include "write_json.hpp"
|
||||
@@ -145,53 +143,55 @@ std::vector<mvt_layer> parse_layers(int fd, int z, unsigned x, unsigned y, std::
|
||||
}
|
||||
|
||||
// Reads from the prefilter
|
||||
serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::vector<std::map<std::string, layermap_entry>> *layermaps, size_t tiling_seg, std::vector<std::vector<std::string>> *layer_unmaps, bool postfilter, key_pool &key_pool) {
|
||||
serial_feature parse_feature(json_pull_ptr &jp, int z, unsigned x, unsigned y, std::vector<std::map<std::string, layermap_entry>> *layermaps, size_t tiling_seg, std::vector<std::vector<std::string>> *layer_unmaps, bool postfilter, key_pool &key_pool) {
|
||||
serial_feature sf;
|
||||
|
||||
while (1) {
|
||||
// json_read also returns the intermediate containers of a feature
|
||||
// still being assembled, so the `continue` paths leave `j` alone;
|
||||
// freeing one would splice it out of its parent. `j` is only freed
|
||||
// once it is a complete Feature.
|
||||
json_object *j = json_read(jp);
|
||||
if (j == NULL) {
|
||||
if (jp->error != NULL) {
|
||||
if (j == nullptr) {
|
||||
if (jp->error != nullptr) {
|
||||
fprintf(stderr, "Filter output:%d: %s: ", jp->line, jp->error);
|
||||
if (jp->root != NULL) {
|
||||
json_context(jp->root);
|
||||
if (jp->root != nullptr) {
|
||||
json_context(jp->root.get());
|
||||
} else {
|
||||
fprintf(stderr, "\n");
|
||||
}
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
json_free(jp->root);
|
||||
jp->root.reset();
|
||||
sf.t = -1;
|
||||
return sf;
|
||||
}
|
||||
|
||||
json_object *type = json_hash_get(j, "type");
|
||||
if (type == NULL || type->type != JSON_STRING) {
|
||||
if (type == nullptr || type->type != JSON_STRING) {
|
||||
continue;
|
||||
}
|
||||
if (strcmp(type->value.string.string, "Feature") != 0) {
|
||||
if (type->string() != "Feature") {
|
||||
continue;
|
||||
}
|
||||
|
||||
json_object *geometry = json_hash_get(j, "geometry");
|
||||
if (geometry == NULL) {
|
||||
if (geometry == nullptr) {
|
||||
fprintf(stderr, "Filter output:%d: filtered feature with no geometry: ", jp->line);
|
||||
json_context(j);
|
||||
json_free(j);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
json_object *properties = json_hash_get(j, "properties");
|
||||
if (properties == NULL || (properties->type != JSON_HASH && properties->type != JSON_NULL)) {
|
||||
if (properties == nullptr || (properties->type != JSON_HASH && properties->type != JSON_NULL)) {
|
||||
fprintf(stderr, "Filter output:%d: feature without properties hash: ", jp->line);
|
||||
json_context(j);
|
||||
json_free(j);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
json_object *geometry_type = json_hash_get(geometry, "type");
|
||||
if (geometry_type == NULL) {
|
||||
if (geometry_type == nullptr) {
|
||||
fprintf(stderr, "Filter output:%d: null geometry (additional not reported): ", jp->line);
|
||||
json_context(j);
|
||||
exit(EXIT_JSON);
|
||||
@@ -204,7 +204,7 @@ serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::
|
||||
}
|
||||
|
||||
json_object *coordinates = json_hash_get(geometry, "coordinates");
|
||||
if (coordinates == NULL || coordinates->type != JSON_ARRAY) {
|
||||
if (coordinates == nullptr || coordinates->type != JSON_ARRAY) {
|
||||
fprintf(stderr, "Filter output:%d: feature without coordinates array: ", jp->line);
|
||||
json_context(j);
|
||||
exit(EXIT_JSON);
|
||||
@@ -212,12 +212,12 @@ serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::
|
||||
|
||||
int t;
|
||||
for (t = 0; t < GEOM_TYPES; t++) {
|
||||
if (strcmp(geometry_type->value.string.string, geometry_names[t]) == 0) {
|
||||
if (geometry_type->string() == geometry_names[t]) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
if (t >= GEOM_TYPES) {
|
||||
fprintf(stderr, "Filter output:%d: Can't handle geometry type %s: ", jp->line, geometry_type->value.string.string);
|
||||
fprintf(stderr, "Filter output:%d: Can't handle geometry type %s: ", jp->line, geometry_type->string().c_str());
|
||||
json_context(j);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
@@ -253,29 +253,29 @@ serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::
|
||||
|
||||
std::string layername = "unknown";
|
||||
json_object *tippecanoe = json_hash_get(j, "tippecanoe");
|
||||
if (tippecanoe != NULL) {
|
||||
if (tippecanoe != nullptr) {
|
||||
json_object *layer = json_hash_get(tippecanoe, "layer");
|
||||
if (layer != NULL && layer->type == JSON_STRING) {
|
||||
layername = std::string(layer->value.string.string);
|
||||
if (layer != nullptr && layer->type == JSON_STRING) {
|
||||
layername = layer->string();
|
||||
}
|
||||
|
||||
json_object *index = json_hash_get(tippecanoe, "index");
|
||||
if (index != NULL && index->type == JSON_NUMBER) {
|
||||
sf.index = index->value.number.number;
|
||||
if (index != nullptr && index->type == JSON_NUMBER) {
|
||||
sf.index = index->number();
|
||||
}
|
||||
|
||||
json_object *sequence = json_hash_get(tippecanoe, "sequence");
|
||||
if (sequence != NULL && sequence->type == JSON_NUMBER) {
|
||||
sf.seq = sequence->value.number.number;
|
||||
if (sequence != nullptr && sequence->type == JSON_NUMBER) {
|
||||
sf.seq = sequence->number();
|
||||
}
|
||||
|
||||
json_object *extent = json_hash_get(tippecanoe, "extent");
|
||||
if (extent != NULL && extent->type == JSON_NUMBER) {
|
||||
sf.extent = extent->value.number.number;
|
||||
if (extent != nullptr && extent->type == JSON_NUMBER) {
|
||||
sf.extent = extent->number();
|
||||
}
|
||||
|
||||
json_object *dropped = json_hash_get(tippecanoe, "dropped");
|
||||
if (dropped != NULL && dropped->type == JSON_TRUE) {
|
||||
if (dropped != nullptr && dropped->type == JSON_TRUE) {
|
||||
sf.dropped = FEATURE_DROPPED; // dropped
|
||||
} else {
|
||||
sf.dropped = FEATURE_KEPT; // kept
|
||||
@@ -300,10 +300,10 @@ serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::
|
||||
}
|
||||
|
||||
json_object *id = json_hash_get(j, "id");
|
||||
if (id != NULL && id->type == JSON_NUMBER) {
|
||||
sf.id = id->value.number.number;
|
||||
if (id->value.number.large_unsigned > 0) {
|
||||
sf.id = id->value.number.large_unsigned;
|
||||
if (id != nullptr && id->type == JSON_NUMBER) {
|
||||
sf.id = id->number();
|
||||
if (id->large_unsigned() > 0) {
|
||||
sf.id = id->large_unsigned();
|
||||
}
|
||||
sf.has_id = true;
|
||||
}
|
||||
@@ -347,18 +347,20 @@ serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::
|
||||
}
|
||||
}
|
||||
|
||||
for (size_t i = 0; i < properties->value.object.length; i++) {
|
||||
serial_val v = stringify_value(properties->value.object.values[i], "Filter output", jp->line, j);
|
||||
if (properties->type == JSON_HASH) {
|
||||
for (const auto &e : properties->entries()) {
|
||||
serial_val v = stringify_value(e.value.get(), "Filter output", jp->line, j);
|
||||
|
||||
// Nulls can be excluded here because the expression evaluation filter
|
||||
// would have already run before prefiltering
|
||||
// Nulls can be excluded here because the expression evaluation filter
|
||||
// would have already run before prefiltering
|
||||
|
||||
if (v.type != mvt_null) {
|
||||
sf.full_keys.push_back(key_pool.pool(std::string(properties->value.object.keys[i]->value.string.string)));
|
||||
sf.full_values.push_back(v);
|
||||
if (v.type != mvt_null) {
|
||||
sf.full_keys.push_back(key_pool.pool(e.key->string()));
|
||||
sf.full_values.push_back(v);
|
||||
|
||||
if (!postfilter) {
|
||||
add_to_tilestats(ts->second.tilestats, std::string(properties->value.object.keys[i]->value.string.string), v);
|
||||
if (!postfilter) {
|
||||
add_to_tilestats(ts->second.tilestats, e.key->string(), v);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
+1
-1
@@ -1,4 +1,4 @@
|
||||
struct key_pool;
|
||||
std::vector<mvt_layer> filter_layers(const char *filter, std::vector<mvt_layer> &layer, unsigned z, unsigned x, unsigned y, std::vector<std::map<std::string, layermap_entry>> *layermaps, size_t tiling_seg, std::vector<std::vector<std::string>> *layer_unmaps, int extent);
|
||||
void setup_filter(const char *filter, int *write_to, int *read_from, pid_t *pid, unsigned z, unsigned x, unsigned y);
|
||||
serial_feature parse_feature(json_pull *jp, int z, unsigned x, unsigned y, std::vector<std::map<std::string, layermap_entry>> *layermaps, size_t tiling_seg, std::vector<std::vector<std::string>> *layer_unmaps, bool filters, key_pool &key_pool);
|
||||
serial_feature parse_feature(json_pull_ptr &jp, int z, unsigned x, unsigned y, std::vector<std::map<std::string, layermap_entry>> *layermaps, size_t tiling_seg, std::vector<std::vector<std::string>> *layer_unmaps, bool filters, key_pool &key_pool);
|
||||
|
||||
+25
-20
@@ -397,9 +397,9 @@ sqlite3 *pmtilesmeta2tmp(const char *fname, const char *pmtiles_map) {
|
||||
exit(EXIT_OPEN);
|
||||
}
|
||||
|
||||
json_pull *jp = json_begin_string(decompressed_json.c_str());
|
||||
json_object *o = json_read_tree(jp);
|
||||
if (o == NULL) {
|
||||
json_pull_ptr jp = json_begin_string(decompressed_json.c_str());
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
if (o == nullptr) {
|
||||
fprintf(stderr, "%s: metadata parsing error: %s\n", fname, jp->error);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
@@ -415,45 +415,50 @@ sqlite3 *pmtilesmeta2tmp(const char *fname, const char *pmtiles_map) {
|
||||
state.nospace = true;
|
||||
state.json_write_hash();
|
||||
|
||||
for (size_t i = 0; i < o->value.object.length; i++) {
|
||||
const char *key = o->value.object.keys[i]->value.string.string;
|
||||
if (strcmp(key, "vector_layers") == 0 && o->value.object.values[i]->type == JSON_ARRAY) {
|
||||
for (const auto &e : o->entries()) {
|
||||
// Check before reading, since string() asserts on the type.
|
||||
if (e.key->type != JSON_STRING) {
|
||||
fprintf(stderr, "%s: non-string key in metadata\n", fname);
|
||||
continue;
|
||||
}
|
||||
|
||||
const std::string &key = e.key->string();
|
||||
if (key == "vector_layers" && e.value->type == JSON_ARRAY) {
|
||||
has_json = true;
|
||||
state.nospace = true;
|
||||
state.json_write_string("vector_layers");
|
||||
state.nospace = true;
|
||||
state.json_write_json(json_stringify(o->value.object.values[i]));
|
||||
} else if (strcmp(key, "tilestats") == 0 && o->value.object.values[i]->type == JSON_HASH) {
|
||||
state.json_write_json(json_stringify(e.value.get()));
|
||||
} else if (key == "tilestats" && e.value->type == JSON_HASH) {
|
||||
has_json = true;
|
||||
state.nospace = true;
|
||||
state.json_write_string("tilestats");
|
||||
state.nospace = true;
|
||||
state.json_write_json(json_stringify(o->value.object.values[i]));
|
||||
} else if (strcmp(key, "strategies") == 0 && o->value.object.values[i]->type == JSON_ARRAY) {
|
||||
sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES ('strategies', %Q);", json_stringify(o->value.object.values[i]));
|
||||
state.json_write_json(json_stringify(e.value.get()));
|
||||
} else if (key == "strategies" && e.value->type == JSON_ARRAY) {
|
||||
sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES ('strategies', %Q);", json_stringify(e.value.get()).c_str());
|
||||
if (sqlite3_exec(db, sql, NULL, NULL, &err) != SQLITE_OK) {
|
||||
fprintf(stderr, "set %s in metadata: %s\n", key, err);
|
||||
fprintf(stderr, "set %s in metadata: %s\n", key.c_str(), err);
|
||||
}
|
||||
sqlite3_free(sql);
|
||||
} else if (strcmp(key, "tippecanoe_decisions") == 0 && o->value.object.values[i]->type == JSON_HASH) {
|
||||
sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES ('tippecanoe_decisions', %Q);", json_stringify(o->value.object.values[i]));
|
||||
} else if (key == "tippecanoe_decisions" && e.value->type == JSON_HASH) {
|
||||
sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES ('tippecanoe_decisions', %Q);", json_stringify(e.value.get()).c_str());
|
||||
if (sqlite3_exec(db, sql, NULL, NULL, &err) != SQLITE_OK) {
|
||||
fprintf(stderr, "set %s in metadata: %s\n", key, err);
|
||||
fprintf(stderr, "set %s in metadata: %s\n", key.c_str(), err);
|
||||
}
|
||||
sqlite3_free(sql);
|
||||
} else if (o->value.object.keys[i]->type != JSON_STRING || o->value.object.values[i]->type != JSON_STRING) {
|
||||
fprintf(stderr, "%s\n", key);
|
||||
} else if (e.value->type != JSON_STRING) {
|
||||
fprintf(stderr, "%s\n", key.c_str());
|
||||
fprintf(stderr, "%s: non-string in metadata\n", fname);
|
||||
} else {
|
||||
sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES (%Q, %Q);", key, o->value.object.values[i]->value.string.string);
|
||||
sql = sqlite3_mprintf("INSERT INTO metadata (name, value) VALUES (%Q, %Q);", key.c_str(), e.value->string().c_str());
|
||||
if (sqlite3_exec(db, sql, NULL, NULL, &err) != SQLITE_OK) {
|
||||
fprintf(stderr, "set %s in metadata: %s\n", key, err);
|
||||
fprintf(stderr, "set %s in metadata: %s\n", key.c_str(), err);
|
||||
}
|
||||
sqlite3_free(sql);
|
||||
}
|
||||
}
|
||||
|
||||
json_end(jp);
|
||||
state.nospace = true;
|
||||
state.json_end_hash();
|
||||
|
||||
|
||||
+53
-56
@@ -43,18 +43,18 @@ int mb_geometry[GEOM_TYPES] = {
|
||||
};
|
||||
|
||||
void json_context(json_object *j) {
|
||||
char *s = json_stringify(j);
|
||||
std::string s = json_stringify(j);
|
||||
|
||||
if (strlen(s) >= 500) {
|
||||
snprintf(s + 497, strlen(s) + 1 - 497, "...");
|
||||
if (s.size() >= 500) {
|
||||
s = truncate_string(s, 497);
|
||||
s.append("...");
|
||||
}
|
||||
|
||||
fprintf(stderr, "in JSON object %s\n", s);
|
||||
free(s); // stringify
|
||||
fprintf(stderr, "in JSON object %s\n", s.c_str());
|
||||
}
|
||||
|
||||
void parse_coordinates(int t, json_object *j, drawvec &out, int op, const char *fname, int line, json_object *feature) {
|
||||
if (j == NULL || j->type != JSON_ARRAY) {
|
||||
if (j == nullptr || j->type != JSON_ARRAY) {
|
||||
fprintf(stderr, "%s:%d: expected array for geometry type %d: ", fname, line, t);
|
||||
json_context(feature);
|
||||
return;
|
||||
@@ -63,7 +63,7 @@ void parse_coordinates(int t, json_object *j, drawvec &out, int op, const char *
|
||||
int within = geometry_within[t];
|
||||
if (within >= 0) {
|
||||
size_t i;
|
||||
for (i = 0; i < j->value.array.length; i++) {
|
||||
for (i = 0; i < j->array().size(); i++) {
|
||||
if (within == GEOM_POINT) {
|
||||
if (i == 0 || mb_geometry[t] == VT_POINT) {
|
||||
op = VT_MOVETO;
|
||||
@@ -72,16 +72,16 @@ void parse_coordinates(int t, json_object *j, drawvec &out, int op, const char *
|
||||
}
|
||||
}
|
||||
|
||||
parse_coordinates(within, j->value.array.array[i], out, op, fname, line, feature);
|
||||
parse_coordinates(within, j->array()[i].get(), out, op, fname, line, feature);
|
||||
}
|
||||
} else {
|
||||
if (j->value.array.length >= 2 && j->value.array.array[0]->type == JSON_NUMBER && j->value.array.array[1]->type == JSON_NUMBER) {
|
||||
if (j->array().size() >= 2 && j->array()[0]->type == JSON_NUMBER && j->array()[1]->type == JSON_NUMBER) {
|
||||
long long x, y;
|
||||
double lon = j->value.array.array[0]->value.number.number;
|
||||
double lat = j->value.array.array[1]->value.number.number;
|
||||
double lon = j->array()[0]->number();
|
||||
double lat = j->array()[1]->number();
|
||||
projection->project(lon, lat, 32, &x, &y);
|
||||
|
||||
if (j->value.array.length > 2) {
|
||||
if (j->array().size() > 2) {
|
||||
static int warned = 0;
|
||||
|
||||
if (!warned) {
|
||||
@@ -124,12 +124,12 @@ void parse_coordinates(int t, json_object *j, drawvec &out, int op, const char *
|
||||
serial_val stringify_value(json_object *value, const char *reading, int line, json_object *feature) {
|
||||
serial_val sv;
|
||||
|
||||
if (value != NULL) {
|
||||
if (value != nullptr) {
|
||||
int vt = value->type;
|
||||
|
||||
if (vt == JSON_STRING) {
|
||||
sv.type = mvt_string;
|
||||
sv.s = value->value.string.string;
|
||||
sv.s = value->string();
|
||||
|
||||
std::string err = check_utf8(sv.s);
|
||||
if (err.size() > 0) {
|
||||
@@ -140,12 +140,12 @@ serial_val stringify_value(json_object *value, const char *reading, int line, js
|
||||
} else if (vt == JSON_NUMBER) {
|
||||
sv.type = mvt_double;
|
||||
|
||||
if (value->value.number.large_unsigned != 0) {
|
||||
sv.s = std::to_string(value->value.number.large_unsigned);
|
||||
} else if (value->value.number.large_signed != 0) {
|
||||
sv.s = std::to_string(value->value.number.large_signed);
|
||||
if (value->large_unsigned() != 0) {
|
||||
sv.s = std::to_string(value->large_unsigned());
|
||||
} else if (value->large_signed() != 0) {
|
||||
sv.s = std::to_string(value->large_signed());
|
||||
} else {
|
||||
sv.s = milo::dtoa_milo(value->value.number.number);
|
||||
sv.s = milo::dtoa_milo(value->number());
|
||||
}
|
||||
} else if (vt == JSON_TRUE) {
|
||||
sv.type = mvt_bool;
|
||||
@@ -158,9 +158,7 @@ serial_val stringify_value(json_object *value, const char *reading, int line, js
|
||||
sv.s = "null";
|
||||
} else {
|
||||
sv.type = mvt_string;
|
||||
const char *v = json_stringify(value);
|
||||
sv.s = std::string(v);
|
||||
free((void *) v); // stringify
|
||||
sv.s = json_stringify(value);
|
||||
}
|
||||
}
|
||||
|
||||
@@ -178,10 +176,10 @@ static std::vector<mvt_geometry> to_feature(drawvec &geom) {
|
||||
return out;
|
||||
}
|
||||
|
||||
std::pair<int, drawvec> parse_geometry(json_object *geometry, json_pull *jp, json_object *j,
|
||||
std::pair<int, drawvec> parse_geometry(json_object *geometry, json_pull_ptr &jp, json_object *j,
|
||||
int z, int x, int y, long long extent, bool fix_longitudes, bool mvt_style) {
|
||||
json_object *geometry_type = json_hash_get(geometry, "type");
|
||||
if (geometry_type == NULL) {
|
||||
if (geometry_type == nullptr) {
|
||||
fprintf(stderr, "Filter output:%d: null geometry (additional not reported): ", jp->line);
|
||||
json_context(j);
|
||||
exit(EXIT_JSON);
|
||||
@@ -194,7 +192,7 @@ std::pair<int, drawvec> parse_geometry(json_object *geometry, json_pull *jp, jso
|
||||
}
|
||||
|
||||
json_object *coordinates = json_hash_get(geometry, "coordinates");
|
||||
if (coordinates == NULL || coordinates->type != JSON_ARRAY) {
|
||||
if (coordinates == nullptr || coordinates->type != JSON_ARRAY) {
|
||||
fprintf(stderr, "Filter output:%d: geometry without coordinates array: ", jp->line);
|
||||
json_context(j);
|
||||
exit(EXIT_JSON);
|
||||
@@ -202,12 +200,12 @@ std::pair<int, drawvec> parse_geometry(json_object *geometry, json_pull *jp, jso
|
||||
|
||||
int t;
|
||||
for (t = 0; t < GEOM_TYPES; t++) {
|
||||
if (strcmp(geometry_type->value.string.string, geometry_names[t]) == 0) {
|
||||
if (geometry_type->string() == geometry_names[t]) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
if (t >= GEOM_TYPES) {
|
||||
fprintf(stderr, "Filter output:%d: Can't handle geometry type %s: ", jp->line, geometry_type->value.string.string);
|
||||
fprintf(stderr, "Filter output:%d: Can't handle geometry type %s: ", jp->line, geometry_type->string().c_str());
|
||||
json_context(j);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
@@ -305,47 +303,47 @@ std::vector<mvt_layer> parse_layers(FILE *fp, int z, unsigned x, unsigned y, int
|
||||
std::map<std::string, mvt_layer> ret;
|
||||
std::shared_ptr<std::string> tile_stringpool = std::make_shared<std::string>();
|
||||
|
||||
json_pull *jp = json_begin_file(fp);
|
||||
json_pull_ptr jp = json_begin_file(fp);
|
||||
while (1) {
|
||||
json_object *j = json_read(jp);
|
||||
if (j == NULL) {
|
||||
if (jp->error != NULL) {
|
||||
if (j == nullptr) {
|
||||
if (jp->error != nullptr) {
|
||||
fprintf(stderr, "Filter output:%d: %s: ", jp->line, jp->error);
|
||||
if (jp->root != NULL) {
|
||||
json_context(jp->root);
|
||||
if (jp->root != nullptr) {
|
||||
json_context(jp->root.get());
|
||||
} else {
|
||||
fprintf(stderr, "\n");
|
||||
}
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
json_free(jp->root);
|
||||
jp->root.reset();
|
||||
break;
|
||||
}
|
||||
|
||||
// Only complete Features are freed; see plugin.cpp::parse_feature.
|
||||
json_object *type = json_hash_get(j, "type");
|
||||
if (type == NULL || type->type != JSON_STRING) {
|
||||
if (type == nullptr || type->type != JSON_STRING) {
|
||||
continue;
|
||||
}
|
||||
if (strcmp(type->value.string.string, "Feature") != 0) {
|
||||
if (type->string() != "Feature") {
|
||||
continue;
|
||||
}
|
||||
|
||||
json_object *properties = json_hash_get(j, "properties");
|
||||
if (properties == NULL || (properties->type != JSON_HASH && properties->type != JSON_NULL)) {
|
||||
if (properties == nullptr || (properties->type != JSON_HASH && properties->type != JSON_NULL)) {
|
||||
fprintf(stderr, "Filter output:%d: feature without properties hash: ", jp->line);
|
||||
json_context(j);
|
||||
json_free(j);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
std::string layername = "unknown";
|
||||
json_object *tippecanoe = json_hash_get(j, "tippecanoe");
|
||||
json_object *layer = NULL;
|
||||
if (tippecanoe != NULL) {
|
||||
json_object *layer = nullptr;
|
||||
if (tippecanoe != nullptr) {
|
||||
layer = json_hash_get(tippecanoe, "layer");
|
||||
if (layer != NULL && layer->type == JSON_STRING) {
|
||||
layername = std::string(layer->value.string.string);
|
||||
if (layer != nullptr && layer->type == JSON_STRING) {
|
||||
layername = layer->string();
|
||||
}
|
||||
}
|
||||
|
||||
@@ -360,10 +358,9 @@ std::vector<mvt_layer> parse_layers(FILE *fp, int z, unsigned x, unsigned y, int
|
||||
auto l = ret.find(layername);
|
||||
|
||||
json_object *geometry = json_hash_get(j, "geometry");
|
||||
if (geometry == NULL) {
|
||||
if (geometry == nullptr) {
|
||||
fprintf(stderr, "Filter output:%d: filtered feature with no geometry: ", jp->line);
|
||||
json_context(j);
|
||||
json_free(j);
|
||||
exit(EXIT_JSON);
|
||||
}
|
||||
|
||||
@@ -378,23 +375,25 @@ std::vector<mvt_layer> parse_layers(FILE *fp, int z, unsigned x, unsigned y, int
|
||||
feature.geometry = to_feature(dv);
|
||||
|
||||
json_object *id = json_hash_get(j, "id");
|
||||
if (id != NULL && id->type == JSON_NUMBER) {
|
||||
feature.id = id->value.number.number;
|
||||
if (id->value.number.large_unsigned > 0) {
|
||||
feature.id = id->value.number.large_unsigned;
|
||||
if (id != nullptr && id->type == JSON_NUMBER) {
|
||||
feature.id = id->number();
|
||||
if (id->large_unsigned() > 0) {
|
||||
feature.id = id->large_unsigned();
|
||||
}
|
||||
feature.has_id = true;
|
||||
}
|
||||
|
||||
for (size_t i = 0; i < properties->value.object.length; i++) {
|
||||
serial_val sv = stringify_value(properties->value.object.values[i], "Filter output", jp->line, j);
|
||||
if (properties->type == JSON_HASH) {
|
||||
for (const auto &e : properties->entries()) {
|
||||
serial_val sv = stringify_value(e.value.get(), "Filter output", jp->line, j);
|
||||
|
||||
// Nulls can be excluded here because this is the postfilter
|
||||
// and it is nearly time to create the vector representation
|
||||
// Nulls can be excluded here because this is the postfilter
|
||||
// and it is nearly time to create the vector representation
|
||||
|
||||
if (sv.type != mvt_null) {
|
||||
mvt_value v = stringified_to_mvt_value(sv.type, sv.s.c_str(), tile_stringpool);
|
||||
l->second.tag(feature, std::string(properties->value.object.keys[i]->value.string.string), v);
|
||||
if (sv.type != mvt_null) {
|
||||
mvt_value v = stringified_to_mvt_value(sv.type, sv.s.c_str(), tile_stringpool);
|
||||
l->second.tag(feature, e.key->string(), v);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -404,8 +403,6 @@ std::vector<mvt_layer> parse_layers(FILE *fp, int z, unsigned x, unsigned y, int
|
||||
json_free(j);
|
||||
}
|
||||
|
||||
json_end(jp);
|
||||
|
||||
std::vector<mvt_layer> final;
|
||||
for (auto a : ret) {
|
||||
final.push_back(a.second);
|
||||
|
||||
+1
-1
@@ -12,7 +12,7 @@ extern int mb_geometry[GEOM_TYPES];
|
||||
|
||||
void json_context(json_object *j);
|
||||
void parse_coordinates(int t, json_object *j, drawvec &out, int op, const char *fname, int line, json_object *feature);
|
||||
std::pair<int, drawvec> parse_geometry(json_object *geometry, json_pull *jp, json_object *j,
|
||||
std::pair<int, drawvec> parse_geometry(json_object *geometry, json_pull_ptr &jp, json_object *j,
|
||||
int z, int x, int y, long long extent, bool fix_longitudes, bool mvt_style);
|
||||
std::vector<mvt_layer> parse_layers(FILE *fp, int z, unsigned x, unsigned y, int extent, bool fix_longitudes);
|
||||
|
||||
|
||||
+10
-2
@@ -665,10 +665,18 @@ int serialize_feature(struct serialization_state *sst, serial_feature &sf, std::
|
||||
// VT_POINT extent will be calculated in write_tile from the distance between adjacent features.
|
||||
}
|
||||
|
||||
if (extent <= LLONG_MAX) {
|
||||
// Clamp before converting, since converting a double that is out of range
|
||||
// for a long long is undefined. The bounds are asymmetric: LLONG_MAX is not
|
||||
// representable as a double and rounds up to 2^63, so the upper bound has to
|
||||
// be exclusive, while LLONG_MIN is exactly -2^63 and so can be included.
|
||||
// Areas are signed, so holes that outweigh their rings can make this
|
||||
// negative.
|
||||
if (extent >= (double) LLONG_MIN && extent < (double) LLONG_MAX) {
|
||||
sf.extent = (long long) extent;
|
||||
} else if (extent < 0) {
|
||||
sf.extent = LLONG_MIN;
|
||||
} else {
|
||||
sf.extent = LLONG_MAX;
|
||||
sf.extent = LLONG_MAX; // also the NaN case
|
||||
}
|
||||
|
||||
if (sst->want_dist && sf.t == VT_POLYGON) {
|
||||
|
||||
+14
-2
@@ -70,6 +70,20 @@ struct serial_val {
|
||||
type = mvt_string;
|
||||
s = val;
|
||||
}
|
||||
|
||||
size_t get_count() const {
|
||||
size_t found = s.find('\0');
|
||||
if (found == std::string::npos) {
|
||||
return 0;
|
||||
} else {
|
||||
return atoll(s.c_str() + found + 1);
|
||||
}
|
||||
}
|
||||
|
||||
void set_double_count(double v, size_t c) {
|
||||
type = mvt_double;
|
||||
s = milo::dtoa_milo(v) + '\0' + std::to_string(c);
|
||||
}
|
||||
};
|
||||
|
||||
struct key_pool {
|
||||
@@ -151,8 +165,6 @@ struct serial_feature {
|
||||
long long clustered; // does this feature need the clustered/point_count attributes?
|
||||
const char *stringpool; // string pool for keys/values lookup
|
||||
std::shared_ptr<std::string> tile_stringpool; // string pool for mvt_value construction
|
||||
std::set<std::string> need_tilestats;
|
||||
std::unordered_map<std::string, accum_state> attribute_accum_state;
|
||||
|
||||
int z; // tile being produced
|
||||
int tx;
|
||||
|
||||
+47
-47
@@ -83,13 +83,13 @@ bool edges_same(std::pair<std::vector<edge>::iterator, std::vector<edge>::iterat
|
||||
return true;
|
||||
}
|
||||
|
||||
bool find_common_edges(std::vector<serial_feature> &features, int z, int line_detail, double simplification, int maxzoom, double merge_fraction) {
|
||||
bool find_common_edges(std::vector<std::shared_ptr<serial_feature>> &features, int z, int line_detail, double simplification, int maxzoom, double merge_fraction) {
|
||||
size_t merge_count = ceil((1 - merge_fraction) * features.size());
|
||||
|
||||
for (size_t i = 0; i < features.size(); i++) {
|
||||
if (features[i].t == VT_POLYGON) {
|
||||
if (features[i]->t == VT_POLYGON) {
|
||||
{
|
||||
drawvec &g = features[i].geometry;
|
||||
drawvec &g = features[i]->geometry;
|
||||
drawvec out;
|
||||
|
||||
for (size_t k = 0; k < g.size(); k++) {
|
||||
@@ -100,7 +100,7 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
}
|
||||
}
|
||||
|
||||
features[i].geometry = out;
|
||||
features[i]->geometry = out;
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -112,21 +112,21 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
std::vector<edge> edges;
|
||||
size_t ring = 0;
|
||||
for (size_t i = 0; i < features.size(); i++) {
|
||||
if (features[i].t == VT_POLYGON) {
|
||||
if (features[i]->t == VT_POLYGON) {
|
||||
{
|
||||
for (size_t k = 0; k + 1 < features[i].geometry.size(); k++) {
|
||||
if (features[i].geometry[k].op == VT_MOVETO) {
|
||||
for (size_t k = 0; k + 1 < features[i]->geometry.size(); k++) {
|
||||
if (features[i]->geometry[k].op == VT_MOVETO) {
|
||||
ring++;
|
||||
}
|
||||
|
||||
if (features[i].geometry[k + 1].op == VT_LINETO) {
|
||||
if (features[i]->geometry[k + 1].op == VT_LINETO) {
|
||||
drawvec dv;
|
||||
if (features[i].geometry[k] < features[i].geometry[k + 1]) {
|
||||
dv.push_back(features[i].geometry[k]);
|
||||
dv.push_back(features[i].geometry[k + 1]);
|
||||
if (features[i]->geometry[k] < features[i]->geometry[k + 1]) {
|
||||
dv.push_back(features[i]->geometry[k]);
|
||||
dv.push_back(features[i]->geometry[k + 1]);
|
||||
} else {
|
||||
dv.push_back(features[i].geometry[k + 1]);
|
||||
dv.push_back(features[i].geometry[k]);
|
||||
dv.push_back(features[i]->geometry[k + 1]);
|
||||
dv.push_back(features[i]->geometry[k]);
|
||||
}
|
||||
|
||||
edges.push_back(edge(dv[0].x, dv[0].y, dv[1].x, dv[1].y, ring));
|
||||
@@ -143,9 +143,9 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
// is not the same as the set of rings using the edge on the other side.
|
||||
|
||||
for (size_t i = 0; i < features.size(); i++) {
|
||||
if (features[i].t == VT_POLYGON) {
|
||||
if (features[i]->t == VT_POLYGON) {
|
||||
{
|
||||
drawvec &g = features[i].geometry;
|
||||
drawvec &g = features[i]->geometry;
|
||||
|
||||
for (size_t k = 0; k < g.size(); k++) {
|
||||
g[k].necessary = 0;
|
||||
@@ -223,9 +223,9 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
// Roll rings that include a necessary point around so they start at one
|
||||
|
||||
for (size_t i = 0; i < features.size(); i++) {
|
||||
if (features[i].t == VT_POLYGON) {
|
||||
if (features[i]->t == VT_POLYGON) {
|
||||
{
|
||||
drawvec &g = features[i].geometry;
|
||||
drawvec &g = features[i]->geometry;
|
||||
|
||||
for (size_t k = 0; k < g.size(); k++) {
|
||||
if (necessaries.count(g[k]) != 0) {
|
||||
@@ -315,21 +315,21 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
// Add new arc
|
||||
size_t added = arcs.size() + 1;
|
||||
arcs.insert(std::pair<drawvec, size_t>(arc, added));
|
||||
features[i].arc_polygon.push_back(added);
|
||||
features[i]->arc_polygon.push_back(added);
|
||||
merge_candidates.insert(std::pair<ssize_t, size_t>(added, i));
|
||||
} else {
|
||||
features[i].arc_polygon.push_back(-(ssize_t) f2->second);
|
||||
features[i]->arc_polygon.push_back(-(ssize_t) f2->second);
|
||||
merge_candidates.insert(std::pair<ssize_t, size_t>(-(ssize_t) f2->second, i));
|
||||
}
|
||||
} else {
|
||||
features[i].arc_polygon.push_back(f->second);
|
||||
features[i]->arc_polygon.push_back(f->second);
|
||||
merge_candidates.insert(std::pair<ssize_t, size_t>(f->second, i));
|
||||
}
|
||||
|
||||
m = n - 1;
|
||||
}
|
||||
|
||||
features[i].arc_polygon.push_back(0);
|
||||
features[i]->arc_polygon.push_back(0);
|
||||
|
||||
k = l - 1;
|
||||
}
|
||||
@@ -385,10 +385,10 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
if (r1i->second != r2i->second) {
|
||||
merge_order mo;
|
||||
mo.edge = i;
|
||||
if (features[r1i->second].index > features[r2i->second].index) {
|
||||
mo.gap = features[r1i->second].index - features[r2i->second].index;
|
||||
if (features[r1i->second]->index > features[r2i->second]->index) {
|
||||
mo.gap = features[r1i->second]->index - features[r2i->second]->index;
|
||||
} else {
|
||||
mo.gap = features[r2i->second].index - features[r1i->second].index;
|
||||
mo.gap = features[r2i->second]->index - features[r1i->second]->index;
|
||||
}
|
||||
mo.p1 = r1i->second;
|
||||
mo.p2 = r2i->second;
|
||||
@@ -406,19 +406,19 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
}
|
||||
|
||||
size_t i = order[o].p1;
|
||||
while (features[i].renamed >= 0) {
|
||||
i = features[i].renamed;
|
||||
while (features[i]->renamed >= 0) {
|
||||
i = features[i]->renamed;
|
||||
}
|
||||
size_t i2 = order[o].p2;
|
||||
while (features[i2].renamed >= 0) {
|
||||
i2 = features[i2].renamed;
|
||||
while (features[i2]->renamed >= 0) {
|
||||
i2 = features[i2]->renamed;
|
||||
}
|
||||
|
||||
for (size_t j = 0; j < features[i].arc_polygon.size() && merged < merge_count; j++) {
|
||||
if (features[i].arc_polygon[j] == order[o].edge) {
|
||||
for (size_t j = 0; j < features[i]->arc_polygon.size() && merged < merge_count; j++) {
|
||||
if (features[i]->arc_polygon[j] == order[o].edge) {
|
||||
{
|
||||
// XXX snap links
|
||||
if (features[order[o].p2].arc_polygon.size() > 0) {
|
||||
if (features[order[o].p2]->arc_polygon.size() > 0) {
|
||||
// This has to merge the ring that contains the anti-arc to this arc
|
||||
// into the current ring, and then add whatever other rings were in
|
||||
// that feature on to the end.
|
||||
@@ -427,11 +427,11 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
// the rings in order, but Wagyu should sort that out later
|
||||
|
||||
std::vector<ssize_t> additions;
|
||||
std::vector<ssize_t> &here = features[i].arc_polygon;
|
||||
std::vector<ssize_t> &other = features[i2].arc_polygon;
|
||||
std::vector<ssize_t> &here = features[i]->arc_polygon;
|
||||
std::vector<ssize_t> &other = features[i2]->arc_polygon;
|
||||
|
||||
#if 0
|
||||
printf("seeking %zd\n", features[i].arc_polygon[j]);
|
||||
printf("seeking %zd\n", features[i]->arc_polygon[j]);
|
||||
printf("before: ");
|
||||
for (size_t k = 0; k < here.size(); k++) {
|
||||
printf("%zd ", here[k]);
|
||||
@@ -464,7 +464,7 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
|
||||
size_t m;
|
||||
for (m = k; m <= l; m++) {
|
||||
if (other[m] == -features[i].arc_polygon[j]) {
|
||||
if (other[m] == -features[i]->arc_polygon[j]) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
@@ -494,12 +494,12 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
k = l;
|
||||
}
|
||||
|
||||
features[i2].arc_polygon.clear();
|
||||
features[i2].renamed = i;
|
||||
features[i2]->arc_polygon.clear();
|
||||
features[i2]->renamed = i;
|
||||
merged++;
|
||||
|
||||
for (size_t k = 0; k < additions.size(); k++) {
|
||||
features[i].arc_polygon.push_back(additions[k]);
|
||||
features[i]->arc_polygon.push_back(additions[k]);
|
||||
}
|
||||
|
||||
#if 0
|
||||
@@ -528,37 +528,37 @@ bool find_common_edges(std::vector<serial_feature> &features, int z, int line_de
|
||||
// Turn the arc representations of the polygons back into standard polygon geometries
|
||||
|
||||
for (size_t i = 0; i < features.size(); i++) {
|
||||
if (features[i].t == VT_POLYGON) {
|
||||
features[i].geometry.clear();
|
||||
if (features[i]->t == VT_POLYGON) {
|
||||
features[i]->geometry.clear();
|
||||
bool at_start = true;
|
||||
draw first(-1, 0, 0);
|
||||
|
||||
for (size_t j = 0; j < features[i].arc_polygon.size(); j++) {
|
||||
ssize_t p = features[i].arc_polygon[j];
|
||||
for (size_t j = 0; j < features[i]->arc_polygon.size(); j++) {
|
||||
ssize_t p = features[i]->arc_polygon[j];
|
||||
|
||||
if (p == 0) {
|
||||
if (first.op >= 0) {
|
||||
features[i].geometry.push_back(first);
|
||||
features[i]->geometry.push_back(first);
|
||||
first = draw(-1, 0, 0);
|
||||
}
|
||||
at_start = true;
|
||||
} else if (p > 0) {
|
||||
for (size_t k = 0; k + 1 < simplified_arcs[p].size(); k++) {
|
||||
if (at_start) {
|
||||
features[i].geometry.push_back(draw(VT_MOVETO, simplified_arcs[p][k].x, simplified_arcs[p][k].y));
|
||||
features[i]->geometry.push_back(draw(VT_MOVETO, simplified_arcs[p][k].x, simplified_arcs[p][k].y));
|
||||
first = draw(VT_LINETO, simplified_arcs[p][k].x, simplified_arcs[p][k].y);
|
||||
} else {
|
||||
features[i].geometry.push_back(draw(VT_LINETO, simplified_arcs[p][k].x, simplified_arcs[p][k].y));
|
||||
features[i]->geometry.push_back(draw(VT_LINETO, simplified_arcs[p][k].x, simplified_arcs[p][k].y));
|
||||
}
|
||||
at_start = 0;
|
||||
}
|
||||
} else { /* p < 0 */
|
||||
for (ssize_t k = simplified_arcs[-p].size() - 1; k > 0; k--) {
|
||||
if (at_start) {
|
||||
features[i].geometry.push_back(draw(VT_MOVETO, simplified_arcs[-p][k].x, simplified_arcs[-p][k].y));
|
||||
features[i]->geometry.push_back(draw(VT_MOVETO, simplified_arcs[-p][k].x, simplified_arcs[-p][k].y));
|
||||
first = draw(VT_LINETO, simplified_arcs[-p][k].x, simplified_arcs[-p][k].y);
|
||||
} else {
|
||||
features[i].geometry.push_back(draw(VT_LINETO, simplified_arcs[-p][k].x, simplified_arcs[-p][k].y));
|
||||
features[i]->geometry.push_back(draw(VT_LINETO, simplified_arcs[-p][k].x, simplified_arcs[-p][k].y));
|
||||
}
|
||||
at_start = 0;
|
||||
}
|
||||
|
||||
+1
-1
@@ -1 +1 @@
|
||||
bool find_common_edges(std::vector<serial_feature> &features, int z, int line_detail, double simplification, int maxzoom, double merge_fraction);
|
||||
bool find_common_edges(std::vector<std::shared_ptr<serial_feature>> &features, int z, int line_detail, double simplification, int maxzoom, double merge_fraction);
|
||||
|
||||
@@ -6,7 +6,7 @@
|
||||
|
||||
#define MAX_MEMORY (1024 * 1024 * 1024) // 1 GB
|
||||
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem) {
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem, const char *tmpdir) {
|
||||
std::string pivot;
|
||||
FILE *fp1, *fp2;
|
||||
|
||||
@@ -67,8 +67,8 @@ void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *,
|
||||
size_t pivot_off = width * (buf.size() / width / 2);
|
||||
pivot = std::string(buf, pivot_off, width);
|
||||
|
||||
std::string t1 = "/tmp/sort1.XXXXXX";
|
||||
std::string t2 = "/tmp/sort2.XXXXXX";
|
||||
std::string t1 = std::string(tmpdir) + "/sort1.XXXXXX";
|
||||
std::string t2 = std::string(tmpdir) + "/sort2.XXXXXX";
|
||||
|
||||
int fd1 = mkstemp((char *) t1.c_str());
|
||||
unlink(t1.c_str());
|
||||
@@ -117,11 +117,11 @@ void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *,
|
||||
|
||||
std::vector<FILE *> v1;
|
||||
v1.emplace_back(fp1);
|
||||
fqsort(v1, width, cmp, out, mem);
|
||||
fqsort(v1, width, cmp, out, mem, tmpdir);
|
||||
fclose(fp1);
|
||||
|
||||
std::vector<FILE *> v2;
|
||||
v2.emplace_back(fp2);
|
||||
fqsort(v2, width, cmp, out, mem);
|
||||
fqsort(v2, width, cmp, out, mem, tmpdir);
|
||||
fclose(fp2);
|
||||
}
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
#ifndef SORT_HPP
|
||||
#define SORT_HPP
|
||||
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem);
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem, const char *tmpdir);
|
||||
|
||||
#endif
|
||||
|
||||
+2
-2
File diff suppressed because one or more lines are too long
Binary file not shown.
@@ -0,0 +1,5 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "numeric-properties", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "byte_min": -128, "ubyte_max": 255, "bool_value": true, "short_min": -32768, "ushort_max": 65535, "int_min": -2147483648, "uint_max": 4294967295, "long_min": -9223372036854775808, "ulong_max": 18446744073709551615, "float_value": 1.25, "double_value": 12345.678901234, "guid_value": "123e4567-e89b-12d3-a456-426614174000" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
] }
|
||||
] }
|
||||
@@ -0,0 +1,2 @@
|
||||
{"type":"Feature","properties":{"explanation":"in z0, the value at 0,0 will get averaged onto this point at -10,-10 even though the attribute isn't present in this feature"},"geometry":{"type":"Point","coordinates":[-10,-10]}}
|
||||
{"type":"Feature","properties":{"value":5},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
@@ -0,0 +1,47 @@
|
||||
{ "type": "FeatureCollection", "properties": {
|
||||
"antimeridian_adjusted_bounds": "-10.000000,-10.000000,0.000000,0.000000",
|
||||
"bounds": "-10.000000,-10.000000,0.000000,0.000000",
|
||||
"center": "-10.000000,-10.000000,1",
|
||||
"description": "tests/mean-accumulation/out/-z1_--accumulate-attribute_value%3amean.json.check.mbtiles",
|
||||
"format": "pbf",
|
||||
"generator_options": "./tippecanoe -q -a@ -f -o tests/mean-accumulation/out/-z1_--accumulate-attribute_value%3amean.json.check.mbtiles -z1 --accumulate-attribute value:mean tests/mean-accumulation/in.json",
|
||||
"json": "{\"vector_layers\":[{\"id\":\"in\",\"description\":\"\",\"minzoom\":0,\"maxzoom\":1,\"fields\":{\"explanation\":\"String\",\"value\":\"Number\"}}],\"tilestats\":{\"layerCount\":1,\"layers\":[{\"layer\":\"in\",\"count\":2,\"geometry\":\"Point\",\"attributeCount\":2,\"attributes\":[{\"attribute\":\"explanation\",\"count\":1,\"type\":\"string\",\"values\":[\"in z0, the value at 0,0 will get averaged onto this point at -10,-10 even though the attribute isn't present in this feature\"]},{\"attribute\":\"value\",\"count\":1,\"type\":\"number\",\"values\":[5],\"min\":5,\"max\":5}]}]}}",
|
||||
"maxzoom": "1",
|
||||
"minzoom": "0",
|
||||
"name": "tests/mean-accumulation/out/-z1_--accumulate-attribute_value%3amean.json.check.mbtiles",
|
||||
"strategies": "[{\"dropped_by_rate\":1},{}]",
|
||||
"type": "overlay",
|
||||
"version": "2"
|
||||
}, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "explanation": "in z0, the value at 0,0 will get averaged onto this point at -10,-10 even though the attribute isn't present in this feature", "value": 5 }, "geometry": { "type": "Point", "coordinates": [ -10.019531, -10.055403 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 0, "y": 1 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "explanation": "in z0, the value at 0,0 will get averaged onto this point at -10,-10 even though the attribute isn't present in this feature" }, "geometry": { "type": "Point", "coordinates": [ -10.019531, -10.012130 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "value": 5 }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "value": 5 }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 1 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "value": 5 }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "value": 5 }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
] }
|
||||
] }
|
||||
] }
|
||||
@@ -0,0 +1,2 @@
|
||||
{"type":"Feature","id":1,"tippecanoe":{"minzoom":10},"properties":{"depth":10},"geometry":{"type":"Point","coordinates":[0.05,0.05]}}
|
||||
{"type":"Feature","id":2,"tippecanoe":{"minzoom":11},"properties":{"depth":11},"geometry":{"type":"Point","coordinates":[0.06,0.06]}}
|
||||
+28
@@ -0,0 +1,28 @@
|
||||
{ "type": "FeatureCollection", "properties": {
|
||||
"antimeridian_adjusted_bounds": "0.050000,0.050000,0.060000,0.060000",
|
||||
"bounds": "0.050000,0.050000,0.060000,0.060000",
|
||||
"center": "0.060000,0.060000,11",
|
||||
"description": "tests/minzoom-variable-depth/out/-Z10_-z11_--generate-variable-depth-tile-pyramid.json.check.mbtiles",
|
||||
"format": "pbf",
|
||||
"generator_options": "./tippecanoe -q -a@ -f -o tests/minzoom-variable-depth/out/-Z10_-z11_--generate-variable-depth-tile-pyramid.json.check.mbtiles -Z10 -z11 --generate-variable-depth-tile-pyramid tests/minzoom-variable-depth/in.json",
|
||||
"json": "{\"vector_layers\":[{\"id\":\"in\",\"description\":\"\",\"minzoom\":10,\"maxzoom\":11,\"fields\":{\"depth\":\"Number\"}}],\"tilestats\":{\"layerCount\":1,\"layers\":[{\"layer\":\"in\",\"count\":2,\"geometry\":\"Point\",\"attributeCount\":1,\"attributes\":[{\"attribute\":\"depth\",\"count\":2,\"type\":\"number\",\"values\":[10,11],\"min\":10,\"max\":11}]}]}}",
|
||||
"maxzoom": "11",
|
||||
"minzoom": "10",
|
||||
"name": "tests/minzoom-variable-depth/out/-Z10_-z11_--generate-variable-depth-tile-pyramid.json.check.mbtiles",
|
||||
"type": "overlay",
|
||||
"version": "2"
|
||||
}, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 10, "x": 512, "y": 511 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "id": 1, "properties": { "depth": 10 }, "geometry": { "type": "Point", "coordinates": [ 0.050039, 0.049953 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 11, "x": 1024, "y": 1023 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "id": 1, "properties": { "depth": 10 }, "geometry": { "type": "Point", "coordinates": [ 0.049996, 0.049996 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 2, "properties": { "depth": 11 }, "geometry": { "type": "Point", "coordinates": [ 0.059996, 0.059996 ] } }
|
||||
] }
|
||||
] }
|
||||
] }
|
||||
@@ -9,7 +9,6 @@
|
||||
"maxzoom": "2",
|
||||
"minzoom": "0",
|
||||
"name": "tests/ne_110m_admin_0_countries/out/-z2_--convert-polygons-to-label-points.json.check.mbtiles",
|
||||
"strategies": "[{},{},{\"tiny_polygons\":1}]",
|
||||
"type": "overlay",
|
||||
"version": "2"
|
||||
}, "features": [
|
||||
|
||||
+521
-105
File diff suppressed because one or more lines are too long
+516
-96
File diff suppressed because one or more lines are too long
+1817
File diff suppressed because it is too large
Load Diff
-1426
File diff suppressed because one or more lines are too long
+767
@@ -0,0 +1,767 @@
|
||||
{ "type": "FeatureCollection", "properties": {
|
||||
"antimeridian_adjusted_bounds": "-175.220564,-41.299973,179.216647,64.150023",
|
||||
"bounds": "-175.220564,-41.299973,179.216647,64.150023",
|
||||
"center": "90.000000,42.525564,1",
|
||||
"description": "tests/ne_110m_populated_places_nulls/out/-z1_--accumulate-attribute_POP2000%3amean_-yNAME_-yPOP2000.json.check.mbtiles",
|
||||
"format": "pbf",
|
||||
"generator_options": "./tippecanoe -q -a@ -f -o tests/ne_110m_populated_places_nulls/out/-z1_--accumulate-attribute_POP2000%3amean_-yNAME_-yPOP2000.json.check.mbtiles -z1 --accumulate-attribute POP2000:mean -yNAME -yPOP2000 tests/ne_110m_populated_places_nulls/in.json",
|
||||
"json": "{\"vector_layers\":[{\"id\":\"in\",\"description\":\"\",\"minzoom\":0,\"maxzoom\":1,\"fields\":{\"NAME\":\"String\",\"POP2000\":\"Number\"}}],\"tilestats\":{\"layerCount\":1,\"layers\":[{\"layer\":\"in\",\"count\":243,\"geometry\":\"Point\",\"attributeCount\":2,\"attributes\":[{\"attribute\":\"NAME\",\"count\":243,\"type\":\"string\",\"values\":[\"Abidjan\",\"Abu Dhabi\",\"Abuja\",\"Accra\",\"Addis Ababa\",\"Algiers\",\"Amman\",\"Amsterdam\",\"Andorra\",\"Ankara\",\"Antananarivo\",\"Apia\",\"Ashgabat\",\"Asmara\",\"Astana\",\"Asuncion\",\"Athens\",\"Atlanta\",\"Auckland\",\"Baghdad\",\"Baguio City\",\"Baku\",\"Bamako\",\"Bandar Seri Begawan\",\"Bangalore\",\"Bangkok\",\"Bangui\",\"Banjul\",\"Basseterre\",\"Beijing\",\"Beirut\",\"Belgrade\",\"Belmopan\",\"Berlin\",\"Bern\",\"Bir Lehlou\",\"Bishkek\",\"Bissau\",\"Bloemfontein\",\"Bogota\",\"Brasilia\",\"Bratislava\",\"Brazzaville\",\"Bridgetown\",\"Brussels\",\"Bucharest\",\"Budapest\",\"Buenos Aires\",\"Bujumbura\",\"Cairo\",\"Canberra\",\"Cape Town\",\"Caracas\",\"Casablanca\",\"Castries\",\"Chengdu\",\"Chicago\",\"Chisinau\",\"Colombo\",\"Conakry\",\"Cotonou\",\"Dakar\",\"Damascus\",\"Dar es Salaam\",\"Denver\",\"Dhaka\",\"Dili\",\"Djibouti\",\"Dodoma\",\"Doha\",\"Dubai\",\"Dublin\",\"Dushanbe\",\"Freetown\",\"Funafuti\",\"Gaborone\",\"Geneva\",\"Georgetown\",\"Guatemala\",\"Hanoi\",\"Harare\",\"Hargeysa\",\"Havana\",\"Helsinki\",\"Hong Kong\",\"Honiara\",\"Houston\",\"Islamabad\",\"Istanbul\",\"Jakarta\",\"Jerusalem\",\"Johannesburg\",\"Juba\",\"Kabul\",\"Kampala\",\"Kathmandu\",\"Khartoum\",\"Kiev\",\"Kigali\",\"Kingston\"]},{\"attribute\":\"POP2000\",\"count\":185,\"type\":\"number\",\"values\":[10016,1005,1007,10151,1019,1023,10285,1032,1050.6666666666668,10534,1063,1072,1073,1077,1079,10803,1084,10897.5,1096,1097,1100,1110,1111,11165,1127,1128,1160,1172,11814,11847,1192,1201,1206,1219,1233,1278.5,13058,1306,13243,1357,1361,1365,1369,1379,1390,1452.5,14572,1487,1499,1507,1561,1606,16086,1653,1666,1674,1700,17099,1730,1733,1765.5,17846,1787,18022,1806,1854,1877,1894.3333333333333,1912,1949,1959,1963,1998,2029,2044,2116,2135,2158,2187,2233,2278,2456,2478,2489.3333333333337,2493,2533,2591,2597.5,2606,2640,2672,2715,2732,2746,2752,2754,2864,3032,3043,3076],\"min\":497,\"max\":34450}]}]}}",
|
||||
"maxzoom": "1",
|
||||
"minzoom": "0",
|
||||
"name": "tests/ne_110m_populated_places_nulls/out/-z1_--accumulate-attribute_POP2000%3amean_-yNAME_-yPOP2000.json.check.mbtiles",
|
||||
"strategies": "[{\"dropped_by_rate\":145},{}]",
|
||||
"type": "overlay",
|
||||
"version": "2"
|
||||
}, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "NAME": "Vancouver", "POP2000": 2597.5 }, "geometry": { "type": "Point", "coordinates": [ -123.134766, 49.267805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Los Angeles", "POP2000": 6906 }, "geometry": { "type": "Point", "coordinates": [ -118.125000, 33.943360 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Monterrey", "POP2000": 8379 }, "geometry": { "type": "Point", "coordinates": [ -100.283203, 25.641526 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Guatemala", "POP2000": 4620.5 }, "geometry": { "type": "Point", "coordinates": [ -90.527344, 14.604847 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Toronto", "POP2000": 3076 }, "geometry": { "type": "Point", "coordinates": [ -79.365234, 43.707594 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Havana", "POP2000": 3566.5 }, "geometry": { "type": "Point", "coordinates": [ -82.353516, 23.079732 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Washington, D.C.", "POP2000": 10897.5 }, "geometry": { "type": "Point", "coordinates": [ -76.992188, 38.891033 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Belmopan", "POP2000": 793 }, "geometry": { "type": "Point", "coordinates": [ -88.769531, 17.224758 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "San Salvador", "POP2000": 1050.6666666666668 }, "geometry": { "type": "Point", "coordinates": [ -89.208984, 13.667338 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Panama City", "POP2000": 1072 }, "geometry": { "type": "Point", "coordinates": [ -79.541016, 8.928487 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Port-au-Prince", "POP2000": 3287.6666666666667 }, "geometry": { "type": "Point", "coordinates": [ -72.333984, 18.562947 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Basseterre" }, "geometry": { "type": "Point", "coordinates": [ -62.666016, 17.308688 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Roseau" }, "geometry": { "type": "Point", "coordinates": [ -61.347656, 15.284185 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Saint George's" }, "geometry": { "type": "Point", "coordinates": [ -61.699219, 12.039321 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Caracas", "POP2000": 2864 }, "geometry": { "type": "Point", "coordinates": [ -66.884766, 10.487812 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Paramaribo" }, "geometry": { "type": "Point", "coordinates": [ -55.107422, 5.790897 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dublin", "POP2000": 4607 }, "geometry": { "type": "Point", "coordinates": [ -6.240234, 53.330873 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Laayoune", "POP2000": 2672 }, "geometry": { "type": "Point", "coordinates": [ -13.183594, 27.137368 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Casablanca", "POP2000": 3198.3333333333337 }, "geometry": { "type": "Point", "coordinates": [ -7.558594, 33.578015 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bir Lehlou", "POP2000": 2029 }, "geometry": { "type": "Point", "coordinates": [ -9.667969, 26.115986 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nouakchott" }, "geometry": { "type": "Point", "coordinates": [ -15.996094, 18.062312 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Conakry", "POP2000": 953.5 }, "geometry": { "type": "Point", "coordinates": [ -13.623047, 9.535749 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bamako", "POP2000": 924.6666666666666 }, "geometry": { "type": "Point", "coordinates": [ -7.998047, 12.640338 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Yamoussoukro", "POP2000": 3032 }, "geometry": { "type": "Point", "coordinates": [ -5.273438, 6.839170 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Accra", "POP2000": 1674 }, "geometry": { "type": "Point", "coordinates": [ -0.175781, 5.528511 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Quito", "POP2000": 4236.5 }, "geometry": { "type": "Point", "coordinates": [ -78.486328, -0.263671 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "La Paz", "POP2000": 2489.3333333333337 }, "geometry": { "type": "Point", "coordinates": [ -68.115234, -16.551962 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sucre", "POP2000": 2746 }, "geometry": { "type": "Point", "coordinates": [ -65.214844, -19.062118 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Asuncion", "POP2000": 10151 }, "geometry": { "type": "Point", "coordinates": [ -57.656250, -25.324167 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Montevideo", "POP2000": 6182 }, "geometry": { "type": "Point", "coordinates": [ -56.162109, -34.885931 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Oslo", "POP2000": 990 }, "geometry": { "type": "Point", "coordinates": [ 10.810547, 59.888937 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Amsterdam", "POP2000": 1369 }, "geometry": { "type": "Point", "coordinates": [ 4.921875, 52.321911 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Luxembourg", "POP2000": 9692 }, "geometry": { "type": "Point", "coordinates": [ 6.152344, 49.610710 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Geneva" }, "geometry": { "type": "Point", "coordinates": [ 6.152344, 46.195042 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vaduz", "POP2000": 1077 }, "geometry": { "type": "Point", "coordinates": [ 9.580078, 47.100045 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Berlin", "POP2000": 2278 }, "geometry": { "type": "Point", "coordinates": [ 13.447266, 52.536273 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Warsaw", "POP2000": 1912 }, "geometry": { "type": "Point", "coordinates": [ 21.005859, 52.214339 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Zagreb" }, "geometry": { "type": "Point", "coordinates": [ 15.996094, 45.767523 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vatican City", "POP2000": 3385 }, "geometry": { "type": "Point", "coordinates": [ 12.480469, 41.902277 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Budapest", "POP2000": 1787 }, "geometry": { "type": "Point", "coordinates": [ 19.072266, 47.457809 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Podgorica", "POP2000": 1127 }, "geometry": { "type": "Point", "coordinates": [ 19.248047, 42.423457 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Pristina" }, "geometry": { "type": "Point", "coordinates": [ 21.181641, 42.682435 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Helsinki", "POP2000": 1019 }, "geometry": { "type": "Point", "coordinates": [ 24.960938, 60.152442 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vilnius", "POP2000": 1700 }, "geometry": { "type": "Point", "coordinates": [ 25.312500, 54.673831 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kiev", "POP2000": 1894.3333333333333 }, "geometry": { "type": "Point", "coordinates": [ 30.498047, 50.401515 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Chisinau", "POP2000": 8744 }, "geometry": { "type": "Point", "coordinates": [ 28.916016, 46.980252 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Moscow", "POP2000": 4623.333333333333 }, "geometry": { "type": "Point", "coordinates": [ 37.617188, 55.727110 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tunis", "POP2000": 1877 }, "geometry": { "type": "Point", "coordinates": [ 10.195312, 36.809285 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Valletta", "POP2000": 851.5 }, "geometry": { "type": "Point", "coordinates": [ 14.501953, 35.889050 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Cotonou", "POP2000": 642 }, "geometry": { "type": "Point", "coordinates": [ 2.548828, 6.402648 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lagos", "POP2000": 4032.5 }, "geometry": { "type": "Point", "coordinates": [ 3.427734, 6.402648 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Malabo" }, "geometry": { "type": "Point", "coordinates": [ 8.789062, 3.688855 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ndjamena", "POP2000": 951.5 }, "geometry": { "type": "Point", "coordinates": [ 15.029297, 12.125264 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Athens", "POP2000": 3179 }, "geometry": { "type": "Point", "coordinates": [ 23.730469, 37.996163 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nicosia", "POP2000": 6643 }, "geometry": { "type": "Point", "coordinates": [ 33.398438, 35.173808 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Beirut", "POP2000": 1765.5 }, "geometry": { "type": "Point", "coordinates": [ 35.507812, 33.870416 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Yerevan", "POP2000": 3155.5 }, "geometry": { "type": "Point", "coordinates": [ 44.560547, 40.178873 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Amman", "POP2000": 2478 }, "geometry": { "type": "Point", "coordinates": [ 35.947266, 31.952162 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Juba", "POP2000": 1097 }, "geometry": { "type": "Point", "coordinates": [ 31.640625, 4.828260 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sanaa", "POP2000": 1365 }, "geometry": { "type": "Point", "coordinates": [ 44.208984, 15.368950 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Addis Ababa", "POP2000": 2493 }, "geometry": { "type": "Point", "coordinates": [ 38.759766, 9.015302 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tashkent", "POP2000": 1452.5 }, "geometry": { "type": "Point", "coordinates": [ 69.345703, 41.310824 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Urumqi", "POP2000": 3554.6666666666667 }, "geometry": { "type": "Point", "coordinates": [ 87.626953, 43.771094 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kuwait", "POP2000": 2533 }, "geometry": { "type": "Point", "coordinates": [ 47.988281, 29.382175 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Manama", "POP2000": 938 }, "geometry": { "type": "Point", "coordinates": [ 50.625000, 26.194877 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Abu Dhabi" }, "geometry": { "type": "Point", "coordinates": [ 54.404297, 24.447150 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Muscat", "POP2000": 1201 }, "geometry": { "type": "Point", "coordinates": [ 58.623047, 23.563987 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kabul", "POP2000": 1278.5 }, "geometry": { "type": "Point", "coordinates": [ 69.169922, 34.524661 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "New Delhi", "POP2000": 644 }, "geometry": { "type": "Point", "coordinates": [ 77.255859, 28.613459 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kolkata", "POP2000": 14572 }, "geometry": { "type": "Point", "coordinates": [ 88.330078, 22.512557 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bangalore", "POP2000": 5567 }, "geometry": { "type": "Point", "coordinates": [ 77.607422, 12.983148 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sri Jawewardenepura Kotte", "POP2000": 763 }, "geometry": { "type": "Point", "coordinates": [ 79.980469, 6.839170 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dhaka", "POP2000": 7102 }, "geometry": { "type": "Point", "coordinates": [ 90.439453, 23.725012 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Rangoon", "POP2000": 4942.5 }, "geometry": { "type": "Point", "coordinates": [ 96.152344, 16.804541 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vientiane", "POP2000": 2456 }, "geometry": { "type": "Point", "coordinates": [ 102.656250, 17.978733 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kuala Lumpur", "POP2000": 1306 }, "geometry": { "type": "Point", "coordinates": [ 101.689453, 3.162456 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Singapore", "POP2000": 6820.333333333333 }, "geometry": { "type": "Point", "coordinates": [ 103.886719, 1.230374 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Shanghai", "POP2000": 7941.5 }, "geometry": { "type": "Point", "coordinates": [ 121.464844, 31.203405 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Pyongyang", "POP2000": 6517 }, "geometry": { "type": "Point", "coordinates": [ 125.771484, 39.027719 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Manila", "POP2000": 9958 }, "geometry": { "type": "Point", "coordinates": [ 121.025391, 14.604847 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Melekeok", "POP2000": 6485.5 }, "geometry": { "type": "Point", "coordinates": [ 134.648438, 7.449624 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tokyo", "POP2000": 34450 }, "geometry": { "type": "Point", "coordinates": [ 139.746094, 35.675147 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Majuro", "POP2000": 986 }, "geometry": { "type": "Point", "coordinates": [ 171.386719, 7.100893 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kinshasa", "POP2000": 4038 }, "geometry": { "type": "Point", "coordinates": [ 15.292969, -4.390229 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Windhoek", "POP2000": 1606 }, "geometry": { "type": "Point", "coordinates": [ 17.138672, -22.593726 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bujumbura", "POP2000": 1073 }, "geometry": { "type": "Point", "coordinates": [ 29.355469, -3.425692 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Harare", "POP2000": 1806 }, "geometry": { "type": "Point", "coordinates": [ 31.025391, -17.811456 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dar es Salaam", "POP2000": 2116 }, "geometry": { "type": "Point", "coordinates": [ 39.287109, -6.839170 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Moroni", "POP2000": 2732 }, "geometry": { "type": "Point", "coordinates": [ 43.242188, -11.695273 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bloemfontein" }, "geometry": { "type": "Point", "coordinates": [ 26.279297, -29.152161 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Pretoria", "POP2000": 1084 }, "geometry": { "type": "Point", "coordinates": [ 28.212891, -25.720735 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Maputo", "POP2000": 1096 }, "geometry": { "type": "Point", "coordinates": [ 32.607422, -25.958045 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Antananarivo", "POP2000": 4875.5 }, "geometry": { "type": "Point", "coordinates": [ 47.548828, -18.895893 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dili" }, "geometry": { "type": "Point", "coordinates": [ 125.595703, -8.581021 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Melbourne", "POP2000": 3755.5 }, "geometry": { "type": "Point", "coordinates": [ 145.019531, -37.857507 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Honiara" }, "geometry": { "type": "Point", "coordinates": [ 159.960938, -9.449062 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Funafuti", "POP2000": 1063 }, "geometry": { "type": "MultiPoint", "coordinates": [ [ 179.208984, -8.581021 ], [ -180.791016, -8.581021 ] ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Wellington" }, "geometry": { "type": "MultiPoint", "coordinates": [ [ 174.814453, -41.310824 ], [ -185.273438, -41.310824 ] ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 0, "y": 1 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "NAME": "Nukualofa" }, "geometry": { "type": "Point", "coordinates": [ -175.209961, -21.125498 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Apia" }, "geometry": { "type": "Point", "coordinates": [ -171.738281, -13.838080 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Quito", "POP2000": 1357 }, "geometry": { "type": "Point", "coordinates": [ -78.486328, -0.219726 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lima", "POP2000": 7116 }, "geometry": { "type": "Point", "coordinates": [ -77.036133, -12.039321 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "La Paz", "POP2000": 1390 }, "geometry": { "type": "Point", "coordinates": [ -68.159180, -16.509833 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Valparaiso", "POP2000": 803 }, "geometry": { "type": "Point", "coordinates": [ -71.630859, -33.063924 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Santiago", "POP2000": 5275 }, "geometry": { "type": "Point", "coordinates": [ -70.664062, -33.431441 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sucre" }, "geometry": { "type": "Point", "coordinates": [ -65.258789, -19.020577 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Brasilia", "POP2000": 2746 }, "geometry": { "type": "Point", "coordinates": [ -47.900391, -15.792254 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Asuncion", "POP2000": 1507 }, "geometry": { "type": "Point", "coordinates": [ -57.656250, -25.284438 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Buenos Aires", "POP2000": 11847 }, "geometry": { "type": "Point", "coordinates": [ -58.403320, -34.597042 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sao Paulo", "POP2000": 17099 }, "geometry": { "type": "Point", "coordinates": [ -46.625977, -23.563987 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Montevideo", "POP2000": 1561 }, "geometry": { "type": "Point", "coordinates": [ -56.162109, -34.849875 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Rio de Janeiro", "POP2000": 10803 }, "geometry": { "type": "Point", "coordinates": [ -43.242188, -22.917923 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Funafuti" }, "geometry": { "type": "Point", "coordinates": [ -180.791016, -8.537565 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Suva" }, "geometry": { "type": "Point", "coordinates": [ -181.538086, -18.145852 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "NAME": "Vancouver", "POP2000": 1959 }, "geometry": { "type": "Point", "coordinates": [ -123.134766, 49.267805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "San Francisco", "POP2000": 3236 }, "geometry": { "type": "Point", "coordinates": [ -122.431641, 37.753344 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Los Angeles", "POP2000": 11814 }, "geometry": { "type": "Point", "coordinates": [ -118.168945, 33.979809 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Denver", "POP2000": 1998 }, "geometry": { "type": "Point", "coordinates": [ -104.985352, 39.740986 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Monterrey", "POP2000": 3266 }, "geometry": { "type": "Point", "coordinates": [ -100.327148, 25.681137 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Houston", "POP2000": 3849 }, "geometry": { "type": "Point", "coordinates": [ -95.361328, 29.840644 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Mexico City", "POP2000": 18022 }, "geometry": { "type": "Point", "coordinates": [ -99.140625, 19.435514 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Guatemala", "POP2000": 908 }, "geometry": { "type": "Point", "coordinates": [ -90.527344, 14.604847 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Chicago", "POP2000": 8333 }, "geometry": { "type": "Point", "coordinates": [ -87.758789, 41.836828 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Toronto", "POP2000": 4607 }, "geometry": { "type": "Point", "coordinates": [ -79.409180, 43.707594 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ottawa", "POP2000": 1079 }, "geometry": { "type": "Point", "coordinates": [ -75.717773, 45.429299 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Atlanta", "POP2000": 3542 }, "geometry": { "type": "Point", "coordinates": [ -84.418945, 33.833920 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Havana", "POP2000": 2187 }, "geometry": { "type": "Point", "coordinates": [ -82.353516, 23.120154 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Miami", "POP2000": 4946 }, "geometry": { "type": "Point", "coordinates": [ -80.244141, 25.799891 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Washington, D.C.", "POP2000": 3949 }, "geometry": { "type": "Point", "coordinates": [ -76.992188, 38.891033 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "New York", "POP2000": 17846 }, "geometry": { "type": "Point", "coordinates": [ -74.003906, 40.747257 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nassau" }, "geometry": { "type": "Point", "coordinates": [ -77.343750, 25.085599 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Belmopan" }, "geometry": { "type": "Point", "coordinates": [ -88.769531, 17.266728 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tegucigalpa", "POP2000": 793 }, "geometry": { "type": "Point", "coordinates": [ -87.231445, 14.093957 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "San Salvador", "POP2000": 1233 }, "geometry": { "type": "Point", "coordinates": [ -89.208984, 13.710035 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Managua", "POP2000": 887 }, "geometry": { "type": "Point", "coordinates": [ -86.264648, 12.168226 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "San Jose", "POP2000": 1032 }, "geometry": { "type": "Point", "coordinates": [ -84.067383, 9.925566 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Panama City", "POP2000": 1072 }, "geometry": { "type": "Point", "coordinates": [ -79.541016, 8.971897 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kingston" }, "geometry": { "type": "Point", "coordinates": [ -76.772461, 17.978733 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Port-au-Prince", "POP2000": 1653 }, "geometry": { "type": "Point", "coordinates": [ -72.333984, 18.562947 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Santo Domingo", "POP2000": 1854 }, "geometry": { "type": "Point", "coordinates": [ -69.916992, 18.479609 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bogota", "POP2000": 6356 }, "geometry": { "type": "Point", "coordinates": [ -74.091797, 4.609278 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Basseterre" }, "geometry": { "type": "Point", "coordinates": [ -62.709961, 17.308688 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Saint John's" }, "geometry": { "type": "Point", "coordinates": [ -61.831055, 17.098792 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Roseau" }, "geometry": { "type": "Point", "coordinates": [ -61.391602, 15.284185 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Castries" }, "geometry": { "type": "Point", "coordinates": [ -60.996094, 14.008696 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kingstown" }, "geometry": { "type": "Point", "coordinates": [ -61.215820, 13.154376 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Saint George's" }, "geometry": { "type": "Point", "coordinates": [ -61.743164, 12.039321 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bridgetown" }, "geometry": { "type": "Point", "coordinates": [ -59.633789, 13.111580 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Caracas", "POP2000": 2864 }, "geometry": { "type": "Point", "coordinates": [ -66.928711, 10.487812 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Port-of-Spain" }, "geometry": { "type": "Point", "coordinates": [ -61.523438, 10.660608 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Georgetown" }, "geometry": { "type": "Point", "coordinates": [ -58.183594, 6.795535 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Paramaribo" }, "geometry": { "type": "Point", "coordinates": [ -55.151367, 5.834616 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Reykjavík" }, "geometry": { "type": "Point", "coordinates": [ -21.928711, 64.148952 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dublin", "POP2000": 989 }, "geometry": { "type": "Point", "coordinates": [ -6.240234, 53.330873 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "London", "POP2000": 8225 }, "geometry": { "type": "Point", "coordinates": [ -0.131836, 51.508742 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Praia" }, "geometry": { "type": "Point", "coordinates": [ -23.510742, 14.902322 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Laayoune" }, "geometry": { "type": "Point", "coordinates": [ -13.183594, 27.137368 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lisbon", "POP2000": 2672 }, "geometry": { "type": "Point", "coordinates": [ -9.140625, 38.719805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Casablanca", "POP2000": 3043 }, "geometry": { "type": "Point", "coordinates": [ -7.602539, 33.614619 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Rabat", "POP2000": 1507 }, "geometry": { "type": "Point", "coordinates": [ -6.855469, 34.016242 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Madrid", "POP2000": 5045 }, "geometry": { "type": "Point", "coordinates": [ -3.691406, 40.413496 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bir Lehlou" }, "geometry": { "type": "Point", "coordinates": [ -9.667969, 26.115986 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dakar", "POP2000": 2029 }, "geometry": { "type": "Point", "coordinates": [ -17.490234, 14.732386 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nouakchott" }, "geometry": { "type": "Point", "coordinates": [ -15.996094, 18.104087 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Banjul" }, "geometry": { "type": "Point", "coordinates": [ -16.611328, 13.453737 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bissau" }, "geometry": { "type": "Point", "coordinates": [ -15.600586, 11.867351 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Conakry", "POP2000": 1219 }, "geometry": { "type": "Point", "coordinates": [ -13.666992, 9.535749 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Freetown", "POP2000": 688 }, "geometry": { "type": "Point", "coordinates": [ -13.227539, 8.450639 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bamako", "POP2000": 1110 }, "geometry": { "type": "Point", "coordinates": [ -7.998047, 12.640338 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ouagadougou", "POP2000": 828 }, "geometry": { "type": "Point", "coordinates": [ -1.538086, 12.382928 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Monrovia", "POP2000": 836 }, "geometry": { "type": "Point", "coordinates": [ -10.810547, 6.315299 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Yamoussoukro" }, "geometry": { "type": "Point", "coordinates": [ -5.273438, 6.839170 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Abidjan", "POP2000": 3032 }, "geometry": { "type": "Point", "coordinates": [ -4.042969, 5.309766 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Accra", "POP2000": 1674 }, "geometry": { "type": "Point", "coordinates": [ -0.219727, 5.572250 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Quito", "POP2000": 1357 }, "geometry": { "type": "Point", "coordinates": [ -78.486328, -0.219726 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Paris", "POP2000": 9692 }, "geometry": { "type": "Point", "coordinates": [ 2.329102, 48.864715 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Andorra" }, "geometry": { "type": "Point", "coordinates": [ 1.538086, 42.488302 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Algiers", "POP2000": 2754 }, "geometry": { "type": "Point", "coordinates": [ 3.032227, 36.774092 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Niamey", "POP2000": 680 }, "geometry": { "type": "Point", "coordinates": [ 2.109375, 13.539201 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lome", "POP2000": 1023 }, "geometry": { "type": "Point", "coordinates": [ 1.230469, 6.140555 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Cotonou", "POP2000": 642 }, "geometry": { "type": "Point", "coordinates": [ 2.504883, 6.402648 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Porto-Novo" }, "geometry": { "type": "Point", "coordinates": [ 2.636719, 6.489983 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lagos", "POP2000": 7233 }, "geometry": { "type": "Point", "coordinates": [ 3.383789, 6.446318 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 1 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "NAME": "Sao Tome" }, "geometry": { "type": "Point", "coordinates": [ 6.723633, 0.351560 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Libreville" }, "geometry": { "type": "Point", "coordinates": [ 9.448242, 0.395505 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kampala", "POP2000": 1097 }, "geometry": { "type": "Point", "coordinates": [ 32.563477, 0.307616 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Mogadishu", "POP2000": 1201 }, "geometry": { "type": "Point", "coordinates": [ 45.351562, 2.064982 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kuala Lumpur", "POP2000": 1306 }, "geometry": { "type": "Point", "coordinates": [ 101.689453, 3.162456 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Putrajaya" }, "geometry": { "type": "Point", "coordinates": [ 101.689453, 2.899153 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Singapore", "POP2000": 4017 }, "geometry": { "type": "Point", "coordinates": [ 103.842773, 1.274309 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tarawa" }, "geometry": { "type": "Point", "coordinates": [ 173.012695, 1.318243 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Brazzaville", "POP2000": 986 }, "geometry": { "type": "Point", "coordinates": [ 15.292969, -4.258768 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kinshasa", "POP2000": 5485 }, "geometry": { "type": "Point", "coordinates": [ 15.292969, -4.346411 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Luanda", "POP2000": 2591 }, "geometry": { "type": "Point", "coordinates": [ 13.227539, -8.841651 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Windhoek" }, "geometry": { "type": "Point", "coordinates": [ 17.094727, -22.553147 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Cape Town", "POP2000": 2715 }, "geometry": { "type": "Point", "coordinates": [ 18.413086, -33.906896 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kigali", "POP2000": 497 }, "geometry": { "type": "Point", "coordinates": [ 30.058594, -1.933227 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bujumbura" }, "geometry": { "type": "Point", "coordinates": [ 29.355469, -3.381824 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lusaka", "POP2000": 1073 }, "geometry": { "type": "Point", "coordinates": [ 28.300781, -15.411319 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Harare", "POP2000": 1379 }, "geometry": { "type": "Point", "coordinates": [ 31.025391, -17.811456 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nairobi", "POP2000": 2233 }, "geometry": { "type": "Point", "coordinates": [ 36.826172, -1.274309 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dodoma" }, "geometry": { "type": "Point", "coordinates": [ 35.771484, -6.184246 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dar es Salaam", "POP2000": 2116 }, "geometry": { "type": "Point", "coordinates": [ 39.287109, -6.795535 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lilongwe" }, "geometry": { "type": "Point", "coordinates": [ 33.793945, -13.966054 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Moroni" }, "geometry": { "type": "Point", "coordinates": [ 43.242188, -11.695273 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Gaborone" }, "geometry": { "type": "Point", "coordinates": [ 25.927734, -24.647017 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Johannesburg", "POP2000": 2732 }, "geometry": { "type": "Point", "coordinates": [ 28.037109, -26.155438 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bloemfontein" }, "geometry": { "type": "Point", "coordinates": [ 26.235352, -29.113775 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Maseru" }, "geometry": { "type": "Point", "coordinates": [ 27.465820, -29.305561 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Pretoria", "POP2000": 1084 }, "geometry": { "type": "Point", "coordinates": [ 28.212891, -25.720735 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Mbabane" }, "geometry": { "type": "Point", "coordinates": [ 31.113281, -26.313113 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lobamba" }, "geometry": { "type": "Point", "coordinates": [ 31.201172, -26.470573 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Maputo", "POP2000": 1096 }, "geometry": { "type": "Point", "coordinates": [ 32.607422, -25.958045 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Victoria" }, "geometry": { "type": "Point", "coordinates": [ 55.458984, -4.609278 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Antananarivo", "POP2000": 1361 }, "geometry": { "type": "Point", "coordinates": [ 47.504883, -18.895893 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Port Louis" }, "geometry": { "type": "Point", "coordinates": [ 57.480469, -20.179724 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Jakarta", "POP2000": 8390 }, "geometry": { "type": "Point", "coordinates": [ 106.831055, -6.184246 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dili" }, "geometry": { "type": "Point", "coordinates": [ 125.595703, -8.581021 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Port Moresby" }, "geometry": { "type": "Point", "coordinates": [ 147.172852, -9.449062 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Melbourne", "POP2000": 3433 }, "geometry": { "type": "Point", "coordinates": [ 144.975586, -37.822802 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sydney", "POP2000": 4078 }, "geometry": { "type": "Point", "coordinates": [ 151.171875, -33.906896 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Canberra" }, "geometry": { "type": "Point", "coordinates": [ 149.150391, -35.281501 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Honiara" }, "geometry": { "type": "Point", "coordinates": [ 159.960938, -9.449062 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Port Vila" }, "geometry": { "type": "Point", "coordinates": [ 168.310547, -17.727759 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Funafuti" }, "geometry": { "type": "Point", "coordinates": [ 179.208984, -8.537565 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Suva" }, "geometry": { "type": "Point", "coordinates": [ 178.461914, -18.145852 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Auckland", "POP2000": 1063 }, "geometry": { "type": "Point", "coordinates": [ 174.770508, -36.844461 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Wellington" }, "geometry": { "type": "Point", "coordinates": [ 174.770508, -41.310824 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "NAME": "London", "POP2000": 8225 }, "geometry": { "type": "Point", "coordinates": [ -0.131836, 51.508742 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ouagadougou", "POP2000": 828 }, "geometry": { "type": "Point", "coordinates": [ -1.538086, 12.382928 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Accra", "POP2000": 1674 }, "geometry": { "type": "Point", "coordinates": [ -0.219727, 5.572250 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Oslo", "POP2000": 774 }, "geometry": { "type": "Point", "coordinates": [ 10.766602, 59.910976 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Stockholm", "POP2000": 1206 }, "geometry": { "type": "Point", "coordinates": [ 18.105469, 59.355596 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "The Hague" }, "geometry": { "type": "Point", "coordinates": [ 4.262695, 52.079506 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Amsterdam", "POP2000": 1005 }, "geometry": { "type": "Point", "coordinates": [ 4.921875, 52.348763 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Brussels", "POP2000": 1733 }, "geometry": { "type": "Point", "coordinates": [ 4.350586, 50.847573 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Luxembourg" }, "geometry": { "type": "Point", "coordinates": [ 6.108398, 49.610710 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Paris", "POP2000": 9692 }, "geometry": { "type": "Point", "coordinates": [ 2.329102, 48.864715 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Andorra" }, "geometry": { "type": "Point", "coordinates": [ 1.538086, 42.488302 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Geneva" }, "geometry": { "type": "Point", "coordinates": [ 6.152344, 46.195042 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bern" }, "geometry": { "type": "Point", "coordinates": [ 7.470703, 46.920255 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vaduz" }, "geometry": { "type": "Point", "coordinates": [ 9.536133, 47.129951 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Monaco" }, "geometry": { "type": "Point", "coordinates": [ 7.426758, 43.739352 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "København", "POP2000": 1077 }, "geometry": { "type": "Point", "coordinates": [ 12.568359, 55.677584 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Berlin", "POP2000": 3384 }, "geometry": { "type": "Point", "coordinates": [ 13.403320, 52.536273 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Prague", "POP2000": 1172 }, "geometry": { "type": "Point", "coordinates": [ 14.458008, 50.092393 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Warsaw", "POP2000": 1666 }, "geometry": { "type": "Point", "coordinates": [ 21.005859, 52.241256 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vienna", "POP2000": 2158 }, "geometry": { "type": "Point", "coordinates": [ 16.347656, 48.195387 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ljubljana" }, "geometry": { "type": "Point", "coordinates": [ 14.501953, 46.042736 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Zagreb" }, "geometry": { "type": "Point", "coordinates": [ 15.996094, 45.798170 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "San Marino" }, "geometry": { "type": "Point", "coordinates": [ 12.436523, 43.929550 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vatican City" }, "geometry": { "type": "Point", "coordinates": [ 12.436523, 41.902277 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Rome", "POP2000": 3385 }, "geometry": { "type": "Point", "coordinates": [ 12.480469, 41.902277 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bratislava" }, "geometry": { "type": "Point", "coordinates": [ 17.138672, 48.136767 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Budapest", "POP2000": 1787 }, "geometry": { "type": "Point", "coordinates": [ 19.072266, 47.487513 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sarajevo" }, "geometry": { "type": "Point", "coordinates": [ 18.369141, 43.834527 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Podgorica" }, "geometry": { "type": "Point", "coordinates": [ 19.248047, 42.455888 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Belgrade", "POP2000": 1127 }, "geometry": { "type": "Point", "coordinates": [ 20.478516, 44.809122 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tirana" }, "geometry": { "type": "Point", "coordinates": [ 19.819336, 41.343825 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Pristina" }, "geometry": { "type": "Point", "coordinates": [ 21.181641, 42.682435 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Skopje" }, "geometry": { "type": "Point", "coordinates": [ 21.445312, 42.000325 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Helsinki", "POP2000": 1019 }, "geometry": { "type": "Point", "coordinates": [ 24.916992, 60.174306 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tallinn" }, "geometry": { "type": "Point", "coordinates": [ 24.741211, 59.422728 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Riga" }, "geometry": { "type": "Point", "coordinates": [ 24.082031, 56.944974 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vilnius" }, "geometry": { "type": "Point", "coordinates": [ 25.312500, 54.673831 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Minsk", "POP2000": 1700 }, "geometry": { "type": "Point", "coordinates": [ 27.553711, 53.904338 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kiev", "POP2000": 2606 }, "geometry": { "type": "Point", "coordinates": [ 30.498047, 50.429518 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sofia", "POP2000": 1128 }, "geometry": { "type": "Point", "coordinates": [ 23.334961, 42.682435 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bucharest", "POP2000": 1949 }, "geometry": { "type": "Point", "coordinates": [ 26.103516, 44.433780 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Chisinau" }, "geometry": { "type": "Point", "coordinates": [ 28.872070, 47.010226 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Istanbul", "POP2000": 8744 }, "geometry": { "type": "Point", "coordinates": [ 29.003906, 41.112469 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Moscow", "POP2000": 10016 }, "geometry": { "type": "Point", "coordinates": [ 37.617188, 55.751849 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tbilisi", "POP2000": 1100 }, "geometry": { "type": "Point", "coordinates": [ 44.780273, 41.738528 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Algiers", "POP2000": 2754 }, "geometry": { "type": "Point", "coordinates": [ 3.032227, 36.774092 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tunis" }, "geometry": { "type": "Point", "coordinates": [ 10.195312, 36.809285 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tripoli", "POP2000": 1877 }, "geometry": { "type": "Point", "coordinates": [ 13.183594, 32.879587 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Valletta" }, "geometry": { "type": "Point", "coordinates": [ 14.501953, 35.889050 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Niamey", "POP2000": 680 }, "geometry": { "type": "Point", "coordinates": [ 2.109375, 13.539201 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lome", "POP2000": 1023 }, "geometry": { "type": "Point", "coordinates": [ 1.230469, 6.140555 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Cotonou", "POP2000": 642 }, "geometry": { "type": "Point", "coordinates": [ 2.504883, 6.402648 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Porto-Novo" }, "geometry": { "type": "Point", "coordinates": [ 2.636719, 6.489983 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Lagos", "POP2000": 7233 }, "geometry": { "type": "Point", "coordinates": [ 3.383789, 6.446318 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Abuja", "POP2000": 832 }, "geometry": { "type": "Point", "coordinates": [ 7.514648, 9.102097 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sao Tome" }, "geometry": { "type": "Point", "coordinates": [ 6.723633, 0.351560 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Malabo" }, "geometry": { "type": "Point", "coordinates": [ 8.789062, 3.732708 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Libreville" }, "geometry": { "type": "Point", "coordinates": [ 9.448242, 0.395505 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ndjamena", "POP2000": 711 }, "geometry": { "type": "Point", "coordinates": [ 15.029297, 12.125264 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Yaounde", "POP2000": 1192 }, "geometry": { "type": "Point", "coordinates": [ 11.513672, 3.864255 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bangui" }, "geometry": { "type": "Point", "coordinates": [ 18.544922, 4.346411 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Athens", "POP2000": 3179 }, "geometry": { "type": "Point", "coordinates": [ 23.730469, 37.996163 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ankara", "POP2000": 3179 }, "geometry": { "type": "Point", "coordinates": [ 32.871094, 39.943436 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nicosia" }, "geometry": { "type": "Point", "coordinates": [ 33.354492, 35.173808 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Cairo", "POP2000": 10534 }, "geometry": { "type": "Point", "coordinates": [ 31.245117, 30.069094 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tel Aviv-Yafo", "POP2000": 2752 }, "geometry": { "type": "Point", "coordinates": [ 34.760742, 32.063956 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Beirut", "POP2000": 1487 }, "geometry": { "type": "Point", "coordinates": [ 35.507812, 33.870416 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Damascus", "POP2000": 2044 }, "geometry": { "type": "Point", "coordinates": [ 36.298828, 33.504759 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Yerevan", "POP2000": 1111 }, "geometry": { "type": "Point", "coordinates": [ 44.516602, 40.178873 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Baghdad", "POP2000": 5200 }, "geometry": { "type": "Point", "coordinates": [ 44.384766, 33.358062 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Jerusalem" }, "geometry": { "type": "Point", "coordinates": [ 35.200195, 31.765537 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Amman", "POP2000": 1007 }, "geometry": { "type": "Point", "coordinates": [ 35.947266, 31.952162 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Khartoum", "POP2000": 3949 }, "geometry": { "type": "Point", "coordinates": [ 32.519531, 15.580711 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Juba" }, "geometry": { "type": "Point", "coordinates": [ 31.596680, 4.828260 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kampala", "POP2000": 1097 }, "geometry": { "type": "Point", "coordinates": [ 32.563477, 0.307616 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Asmara" }, "geometry": { "type": "Point", "coordinates": [ 38.935547, 15.326572 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sanaa", "POP2000": 1365 }, "geometry": { "type": "Point", "coordinates": [ 44.208984, 15.368950 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Djibouti" }, "geometry": { "type": "Point", "coordinates": [ 43.154297, 11.609193 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Addis Ababa", "POP2000": 2493 }, "geometry": { "type": "Point", "coordinates": [ 38.715820, 9.015302 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Hargeysa" }, "geometry": { "type": "Point", "coordinates": [ 44.077148, 9.579084 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Astana" }, "geometry": { "type": "Point", "coordinates": [ 71.411133, 51.179343 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tashkent", "POP2000": 2135 }, "geometry": { "type": "Point", "coordinates": [ 69.301758, 41.310824 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bishkek", "POP2000": 770 }, "geometry": { "type": "Point", "coordinates": [ 74.575195, 42.875964 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Urumqi", "POP2000": 1730 }, "geometry": { "type": "Point", "coordinates": [ 87.583008, 43.802819 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Baku", "POP2000": 1806 }, "geometry": { "type": "Point", "coordinates": [ 49.877930, 40.413496 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tehran", "POP2000": 7128 }, "geometry": { "type": "Point", "coordinates": [ 51.416016, 35.675147 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kuwait", "POP2000": 1499 }, "geometry": { "type": "Point", "coordinates": [ 47.988281, 29.382175 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Riyadh", "POP2000": 3567 }, "geometry": { "type": "Point", "coordinates": [ 46.757812, 24.647017 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Manama" }, "geometry": { "type": "Point", "coordinates": [ 50.581055, 26.234302 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Doha" }, "geometry": { "type": "Point", "coordinates": [ 51.547852, 25.284438 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dubai", "POP2000": 938 }, "geometry": { "type": "Point", "coordinates": [ 55.283203, 25.244696 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Abu Dhabi" }, "geometry": { "type": "Point", "coordinates": [ 54.360352, 24.447150 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ashgabat" }, "geometry": { "type": "Point", "coordinates": [ 58.403320, 37.961523 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Muscat" }, "geometry": { "type": "Point", "coordinates": [ 58.579102, 23.604262 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Mogadishu", "POP2000": 1201 }, "geometry": { "type": "Point", "coordinates": [ 45.351562, 2.064982 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dushanbe" }, "geometry": { "type": "Point", "coordinates": [ 68.774414, 38.548165 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kabul", "POP2000": 1963 }, "geometry": { "type": "Point", "coordinates": [ 69.169922, 34.524661 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Islamabad", "POP2000": 594 }, "geometry": { "type": "Point", "coordinates": [ 73.168945, 33.687782 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "New Delhi" }, "geometry": { "type": "Point", "coordinates": [ 77.211914, 28.613459 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kathmandu", "POP2000": 644 }, "geometry": { "type": "Point", "coordinates": [ 85.297852, 27.722436 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Thimphu" }, "geometry": { "type": "Point", "coordinates": [ 89.648438, 27.488781 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kolkata", "POP2000": 13058 }, "geometry": { "type": "Point", "coordinates": [ 88.330078, 22.512557 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Mumbai", "POP2000": 16086 }, "geometry": { "type": "Point", "coordinates": [ 72.861328, 19.020577 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bangalore", "POP2000": 5567 }, "geometry": { "type": "Point", "coordinates": [ 77.563477, 12.983148 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Male" }, "geometry": { "type": "Point", "coordinates": [ 73.520508, 4.171115 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Colombo" }, "geometry": { "type": "Point", "coordinates": [ 79.848633, 6.926427 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Sri Jawewardenepura Kotte" }, "geometry": { "type": "Point", "coordinates": [ 79.936523, 6.882800 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Ulaanbaatar", "POP2000": 763 }, "geometry": { "type": "Point", "coordinates": [ 106.918945, 47.931066 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Dhaka", "POP2000": 10285 }, "geometry": { "type": "Point", "coordinates": [ 90.395508, 23.725012 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Chengdu", "POP2000": 3919 }, "geometry": { "type": "Point", "coordinates": [ 104.062500, 30.675715 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Naypyidaw" }, "geometry": { "type": "Point", "coordinates": [ 96.108398, 19.766704 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Rangoon", "POP2000": 3553 }, "geometry": { "type": "Point", "coordinates": [ 96.152344, 16.804541 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bangkok", "POP2000": 6332 }, "geometry": { "type": "Point", "coordinates": [ 100.502930, 13.752725 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Vientiane" }, "geometry": { "type": "Point", "coordinates": [ 102.612305, 17.978733 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Hanoi", "POP2000": 3752 }, "geometry": { "type": "Point", "coordinates": [ 105.864258, 21.043491 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Phnom Penh", "POP2000": 1160 }, "geometry": { "type": "Point", "coordinates": [ 104.897461, 11.566144 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kuala Lumpur", "POP2000": 1306 }, "geometry": { "type": "Point", "coordinates": [ 101.689453, 3.162456 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Putrajaya" }, "geometry": { "type": "Point", "coordinates": [ 101.689453, 2.899153 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Singapore", "POP2000": 4017 }, "geometry": { "type": "Point", "coordinates": [ 103.842773, 1.274309 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Beijing", "POP2000": 9782 }, "geometry": { "type": "Point", "coordinates": [ 116.367188, 39.943436 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Hong Kong", "POP2000": 6662 }, "geometry": { "type": "Point", "coordinates": [ 114.169922, 22.309426 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Shanghai", "POP2000": 13243 }, "geometry": { "type": "Point", "coordinates": [ 121.420898, 31.203405 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Taipei", "POP2000": 2640 }, "geometry": { "type": "Point", "coordinates": [ 121.552734, 25.045792 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Pyongyang", "POP2000": 3117 }, "geometry": { "type": "Point", "coordinates": [ 125.771484, 39.027719 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Seoul", "POP2000": 9917 }, "geometry": { "type": "Point", "coordinates": [ 127.001953, 37.579413 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Baguio City" }, "geometry": { "type": "Point", "coordinates": [ 120.585938, 16.425548 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Manila", "POP2000": 9958 }, "geometry": { "type": "Point", "coordinates": [ 120.981445, 14.604847 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bandar Seri Begawan" }, "geometry": { "type": "Point", "coordinates": [ 114.916992, 4.872048 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Melekeok" }, "geometry": { "type": "Point", "coordinates": [ 134.648438, 7.493196 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Osaka", "POP2000": 11165 }, "geometry": { "type": "Point", "coordinates": [ 135.439453, 34.741612 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kyoto", "POP2000": 1806 }, "geometry": { "type": "Point", "coordinates": [ 135.747070, 35.029996 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tokyo", "POP2000": 34450 }, "geometry": { "type": "Point", "coordinates": [ 139.746094, 35.675147 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Palikir" }, "geometry": { "type": "Point", "coordinates": [ 158.159180, 6.926427 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Majuro" }, "geometry": { "type": "Point", "coordinates": [ 171.386719, 7.100893 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Tarawa" }, "geometry": { "type": "Point", "coordinates": [ 173.012695, 1.318243 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Kigali", "POP2000": 497 }, "geometry": { "type": "Point", "coordinates": [ 30.058594, -1.933227 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Bujumbura" }, "geometry": { "type": "Point", "coordinates": [ 29.355469, -3.381824 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "NAME": "Nairobi", "POP2000": 2233 }, "geometry": { "type": "Point", "coordinates": [ 36.826172, -1.274309 ] } }
|
||||
] }
|
||||
] }
|
||||
] }
|
||||
@@ -1,21 +1,15 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 4, "NAME": "Castries" }, "geometry": { "type": "Point", "coordinates": [ -60.996094, 14.008696 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Reykjavík", "LATITUDE": 64.150024 }, "geometry": { "type": "Point", "coordinates": [ -21.884766, 64.129784 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Niamey" }, "geometry": { "type": "Point", "coordinates": [ 2.109375, 13.496473 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Astana", "LATITUDE": 51.181125 }, "geometry": { "type": "Point", "coordinates": [ 71.455078, 51.179343 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Wellington" }, "geometry": { "type": "MultiPoint", "coordinates": [ [ 174.814453, -41.310824 ], [ -185.273438, -41.310824 ] ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Yerevan", "LATITUDE": 40.181151 }, "geometry": { "type": "Point", "coordinates": [ 44.560547, 40.178873 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Sucre" }, "geometry": { "type": "Point", "coordinates": [ -65.214844, -19.062118 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 2, "NAME": "Oslo", "LATITUDE": 59.91669 }, "geometry": { "type": "Point", "coordinates": [ 10.810547, 59.888937 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Hargeysa" }, "geometry": { "type": "Point", "coordinates": [ 44.121094, 9.535749 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vancouver", "LATITUDE": 49.273417 }, "geometry": { "type": "Point", "coordinates": [ -123.134766, 49.267805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Chengdu" }, "geometry": { "type": "Point", "coordinates": [ 104.062500, 30.675715 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vancouver" }, "geometry": { "type": "Point", "coordinates": [ -123.134766, 49.267805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vienna" }, "geometry": { "type": "Point", "coordinates": [ 16.347656, 48.166085 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 0, "NAME": "Cape Town" }, "geometry": { "type": "Point", "coordinates": [ 18.457031, -33.943360 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vienna", "LATITUDE": 48.200015 }, "geometry": { "type": "Point", "coordinates": [ 16.347656, 48.166085 ] } }
|
||||
] }
|
||||
] }
|
||||
|
||||
@@ -0,0 +1,3 @@
|
||||
{"type":"Feature","properties":{"what":"no id"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12345,"properties":{"what":"will survive"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12346,"properties":{"what":"will win over the duplicate even though it's in another tile"},"geometry":{"type":"Point","coordinates":[-1,-1]}}
|
||||
@@ -0,0 +1,3 @@
|
||||
{"type":"Feature","properties":{"what":"no id again"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12346,"properties":{"what":"will be lost as a duplicate"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12347,"properties":{"what":"will be added"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
@@ -0,0 +1,11 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "layer", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "what": "no id" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12345, "properties": { "what": "will survive" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "what": "no id again" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12347, "properties": { "what": "will be added" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
] }
|
||||
] }
|
||||
@@ -0,0 +1,13 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "layer", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "what": "no id" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12345, "properties": { "what": "will survive" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "what": "no id again" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12346, "properties": { "what": "will be lost as a duplicate" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12347, "properties": { "what": "will be added" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
] }
|
||||
] }
|
||||
@@ -1 +1 @@
|
||||
{"*":["SCALERANK","eq",0]}
|
||||
{"*":["==","SCALERANK",0]}
|
||||
|
||||
+549
-779
File diff suppressed because one or more lines are too long
+2434
File diff suppressed because one or more lines are too long
+2426
File diff suppressed because one or more lines are too long
+1906
File diff suppressed because one or more lines are too long
+175
-326
@@ -44,6 +44,7 @@
|
||||
#include "geometry.hpp"
|
||||
#include "thread.hpp"
|
||||
#include "platform.hpp"
|
||||
#include "usage.hpp"
|
||||
|
||||
int pk = false;
|
||||
int pC = false;
|
||||
@@ -56,12 +57,8 @@ int minzoom = 0;
|
||||
std::map<std::string, std::string> renames;
|
||||
bool exclude_all = false;
|
||||
bool exclude_all_tile_attributes = false;
|
||||
bool exclude_all_tile_geometries = false;
|
||||
std::vector<std::string> unidecode_data;
|
||||
std::string join_tile_attribute;
|
||||
std::string join_table_expression;
|
||||
std::string join_table;
|
||||
size_t join_count_limit = 1;
|
||||
std::string attribute_for_id;
|
||||
|
||||
bool want_overzoom = false;
|
||||
int buffer = 5;
|
||||
@@ -79,92 +76,6 @@ struct stats {
|
||||
std::vector<struct strategy> strategies{};
|
||||
};
|
||||
|
||||
// list, per feature in the tile,
|
||||
// of lists of features in the sqlite response,
|
||||
// each of which is a mapping from keys to values
|
||||
std::vector<std::vector<std::map<std::string, mvt_value>>> get_joined_rows(sqlite3 *db, const std::vector<mvt_value> &join_keys) {
|
||||
std::vector<std::vector<std::map<std::string, mvt_value>>> ret;
|
||||
ret.resize(join_keys.size());
|
||||
|
||||
// double quotes for table and column identifiers
|
||||
const char *s = sqlite3_mprintf("select %s, * from \"%w\" where %s in (",
|
||||
join_table_expression.c_str(), join_table.c_str(), join_table_expression.c_str());
|
||||
std::string query = s;
|
||||
sqlite3_free((void *) s);
|
||||
|
||||
std::multimap<std::string, size_t> key_to_row;
|
||||
for (size_t i = 0; i < join_keys.size(); i++) {
|
||||
const mvt_value &v = join_keys[i];
|
||||
|
||||
// single quotes for literals
|
||||
if (v.type == mvt_string) {
|
||||
s = sqlite3_mprintf("'%q'", v.c_str());
|
||||
query += s;
|
||||
sqlite3_free((void *) s);
|
||||
key_to_row.emplace(v.get_string_value(), i);
|
||||
} else {
|
||||
std::string stringified = v.toString();
|
||||
key_to_row.emplace(stringified, i);
|
||||
query += stringified;
|
||||
}
|
||||
|
||||
if (i + 1 < join_keys.size()) {
|
||||
query += ", ";
|
||||
}
|
||||
}
|
||||
|
||||
// this doesn't add a LIMIT to the query because our limit
|
||||
// is per tiled feature, not a limit on the entire query response.
|
||||
query += ");";
|
||||
|
||||
sqlite3_stmt *stmt;
|
||||
if (sqlite3_prepare_v2(db, query.c_str(), -1, &stmt, NULL) != SQLITE_OK) {
|
||||
fprintf(stderr, "sqlite3 query %s failed: %s\n", query.c_str(), sqlite3_errmsg(db));
|
||||
exit(EXIT_SQLITE);
|
||||
}
|
||||
while (sqlite3_step(stmt) == SQLITE_ROW) {
|
||||
int count = sqlite3_column_count(stmt);
|
||||
std::map<std::string, mvt_value> row;
|
||||
|
||||
if (count > 0) {
|
||||
// join key is 0th column of query
|
||||
std::string key = (const char *) sqlite3_column_text(stmt, 0);
|
||||
auto f = key_to_row.equal_range(key);
|
||||
if (f.first == f.second) {
|
||||
fprintf(stderr, "Unexpected join key: %s\n", key.c_str());
|
||||
continue;
|
||||
}
|
||||
|
||||
for (auto ff = f.first; ff != f.second; ++ff) {
|
||||
if (ret[ff->second].size() < join_count_limit) {
|
||||
for (int i = 1; i < count; i++) {
|
||||
int type = sqlite3_column_type(stmt, i);
|
||||
mvt_value v;
|
||||
v.type = mvt_null;
|
||||
|
||||
if (type == SQLITE_INTEGER || type == SQLITE_FLOAT) {
|
||||
v = mvt_value(sqlite3_column_double(stmt, i));
|
||||
} else if (type == SQLITE_TEXT || type == SQLITE_BLOB) {
|
||||
v.set_string_value((const char *) sqlite3_column_text(stmt, i));
|
||||
}
|
||||
|
||||
const char *name = sqlite3_column_name(stmt, i);
|
||||
row.emplace(name, v);
|
||||
}
|
||||
|
||||
ret[ff->second].push_back(row);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
if (sqlite3_finalize(stmt) != SQLITE_OK) {
|
||||
fprintf(stderr, "sqlite3 finalize failed: %s\n", sqlite3_errmsg(db));
|
||||
exit(EXIT_SQLITE);
|
||||
}
|
||||
|
||||
return ret;
|
||||
}
|
||||
|
||||
struct arg {
|
||||
std::map<zxy, std::vector<std::string>> inputs{};
|
||||
std::map<zxy, std::string> outputs{};
|
||||
@@ -187,7 +98,7 @@ struct arg {
|
||||
double minlon2, maxlon2;
|
||||
};
|
||||
|
||||
void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<std::string, layermap_entry> &layermap, std::vector<std::string> &header, std::map<std::string, std::vector<std::string>> &mapping, sqlite3 *db, std::set<std::string> &exclude, std::set<std::string> &include, std::set<std::string> &keep_layers, std::set<std::string> &remove_layers, int ifmatched, mvt_tile &outtile, json_object *filter, struct arg *a) {
|
||||
void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<std::string, layermap_entry> &layermap, std::vector<std::string> &header, std::map<std::string, std::vector<std::string>> &mapping, sqlite3 * /* db */, std::set<std::string> &exclude, std::set<std::string> &include, std::set<std::string> &keep_layers, std::set<std::string> &remove_layers, int ifmatched, mvt_tile &outtile, json_object *filter, struct arg *a) {
|
||||
mvt_tile tile;
|
||||
int features_added = 0;
|
||||
bool was_compressed;
|
||||
@@ -253,30 +164,6 @@ void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<st
|
||||
}
|
||||
}
|
||||
|
||||
std::vector<std::vector<std::map<std::string, mvt_value>>> joined;
|
||||
if (db != NULL) {
|
||||
// collect join keys for sql query
|
||||
|
||||
std::vector<mvt_value> join_keys;
|
||||
join_keys.resize(layer.features.size());
|
||||
|
||||
for (size_t f = 0; f < layer.features.size(); f++) {
|
||||
mvt_feature &feat = layer.features[f];
|
||||
join_keys[f].type = mvt_no_such_key;
|
||||
|
||||
for (size_t t = 0; t + 1 < feat.tags.size(); t += 2) {
|
||||
const std::string &key = layer.keys[feat.tags[t]];
|
||||
if (key == join_tile_attribute) {
|
||||
const mvt_value &val = layer.values[feat.tags[t + 1]];
|
||||
join_keys[f] = val;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
joined = get_joined_rows(db, join_keys);
|
||||
}
|
||||
|
||||
auto tilestats = layermap.find(layer.name);
|
||||
|
||||
long long minx = LLONG_MAX;
|
||||
@@ -306,47 +193,6 @@ void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<st
|
||||
std::vector<match> matches;
|
||||
bool matched = false;
|
||||
|
||||
// start filling out sql matches
|
||||
|
||||
if (f < joined.size()) {
|
||||
if (joined[f].size() > 0) {
|
||||
matched = true;
|
||||
}
|
||||
|
||||
for (auto const &joined_feature : joined[f]) {
|
||||
match m;
|
||||
m.has_id = feat.has_id;
|
||||
m.id = feat.id;
|
||||
|
||||
if (!exclude_all_tile_attributes) {
|
||||
for (size_t t = 0; t + 1 < feat.tags.size(); t += 2) {
|
||||
const std::string &key = layer.keys[feat.tags[t]];
|
||||
mvt_value &val = layer.values[feat.tags[t + 1]];
|
||||
serial_val sv = mvt_value_to_serial_val(val);
|
||||
|
||||
if (include.count(key) || (!exclude_all && exclude.count(key) == 0 && exclude_attributes.count(key) == 0)) {
|
||||
m.attributes.insert(std::pair<std::string, std::pair<mvt_value, serial_val>>(key, std::pair<mvt_value, serial_val>(val, sv)));
|
||||
m.key_order.push_back(key);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
for (auto const &kv : joined_feature) {
|
||||
if (kv.first == attribute_for_id) {
|
||||
m.has_id = true;
|
||||
m.id = mvt_value_to_long_long(kv.second);
|
||||
} else if (include.count(kv.first) || (!exclude_all && exclude.count(kv.first) == 0 && exclude_attributes.count(kv.first) == 0)) {
|
||||
if (kv.second.type != mvt_null) {
|
||||
m.attributes.insert(std::pair<std::string, std::pair<mvt_value, serial_val>>(kv.first, std::pair<mvt_value, serial_val>(kv.second, mvt_value_to_serial_val(kv.second))));
|
||||
m.key_order.push_back(kv.first);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
matches.push_back(m);
|
||||
}
|
||||
}
|
||||
|
||||
// look for csv matches and start filling them out
|
||||
|
||||
if (!matched) {
|
||||
@@ -479,42 +325,46 @@ void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<st
|
||||
}
|
||||
}
|
||||
|
||||
outfeature.type = feat.type;
|
||||
outfeature.geometry = feat.geometry;
|
||||
if (exclude_all_tile_geometries) {
|
||||
outfeature.type = -1;
|
||||
} else {
|
||||
outfeature.type = feat.type;
|
||||
outfeature.geometry = feat.geometry;
|
||||
|
||||
if (layer.extent != outlayer.extent) {
|
||||
for (size_t i = 0; i < outfeature.geometry.size(); i++) {
|
||||
outfeature.geometry[i].x = outfeature.geometry[i].x * outlayer.extent / layer.extent;
|
||||
outfeature.geometry[i].y = outfeature.geometry[i].y * outlayer.extent / layer.extent;
|
||||
}
|
||||
}
|
||||
|
||||
for (auto const &g : outfeature.geometry) {
|
||||
if (g.op == mvt_moveto || g.op == mvt_lineto) {
|
||||
// pin to the tile extent, since we don't want bounds bigger than the earth
|
||||
long long gx = std::min((long long) outlayer.extent, std::max(0LL, g.x));
|
||||
long long gy = std::min((long long) outlayer.extent, std::max(0LL, g.y));
|
||||
|
||||
// to world scale
|
||||
gx = gx * (1LL << (32 - z)) / outlayer.extent;
|
||||
gy = gy * (1LL << (32 - z)) / outlayer.extent;
|
||||
|
||||
// to world offset
|
||||
gx += (1LL << (32 - z)) * x;
|
||||
gy += (1LL << (32 - z)) * y;
|
||||
|
||||
minx = std::min(minx, gx);
|
||||
miny = std::min(miny, gy);
|
||||
maxx = std::max(maxx, gx);
|
||||
maxy = std::max(maxy, gy);
|
||||
|
||||
// if in the western hemisphere, try shifting to east
|
||||
if (gx < (1LL << 31)) {
|
||||
gx += 1LL << 32;
|
||||
if (layer.extent != outlayer.extent) {
|
||||
for (size_t i = 0; i < outfeature.geometry.size(); i++) {
|
||||
outfeature.geometry[i].x = outfeature.geometry[i].x * outlayer.extent / layer.extent;
|
||||
outfeature.geometry[i].y = outfeature.geometry[i].y * outlayer.extent / layer.extent;
|
||||
}
|
||||
}
|
||||
|
||||
minx2 = std::min(minx2, gx);
|
||||
maxx2 = std::max(maxx2, gx);
|
||||
for (auto const &g : outfeature.geometry) {
|
||||
if (g.op == mvt_moveto || g.op == mvt_lineto) {
|
||||
// pin to the tile extent, since we don't want bounds bigger than the earth
|
||||
long long gx = std::min((long long) outlayer.extent, std::max(0LL, g.x));
|
||||
long long gy = std::min((long long) outlayer.extent, std::max(0LL, g.y));
|
||||
|
||||
// to world scale
|
||||
gx = gx * (1LL << (32 - z)) / outlayer.extent;
|
||||
gy = gy * (1LL << (32 - z)) / outlayer.extent;
|
||||
|
||||
// to world offset
|
||||
gx += (1LL << (32 - z)) * x;
|
||||
gy += (1LL << (32 - z)) * y;
|
||||
|
||||
minx = std::min(minx, gx);
|
||||
miny = std::min(miny, gy);
|
||||
maxx = std::max(maxx, gx);
|
||||
maxy = std::max(maxy, gy);
|
||||
|
||||
// if in the western hemisphere, try shifting to east
|
||||
if (gx < (1LL << 31)) {
|
||||
gx += 1LL << 32;
|
||||
}
|
||||
|
||||
minx2 = std::min(minx2, gx);
|
||||
maxx2 = std::max(maxx2, gx);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -982,7 +832,7 @@ struct tileset_reader {
|
||||
false, &next_overzoomed_tiles, false, NULL, false,
|
||||
std::unordered_map<std::string, attribute_op>(), unidecode_data, 0, 0,
|
||||
std::vector<mvt_layer>(), "", "", SIZE_MAX,
|
||||
std::vector<clipbbox>());
|
||||
std::vector<clipbbox>(), false);
|
||||
return ret;
|
||||
}
|
||||
|
||||
@@ -1043,7 +893,7 @@ void *join_worker(void *v) {
|
||||
}
|
||||
|
||||
void dispatch_tasks(std::map<zxy, std::vector<std::string>> &tasks, std::vector<std::map<std::string, layermap_entry>> &layermaps, sqlite3 *outdb, const char *outdir, std::vector<std::string> &header, std::map<std::string, std::vector<std::string>> &mapping, sqlite3 *db, std::set<std::string> &exclude, std::set<std::string> &include, int ifmatched, std::set<std::string> &keep_layers, std::set<std::string> &remove_layers, json_object *filter, struct tileset_reader *readers, double *minlat, double *minlon, double *maxlat, double *maxlon, double *minlon2, double *maxlon2) {
|
||||
pthread_t pthreads[CPUS];
|
||||
std::vector<pthread_t> pthreads(CPUS);
|
||||
std::vector<arg> args;
|
||||
|
||||
for (size_t i = 0; i < CPUS; i++) {
|
||||
@@ -1116,44 +966,44 @@ void dispatch_tasks(std::map<zxy, std::vector<std::string>> &tasks, std::vector<
|
||||
}
|
||||
|
||||
void handle_strategies(const unsigned char *s, std::vector<strategy> *st) {
|
||||
json_pull *jp = json_begin_string((const char *) s);
|
||||
json_object *o = json_read_tree(jp);
|
||||
json_pull_ptr jp = json_begin_string((const char *) s);
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
if (o != NULL && o->type == JSON_ARRAY) {
|
||||
for (size_t i = 0; i < o->value.array.length; i++) {
|
||||
json_object *h = o->value.array.array[i];
|
||||
if (o != nullptr && o->type == JSON_ARRAY) {
|
||||
for (size_t i = 0; i < o->array().size(); i++) {
|
||||
const json_object_ptr &h = o->array()[i];
|
||||
if (h->type == JSON_HASH) {
|
||||
for (size_t j = 0; j < h->value.object.length; j++) {
|
||||
json_object *k = h->value.object.keys[j];
|
||||
json_object *v = h->value.object.values[j];
|
||||
for (size_t j = 0; j < h->entries().size(); j++) {
|
||||
const auto &kv = h->entries()[j];
|
||||
|
||||
if (k->type != JSON_STRING) {
|
||||
if (kv.key->type != JSON_STRING) {
|
||||
fprintf(stderr, "Key %zu of %zu is not a string: %s\n", j, i, s);
|
||||
} else if (v->type != JSON_NUMBER) {
|
||||
} else if (kv.value->type != JSON_NUMBER) {
|
||||
fprintf(stderr, "Value %zu of %zu is not a number: %s\n", j, i, s);
|
||||
} else {
|
||||
if (i >= st->size()) {
|
||||
st->resize(i + 1);
|
||||
}
|
||||
|
||||
if (strcmp(k->value.string.string, "dropped_by_rate") == 0) {
|
||||
(*st)[i].dropped_by_rate += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "dropped_by_gamma") == 0) {
|
||||
(*st)[i].dropped_by_gamma += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "dropped_as_needed") == 0) {
|
||||
(*st)[i].dropped_as_needed += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "coalesced_as_needed") == 0) {
|
||||
(*st)[i].coalesced_as_needed += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "truncated_zooms") == 0) {
|
||||
(*st)[i].truncated_zooms += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "detail_reduced") == 0) {
|
||||
(*st)[i].detail_reduced += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "tiny_polygons") == 0) {
|
||||
(*st)[i].tiny_polygons += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "tile_size_desired") == 0) {
|
||||
(*st)[i].tile_size += v->value.number.number;
|
||||
} else if (strcmp(k->value.string.string, "feature_count_desired") == 0) {
|
||||
(*st)[i].feature_count += v->value.number.number;
|
||||
const std::string &key = kv.key->string();
|
||||
if (key == "dropped_by_rate") {
|
||||
(*st)[i].dropped_by_rate += kv.value->number();
|
||||
} else if (key == "dropped_by_gamma") {
|
||||
(*st)[i].dropped_by_gamma += kv.value->number();
|
||||
} else if (key == "dropped_as_needed") {
|
||||
(*st)[i].dropped_as_needed += kv.value->number();
|
||||
} else if (key == "coalesced_as_needed") {
|
||||
(*st)[i].coalesced_as_needed += kv.value->number();
|
||||
} else if (key == "truncated_zooms") {
|
||||
(*st)[i].truncated_zooms += kv.value->number();
|
||||
} else if (key == "detail_reduced") {
|
||||
(*st)[i].detail_reduced += kv.value->number();
|
||||
} else if (key == "tiny_polygons") {
|
||||
(*st)[i].tiny_polygons += kv.value->number();
|
||||
} else if (key == "tile_size_desired") {
|
||||
(*st)[i].tile_size += kv.value->number();
|
||||
} else if (key == "feature_count_desired") {
|
||||
(*st)[i].feature_count += kv.value->number();
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1161,22 +1011,19 @@ void handle_strategies(const unsigned char *s, std::vector<strategy> *st) {
|
||||
fprintf(stderr, "Element %zu is not a hash: %s\n", i, s);
|
||||
}
|
||||
}
|
||||
json_free(o);
|
||||
}
|
||||
|
||||
json_end(jp);
|
||||
}
|
||||
|
||||
void handle_vector_layers(json_object *vector_layers, std::map<std::string, layermap_entry> &layermap, std::map<std::string, std::string> &attribute_descriptions) {
|
||||
if (vector_layers != NULL && vector_layers->type == JSON_ARRAY) {
|
||||
for (size_t i = 0; i < vector_layers->value.array.length; i++) {
|
||||
if (vector_layers->value.array.array[i]->type == JSON_HASH) {
|
||||
json_object *id = json_hash_get(vector_layers->value.array.array[i], "id");
|
||||
json_object *desc = json_hash_get(vector_layers->value.array.array[i], "description");
|
||||
if (vector_layers != nullptr && vector_layers->type == JSON_ARRAY) {
|
||||
for (size_t i = 0; i < vector_layers->array().size(); i++) {
|
||||
if (vector_layers->array()[i]->type == JSON_HASH) {
|
||||
json_object *id = json_hash_get(vector_layers->array()[i].get(), "id");
|
||||
json_object *desc = json_hash_get(vector_layers->array()[i].get(), "description");
|
||||
|
||||
if (id != NULL && desc != NULL && id->type == JSON_STRING && desc->type == JSON_STRING) {
|
||||
std::string sid = id->value.string.string;
|
||||
std::string sdesc = desc->value.string.string;
|
||||
if (id != nullptr && desc != nullptr && id->type == JSON_STRING && desc->type == JSON_STRING) {
|
||||
const std::string &sid = id->string();
|
||||
const std::string &sdesc = desc->string();
|
||||
|
||||
if (sdesc.size() != 0) {
|
||||
auto f = layermap.find(sid);
|
||||
@@ -1186,17 +1033,18 @@ void handle_vector_layers(json_object *vector_layers, std::map<std::string, laye
|
||||
}
|
||||
}
|
||||
|
||||
json_object *fields = json_hash_get(vector_layers->value.array.array[i], "fields");
|
||||
if (fields != NULL && fields->type == JSON_HASH) {
|
||||
for (size_t j = 0; j < fields->value.object.length; j++) {
|
||||
if (fields->value.object.keys[j]->type == JSON_STRING && fields->value.object.values[j]->type) {
|
||||
const char *desc2 = fields->value.object.values[j]->value.string.string;
|
||||
json_object *fields = json_hash_get(vector_layers->array()[i].get(), "fields");
|
||||
if (fields != nullptr && fields->type == JSON_HASH) {
|
||||
for (const auto &e : fields->entries()) {
|
||||
if (e.key != nullptr && e.key->type == JSON_STRING &&
|
||||
e.value != nullptr && e.value->type == JSON_STRING) {
|
||||
const std::string &desc2 = e.value->string();
|
||||
|
||||
if (strcmp(desc2, "Number") != 0 &&
|
||||
strcmp(desc2, "String") != 0 &&
|
||||
strcmp(desc2, "Boolean") != 0 &&
|
||||
strcmp(desc2, "Mixed") != 0) {
|
||||
attribute_descriptions.insert(std::pair<std::string, std::string>(fields->value.object.keys[j]->value.string.string, desc2));
|
||||
if (desc2 != "Number" &&
|
||||
desc2 != "String" &&
|
||||
desc2 != "Boolean" &&
|
||||
desc2 != "Mixed") {
|
||||
attribute_descriptions.insert(std::pair<std::string, std::string>(e.key->string(), desc2));
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1356,17 +1204,14 @@ void decode(struct tileset_reader *readers, std::map<std::string, layermap_entry
|
||||
const unsigned char *s = sqlite3_column_text(stmt, 0);
|
||||
|
||||
if (s != NULL) {
|
||||
json_pull *jp = json_begin_string((const char *) s);
|
||||
json_object *o = json_read_tree(jp);
|
||||
json_pull_ptr jp = json_begin_string((const char *) s);
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
if (o != NULL && o->type == JSON_HASH) {
|
||||
if (o != nullptr && o->type == JSON_HASH) {
|
||||
json_object *vector_layers = json_hash_get(o, "vector_layers");
|
||||
|
||||
handle_vector_layers(vector_layers, layermap, attribute_descriptions);
|
||||
json_free(o);
|
||||
}
|
||||
|
||||
json_end(jp);
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1404,8 +1249,81 @@ void decode(struct tileset_reader *readers, std::map<std::string, layermap_entry
|
||||
}
|
||||
}
|
||||
|
||||
static const struct option long_options[] = {
|
||||
{"Output tileset", 0, 0, 0},
|
||||
{"output", required_argument, 0, 'o'},
|
||||
{"output-to-directory", required_argument, 0, 'e'},
|
||||
{"force", no_argument, 0, 'f'},
|
||||
|
||||
{"Tileset description and attribution", 0, 0, 0},
|
||||
{"name", required_argument, 0, 'n'},
|
||||
{"attribution", required_argument, 0, 'A'},
|
||||
{"description", required_argument, 0, 'N'},
|
||||
|
||||
{"Input tilesets", 0, 0, 0},
|
||||
{"read-from", required_argument, 0, 'r'},
|
||||
|
||||
{"Zoom levels", 0, 0, 0},
|
||||
{"maximum-zoom", required_argument, 0, 'z'},
|
||||
{"minimum-zoom", required_argument, 0, 'Z'},
|
||||
{"overzoom", no_argument, 0, 'O'},
|
||||
{"buffer", required_argument, 0, 'b'},
|
||||
|
||||
{"Layer names", 0, 0, 0},
|
||||
{"layer", required_argument, 0, 'l'},
|
||||
{"exclude-layer", required_argument, 0, 'L'},
|
||||
{"rename-layer", required_argument, 0, 'R'},
|
||||
|
||||
{"Joining with a CSV file", 0, 0, 0},
|
||||
{"csv", required_argument, 0, 'c'},
|
||||
{"if-matched", no_argument, 0, 'i'},
|
||||
{"empty-csv-columns-are-null", no_argument, &pe, 1},
|
||||
|
||||
{"Filtering feature attributes", 0, 0, 0},
|
||||
{"exclude", required_argument, 0, 'x'},
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{"exclude-all", no_argument, 0, 'X'},
|
||||
{"exclude-all-tile-attributes", no_argument, 0, '~'},
|
||||
{"exclude-all-tile-geometries", no_argument, 0, '~'},
|
||||
|
||||
{"Filtering features by attributes", 0, 0, 0},
|
||||
{"feature-filter-file", required_argument, 0, 'J'},
|
||||
{"feature-filter", required_argument, 0, 'j'},
|
||||
|
||||
{"Setting or disabling tile size limits", 0, 0, 0},
|
||||
{"no-tile-size-limit", no_argument, &pk, 1},
|
||||
{"no-tile-compression", no_argument, &pC, 1},
|
||||
{"no-tile-stats", no_argument, &pg, 1},
|
||||
{"tile-stats-attributes-limit", required_argument, 0, '~'},
|
||||
{"tile-stats-sample-values-limit", required_argument, 0, '~'},
|
||||
{"tile-stats-values-limit", required_argument, 0, '~'},
|
||||
|
||||
{"Progress indicator", 0, 0, 0},
|
||||
{"quiet", no_argument, 0, 'q'},
|
||||
|
||||
{"", 0, 0, 0},
|
||||
{"prevent", required_argument, 0, 'p'},
|
||||
{"unidecode-data", required_argument, 0, '~'},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
// the options above, with the usage message headings removed
|
||||
static struct option real_long_options[sizeof(long_options) / sizeof(long_options[0])];
|
||||
|
||||
void usage(char **argv) {
|
||||
fprintf(stderr, "Usage: %s [-f] [-i] [-pk] [-pC] [-c joins.csv] [-X] [-x exclude ...] [-y include ...] [-r inputfile.txt ] -o new.mbtiles source.mbtiles ...\n", argv[0]);
|
||||
static const char *const forms[] = {
|
||||
"[options] source.mbtiles ...",
|
||||
"[options] --read-from=inputfile.txt",
|
||||
NULL,
|
||||
};
|
||||
static const struct usage_required_option required[] = {
|
||||
{"output", "new.mbtiles", 1},
|
||||
{"output-to-directory", "directory", 1},
|
||||
{NULL, NULL, 0},
|
||||
};
|
||||
|
||||
print_usage(stderr, argv[0], forms, long_options, required);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
@@ -1417,7 +1335,7 @@ int main(int argc, char **argv) {
|
||||
int force = 0;
|
||||
int ifmatched = 0;
|
||||
int filearg = 0;
|
||||
json_object *filter = NULL;
|
||||
json_object_ptr filter;
|
||||
|
||||
std::string join_sqlite_fname;
|
||||
|
||||
@@ -1449,61 +1367,8 @@ int main(int argc, char **argv) {
|
||||
|
||||
std::string set_name, set_description, set_attribution;
|
||||
|
||||
struct option long_options[] = {
|
||||
{"output", required_argument, 0, 'o'},
|
||||
{"output-to-directory", required_argument, 0, 'e'},
|
||||
{"force", no_argument, 0, 'f'},
|
||||
{"overzoom", no_argument, 0, 'O'},
|
||||
{"buffer", required_argument, 0, 'b'},
|
||||
{"if-matched", no_argument, 0, 'i'},
|
||||
{"attribution", required_argument, 0, 'A'},
|
||||
{"name", required_argument, 0, 'n'},
|
||||
{"description", required_argument, 0, 'N'},
|
||||
{"prevent", required_argument, 0, 'p'},
|
||||
{"csv", required_argument, 0, 'c'},
|
||||
{"exclude", required_argument, 0, 'x'},
|
||||
{"exclude-all", no_argument, 0, 'X'},
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{"exclude-all-tile-attributes", no_argument, 0, '~'},
|
||||
{"layer", required_argument, 0, 'l'},
|
||||
{"exclude-layer", required_argument, 0, 'L'},
|
||||
{"quiet", no_argument, 0, 'q'},
|
||||
{"maximum-zoom", required_argument, 0, 'z'},
|
||||
{"minimum-zoom", required_argument, 0, 'Z'},
|
||||
{"feature-filter-file", required_argument, 0, 'J'},
|
||||
{"feature-filter", required_argument, 0, 'j'},
|
||||
{"rename-layer", required_argument, 0, 'R'},
|
||||
{"read-from", required_argument, 0, 'r'},
|
||||
|
||||
{"join-sqlite", required_argument, 0, '~'},
|
||||
{"join-tile-attribute", required_argument, 0, '~'},
|
||||
{"join-table-expression", required_argument, 0, '~'},
|
||||
{"join-table", required_argument, 0, '~'},
|
||||
{"join-count-limit", required_argument, 0, '~'},
|
||||
{"use-attribute-for-id", required_argument, 0, '~'},
|
||||
|
||||
{"no-tile-size-limit", no_argument, &pk, 1},
|
||||
{"no-tile-compression", no_argument, &pC, 1},
|
||||
{"empty-csv-columns-are-null", no_argument, &pe, 1},
|
||||
{"no-tile-stats", no_argument, &pg, 1},
|
||||
{"tile-stats-attributes-limit", required_argument, 0, '~'},
|
||||
{"tile-stats-sample-values-limit", required_argument, 0, '~'},
|
||||
{"tile-stats-values-limit", required_argument, 0, '~'},
|
||||
{"unidecode-data", required_argument, 0, '~'},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
};
|
||||
|
||||
std::string getopt_str;
|
||||
for (size_t lo = 0; long_options[lo].name != NULL; lo++) {
|
||||
if (long_options[lo].val > ' ') {
|
||||
getopt_str.push_back(long_options[lo].val);
|
||||
|
||||
if (long_options[lo].has_arg == required_argument) {
|
||||
getopt_str.push_back(':');
|
||||
}
|
||||
}
|
||||
}
|
||||
strip_usage_headings(long_options, real_long_options);
|
||||
std::string getopt_str = getopt_string(real_long_options);
|
||||
|
||||
extern int optind;
|
||||
extern char *optarg;
|
||||
@@ -1512,7 +1377,7 @@ int main(int argc, char **argv) {
|
||||
std::string commandline = format_commandline(argc, argv);
|
||||
|
||||
int option_index = 0;
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), long_options, &option_index)) != -1) {
|
||||
while ((i = getopt_long(argc, argv, getopt_str.c_str(), real_long_options, &option_index)) != -1) {
|
||||
switch (i) {
|
||||
case 0:
|
||||
break;
|
||||
@@ -1657,7 +1522,7 @@ int main(int argc, char **argv) {
|
||||
break;
|
||||
|
||||
case '~': {
|
||||
const char *opt = long_options[option_index].name;
|
||||
const char *opt = real_long_options[option_index].name;
|
||||
if (strcmp(opt, "tile-stats-attributes-limit") == 0) {
|
||||
max_tilestats_attributes = atoi(optarg);
|
||||
} else if (strcmp(opt, "tile-stats-sample-values-limit") == 0) {
|
||||
@@ -1666,24 +1531,10 @@ int main(int argc, char **argv) {
|
||||
max_tilestats_values = atoi(optarg);
|
||||
} else if (strcmp(opt, "unidecode-data") == 0) {
|
||||
unidecode_data = read_unidecode(optarg);
|
||||
} else if (strcmp(opt, "join-sqlite") == 0) {
|
||||
join_sqlite_fname = optarg;
|
||||
if (sqlite3_open(optarg, &db) != SQLITE_OK) {
|
||||
fprintf(stderr, "%s: %s\n", optarg, sqlite3_errmsg(db));
|
||||
exit(EXIT_SQLITE);
|
||||
}
|
||||
} else if (strcmp(opt, "join-table") == 0) {
|
||||
join_table = optarg;
|
||||
} else if (strcmp(opt, "join-table-expression") == 0) {
|
||||
join_table_expression = optarg;
|
||||
} else if (strcmp(opt, "join-tile-attribute") == 0) {
|
||||
join_tile_attribute = optarg;
|
||||
} else if (strcmp(opt, "use-attribute-for-id") == 0) {
|
||||
attribute_for_id = optarg;
|
||||
} else if (strcmp(opt, "exclude-all-tile-attributes") == 0) {
|
||||
exclude_all_tile_attributes = true;
|
||||
} else if (strcmp(opt, "join-count-limit") == 0) {
|
||||
join_count_limit = atoi(optarg);
|
||||
} else if (strcmp(opt, "exclude-all-tile-geometries") == 0) {
|
||||
exclude_all_tile_geometries = true;
|
||||
} else {
|
||||
fprintf(stderr, "%s: Unrecognized option --%s\n", argv[0], opt);
|
||||
exit(EXIT_ARGS);
|
||||
@@ -1765,7 +1616,7 @@ int main(int argc, char **argv) {
|
||||
std::string generator_options;
|
||||
std::vector<strategy> strategies;
|
||||
|
||||
decode(readers, layermap, outdb, out_dir, &st, header, mapping, db, exclude, include, ifmatched, attribution, description, keep_layers, remove_layers, name, filter, attribute_descriptions, generator_options, &strategies);
|
||||
decode(readers, layermap, outdb, out_dir, &st, header, mapping, db, exclude, include, ifmatched, attribution, description, keep_layers, remove_layers, name, filter.get(), attribute_descriptions, generator_options, &strategies);
|
||||
|
||||
if (set_attribution.size() != 0) {
|
||||
attribution = set_attribution;
|
||||
@@ -1817,9 +1668,7 @@ int main(int argc, char **argv) {
|
||||
mbtiles_close(outdb, argv[0]);
|
||||
}
|
||||
|
||||
if (filter != NULL) {
|
||||
json_free(filter);
|
||||
}
|
||||
filter.reset();
|
||||
|
||||
if (pmtiles_has_suffix(out_mbtiles)) {
|
||||
mbtiles_map_image_to_pmtiles(out_mbtiles, m, !pC, quiet, false);
|
||||
|
||||
@@ -62,7 +62,7 @@ struct strategy {
|
||||
|
||||
// long long write_tile(char **geom, char *stringpool, unsigned *file_bbox, int z, unsigned x, unsigned y, int detail, int min_detail, int basezoom, sqlite3 *outdb, const char *outdir, double droprate, int buffer, const char *fname, FILE **geomfile, int file_minzoom, int file_maxzoom, double todo, char *geomstart, long long along, double gamma, int nlayers, std::atomic<strategy> *strategy);
|
||||
|
||||
int traverse_zooms(int *geomfd, off_t *geom_size, char *stringpool, std::atomic<unsigned> *midx, std::atomic<unsigned> *midy, int &maxzoom, int minzoom, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, const char *tmpdir, double gamma, int full_detail, int low_detail, int min_detail, long long *pool_off, unsigned *initial_x, unsigned *initial_y, double simplification, double maxzoom_simplification, std::vector<std::map<std::string, layermap_entry> > &layermap, const char *prefilter, const char *postfilter, std::unordered_map<std::string, attribute_op> const *attribute_accum, struct json_object *filter, std::vector<strategy> &strategies, int iz, struct node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, int basezoom, double droprate, std::vector<std::string> const &unidecode_data);
|
||||
int traverse_zooms(int *geomfd, off_t *geom_size, char *stringpool, std::atomic<unsigned> *midx, std::atomic<unsigned> *midy, int &maxzoom, int minzoom, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, const char *tmpdir, double gamma, int full_detail, int low_detail, int min_detail, long long *pool_off, unsigned *initial_x, unsigned *initial_y, double simplification, double maxzoom_simplification, std::vector<std::map<std::string, layermap_entry> > &layermap, const char *prefilter, const char *postfilter, std::unordered_map<std::string, attribute_op> const *attribute_accum, json_object *filter, std::vector<strategy> &strategies, int iz, struct node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, int basezoom, double droprate, std::vector<std::string> const &unidecode_data, std::string const *drop_by_attribute_as_needed_attribute, bool drop_by_attribute_descending);
|
||||
|
||||
int manage_gap(unsigned long long index, unsigned long long *previndex, double scale, double gamma, double *gap);
|
||||
|
||||
|
||||
@@ -6,6 +6,7 @@
|
||||
#include "mvt.hpp"
|
||||
#include "projection.hpp"
|
||||
#include "geometry.hpp"
|
||||
#include "jsonpull/jsonpull.h"
|
||||
#include <unistd.h>
|
||||
#include <limits.h>
|
||||
|
||||
@@ -73,7 +74,7 @@ TEST_CASE("External quicksort", "fqsort") {
|
||||
unlink(tmpname.c_str());
|
||||
FILE *f = fdopen(fd, "w+b");
|
||||
|
||||
fqsort(inputs, sizeof(int), intcmp, f, 256);
|
||||
fqsort(inputs, sizeof(int), intcmp, f, 256, "/tmp");
|
||||
rewind(f);
|
||||
|
||||
int prev = INT_MIN;
|
||||
@@ -128,27 +129,402 @@ TEST_CASE("Bit reversal", "bit reversal") {
|
||||
REQUIRE(bit_reverse(0xF3D912481E6A2C48) == 0x1234567812489BCF);
|
||||
}
|
||||
|
||||
TEST_CASE("mvt_geometry bbox") {
|
||||
std::vector<mvt_geometry> geom;
|
||||
TEST_CASE("line_is_too_small") {
|
||||
drawvec dv;
|
||||
dv.emplace_back(VT_MOVETO, 4243099709, 2683872952);
|
||||
dv.emplace_back(VT_LINETO, 4243102487, 2683873977);
|
||||
dv.emplace_back(VT_MOVETO, -51867587, 2683872952);
|
||||
dv.emplace_back(VT_LINETO, -51864809, 2683873977);
|
||||
REQUIRE(line_is_too_small(dv, 0, 10));
|
||||
}
|
||||
|
||||
geom.emplace_back(mvt_moveto, 128, 128);
|
||||
geom.emplace_back(mvt_lineto, 256, 256);
|
||||
// A high surrogate followed by a non-surrogate used to be combined into one
|
||||
// code point, because the range check tested the outer-loop byte instead of
|
||||
// the parsed code unit. The stale surrogate should come out as standalone
|
||||
// CESU-8, then U+E000 encoded normally.
|
||||
TEST_CASE("jsonpull surrogate-pair regression", "[jsonpull][surrogate]") {
|
||||
json_pull_ptr jp = json_begin_string("\"\\uD83D\\uE000\"");
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
get_bbox(geom, &xmin, &ymin, &xmax, &ymax, 11, 327, 791, 9);
|
||||
REQUIRE(jp->error == nullptr);
|
||||
REQUIRE(o != nullptr);
|
||||
REQUIRE(o->type == JSON_STRING);
|
||||
|
||||
double lon, lat;
|
||||
tile2lonlat(xmin, ymin, 32, &lon, &lat);
|
||||
REQUIRE(std::to_string(lon) == "-122.475586");
|
||||
REQUIRE(std::to_string(lat) == "37.822802");
|
||||
const std::string expected = "\xED\xA0\xBD\xEE\x80\x80";
|
||||
REQUIRE(o->string() == expected);
|
||||
|
||||
tile2lonlat(xmax, ymax, 32, &lon, &lat);
|
||||
REQUIRE(std::to_string(lon) == "-122.431641");
|
||||
REQUIRE(std::to_string(lat) == "37.788081");
|
||||
// Sanity check: the buggy output (a single 4-byte UTF-8 sequence for
|
||||
// U+1F400) must not be what we got.
|
||||
const std::string buggy = "\xF0\x9F\x90\x80";
|
||||
REQUIRE(o->string() != buggy);
|
||||
}
|
||||
|
||||
unsigned long long start, end;
|
||||
get_quadkey_bounds(xmin, ymin, xmax, ymax, &start, &end);
|
||||
// 22 bits in common, for z11
|
||||
REQUIRE(start == 0x1c84fc0000000000);
|
||||
REQUIRE(end == 0x1c84ffffffffffff);
|
||||
// What geojson-loop does: free each feature once serialized, so they do not
|
||||
// accumulate while the rest of the document is parsed.
|
||||
//
|
||||
// This shape cannot catch the array-splicing bug, at any size: json_read hands
|
||||
// back each container as it completes, so the node freed here is always the
|
||||
// last-added element of its parent, which the old memmove got right by moving
|
||||
// zero bytes. "json_free prunes a non-final element" below covers that.
|
||||
TEST_CASE("json_free prunes a subtree from its parent", "[jsonpull][memory]") {
|
||||
json_pull_ptr jp = json_begin_string("[[1, 2], [3, 4], [5, 6]]");
|
||||
|
||||
json_object *outer = nullptr;
|
||||
int arrays_seen = 0;
|
||||
|
||||
json_object *j;
|
||||
while ((j = json_read(jp)) != nullptr) {
|
||||
if (j->type != JSON_ARRAY) {
|
||||
continue;
|
||||
}
|
||||
arrays_seen++;
|
||||
if (arrays_seen == 2) {
|
||||
// This is [3, 4]; verify, then ask the parser to drop it.
|
||||
REQUIRE(j->array().size() == 2);
|
||||
REQUIRE(j->array()[0]->number() == 3);
|
||||
REQUIRE(j->array()[1]->number() == 4);
|
||||
json_free(j);
|
||||
} else if (j->parent == nullptr) {
|
||||
// The completed outer array; the parser still owns it
|
||||
// via jp->root, so the borrowed pointer stays valid.
|
||||
outer = j;
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
REQUIRE(outer != nullptr);
|
||||
REQUIRE(outer->type == JSON_ARRAY);
|
||||
REQUIRE(outer->array().size() == 2);
|
||||
|
||||
// First surviving element: [1, 2].
|
||||
REQUIRE(outer->array()[0]->type == JSON_ARRAY);
|
||||
REQUIRE(outer->array()[0]->array().size() == 2);
|
||||
REQUIRE(outer->array()[0]->array()[0]->number() == 1);
|
||||
REQUIRE(outer->array()[0]->array()[1]->number() == 2);
|
||||
|
||||
// Second surviving element (previously third): [5, 6].
|
||||
REQUIRE(outer->array()[1]->type == JSON_ARRAY);
|
||||
REQUIRE(outer->array()[1]->array().size() == 2);
|
||||
REQUIRE(outer->array()[1]->array()[0]->number() == 5);
|
||||
REQUIRE(outer->array()[1]->array()[1]->number() == 6);
|
||||
}
|
||||
|
||||
// A top-level value has no parent, so json_free has to drop the parser's
|
||||
// reference instead. jp->root being empty afterwards is also proof the subtree
|
||||
// was destroyed, since jp->root was its only owner.
|
||||
TEST_CASE("json_free releases a top-level value held by the parser", "[jsonpull][memory]") {
|
||||
json_pull_ptr jp = json_begin_string(R"({"a": 1, "b": [2, 3]})");
|
||||
|
||||
// json_read streams atoms first (1, 2, 3, [2,3], ...); the top-level
|
||||
// hash is returned by the final `}` token.
|
||||
json_object *top = nullptr;
|
||||
json_object *j;
|
||||
while ((j = json_read(jp)) != nullptr) {
|
||||
if (j->parent == nullptr) {
|
||||
top = j;
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
REQUIRE(top != nullptr);
|
||||
REQUIRE(top->type == JSON_HASH);
|
||||
REQUIRE(jp->root.get() == top);
|
||||
|
||||
json_free(top);
|
||||
// top is dangling now; do not dereference.
|
||||
|
||||
REQUIRE(jp->root == nullptr);
|
||||
}
|
||||
|
||||
// Nothing in tippecanoe calls json_disconnect today -- the filter loaders get
|
||||
// the same guarantee from json_read_tree -- so cover it here rather than leave
|
||||
// a documented ownership primitive untested.
|
||||
TEST_CASE("json_disconnect hands a subtree to the caller", "[jsonpull][ownership]") {
|
||||
json_object_ptr taken;
|
||||
json_object *outer = nullptr;
|
||||
|
||||
json_pull_ptr jp = json_begin_string("[[1, 2], [3, 4]]");
|
||||
|
||||
int arrays_seen = 0;
|
||||
json_object *j;
|
||||
while ((j = json_read(jp)) != nullptr) {
|
||||
if (j->type != JSON_ARRAY) {
|
||||
continue;
|
||||
}
|
||||
arrays_seen++;
|
||||
if (arrays_seen == 2) {
|
||||
// This is [3, 4]; take it away from the enclosing array.
|
||||
taken = json_disconnect(j);
|
||||
REQUIRE(taken != nullptr);
|
||||
REQUIRE(taken.get() == j);
|
||||
} else if (j->parent == nullptr) {
|
||||
outer = j;
|
||||
break;
|
||||
}
|
||||
}
|
||||
|
||||
// The outer array is left holding only the element we didn't take,
|
||||
// and the parser is still the owner of it.
|
||||
REQUIRE(outer != nullptr);
|
||||
REQUIRE(jp->root.get() == outer);
|
||||
REQUIRE(outer->array().size() == 1);
|
||||
REQUIRE(outer->array()[0]->array().size() == 2);
|
||||
REQUIRE(outer->array()[0]->array()[0]->number() == 1);
|
||||
REQUIRE(outer->array()[0]->array()[1]->number() == 2);
|
||||
|
||||
// The detached subtree holds no pointers into the parser...
|
||||
REQUIRE(taken->parser == nullptr);
|
||||
REQUIRE(taken->array()[0]->parser == nullptr);
|
||||
REQUIRE(taken->array()[1]->parser == nullptr);
|
||||
|
||||
// ...and its root no longer points out at the array it was spliced
|
||||
// from, but the parent links *within* it are left intact so the tree
|
||||
// stays navigable upwards.
|
||||
REQUIRE(taken->parent == nullptr);
|
||||
REQUIRE(taken->array()[0]->parent == taken.get());
|
||||
REQUIRE(taken->array()[1]->parent == taken.get());
|
||||
|
||||
// So the subtree stays valid once the parser, and the tree the parser
|
||||
// still owns, are destroyed.
|
||||
jp.reset();
|
||||
// outer is dangling now; do not dereference.
|
||||
|
||||
REQUIRE(taken->type == JSON_ARRAY);
|
||||
REQUIRE(taken->array().size() == 2);
|
||||
REQUIRE(taken->array()[0]->number() == 3);
|
||||
REQUIRE(taken->array()[1]->number() == 4);
|
||||
}
|
||||
|
||||
// json_free finds a node's owner through o->parent, so clearing the interior
|
||||
// parent links on detach would make this a silent no-op.
|
||||
TEST_CASE("json_free prunes an interior node of a detached tree", "[jsonpull][ownership]") {
|
||||
json_pull_ptr jp = json_begin_string("[[1, 2], [3, 4], [5, 6]]");
|
||||
json_object_ptr tree = json_read_tree(jp);
|
||||
|
||||
REQUIRE(tree != nullptr);
|
||||
REQUIRE(tree->type == JSON_ARRAY);
|
||||
REQUIRE(tree->array().size() == 3);
|
||||
|
||||
// Destroy the parser first, so this is unambiguously operating on a
|
||||
// tree that no longer has one.
|
||||
jp.reset();
|
||||
REQUIRE(tree->parser == nullptr);
|
||||
|
||||
json_object *drop = tree->array()[1].get();
|
||||
REQUIRE(drop->array()[0]->number() == 3);
|
||||
REQUIRE(drop->parent == tree.get());
|
||||
|
||||
json_free(drop);
|
||||
// drop is dangling now; do not dereference.
|
||||
|
||||
// Had the parent links been cleared on detach, json_free would not
|
||||
// have found an owner to splice the node out of, and the array would
|
||||
// still have three elements.
|
||||
REQUIRE(tree->array().size() == 2);
|
||||
REQUIRE(tree->array()[0]->array()[0]->number() == 1);
|
||||
REQUIRE(tree->array()[1]->array()[0]->number() == 5);
|
||||
}
|
||||
|
||||
// Not a removal: the key stays with a JSON_NULL stand-in so the surrounding
|
||||
// pairs keep their alignment, and the entry goes only when both halves do.
|
||||
TEST_CASE("json_free of a hash value leaves a null placeholder", "[jsonpull][ownership]") {
|
||||
json_pull_ptr jp = json_begin_string(R"({"keep": 1, "drop": [2, 3]})");
|
||||
json_object_ptr tree = json_read_tree(jp);
|
||||
|
||||
REQUIRE(tree != nullptr);
|
||||
REQUIRE(tree->entries().size() == 2);
|
||||
|
||||
json_object *drop = json_hash_get(tree, "drop");
|
||||
REQUIRE(drop != nullptr);
|
||||
REQUIRE(drop->type == JSON_ARRAY);
|
||||
|
||||
json_free(drop);
|
||||
// drop is dangling now; do not dereference.
|
||||
|
||||
// The key survives, now paired with a null rather than the array.
|
||||
REQUIRE(tree->entries().size() == 2);
|
||||
json_object *after = json_hash_get(tree, "drop");
|
||||
REQUIRE(after != nullptr);
|
||||
REQUIRE(after->type == JSON_NULL);
|
||||
|
||||
// The neighbouring pair is untouched.
|
||||
REQUIRE(json_hash_get(tree, "keep") != nullptr);
|
||||
REQUIRE(json_hash_get(tree, "keep")->number() == 1);
|
||||
}
|
||||
|
||||
// The array-splicing fix. The old code passed an element count to memmove
|
||||
// where a byte count was wanted, so pruning element 0 of eight left
|
||||
// arr[0] == arr[1] -- one node owned twice -- and dropped the last element.
|
||||
// Asserting each survivor's identity is what discriminates; checking only the
|
||||
// size would not.
|
||||
TEST_CASE("json_free prunes a non-final element", "[jsonpull][ownership]") {
|
||||
json_pull_ptr jp = json_begin_string("[[1], [2], [3], [4], [5], [6], [7], [8]]");
|
||||
json_object_ptr tree = json_read_tree(jp);
|
||||
|
||||
REQUIRE(tree != nullptr);
|
||||
REQUIRE(tree->type == JSON_ARRAY);
|
||||
REQUIRE(tree->array().size() == 8);
|
||||
|
||||
json_free(tree->array()[0].get());
|
||||
|
||||
// Every survivor keeps its identity, in order, and nothing is aliased.
|
||||
REQUIRE(tree->array().size() == 7);
|
||||
for (size_t i = 0; i < tree->array().size(); i++) {
|
||||
json_object *e = tree->array()[i].get();
|
||||
REQUIRE(e->type == JSON_ARRAY);
|
||||
REQUIRE(e->array().size() == 1);
|
||||
REQUIRE(e->array()[0]->number() == (double) (i + 2));
|
||||
|
||||
if (i + 1 < tree->array().size()) {
|
||||
REQUIRE(e != tree->array()[i + 1].get());
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// The mirror of the value case above.
|
||||
TEST_CASE("json_free of a hash key, then of both halves", "[jsonpull][ownership]") {
|
||||
json_pull_ptr jp = json_begin_string(R"({"a": 1, "b": 2, "c": 3})");
|
||||
json_object_ptr tree = json_read_tree(jp);
|
||||
|
||||
REQUIRE(tree != nullptr);
|
||||
REQUIRE(tree->entries().size() == 3);
|
||||
|
||||
// Free the key of the middle pair. The entry stays, with a null key,
|
||||
// and its value is still reachable positionally.
|
||||
json_free(tree->entries()[1].key.get());
|
||||
|
||||
REQUIRE(tree->entries().size() == 3);
|
||||
REQUIRE(tree->entries()[1].key->type == JSON_NULL);
|
||||
REQUIRE(tree->entries()[1].value->number() == 2);
|
||||
|
||||
// The neighbours are untouched, and the now-keyless pair is no longer
|
||||
// findable by name.
|
||||
REQUIRE(json_hash_get(tree, "b") == nullptr);
|
||||
REQUIRE(json_hash_get(tree, "a")->number() == 1);
|
||||
REQUIRE(json_hash_get(tree, "c")->number() == 3);
|
||||
|
||||
// Freeing the other half too retires the whole entry.
|
||||
json_free(tree->entries()[1].value.get());
|
||||
|
||||
REQUIRE(tree->entries().size() == 2);
|
||||
REQUIRE(json_hash_get(tree, "a")->number() == 1);
|
||||
REQUIRE(json_hash_get(tree, "c")->number() == 3);
|
||||
}
|
||||
|
||||
// What the filter loaders and -L / -E do. Each detached tree has to survive
|
||||
// the next json_read_tree call and the parser's destruction.
|
||||
TEST_CASE("repeated json_read_tree on a line-delimited stream", "[jsonpull][ownership]") {
|
||||
json_pull_ptr jp = json_begin_string("{\"n\": 1}\n{\"n\": 2}\n{\"n\": 3}\n");
|
||||
|
||||
std::vector<json_object_ptr> trees;
|
||||
for (int i = 0; i < 3; i++) {
|
||||
json_object_ptr t = json_read_tree(jp);
|
||||
REQUIRE(t != nullptr);
|
||||
REQUIRE(t->type == JSON_HASH);
|
||||
// Reading the next tree must not disturb the ones already taken.
|
||||
REQUIRE(json_hash_get(t, "n")->number() == i + 1);
|
||||
trees.push_back(std::move(t));
|
||||
}
|
||||
|
||||
REQUIRE(json_read_tree(jp) == nullptr);
|
||||
|
||||
// All three outlive the parser they came from.
|
||||
jp.reset();
|
||||
for (int i = 0; i < 3; i++) {
|
||||
REQUIRE(trees[i]->parser == nullptr);
|
||||
REQUIRE(json_hash_get(trees[i], "n")->number() == i + 1);
|
||||
}
|
||||
}
|
||||
|
||||
// What json_context() prints on the error paths: a hash whose last key has no
|
||||
// value yet renders that slot as "...".
|
||||
TEST_CASE("json_stringify of a partially-parsed tree", "[jsonpull][stringify]") {
|
||||
json_pull_ptr jp = json_begin_string("{\"a\": [1, 2], \"b\":");
|
||||
|
||||
// Read until the parser runs out of input mid-hash.
|
||||
while (json_read(jp) != nullptr) {
|
||||
;
|
||||
}
|
||||
REQUIRE(jp->error != nullptr);
|
||||
REQUIRE(jp->root != nullptr);
|
||||
|
||||
std::string s = json_stringify(jp->root.get());
|
||||
REQUIRE(s == "{\"a\":[1,2],\"b\":...}");
|
||||
}
|
||||
|
||||
// Values are std::string now, so an embedded NUL is legal and stringify has to
|
||||
// walk past it rather than stop the way a c_str() loop would.
|
||||
TEST_CASE("json_stringify keeps text after an embedded NUL", "[jsonpull][stringify]") {
|
||||
json_pull_ptr jp = json_begin_string("\"a\\u0000b\"");
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
REQUIRE(o != nullptr);
|
||||
REQUIRE(o->type == JSON_STRING);
|
||||
REQUIRE(o->string().size() == 3);
|
||||
|
||||
std::string s = json_stringify(o.get());
|
||||
REQUIRE(s == "\"a\\u0000b\"");
|
||||
}
|
||||
|
||||
// U+FFFF used to fall through the `< 0xFFFF` test into the four-byte branch
|
||||
// and come out as the overlong F0 8F BF BF, which check_utf8 does not catch.
|
||||
TEST_CASE("jsonpull encodes U+FFFF as three bytes", "[jsonpull][utf8]") {
|
||||
json_pull_ptr jp = json_begin_string("\"a\\uFFFFb\"");
|
||||
json_object_ptr o = json_read_tree(jp);
|
||||
|
||||
REQUIRE(jp->error == nullptr);
|
||||
REQUIRE(o != nullptr);
|
||||
REQUIRE(o->type == JSON_STRING);
|
||||
|
||||
REQUIRE(o->string() ==
|
||||
"a\xEF\xBF\xBF"
|
||||
"b");
|
||||
REQUIRE(o->string() !=
|
||||
"a\xF0\x8F\xBF\xBF"
|
||||
"b");
|
||||
|
||||
// The boundary below it, and a genuine supplementary code point built
|
||||
// from a surrogate pair, both keep their existing encodings.
|
||||
json_pull_ptr jp2 = json_begin_string("\"\\uFFFE\"");
|
||||
json_object_ptr o2 = json_read_tree(jp2);
|
||||
REQUIRE(o2 != nullptr);
|
||||
REQUIRE(o2->string() == "\xEF\xBF\xBE");
|
||||
|
||||
json_pull_ptr jp3 = json_begin_string("\"\\uD83D\\uDC00\"");
|
||||
json_object_ptr o3 = json_read_tree(jp3);
|
||||
REQUIRE(o3 != nullptr);
|
||||
REQUIRE(o3->string() == "\xF0\x9F\x90\x80");
|
||||
}
|
||||
|
||||
TEST_CASE("Polygon cleaning drops a hole that no ring can parent", "[wagyu]") {
|
||||
// Two mutually reversed self-intersecting rings whose union leaves a hole
|
||||
// that wagyu's topology correction cannot assign to any surviving parent
|
||||
// ring (found by fuzzing; same failure as mapbox/tippecanoe#761). Without
|
||||
// the fix in mapbox/geometry/wagyu/topology_correction.hpp, this exits
|
||||
// through the "Could not properly place hole to a parent." handler in
|
||||
// clean_or_clip_poly instead of returning.
|
||||
static const std::vector<std::vector<std::pair<long long, long long>>> rings = {
|
||||
{{0, 5}, {5, 4}, {5, 1}, {4, 4}, {4, 2}, {7, 1}, {0, 5}},
|
||||
{{0, 5}, {7, 1}, {4, 2}, {4, 4}, {5, 1}, {5, 4}, {0, 0}, {0, 5}},
|
||||
};
|
||||
|
||||
drawvec geom;
|
||||
for (auto const &ring : rings) {
|
||||
for (size_t i = 0; i < ring.size(); i++) {
|
||||
geom.push_back(draw(i == 0 ? VT_MOVETO : VT_LINETO, ring[i].first, ring[i].second));
|
||||
}
|
||||
}
|
||||
|
||||
drawvec out = clean_or_clip_poly(geom, 0, 0, false, false);
|
||||
|
||||
// The regression signal is getting here at all: without the fix,
|
||||
// clean_or_clip_poly exits the process from its wagyu error handler.
|
||||
SUCCEED("clean_or_clip_poly returned");
|
||||
|
||||
// Anything that survives must be sanely wound: first ring positive.
|
||||
if (out.size() > 0) {
|
||||
size_t j = 1;
|
||||
while (j < out.size() && out[j].op == VT_LINETO) j++;
|
||||
REQUIRE(get_area(out, 0, j) > 0);
|
||||
}
|
||||
}
|
||||
|
||||
@@ -0,0 +1,133 @@
|
||||
#include <string.h>
|
||||
#include <set>
|
||||
#include <string>
|
||||
#include "usage.hpp"
|
||||
|
||||
// Options are wrapped to fit within this many columns
|
||||
#define USAGE_WIDTH 80
|
||||
|
||||
// The indentation of the continuation lines of the option list
|
||||
#define USAGE_INDENT 8
|
||||
|
||||
std::string getopt_string(const struct option *long_options) {
|
||||
std::string getopt_str;
|
||||
|
||||
for (size_t lo = 0; long_options[lo].name != NULL; lo++) {
|
||||
if (long_options[lo].val > ' ') {
|
||||
getopt_str.push_back(long_options[lo].val);
|
||||
|
||||
if (long_options[lo].has_arg == required_argument) {
|
||||
getopt_str.push_back(':');
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return getopt_str;
|
||||
}
|
||||
|
||||
void strip_usage_headings(const struct option *long_options, struct option *real_long_options) {
|
||||
size_t out = 0;
|
||||
|
||||
for (size_t lo = 0; long_options[lo].name != NULL; lo++) {
|
||||
if (long_options[lo].val != 0) {
|
||||
real_long_options[out++] = long_options[lo];
|
||||
}
|
||||
}
|
||||
|
||||
real_long_options[out] = {0, 0, 0, 0};
|
||||
}
|
||||
|
||||
// The entry for `name` in the list of options that must be specified,
|
||||
// or NULL if it is an optional option
|
||||
static const struct usage_required_option *required_for(const char *name, const struct usage_required_option *required) {
|
||||
for (size_t i = 0; required != NULL && required[i].name != NULL; i++) {
|
||||
if (strcmp(required[i].name, name) == 0) {
|
||||
return &required[i];
|
||||
}
|
||||
}
|
||||
|
||||
return NULL;
|
||||
}
|
||||
|
||||
// "--option", or "--option=placeholder" if the option takes an argument
|
||||
static std::string option_text(const struct option *opt, const struct usage_required_option *req) {
|
||||
std::string text = std::string("--") + opt->name;
|
||||
|
||||
if (opt->has_arg != no_argument) {
|
||||
text += "=";
|
||||
text += (req != NULL && req->placeholder != NULL) ? req->placeholder : "...";
|
||||
}
|
||||
|
||||
return text;
|
||||
}
|
||||
|
||||
// The alternatives that `req` belongs to, as "(--this=... | --that=...)"
|
||||
static std::string alternation_text(const struct option *long_options, const struct usage_required_option *required, int alternation) {
|
||||
std::string text;
|
||||
size_t found = 0;
|
||||
|
||||
for (size_t lo = 0; long_options[lo].name != NULL && long_options[lo].name[0] != '\0'; lo++) {
|
||||
const struct usage_required_option *req = required_for(long_options[lo].name, required);
|
||||
|
||||
if (req != NULL && req->alternation == alternation) {
|
||||
if (found++ > 0) {
|
||||
text += " | ";
|
||||
}
|
||||
|
||||
text += option_text(&long_options[lo], req);
|
||||
}
|
||||
}
|
||||
|
||||
if (found > 1) {
|
||||
text = "(" + text + ")";
|
||||
}
|
||||
|
||||
return text;
|
||||
}
|
||||
|
||||
void print_usage(FILE *out, const char *program, const char *const *forms,
|
||||
const struct option *long_options,
|
||||
const struct usage_required_option *required) {
|
||||
for (size_t f = 0; forms[f] != NULL; f++) {
|
||||
const char *lead = (f == 0) ? "Usage: " : "\n or: ";
|
||||
fprintf(out, "%s%s %s", lead, program, forms[f]);
|
||||
}
|
||||
|
||||
// whatever the forms took up, the option list starts on a line of its own
|
||||
size_t width = USAGE_WIDTH;
|
||||
std::set<int> alternations_listed;
|
||||
|
||||
for (size_t lo = 0; long_options[lo].name != NULL && long_options[lo].name[0] != '\0'; lo++) {
|
||||
if (long_options[lo].val == 0) {
|
||||
fprintf(out, "\n %s\n%*s", long_options[lo].name, USAGE_INDENT, "");
|
||||
width = USAGE_INDENT;
|
||||
continue;
|
||||
}
|
||||
|
||||
const struct usage_required_option *req = required_for(long_options[lo].name, required);
|
||||
std::string text;
|
||||
|
||||
if (req == NULL) {
|
||||
text = "[" + option_text(&long_options[lo], NULL) + "]";
|
||||
} else if (req->alternation == 0) {
|
||||
text = option_text(&long_options[lo], req);
|
||||
} else {
|
||||
if (alternations_listed.count(req->alternation) != 0) {
|
||||
continue; // already listed with the first of its alternatives
|
||||
}
|
||||
alternations_listed.insert(req->alternation);
|
||||
|
||||
text = alternation_text(long_options, required, req->alternation);
|
||||
}
|
||||
|
||||
if (width + 1 + text.size() >= USAGE_WIDTH) {
|
||||
fprintf(out, "\n%*s", USAGE_INDENT, "");
|
||||
width = USAGE_INDENT;
|
||||
}
|
||||
|
||||
fprintf(out, " %s", text.c_str());
|
||||
width += 1 + text.size();
|
||||
}
|
||||
|
||||
fprintf(out, "\n");
|
||||
}
|
||||
@@ -0,0 +1,52 @@
|
||||
#ifndef USAGE_HPP
|
||||
#define USAGE_HPP
|
||||
|
||||
#include <stdio.h>
|
||||
#include <getopt.h>
|
||||
#include <string>
|
||||
|
||||
// An option that must be specified rather than being optional, and the
|
||||
// placeholder to show for its argument in the usage message.
|
||||
//
|
||||
// Options that share the same non-zero `alternation` are alternatives to
|
||||
// each other: one of them must be specified, but not more than one, and
|
||||
// they are listed together as `(--this=... | --that=...)`.
|
||||
struct usage_required_option {
|
||||
const char *name;
|
||||
const char *placeholder;
|
||||
int alternation;
|
||||
};
|
||||
|
||||
// Returns the short option string to pass to getopt_long() for the
|
||||
// options in `long_options`, so that the two can't disagree about
|
||||
// which short options exist or take arguments.
|
||||
std::string getopt_string(const struct option *long_options);
|
||||
|
||||
// Copies `long_options` to `real_long_options`, leaving out the headings
|
||||
// of the usage message, which are not real options and so must not be
|
||||
// passed on to getopt_long(). The destination must be at least as large
|
||||
// as the source.
|
||||
void strip_usage_headings(const struct option *long_options, struct option *real_long_options);
|
||||
|
||||
// Prints a usage message for `program` to `out`:
|
||||
//
|
||||
// Usage: program forms[0]
|
||||
// or: program forms[1]
|
||||
// [--some-option] [--another-option=...] ...
|
||||
//
|
||||
// where `forms` is a NULL-terminated list of the ways the non-option
|
||||
// arguments can be given, and the list of options is derived from
|
||||
// `long_options`, the same table that is passed to getopt_long(), so that
|
||||
// the message stays in sync with the options that are really accepted.
|
||||
//
|
||||
// Options named in `required` (a list terminated by a NULL name, or NULL
|
||||
// if there are none) are shown without brackets, using the placeholder
|
||||
// given there for their argument, and grouped with any alternatives to
|
||||
// them. An entry in `long_options` with no `val` is printed as a heading
|
||||
// for the options that follow it, and an entry with an empty name ends
|
||||
// the listing, hiding any options after it.
|
||||
void print_usage(FILE *out, const char *program, const char *const *forms,
|
||||
const struct option *long_options,
|
||||
const struct usage_required_option *required);
|
||||
|
||||
#endif
|
||||
+1
-1
@@ -1,6 +1,6 @@
|
||||
#ifndef VERSION_HPP
|
||||
#define VERSION_HPP
|
||||
|
||||
#define VERSION "v2.74.0"
|
||||
#define VERSION "v2.82.0"
|
||||
|
||||
#endif
|
||||
|
||||
Reference in New Issue
Block a user