mirror of
https://github.com/felt/tippecanoe.git
synced 2026-10-02 08:25:40 +02:00
Merge remote-tracking branch 'origin/main' into distiguish-duplicates-merge
This commit is contained in:
 Erica Fischer
-110
@@ -1,110 +0,0 @@
|
||||
language: node_js
|
||||
node_js:
|
||||
- "6"
|
||||
|
||||
sudo: false
|
||||
|
||||
matrix:
|
||||
include:
|
||||
# test on docker+centos7
|
||||
- os: linux
|
||||
compiler: clang
|
||||
services:
|
||||
- docker
|
||||
sudo: true
|
||||
dist: trusty
|
||||
env: DOCKERFILE=Dockerfile.centos7
|
||||
before_install: []
|
||||
install:
|
||||
- docker build -t tippecanoe-image -f ${DOCKERFILE} .
|
||||
script:
|
||||
- docker run -it tippecanoe-image
|
||||
# test on docker+ubuntu
|
||||
- os: linux
|
||||
compiler: clang
|
||||
services:
|
||||
- docker
|
||||
sudo: true
|
||||
dist: trusty
|
||||
env: DOCKERFILE=Dockerfile
|
||||
before_install: []
|
||||
install:
|
||||
- docker build -t tippecanoe-image -f ${DOCKERFILE} .
|
||||
script:
|
||||
- docker run -it tippecanoe-image
|
||||
# debug+integer-santizer build
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Debug CC="clang-3.8" CXX="clang++-3.8" CXXFLAGS="-fsanitize=integer" CFLAGS="-fsanitize=integer" LDFLAGS="-fsanitize=integer"
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# debug+leak+address-sanitizer build
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Debug ASAN_OPTIONS=detect_leaks=1 CC="clang-3.8" CXX="clang++-3.8" CXXFLAGS="-fsanitize=address,undefined" CFLAGS="-fsanitize=address,undefined" LDFLAGS="-fsanitize=address,undefined" FEWER=true
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# coverage+debug build
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Debug CC="clang-3.8" CXX="clang++-3.8" CXXFLAGS="--coverage" CFLAGS="--coverage" LDFLAGS="--coverage"
|
||||
after_script:
|
||||
- mason install llvm-cov 3.9.1
|
||||
- mason link llvm-cov 3.9.1
|
||||
- which llvm-cov
|
||||
- curl -S -f https://codecov.io/bash -o codecov
|
||||
- chmod +x codecov
|
||||
- ./codecov -x "llvm-cov gcov" -Z
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# release+linux+g++
|
||||
- os: linux
|
||||
compiler: gcc
|
||||
env: BUILDTYPE=Release CC="gcc-4.9" CXX="g++-4.9"
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test']
|
||||
packages: [ 'g++-4.9' ]
|
||||
# release+linux+clang++
|
||||
- os: linux
|
||||
compiler: clang
|
||||
env: CLANG_VERSION='3.8.0' BUILDTYPE=Release CC="clang-3.8" CXX="clang++-3.8"
|
||||
addons:
|
||||
apt:
|
||||
sources: ['ubuntu-toolchain-r-test' ]
|
||||
packages: [ 'libstdc++6','libstdc++-5-dev' ]
|
||||
# release+osx
|
||||
- os: osx
|
||||
compiler: clang
|
||||
env: BUILDTYPE=Release
|
||||
# debug+osx
|
||||
- os: osx
|
||||
compiler: clang
|
||||
env: BUILDTYPE=Debug
|
||||
|
||||
before_install:
|
||||
- DEPS_DIR="${TRAVIS_BUILD_DIR}/deps"
|
||||
- export PATH=${DEPS_DIR}/bin:${PATH} && mkdir -p ${DEPS_DIR}
|
||||
- |
|
||||
if [[ ${CLANG_VERSION:-false} != false ]]; then
|
||||
export CCOMPILER='clang'
|
||||
export CXXCOMPILER='clang++'
|
||||
CLANG_URL="https://mason-binaries.s3.amazonaws.com/${TRAVIS_OS_NAME}-x86_64/clang/${CLANG_VERSION}.tar.gz"
|
||||
travis_retry wget --quiet -O - ${CLANG_URL} | tar --strip-components=1 -xz -C ${DEPS_DIR}
|
||||
fi
|
||||
|
||||
install:
|
||||
- BUILDTYPE=${BUILDTYPE} make -j
|
||||
|
||||
script:
|
||||
- npm install geobuf
|
||||
- if [ -n "${FEWER}" ]; then
|
||||
BUILDTYPE=${BUILDTYPE} make fewer-tests; else
|
||||
BUILDTYPE=${BUILDTYPE} make test geobuf-test;
|
||||
fi
|
||||
+10
-1
@@ -1,7 +1,16 @@
|
||||
# 2.79.0
|
||||
# 2.81.0
|
||||
|
||||
* Add --distinguish-duplicates option
|
||||
|
||||
# 2.80.0
|
||||
|
||||
* Remove undocumented command-line options
|
||||
|
||||
# 2.79.0
|
||||
|
||||
* When deduplicating features by ID in tippecanoe-overzoom, be careful
|
||||
to track even features that have been clipped away.
|
||||
|
||||
# 2.78.0
|
||||
|
||||
* Fix potential infinite loops in as-needed dropping and coalescing.
|
||||
|
||||
-20
@@ -1,20 +0,0 @@
|
||||
FROM ubuntu:22.04 AS tippecanoe-builder
|
||||
|
||||
RUN apt-get update \
|
||||
&& apt-get -y install make gcc g++ libsqlite3-dev zlib1g-dev
|
||||
|
||||
COPY . /tmp/tippecanoe-src
|
||||
WORKDIR /tmp/tippecanoe-src
|
||||
|
||||
RUN make
|
||||
|
||||
CMD make test
|
||||
|
||||
# Using multistage build reduces the docker image size by alot by only copying the needed binaries
|
||||
FROM ubuntu:22.04
|
||||
RUN apt-get update \
|
||||
&& apt-get -y install libsqlite3-0 \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
COPY --from=tippecanoe-builder /tmp/tippecanoe-src/tippecanoe* /usr/local/bin/
|
||||
COPY --from=tippecanoe-builder /tmp/tippecanoe-src/tile-join /usr/local/bin/
|
||||
WORKDIR /app
|
||||
@@ -1,15 +0,0 @@
|
||||
FROM centos:centos8
|
||||
|
||||
RUN yum install -y make sqlite-devel zlib-devel bash git gcc-c++
|
||||
|
||||
# Create a directory and copy in all files
|
||||
RUN mkdir -p /tmp/tippecanoe-src
|
||||
WORKDIR /tmp/tippecanoe-src
|
||||
COPY . /tmp/tippecanoe-src
|
||||
|
||||
# Build tippecanoe
|
||||
RUN make \
|
||||
&& make install
|
||||
|
||||
# Run the tests
|
||||
CMD make test
|
||||
+5
-5
@@ -1,19 +1,19 @@
|
||||
## [Visualizing a Month of Lightning](http://rousseau.io/2015/03/23/visualizing-a-month-of-lightning) by Jordan Rousseau
|
||||
## [Visualizing a Month of Lightning](https://medium.com/@jvrousseau/visualizing-a-month-of-lightning-8ab63d040d8c) by Jordan Rousseau
|
||||
|
||||

|
||||
|
||||
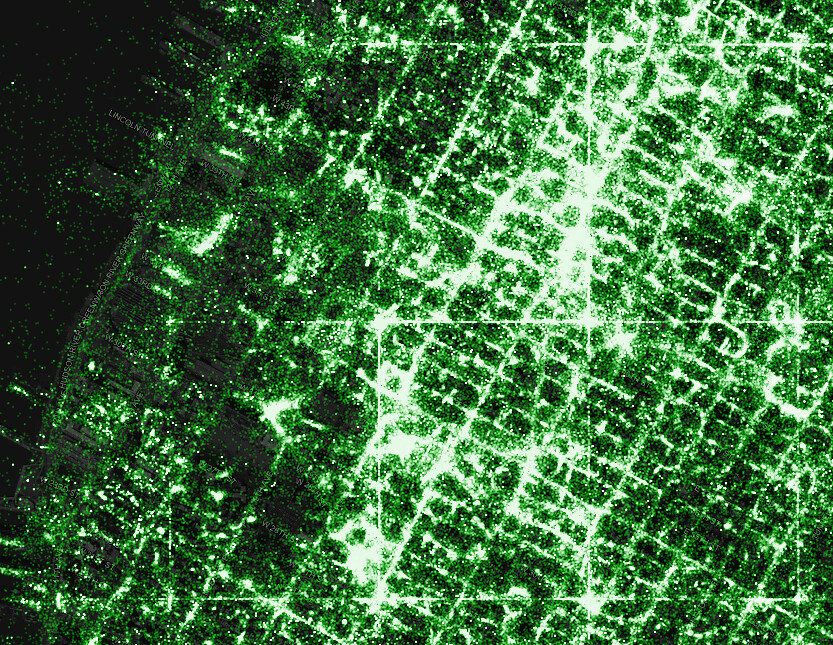
## [Making the most detailed tweet map ever](https://www.mapbox.com/blog/twitter-map-every-tweet/) by Eric Fischer
|
||||
## [Making the most detailed tweet map ever](https://web.archive.org/web/20161220144946/https://www.mapbox.com/blog/twitter-map-every-tweet/) by Eric Fischer
|
||||
|
||||
|
||||
|
||||
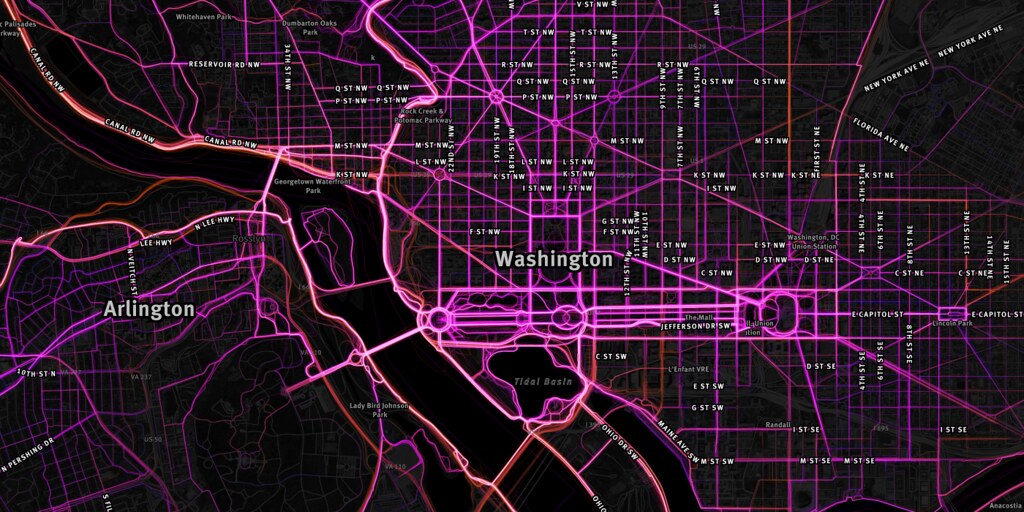
## [Superpowering Runkeeper's 1.5 million walks, runs, and bike rides](https://www.mapbox.com/blog/runkeeper-million-routes/)
|
||||
## [Superpowering Runkeeper's 1.5 million walks, runs, and bike rides](https://web.archive.org/web/20161219225305/https://www.mapbox.com/blog/runkeeper-million-routes/)
|
||||
|
||||
|
||||
|
||||
## [The Geotaggers' World Atlas](https://www.mapbox.com/blog/geotaggers-world-atlas/) by Eric Fischer
|
||||
## [The Geotaggers' World Atlas](https://web.archive.org/web/20170319084321/https://www.mapbox.com/blog/geotaggers-world-atlas/) by Eric Fischer
|
||||
|
||||

|
||||
|
||||
## [Atmospheric River](https://www.mapbox.com/blog/atmospheric-river/)
|
||||
## [Atmospheric River](https://web.archive.org/web/20161011171030/https://www.mapbox.com/blog/atmospheric-river/)
|
||||
|
||||

|
||||
|
||||
@@ -97,7 +97,7 @@ indent:
|
||||
TESTS = $(wildcard tests/*/out/*.json)
|
||||
SPACE = $(NULL) $(NULL)
|
||||
|
||||
test: tippecanoe tippecanoe-decode $(addsuffix .check,$(TESTS)) raw-tiles-test parallel-test pbf-test join-test enumerate-test decode-test join-filter-test unit json-tool-test allow-existing-test csv-test layer-json-test pmtiles-test decode-pmtiles-test overzoom-test accumulate-test
|
||||
test: tippecanoe tippecanoe-decode $(addsuffix .check,$(TESTS)) raw-tiles-test parallel-test pbf-test join-test enumerate-test decode-test join-filter-test unit json-tool-test allow-existing-test csv-test layer-json-test pmtiles-test decode-pmtiles-test overzoom-test flatgeobuf-test
|
||||
./unit
|
||||
|
||||
suffixes = json json.gz
|
||||
@@ -322,7 +322,7 @@ overzoom-test: tippecanoe-overzoom
|
||||
# Filtering
|
||||
# 243 features in the source tile tests/pbf/0-0-0-pop.pbf
|
||||
# 27 of them match the filter and are retained
|
||||
./tippecanoe-overzoom -y NAME -j'{"*":["SCALERANK","eq",0]}' -o tests/pbf/0-0-0-pop-expr.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-overzoom -y NAME -j'{"*":["==","SCALERANK",0]}' -o tests/pbf/0-0-0-pop-expr.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-expr.pbf 0 0 0 > tests/pbf/0-0-0-pop-expr.pbf.json.check
|
||||
cmp tests/pbf/0-0-0-pop-expr.pbf.json.check tests/pbf/0-0-0-pop-expr.pbf.json
|
||||
rm tests/pbf/0-0-0-pop-expr.pbf tests/pbf/0-0-0-pop-expr.pbf.json.check
|
||||
@@ -334,13 +334,13 @@ overzoom-test: tippecanoe-overzoom
|
||||
# Filtering with multiplier
|
||||
# 243 features in the source tile tests/pbf/0-0-0-pop.pbf
|
||||
# 8 features survive into the output, from 9 clusters of 30
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -j'{"*":["SCALERANK","eq",0]}' -m -o tests/pbf/0-0-0-filter-mult.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -j'{"*":["==","SCALERANK",0]}' -m -o tests/pbf/0-0-0-filter-mult.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-filter-mult.pbf 0 0 0 > tests/pbf/0-0-0-filter-mult.pbf.json.check
|
||||
cmp tests/pbf/0-0-0-filter-mult.pbf.json.check tests/pbf/0-0-0-filter-mult.pbf.json
|
||||
rm tests/pbf/0-0-0-filter-mult.pbf tests/pbf/0-0-0-filter-mult.pbf.json.check
|
||||
# Filtering with multiplier and preserve-input-order
|
||||
# 243 features in the source tile tests/pbf/0-0-0-pop.pbf
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -j'{"*":["NAME","cn","e"]}' -m --preserve-input-order -o tests/pbf/0-0-0-filter-mult-order.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-overzoom -y NAME -y SCALERANK -y LATITUDE -j'{"*":[">","LATITUDE",40]}' -m --preserve-input-order -o tests/pbf/0-0-0-filter-mult-order.pbf tests/pbf/0-0-0-pop.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-filter-mult-order.pbf 0 0 0 > tests/pbf/0-0-0-filter-mult-order.pbf.json.check
|
||||
cmp tests/pbf/0-0-0-filter-mult-order.pbf.json.check tests/pbf/0-0-0-filter-mult-order.pbf.json
|
||||
rm tests/pbf/0-0-0-filter-mult-order.pbf tests/pbf/0-0-0-filter-mult-order.pbf.json.check
|
||||
@@ -352,105 +352,19 @@ overzoom-test: tippecanoe-overzoom
|
||||
./tippecanoe-decode tests/muni/out/out.dir/000.pbf 0 0 0 > tests/muni/out/out.dir/overzoomed.json
|
||||
cmp tests/muni/out/out.dir/overzoomed.json tests/muni/out/out.dir/direct.json
|
||||
rm -rf tests/muni/out/out.dir tests/muni/out/out.mbtiles tests/muni/out/out.dir/overzoomed.json tests/muni/out/out.dir/direct.json
|
||||
# Test filter with null attribute
|
||||
./tippecanoe-overzoom -j '{"*":["name","ni",[1,5,6,9]]}' -o tests/pbf/12-2145-1391-filter1.pbf tests/pbf/12-2145-1391.pbf 12/2145/1391 12/2145/1391
|
||||
./tippecanoe-decode tests/pbf/12-2145-1391-filter1.pbf 12 2145 1391 > tests/pbf/12-2145-1391-filter1.pbf.json.check
|
||||
cmp tests/pbf/12-2145-1391-filter1.pbf.json.check tests/pbf/12-2145-1391-filter1.pbf.json
|
||||
rm tests/pbf/12-2145-1391-filter1.pbf.json.check tests/pbf/12-2145-1391-filter1.pbf
|
||||
# Test filter with null attribute in "ni" list
|
||||
./tippecanoe-overzoom -j '{"*":["name","ni",[1,5,6,9,null]]}' -o tests/pbf/12-2145-1391-filter2.pbf tests/pbf/12-2145-1391.pbf 12/2145/1391 12/2145/1391
|
||||
./tippecanoe-decode tests/pbf/12-2145-1391-filter2.pbf 12 2145 1391 > tests/pbf/12-2145-1391-filter2.pbf.json.check
|
||||
cmp tests/pbf/12-2145-1391-filter2.pbf.json.check tests/pbf/12-2145-1391-filter2.pbf.json
|
||||
rm tests/pbf/12-2145-1391-filter2.pbf.json.check tests/pbf/12-2145-1391-filter2.pbf
|
||||
# Tiny polygon reduction
|
||||
./tippecanoe-overzoom --line-simplification=5 --tiny-polygon-size=50 -o tests/pbf/countries-0-0-0.pbf.out tests/pbf/countries-0-0-0.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/countries-0-0-0.pbf.out 0 0 0 > tests/pbf/countries-0-0-0.pbf.out.json.check
|
||||
cmp tests/pbf/countries-0-0-0.pbf.out.json.check tests/pbf/countries-0-0-0.pbf.out.json
|
||||
rm tests/pbf/countries-0-0-0.pbf.out tests/pbf/countries-0-0-0.pbf.out.json.check
|
||||
# Clipping to bounding box
|
||||
./tippecanoe-overzoom --clip-bounding-box 5,5,25.7,50 -o tests/pbf/countries-0-0-0-clip.pbf.out tests/pbf/countries-0-0-0.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/countries-0-0-0-clip.pbf.out 0 0 0 > tests/pbf/countries-0-0-0-clip.pbf.out.json.check
|
||||
cmp tests/pbf/countries-0-0-0-clip.pbf.out.json.check tests/pbf/countries-0-0-0-clip.pbf.out.json
|
||||
rm tests/pbf/countries-0-0-0-clip.pbf.out tests/pbf/countries-0-0-0-clip.pbf.out.json.check
|
||||
# Binning
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791.pbf.out --assign-to-bins tests/pbf/sf-zips.json tests/pbf/muni-11-327-791.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791.pbf.out 11 327 791 > tests/pbf/bin-11-327-791.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791.pbf.out.json.check tests/pbf/bin-11-327-791.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791.pbf.out.json.check tests/pbf/bin-11-327-791.pbf.out
|
||||
# Binning by id
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791-ids.pbf.out --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids.pbf.out.json.check tests/pbf/bin-11-327-791-ids.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids.pbf.out.json.check tests/pbf/bin-11-327-791-ids.pbf.out
|
||||
# Binning by id, clipping by polygon
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791-ids-clip.pbf.out --clip-polygon='{"coordinates":[[[-122.4527379,37.8128815],[-122.4598853,37.7834743],[-122.4280914,37.7959397],[-122.4527379,37.8128815]]],"type":"Polygon"}' --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids-clip.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out
|
||||
# Binning by id, clipping by polygon from file
|
||||
./tippecanoe-overzoom -o tests/pbf/bin-11-327-791-ids-clip.pbf.out --clip-polygon-file=tests/pbf/clip-poly.json --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids-clip.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids-clip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-clip.pbf.out
|
||||
# Binning by id, attribute stripping
|
||||
# Note that it still works even if we exclude the ID that we are binning by
|
||||
./tippecanoe-overzoom -yZCTA5CE10 -ytippecanoe:count -o tests/pbf/bin-11-327-791-ids-zip.pbf.out --assign-to-bins tests/pbf/sf-zips.json --bin-by-id-list bin-ids tests/pbf/yearbuilt.pbf 11/327/791 11/327/791
|
||||
./tippecanoe-decode tests/pbf/bin-11-327-791-ids-zip.pbf.out 11 327 791 > tests/pbf/bin-11-327-791-ids-zip.pbf.out.json.check
|
||||
cmp tests/pbf/bin-11-327-791-ids-zip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-zip.pbf.out.json
|
||||
rm tests/pbf/bin-11-327-791-ids-zip.pbf.out.json.check tests/pbf/bin-11-327-791-ids-zip.pbf.out
|
||||
# Binning with longitude wraparound problems
|
||||
./tippecanoe-overzoom -o tests/pbf/0-0-0-pop-2-0-1.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-2-0-1.geojson tests/pbf/0-0-0.pbf 2/0/1 2/0/1
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-2-0-1.pbf.out 2 0 1 > tests/pbf/0-0-0-pop-2-0-1.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-2-0-1.pbf.out.json.check tests/pbf/0-0-0-pop-2-0-1.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-2-0-1.pbf.out tests/pbf/0-0-0-pop-2-0-1.pbf.out.json.check
|
||||
./tippecanoe-overzoom -o tests/pbf/0-0-0-pop-1-1-0.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-1-1-0.geojson tests/pbf/0-0-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-1-1-0.pbf.out 1 1 0 > tests/pbf/0-0-0-pop-1-1-0.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-1-1-0.pbf.out.json.check tests/pbf/0-0-0-pop-1-1-0.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-1-1-0.pbf.out tests/pbf/0-0-0-pop-1-1-0.pbf.out.json.check
|
||||
./tippecanoe-overzoom -o tests/pbf/0-0-0-pop-0-0-0.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-0-0-0.geojson tests/pbf/0-0-0.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-0-0-0.pbf.out 0 0 0 > tests/pbf/0-0-0-pop-0-0-0.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-0-0-0.pbf.out.json.check tests/pbf/0-0-0-pop-0-0-0.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-0-0-0.pbf.out tests/pbf/0-0-0-pop-0-0-0.pbf.out.json.check
|
||||
# Binning, clipping to bounding box
|
||||
./tippecanoe-overzoom --clip-bounding-box 88,67.5,138,78 -o tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out --accumulate-numeric-attributes=tippecanoe --assign-to-bins tests/pbf/h3-1-1-0.geojson tests/pbf/0-0-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out 1 1 0 > tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json.check
|
||||
cmp tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json.check tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json
|
||||
rm tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out tests/pbf/0-0-0-pop-1-1-0-clip.pbf.out.json.check
|
||||
# Verify fix for crash
|
||||
./tippecanoe-overzoom '-o' tests/10188-crash/out.pbf '-t' '3/2/2' '--assign-to-bins' 'tests/10188-crash/bins.json' '--bin-by-id-list' 'felt:bin_features' '-b5' 'tests/10188-crash/2-0-0.pbf' '2/0/0'
|
||||
rm tests/10188-crash/out.pbf
|
||||
# Polygon clipping
|
||||
./tippecanoe-overzoom -o tests/pbf/countries-1-1-0-clip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/countries-1-1-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/countries-1-1-0-clip.pbf 1 1 0 > tests/pbf/countries-1-1-0-clip.json.check
|
||||
cmp tests/pbf/countries-1-1-0-clip.json.check tests/pbf/countries-1-1-0-clip.json
|
||||
rm tests/pbf/countries-1-1-0-clip.pbf tests/pbf/countries-1-1-0-clip.json.check
|
||||
# LineString clipping
|
||||
./tippecanoe-overzoom -o tests/pbf/roads-1-1-0-clip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/roads-1-1-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/roads-1-1-0-clip.pbf 1 1 0 > tests/pbf/roads-1-1-0-clip.json.check
|
||||
cmp tests/pbf/roads-1-1-0-clip.json.check tests/pbf/roads-1-1-0-clip.json
|
||||
rm tests/pbf/roads-1-1-0-clip.pbf tests/pbf/roads-1-1-0-clip.json.check
|
||||
# Point clipping
|
||||
./tippecanoe-overzoom -o tests/pbf/places-1-1-0-clip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/places-1-1-0.pbf 1/1/0 1/1/0
|
||||
./tippecanoe-decode tests/pbf/places-1-1-0-clip.pbf 1 1 0 > tests/pbf/places-1-1-0-clip.json.check
|
||||
cmp tests/pbf/places-1-1-0-clip.json.check tests/pbf/places-1-1-0-clip.json
|
||||
rm tests/pbf/places-1-1-0-clip.pbf tests/pbf/places-1-1-0-clip.json.check
|
||||
# Polygon clipping, with excessively large clip region
|
||||
./tippecanoe-overzoom -b10 -o tests/pbf/countries-8-135-86-bigclip.pbf --clip-polygon "`cat tests/pbf/region.json`" tests/pbf/countries-1-1-0.pbf 1/1/0 8/135/86
|
||||
./tippecanoe-decode tests/pbf/countries-8-135-86-bigclip.pbf 8 135 86 > tests/pbf/countries-8-135-86-bigclip.json.check
|
||||
cmp tests/pbf/countries-8-135-86-bigclip.json.check tests/pbf/countries-8-135-86-bigclip.json
|
||||
rm tests/pbf/countries-8-135-86-bigclip.pbf tests/pbf/countries-8-135-86-bigclip.json.check
|
||||
# Clip region that does not intersect with the tile
|
||||
./tippecanoe-overzoom -o tests/pbf/squirrels-13-2413-3077-clip.pbf --clip-polygon-file tests/pbf/squirrels-clip.json tests/pbf/squirrels-13-2413-3077.pbf 13/2413/3077 13/2413/3077
|
||||
cmp tests/pbf/squirrels-13-2413-3077-clip.pbf /dev/null # clipped away
|
||||
rm tests/pbf/squirrels-13-2413-3077-clip.pbf
|
||||
# Deduplication by feature ID
|
||||
./tippecanoe -z0 -f -e tests/pbf/1.json.dir -l layer tests/pbf/1.json
|
||||
./tippecanoe -z0 -f -e tests/pbf/2.json.dir -l layer tests/pbf/2.json
|
||||
./tippecanoe-overzoom -o tests/pbf/merged-nodedup.pbf -t 0/0/0 tests/pbf/1.json.dir/0/0/0.pbf 0/0/0 tests/pbf/2.json.dir/0/0/0.pbf 0/0/0
|
||||
./tippecanoe-decode tests/pbf/merged-nodedup.pbf 0 0 0 > tests/pbf/merged-nodedup.pbf.json.check
|
||||
./tippecanoe-overzoom -b0 -o tests/pbf/merged-nodedup.pbf -t 1/1/0 tests/pbf/1.json.dir/0/0/0.pbf 0/0/0 tests/pbf/2.json.dir/0/0/0.pbf 0/0/0
|
||||
./tippecanoe-decode tests/pbf/merged-nodedup.pbf 1 1 0 > tests/pbf/merged-nodedup.pbf.json.check
|
||||
cmp tests/pbf/merged-nodedup.pbf.json.check tests/pbf/merged-nodedup.pbf.json
|
||||
./tippecanoe-overzoom --deduplicate-by-id -o tests/pbf/merged-dedup.pbf -t 0/0/0 tests/pbf/1.json.dir/0/0/0.pbf 0/0/0 tests/pbf/2.json.dir/0/0/0.pbf 0/0/0
|
||||
./tippecanoe-decode tests/pbf/merged-dedup.pbf 0 0 0 > tests/pbf/merged-dedup.pbf.json.check
|
||||
./tippecanoe-overzoom -b0 --deduplicate-by-id -o tests/pbf/merged-dedup.pbf -t 1/1/0 tests/pbf/1.json.dir/0/0/0.pbf 0/0/0 tests/pbf/2.json.dir/0/0/0.pbf 0/0/0
|
||||
./tippecanoe-decode tests/pbf/merged-dedup.pbf 1 1 0 > tests/pbf/merged-dedup.pbf.json.check
|
||||
cmp tests/pbf/merged-dedup.pbf.json.check tests/pbf/merged-dedup.pbf.json
|
||||
rm -r tests/pbf/1.json.dir tests/pbf/2.json.dir tests/pbf/merged-nodedup.pbf tests/pbf/merged-nodedup.pbf.json.check tests/pbf/merged-dedup.pbf.json.check
|
||||
|
||||
@@ -588,145 +502,6 @@ join-test: tippecanoe tippecanoe-decode tile-join
|
||||
./tippecanoe-decode -x generator tests/ne_110m_ocean/join/joined.mbtiles > tests/ne_110m_ocean/join/joined.mbtiles.json.check
|
||||
cmp tests/ne_110m_ocean/join/joined.mbtiles.json.check tests/ne_110m_ocean/join/joined.mbtiles.json
|
||||
rm -f tests/ne_110m_ocean/join/ocean.mbtiles tests/ne_110m_ocean/join/countries.mbtiles tests/ne_110m_ocean/join/joined.mbtiles tests/ne_110m_ocean/join/joined.mbtiles.json.check
|
||||
#
|
||||
# Test sql join
|
||||
#
|
||||
./tile-join -i -f -o tests/join-sql/countries.pmtiles --join-sqlite tests/join-sql/countries.gpkg --join-table countries --join-tile-attribute ne10-admin0:name_en --join-table-expression 'lower(country)' tests/join-sql/bboxes.pmtiles
|
||||
./tippecanoe-decode -x generator tests/join-sql/countries.pmtiles > tests/join-sql/countries.pmtiles.json.check
|
||||
cmp tests/join-sql/countries.pmtiles.json.check tests/join-sql/countries.pmtiles.json
|
||||
rm -f tests/join-sql/countries.pmtiles tests/join-sql/countries.pmtiles.json.check
|
||||
#
|
||||
# Test sql join with limit
|
||||
#
|
||||
./tile-join --join-count-limit 3 -i -f -o tests/join-sql/countries-limit3.pmtiles --join-sqlite tests/join-sql/countries.gpkg --join-table countries --join-tile-attribute ne10-admin0:name_en --join-table-expression 'lower(country)' tests/join-sql/bboxes.pmtiles
|
||||
./tippecanoe-decode -x generator tests/join-sql/countries-limit3.pmtiles > tests/join-sql/countries-limit3.pmtiles.json.check
|
||||
cmp tests/join-sql/countries-limit3.pmtiles.json.check tests/join-sql/countries-limit3.pmtiles.json
|
||||
rm -f tests/join-sql/countries-limit3.pmtiles tests/join-sql/countries-limit3.pmtiles.json.check
|
||||
|
||||
accumulate-test:
|
||||
# there are 144 features with POP1950 in the original dataset
|
||||
test `grep '"POP1950": [0-9]' tests/ne_110m_populated_places_nulls/in.json | wc -l` == 144
|
||||
# and 99 without it
|
||||
test `grep '"POP1950": null' tests/ne_110m_populated_places_nulls/in.json | wc -l` == 99
|
||||
./tippecanoe -yNAME -yPOP1950 -yclustered:cluster_size -yclustered:unrelated -q -z3 -r1.75 -b0 -f -e tests/pbf/accum.dir --accumulate-numeric-attributes=clustered --set-attribute '{"clustered:cluster_size":1}' --accumulate-attribute '{"clustered:cluster_size":"sum"}' --retain-points-multiplier 3 tests/ne_110m_populated_places_nulls/in.json
|
||||
# at this drop rate, there are 61 points at z0 that have no POP1950s clustered onto them....
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | wc -l` == 61
|
||||
# 26 of which have no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 26
|
||||
# 35 of which do have POP1950
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 35
|
||||
# plus 60 that are clustered
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 60
|
||||
# the 60 clustered POP1950s have a total count of 109
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:count:POP1950' | sed 's/.*"clustered:count:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 109
|
||||
# we have already established that there are 36 bare POP1950s
|
||||
# which makes a total of 144, which is the total count expected
|
||||
#
|
||||
# meanwhile, regular attribute accumulation.
|
||||
# there are 121 features in the z0 tile, and they all have clustered:cluster_size
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:cluster_size' | wc -l` == 121
|
||||
# there are no features that lack it.
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:cluster_size' | wc -l` == 0
|
||||
# they add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# But that we *do* preserve those attributes into the output features:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 61
|
||||
#
|
||||
# on to the sums:
|
||||
# in the original data set, the POP1950s that are present add up to 161590
|
||||
test `grep '"POP1950": [0-9]' tests/ne_110m_populated_places_nulls/in.json | sed 's/.*"POP1950": //' | awk '{sum += $$1} END {print sum}' ` == 161590
|
||||
# in the z0 tile, the clustered POP1950s add up to 116967
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 116967
|
||||
# and the non-clustered ones add up to 44623
|
||||
test `./tippecanoe-decode -c tests/pbf/accum.dir/0/0/0.pbf 0 0 0 | grep -v 'clustered:sum:POP1950' | grep POP1950 | sed 's/.*"POP1950": //' | awk '{sum += $$1} END {print sum}'` == 44623
|
||||
# which is the correct 161590
|
||||
#
|
||||
# OK, so do these still hold after megatile filtering?
|
||||
./tippecanoe-overzoom --accumulate-numeric-attributes=clustered --accumulate-attribute '{"clustered:cluster_size":"sum"}' -m -o tests/pbf/accum-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# Now there are 40 features with POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 40
|
||||
# There are 4 with bare POP1950
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 4
|
||||
# And 2 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 2
|
||||
# (which is the same as you get if you don't use -retain-points-multiplier when creating the tileset)
|
||||
#
|
||||
# the clustered and megatile-filtered POP1950s add up to 146370
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 146370
|
||||
# the non-clustered but megatile-filtered POP1950s add up to 15220
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'clustered:sum:POP1950' | grep POP1950 | sed 's/.*"POP1950": //' | awk '{sum += $$1} END {print sum}'` == 15220
|
||||
# which add up to 161590 so we have the right global total
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# But that we *do* preserve those attributes into the output features:
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 22
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
# We actually want to serve point tiles without the numeric accumulations,
|
||||
# but with cluster size, so test that combination:
|
||||
./tippecanoe-overzoom --accumulate-attribute '{"clustered:cluster_size":"sum"}' --exclude-prefix clustered:sum --exclude-prefix clustered:count --exclude-prefix clustered:min --exclude-prefix clustered:max --exclude-prefix clustered:mean -m -o tests/pbf/accum-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# There are no POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 0
|
||||
# But there are still 28 with bare POP1950
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 28
|
||||
# And 18 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 18
|
||||
# which matches the 46 features that you get if you tile without --retain-points-multiplier.
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/accum-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
# Now on to binning!
|
||||
./tippecanoe-overzoom --assign-to-bins tests/pbf/h3-0-0-0.geojson --accumulate-numeric-attributes=clustered --accumulate-attribute '{"clustered:cluster_size":"sum"}' -o tests/pbf/bins-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# Now there are 30 bins with POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 41
|
||||
# There are none with bare POP1950 (which is expected; we should only have summary statistics)
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 0
|
||||
# And 4 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 3
|
||||
#
|
||||
# the clustered and megatile-filtered and binned POP1950s add up to 161590
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 161590
|
||||
# which is the right global total
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# And those attributes do *not* make it onto the bins
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 0
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
# Binning with attribute stripping
|
||||
./tippecanoe-overzoom -y clustered:count:POP1950 -y clustered:sum:POP1950 -y POP1950 -y clustered:cluster_size --assign-to-bins tests/pbf/h3-0-0-0.geojson --accumulate-numeric-attributes=clustered --accumulate-attribute '{"clustered:cluster_size":"sum"}' -o tests/pbf/bins-0-0-0.pbf tests/pbf/accum.dir/0/0/0.pbf 0/0/0 0/0/0
|
||||
# Now there are 30 bins with POP1950 clusters
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:count:POP1950' | wc -l` == 41
|
||||
# There are none with bare POP1950 (which is expected; we should only have summary statistics)
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'clustered:count:POP1950' | grep 'POP1950' | wc -l` == 0
|
||||
# And 4 with no POP1950 at all
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep -v 'POP1950' | wc -l` == 3
|
||||
#
|
||||
# the clustered and megatile-filtered and binned POP1950s add up to 161590
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep 'clustered:sum:POP1950' | sed 's/.*"clustered:sum:POP1950": //' | awk '{sum += $$1} END {print sum}'` == 161590
|
||||
# which is the right global total
|
||||
# Make sure we do *not* accumulate a numeric attribute that already has the magic prefix:
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep sum:clustered:unrelated | wc -l` == 0
|
||||
# And those attributes do *not* make it onto the bins
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | grep clustered:unrelated | wc -l` == 0
|
||||
# the cluster sizes still add up to the 243 original features
|
||||
test `./tippecanoe-decode -c tests/pbf/bins-0-0-0.pbf 0 0 0 | sed 's/.*clustered:cluster_size": //' | awk '{sum += $$1} END {print sum}'` == 243
|
||||
#
|
||||
#
|
||||
# A tile where the counts and means were previously wrong:
|
||||
./tippecanoe-overzoom --accumulate-numeric-attributes=felt -m -o tests/pbf/yearbuilt-accum.pbf tests/pbf/yearbuilt.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/yearbuilt-accum.pbf 0 0 0 > tests/pbf/yearbuilt-accum.pbf.json.check
|
||||
cmp tests/pbf/yearbuilt-accum.pbf.json.check tests/pbf/yearbuilt-accum.pbf.json
|
||||
rm tests/pbf/yearbuilt-accum.pbf tests/pbf/yearbuilt-accum.pbf.json.check
|
||||
# Same tile, with attribute stripping
|
||||
./tippecanoe-overzoom --accumulate-numeric-attributes=felt -y bldgsqft -y felt:sum:bldgsqft -m -o tests/pbf/yearbuilt-accum-bldgsqft.pbf tests/pbf/yearbuilt.pbf 0/0/0 0/0/0
|
||||
./tippecanoe-decode tests/pbf/yearbuilt-accum-bldgsqft.pbf 0 0 0 > tests/pbf/yearbuilt-accum-bldgsqft.pbf.json.check
|
||||
cmp tests/pbf/yearbuilt-accum-bldgsqft.pbf.json.check tests/pbf/yearbuilt-accum-bldgsqft.pbf.json
|
||||
rm tests/pbf/yearbuilt-accum-bldgsqft.pbf tests/pbf/yearbuilt-accum-bldgsqft.pbf.json.check
|
||||
|
||||
join-filter-test: tippecanoe tippecanoe-decode tile-join
|
||||
# Comes out different from the direct tippecanoe run because null attributes are lost
|
||||
@@ -797,6 +572,12 @@ csv-test: tippecanoe tippecanoe-decode
|
||||
cmp tests/csv/out.mbtiles.json.check tests/csv/out.mbtiles.json
|
||||
rm -f tests/csv/out.mbtiles.json.check tests/csv/out.mbtiles
|
||||
|
||||
flatgeobuf-test: tippecanoe tippecanoe-decode
|
||||
./tippecanoe -q -f -z0 -l numeric-properties -o tests/flatgeobuf/numeric-properties.mbtiles tests/flatgeobuf/numeric-properties.fgb
|
||||
./tippecanoe-decode tests/flatgeobuf/numeric-properties.mbtiles 0 0 0 > tests/flatgeobuf/numeric-properties.json.check
|
||||
cmp tests/flatgeobuf/numeric-properties.json.check tests/flatgeobuf/numeric-properties.json
|
||||
rm -f tests/flatgeobuf/numeric-properties.mbtiles tests/flatgeobuf/numeric-properties.json.check
|
||||
|
||||
layer-json-test: tippecanoe tippecanoe-decode
|
||||
# GeoJSON with description and named layer
|
||||
./tippecanoe -q -z0 -r1 -yNAME -f -o tests/layer-json/out.mbtiles -L'{"file":"tests/ne_110m_populated_places/in.json", "description":"World cities", "layer":"places"}'
|
||||
|
||||
@@ -20,11 +20,11 @@ the density and texture of the data rather than a simplification from dropping
|
||||
supposedly unimportant features or clustering or aggregating them.
|
||||
|
||||
If you give it all of OpenStreetMap and zoom out, it should give you back
|
||||
something that looks like "[All Streets](http://benfry.com/allstreets/map5.html)"
|
||||
something that looks like "[All Streets](https://benfry.com/allstreets/)"
|
||||
rather than something that looks like an Interstate road atlas.
|
||||
|
||||
If you give it all the building footprints in Los Angeles and zoom out
|
||||
far enough that most individual buildings are no longer discernable, you
|
||||
far enough that most individual buildings are no longer discernible, you
|
||||
should still be able to see the extent and variety of development in every neighborhood,
|
||||
not just the largest downtown buildings.
|
||||
|
||||
@@ -57,7 +57,7 @@ compiler errors.
|
||||
Usage
|
||||
-----
|
||||
|
||||
```sh
|
||||
```
|
||||
$ tippecanoe -o file.mbtiles [options] [file.json file.json.gz file.fgb ...]
|
||||
```
|
||||
|
||||
@@ -99,7 +99,7 @@ $ tippecanoe -o alameda.mbtiles -l alameda -n "Alameda County from TIGER" -z13 t
|
||||
Create a tileset of all TIGER roads, at only zoom level 12, but with higher detail than normal,
|
||||
with a custom layer name and description, and leaving out the `LINEARID` and `RTTYP` attributes:
|
||||
|
||||
```
|
||||
```sh
|
||||
$ cat tiger/tl_2014_*_roads.json | tippecanoe -o tiger.mbtiles -l roads -n "All TIGER roads, one zoom" -z12 -Z12 -d14 -x LINEARID -x RTTYP
|
||||
```
|
||||
|
||||
@@ -108,7 +108,7 @@ Cookbook
|
||||
|
||||
### Linear features (world railroads), visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_railroads.zip
|
||||
unzip ne_10m_railroads.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_railroads.geojson ne_10m_railroads.shp
|
||||
@@ -122,7 +122,7 @@ tippecanoe -zg -o ne_10m_railroads.mbtiles --drop-densest-as-needed --extend-zoo
|
||||
|
||||
### Discontinuous polygon features (buildings of Rhode Island), visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://usbuildingdata.blob.core.windows.net/usbuildings-v1-1/RhodeIsland.zip
|
||||
unzip RhodeIsland.zip
|
||||
|
||||
@@ -135,7 +135,7 @@ tippecanoe -zg -o RhodeIsland.mbtiles --drop-densest-as-needed --extend-zooms-if
|
||||
|
||||
### Continuous polygon features (states and provinces), visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_admin_1_states_provinces.zip
|
||||
unzip -o ne_10m_admin_1_states_provinces.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_admin_1_states_provinces.geojson ne_10m_admin_1_states_provinces.shp
|
||||
@@ -149,7 +149,7 @@ tippecanoe -zg -o ne_10m_admin_1_states_provinces.mbtiles --coalesce-densest-as-
|
||||
|
||||
### Large point dataset (GPS bus locations), for visualization at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O ftp://avl-data.sfmta.com/avl_data/avl_raw/sfmtaAVLRawData01012013.csv
|
||||
sed 's/PREDICTABLE.*/PREDICTABLE/' sfmtaAVLRawData01012013.csv > sfmta.csv
|
||||
tippecanoe -zg -o sfmta.mbtiles --drop-densest-as-needed --extend-zooms-if-still-dropping sfmta.csv
|
||||
@@ -163,7 +163,7 @@ tippecanoe -zg -o sfmta.mbtiles --drop-densest-as-needed --extend-zooms-if-still
|
||||
|
||||
### Clustered points (world cities), summing the clustered population, visible at all zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_populated_places.zip
|
||||
unzip -o ne_10m_populated_places.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_populated_places.geojson ne_10m_populated_places.shp
|
||||
@@ -178,7 +178,7 @@ tippecanoe -zg -o ne_10m_populated_places.mbtiles -r1 --cluster-distance=10 --ac
|
||||
|
||||
### Show countries at low zoom levels but states at higher zoom levels
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www.naturalearthdata.com/http//www.naturalearthdata.com/download/10m/cultural/ne_10m_admin_0_countries.zip
|
||||
unzip ne_10m_admin_0_countries.zip
|
||||
ogr2ogr -f GeoJSON ne_10m_admin_0_countries.geojson ne_10m_admin_0_countries.shp
|
||||
@@ -206,7 +206,7 @@ States and Provinces:
|
||||
|
||||
### Represent multiple sources (Illinois and Indiana counties) as separate layers
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/COUNTY/2010/tl_2010_17_county10.zip
|
||||
unzip tl_2010_17_county10.zip
|
||||
ogr2ogr -f GeoJSON tl_2010_17_county10.geojson tl_2010_17_county10.shp
|
||||
@@ -224,7 +224,7 @@ tippecanoe -zg -o counties-separate.mbtiles --coalesce-densest-as-needed --exten
|
||||
|
||||
### Merge multiple sources (Illinois and Indiana counties) into the same layer
|
||||
|
||||
```
|
||||
```sh
|
||||
curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/COUNTY/2010/tl_2010_17_county10.zip
|
||||
unzip tl_2010_17_county10.zip
|
||||
ogr2ogr -f GeoJSON tl_2010_17_county10.geojson tl_2010_17_county10.shp
|
||||
@@ -242,7 +242,7 @@ As above, but
|
||||
|
||||
### Selectively remove and replace features (Census tracts) to update a tileset
|
||||
|
||||
```
|
||||
```sh
|
||||
# Retrieve and tile California 2000 Census tracts
|
||||
curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/TRACT/2000/tl_2010_06_tract00.zip
|
||||
unzip tl_2010_06_tract00.zip
|
||||
@@ -316,7 +316,7 @@ If your input is formatted as newline-delimited GeoJSON, use `-P` to make input
|
||||
* `-L` _name_`:`_file.json_ or `--named-layer=`_name_`:`_file.json_: Specify layer names for individual files. If your shell supports it, you can use a subshell redirect like `-L` _name_`:<(cat dir/*.json)` to specify a layer name for the output of streamed input.
|
||||
* `-L{`_layer-json_`}` or `--named-layer={`_layer-json_`}`: Specify an input file and layer options by a JSON object. The JSON object must contain a `"file"` key to specify the filename to read from. (If the `"file"` key is an empty string, it means to read from the standard input stream.) It may also contain a `"layer"` field to specify the name of the layer, and/or a `"description"` field to specify the layer's description in the tileset metadata, and/or a `"format"` field to specify `csv` or `fgb` file format if it is not obvious from the `name`. Example:
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -z5 -o world.mbtiles -L'{"file":"ne_10m_admin_0_countries.json", "layer":"countries", "description":"Natural Earth countries"}'
|
||||
```
|
||||
|
||||
@@ -418,7 +418,6 @@ be reduced to the maximum that can be used with the specified _maxzoom_.
|
||||
`sum`, `product`, `mean`, `max`, `min`, `concat`, or `comma`
|
||||
to specify how the named _attribute_ is accumulated onto the attribute of the same name in a feature that does survive.
|
||||
The attributes and operations may also be specified as JSON keys and values: `--accumulate-attribute='{"attr": "operation", "attr2": "operation2"}'`.
|
||||
* `--accumulate-numeric-attributes` _prefix_: Accumulate sum, count, min, and max for all numeric attributes into new attributes with the specified _prefix_.
|
||||
* `--set-attribute` _attribute_`:`_value_: Set the value of the specified _attribute_ in each feature to the specified _value_. This is mostly useful to give an attribute in each feature an initial value for `--accumulate-attribute`.
|
||||
The attributes and values may also be specified as JSON keys and values: `--set-attribute='{"attr": value, "attr2": value}'`.
|
||||
* `-pe` or `--empty-csv-columns-are-null`: Treat empty CSV columns as nulls rather than as empty strings.
|
||||
@@ -435,20 +434,20 @@ be reduced to the maximum that can be used with the specified _maxzoom_.
|
||||
|
||||
Example: to find the Natural Earth countries with low `scalerank` but high `LABELRANK`:
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -z5 -o filtered.mbtiles -j '{ "ne_10m_admin_0_countries": [ "all", [ "<", "scalerank", 3 ], [ ">", "LABELRANK", 5 ] ] }' ne_10m_admin_0_countries.geojson
|
||||
```
|
||||
|
||||
Example: to retain only major TIGER roads at low zoom levels:
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o roads.mbtiles -j '{ "*": [ "any", [ ">=", "$zoom", 11 ], [ "in", "MTFCC", "S1100", "S1200" ] ] }' tl_2015_06001_roads.json
|
||||
```
|
||||
|
||||
Tippecanoe also accepts expressions of the form `[ "attribute-filter", name, expression ]`, to filter individual feature attributes
|
||||
instead of entire features. For example, you can exclude the road names at low zoom levels by doing
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o roads.mbtiles -j '{ "*": [ "attribute-filter", "FULLNAME", [ ">=", "$zoom", 9 ] ] }' tl_2015_06001_roads.json
|
||||
```
|
||||
|
||||
@@ -478,7 +477,7 @@ the same layer, enclose them in an `all` expression so they will all be evaluate
|
||||
* `-k` _zoom_ or `--cluster-maxzoom=`_zoom_: Max zoom on which to cluster points if clustering is enabled.
|
||||
* `-kg` or `--cluster-maxzoom=g`: Set `--cluster-maxzoom=` to `maxzoom - 1` so that all features are visible at the maximum zoom level.
|
||||
* `--keep-point-cluster-position`: Do not average the location of points as they are clustered.
|
||||
* `--preserve-point-density-threshold=`_level_: At the low zoom levels, do not reduce point density below the specified _level_, even if the specfied drop rate would normally call for it, so that low-density areas of the map do not appear blank. The unit is the distance between preserved points, as a fraction of the size of a tile. Values of 32 or 64 are probably appropriate for typical marker sizes.
|
||||
* `--preserve-point-density-threshold=`_level_: At the low zoom levels, do not reduce point density below the specified _level_, even if the specified drop rate would normally call for it, so that low-density areas of the map do not appear blank. The unit is the distance between preserved points, as a fraction of the size of a tile. Values of 32 or 64 are probably appropriate for typical marker sizes.
|
||||
* `--preserve-multiplier-density-threshold=`_level_: Preserve a minimum point density, but as `--retain-points-multiplier` features, not primary features.
|
||||
|
||||
### Dropping a fraction of features to keep under tile size limits
|
||||
@@ -486,6 +485,7 @@ the same layer, enclose them in an `all` expression so they will all be evaluate
|
||||
* `-as` or `--drop-densest-as-needed`: If a tile is too large, try to reduce it to under 500K by increasing the minimum spacing between features. The discovered spacing applies to the entire zoom level.
|
||||
* `-ad` or `--drop-fraction-as-needed`: Dynamically drop some fraction of features from each zoom level to keep large tiles under the 500K size limit. (This is like `-pd` but applies to the entire zoom level, not to each tile.)
|
||||
* `-an` or `--drop-smallest-as-needed`: Dynamically drop the smallest features (physically smallest: the shortest lines or the smallest polygons) from each zoom level to keep large tiles under the 500K size limit.
|
||||
* `--drop-by-attribute-as-needed=`_attribute_: Dynamically drop features with the lowest values of the specified numeric _attribute_ from each zoom level to keep large tiles under the 500K size limit. Use `--drop-by-attribute-order=desc` to instead drop features with the highest values.
|
||||
* `-aN` or `--coalesce-smallest-as-needed`: Dynamically combine the smallest features (physically smallest: the shortest lines or the smallest polygons or the densest points) from each zoom level into other nearby features to keep large tiles under the 500K size limit. This option will probably not help very much with LineStrings. It is mostly intended for polygons, to maintain the full original area covered by polygons while still reducing the feature count somehow. The attributes of the small polygons are *not* preserved into the combined features (except through `--accumulate-attribute`), only their geometry. Furthermore, the polygons to which nested polygons are coalesced may not necessarily be the immediately enclosing features.
|
||||
* `-aD` or `--coalesce-densest-as-needed`: Dynamically combine the densest features from each zoom level into other nearby features to keep large tiles under the 500K size limit. (Again, mostly useful for polygons.)
|
||||
* `-aS` or `--coalesce-fraction-as-needed`: Dynamically combine a fraction of features from each zoom level into other nearby features to keep large tiles under the 500K size limit. (Again, mostly useful for polygons.)
|
||||
@@ -602,7 +602,7 @@ contain `index`, `sequence`, `extent`, and `dropped`, elements, which must be pa
|
||||
* Make a tileset of the Natural Earth countries to zoom level 5, and also copy the GeoJSON features
|
||||
to files in a `tiles/z/x/y.geojson` directory hierarchy.
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o countries.mbtiles -z5 -C 'mkdir -p tiles/$1/$2; tee tiles/$1/$2/$3.geojson' ne_10m_admin_0_countries.json
|
||||
```
|
||||
|
||||
@@ -610,13 +610,13 @@ tippecanoe -o countries.mbtiles -z5 -C 'mkdir -p tiles/$1/$2; tee tiles/$1/$2/$3
|
||||
intersect the [bounding box of Germany](https://www.flickr.com/places/info/23424829).
|
||||
(The `limit-tiles-to-bbox` script is [in the Tippecanoe source directory](filters/limit-tiles-to-bbox).)
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o countries.mbtiles -z5 -C './filters/limit-tiles-to-bbox 5.8662 47.2702 15.0421 55.0581 $*' ne_10m_admin_0_countries.json
|
||||
```
|
||||
|
||||
* Make a tileset of TIGER roads in Tippecanoe County, leaving out all but primary and secondary roads (as [classified by TIGER](https://www.census.gov/geo/reference/mtfcc.html)) below zoom level 11.
|
||||
|
||||
```
|
||||
```sh
|
||||
tippecanoe -o roads.mbtiles -c 'if [ $1 -lt 11 ]; then grep "\"MTFCC\": \"S1[12]00\""; else cat; fi' tl_2016_18157_roads.json
|
||||
```
|
||||
|
||||
@@ -633,7 +633,7 @@ Tippecanoe defines a GeoJSON extension that you can use to specify the minimum a
|
||||
at which an individual feature will be included in the vector tileset being produced.
|
||||
If you have a feature like this:
|
||||
|
||||
```
|
||||
```json
|
||||
{
|
||||
"type" : "Feature",
|
||||
"tippecanoe" : { "maxzoom" : 9, "minzoom" : 4 },
|
||||
@@ -645,7 +645,7 @@ If you have a feature like this:
|
||||
}
|
||||
```
|
||||
|
||||
with a `tippecanoe` object specifiying a `maxzoom` of 9 and a `minzoom` of 4, the feature
|
||||
with a `tippecanoe` object specifying a `maxzoom` of 9 and a `minzoom` of 4, the feature
|
||||
will only appear in the vector tiles for zoom levels 4 through 9. Note that the `tippecanoe`
|
||||
object belongs to the Feature, not to its `properties`. If you specify a `minzoom` for a feature,
|
||||
it will be preserved down to that zoom level even if dot-dropping with `-r` would otherwise have
|
||||
@@ -654,7 +654,7 @@ dropped it.
|
||||
You can also specify a layer name in the `tippecanoe` object, which will take precedence over
|
||||
the filename or name specified using `--layer`, like this:
|
||||
|
||||
```
|
||||
```json
|
||||
{
|
||||
"type" : "Feature",
|
||||
"tippecanoe" : { "layer" : "streets" },
|
||||
@@ -724,10 +724,10 @@ and perhaps
|
||||
make install
|
||||
|
||||
Tippecanoe now requires features from the 2011 C++ standard. If your compiler is older than
|
||||
that, you will need to install a newer one. On MacOS, updating to the lastest XCode should
|
||||
that, you will need to install a newer one. On MacOS, updating to the latest XCode should
|
||||
get you a new enough version of `clang++`. On Linux, you should be able to upgrade `g++` with
|
||||
|
||||
```
|
||||
```sh
|
||||
sudo add-apt-repository -y ppa:ubuntu-toolchain-r/test
|
||||
sudo apt-get update -y
|
||||
sudo apt-get install -y g++-5
|
||||
@@ -863,7 +863,7 @@ awk 'BEGIN {
|
||||
|
||||
which looks like this:
|
||||
|
||||
```
|
||||
```csv
|
||||
GEOID10,population
|
||||
"060014277003018",0
|
||||
"060014283014046",0
|
||||
@@ -961,7 +961,7 @@ for Tippecanoe County, Indiana.
|
||||
|
||||
Download Census block geometry, and convert to GeoJSON:
|
||||
|
||||
```
|
||||
```sh
|
||||
$ curl -L -O https://www2.census.gov/geo/tiger/TIGER2010/TABBLOCK/2010/tl_2010_18157_tabblock10.zip
|
||||
$ unzip tl_2010_18157_tabblock10.zip
|
||||
$ ogr2ogr -f GeoJSON tl_2010_18157_tabblock10.json tl_2010_18157_tabblock10.shp
|
||||
@@ -969,7 +969,7 @@ $ ogr2ogr -f GeoJSON tl_2010_18157_tabblock10.json tl_2010_18157_tabblock10.shp
|
||||
|
||||
Download Indiana employment data, and fix name of join key in header
|
||||
|
||||
```
|
||||
```sh
|
||||
$ curl -L -O https://lehd.ces.census.gov/data/lodes/LODES7/in/wac/in_wac_S000_JT00_2015.csv.gz
|
||||
$ gzip -dc in_wac_S000_JT00_2015.csv.gz | sed '1s/w_geocode/GEOID10/' > in_wac_S000_JT00_2015.csv
|
||||
```
|
||||
@@ -977,13 +977,13 @@ $ gzip -dc in_wac_S000_JT00_2015.csv.gz | sed '1s/w_geocode/GEOID10/' > in_wac_S
|
||||
Sort GeoJSON block geometry so it is ordered by block ID. If you don't do this, you will get a
|
||||
"GeoJSON file is out of sort" error.
|
||||
|
||||
```
|
||||
```sh
|
||||
$ tippecanoe-json-tool -e GEOID10 tl_2010_18157_tabblock10.json | LC_ALL=C sort > tl_2010_18157_tabblock10.sort.json
|
||||
```
|
||||
|
||||
Join block geometries to employment attributes:
|
||||
|
||||
```
|
||||
```sh
|
||||
$ tippecanoe-json-tool -c in_wac_S000_JT00_2015.csv tl_2010_18157_tabblock10.sort.json > blocks-wac.json
|
||||
```
|
||||
|
||||
|
||||
@@ -1214,47 +1214,6 @@ bool pnpoly_mp(drawvec const &geom, long long x, long long y) {
|
||||
return found;
|
||||
}
|
||||
|
||||
clipbbox parse_clip_poly(std::string arg) {
|
||||
json_pull *jp = json_begin_string(arg.c_str());
|
||||
json_object *j = json_read_tree(jp);
|
||||
if (j == NULL) {
|
||||
fprintf(stderr, "Expected JSON object, not %s\n", arg.c_str());
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
if (j->type != JSON_HASH) {
|
||||
fprintf(stderr, "Expected JSON geometry object, not %s\n", arg.c_str());
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
std::pair<int, drawvec> parsed_geometry = parse_geometry(j, jp, j, 0, 0, 0, 1LL << 32, false, false);
|
||||
json_end(jp);
|
||||
|
||||
clipbbox out;
|
||||
out.minx = LLONG_MAX;
|
||||
out.miny = LLONG_MAX;
|
||||
out.maxx = LLONG_MIN;
|
||||
out.maxy = LLONG_MIN;
|
||||
for (auto const &d : parsed_geometry.second) {
|
||||
if (d.op == VT_MOVETO || d.op == VT_LINETO) {
|
||||
if (d.x < out.minx) {
|
||||
out.minx = d.x;
|
||||
}
|
||||
if (d.y < out.miny) {
|
||||
out.miny = d.y;
|
||||
}
|
||||
if (d.x > out.maxx) {
|
||||
out.maxx = d.x;
|
||||
}
|
||||
if (d.y > out.maxy) {
|
||||
out.maxy = d.y;
|
||||
}
|
||||
}
|
||||
}
|
||||
out.dv = std::move(parsed_geometry.second);
|
||||
|
||||
return out;
|
||||
}
|
||||
|
||||
std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int ny,
|
||||
int detail_or_unspecified, int buffer,
|
||||
std::set<std::string> const &keep,
|
||||
@@ -1266,9 +1225,9 @@ std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int n
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::vector<std::string> const &unidecode_data, double simplification,
|
||||
double tiny_polygon_size,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
std::string const &accumulate_numeric, size_t feature_limit,
|
||||
std::vector<clipbbox> const &clipbboxes,
|
||||
std::vector<mvt_layer> const &unused2, std::string const &unused3,
|
||||
std::string const &unused, size_t feature_limit,
|
||||
std::vector<clipbbox> const &unused4,
|
||||
bool deduplicate_by_id) {
|
||||
std::vector<source_tile> decoded;
|
||||
|
||||
@@ -1295,7 +1254,7 @@ std::string overzoom(std::vector<input_tile> const &tiles, int nz, int nx, int n
|
||||
decoded.push_back(out);
|
||||
}
|
||||
|
||||
return overzoom(decoded, nz, nx, ny, detail_or_unspecified, buffer, keep, exclude, exclude_prefix, do_compress, next_overzoomed_tiles, demultiply, filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, bins, bin_by_id_list, accumulate_numeric, feature_limit, clipbboxes, deduplicate_by_id);
|
||||
return overzoom(decoded, nz, nx, ny, detail_or_unspecified, buffer, keep, exclude, exclude_prefix, do_compress, next_overzoomed_tiles, demultiply, filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, unused2, unused3, unused, feature_limit, unused4, deduplicate_by_id);
|
||||
}
|
||||
|
||||
// like a minimal serial_feature, but with mvt_feature-style attributes
|
||||
@@ -1330,152 +1289,6 @@ static bool should_keep(std::string const &key,
|
||||
return false;
|
||||
}
|
||||
|
||||
static void add_mean(mvt_feature &feature, mvt_layer &layer, std::string const &accumulate_numeric,
|
||||
std::set<std::string> const &keep, std::set<std::string> const &exclude,
|
||||
std::vector<std::string> const &exclude_prefix) {
|
||||
std::string accumulate_numeric_colon = accumulate_numeric + ":";
|
||||
|
||||
std::unordered_map<std::string, size_t> attributes;
|
||||
for (size_t i = 0; i + 1 < feature.tags.size(); i += 2) {
|
||||
std::string const &key = layer.keys[feature.tags[i]];
|
||||
if (starts_with(key, accumulate_numeric_colon)) {
|
||||
attributes.emplace(key, i);
|
||||
}
|
||||
}
|
||||
|
||||
for (size_t i = 0; i + 1 < feature.tags.size(); i += 2) {
|
||||
std::string accumulate_numeric_sum_colon = accumulate_numeric + ":sum:";
|
||||
|
||||
std::string const &key = layer.keys[feature.tags[i]];
|
||||
if (starts_with(key, accumulate_numeric_sum_colon)) {
|
||||
std::string trunc = key.substr(accumulate_numeric_sum_colon.size());
|
||||
auto const f = attributes.find(accumulate_numeric + ":count:" + trunc);
|
||||
if (f != attributes.end()) {
|
||||
mvt_value const &sum = layer.values[feature.tags[i + 1]];
|
||||
mvt_value const &count = layer.values[feature.tags[f->second + 1]];
|
||||
double count_val = mvt_value_to_double(count);
|
||||
if (count_val <= 0) {
|
||||
fprintf(stderr, "can't happen: count is %s (type %d)\n", count.toString().c_str(), count.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
mvt_value mean;
|
||||
mean.type = mvt_double;
|
||||
mean.numeric_value.double_value = mvt_value_to_double(sum) / count_val;
|
||||
|
||||
if (should_keep(key, keep, exclude, exclude_prefix)) {
|
||||
layer.tag(feature, accumulate_numeric + ":mean:" + trunc, mean);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
// accumulate :sum:, :min:, :max:, and :count: versions of the specified attribute
|
||||
static void preserve_numeric(const std::string &key, const mvt_value &val, // numeric attribute being accumulated
|
||||
std::vector<std::shared_ptr<std::string>> &full_keys, // keys of feature being accumulated onto
|
||||
std::vector<mvt_value> &full_values, // values of features being accumulated onto
|
||||
const std::string &accumulate_numeric, // prefix of accumulations
|
||||
std::set<std::string> &keys, // key presence in the source feature
|
||||
std::map<std::string, size_t> &numeric_out_field, // key index in the output feature
|
||||
key_pool &key_pool,
|
||||
std::set<std::string> const &keep, std::set<std::string> const &exclude,
|
||||
std::vector<std::string> const &exclude_prefix) {
|
||||
// If this is a numeric attribute, but there is also a prefix:sum (etc.) for the
|
||||
// same attribute, we want to use that one instead of this one.
|
||||
|
||||
for (auto const &op : numeric_operations) {
|
||||
std::string compound_key = accumulate_numeric + ":" + op.first + ":" + key;
|
||||
auto compound_found = keys.find(compound_key);
|
||||
if (compound_found != keys.end()) {
|
||||
// found, so skip this one
|
||||
} else {
|
||||
// not found, so accumulate this one
|
||||
|
||||
// if this is already prefixed, strip off the prefix
|
||||
// if it is the right one, and skip the attribute if
|
||||
// it is the wrong one.
|
||||
|
||||
std::string outkey = key;
|
||||
bool starting_from_accumulation;
|
||||
|
||||
if (starts_with(outkey, accumulate_numeric + ":")) {
|
||||
std::string prefix = accumulate_numeric + ":" + op.first + ":";
|
||||
if (starts_with(outkey, prefix)) {
|
||||
outkey = outkey.substr(prefix.size());
|
||||
starting_from_accumulation = true; // from a subaccumulation
|
||||
} else {
|
||||
continue; // to next operation
|
||||
}
|
||||
} else {
|
||||
starting_from_accumulation = false; // from a plain value
|
||||
}
|
||||
// and then put it back on for the output field
|
||||
std::string prefixed = accumulate_numeric + ":" + op.first + ":" + outkey;
|
||||
|
||||
if (!should_keep(prefixed, keep, exclude, exclude_prefix)) {
|
||||
continue;
|
||||
}
|
||||
|
||||
// Does it exist in the output feature already?
|
||||
|
||||
auto prefixed_attr = numeric_out_field.find(prefixed);
|
||||
if (prefixed_attr == numeric_out_field.end()) {
|
||||
// No? Does it exist unprefixed in the output feature already?
|
||||
|
||||
auto out_attr = numeric_out_field.find(outkey);
|
||||
if (out_attr == numeric_out_field.end()) {
|
||||
// not present at all, so copy our value to the prefixed output
|
||||
numeric_out_field.emplace(prefixed, full_keys.size());
|
||||
full_keys.push_back(key_pool.pool(prefixed));
|
||||
|
||||
if (op.second == op_count) {
|
||||
if (starting_from_accumulation) {
|
||||
// copy our count
|
||||
full_values.push_back(val);
|
||||
} else {
|
||||
// new count of 1
|
||||
full_values.push_back(mvt_value(1));
|
||||
}
|
||||
} else {
|
||||
full_values.push_back(val);
|
||||
}
|
||||
} else {
|
||||
// exists unprefixed, so copy it, and then accumulate on our value
|
||||
numeric_out_field.emplace(prefixed, full_keys.size());
|
||||
full_keys.push_back(key_pool.pool(prefixed));
|
||||
|
||||
if (op.second == op_count) {
|
||||
mvt_value v;
|
||||
if (starting_from_accumulation) {
|
||||
// sum our count onto the existing 1
|
||||
v = mvt_value(1 + mvt_value_to_long_long(val));
|
||||
} else {
|
||||
// sum our 1 onto the existing 1
|
||||
v = mvt_value(2);
|
||||
}
|
||||
full_values.push_back(v);
|
||||
} else {
|
||||
full_values.push_back(full_values[out_attr->second]);
|
||||
preserve_attribute(op.second, prefixed, val, full_keys, full_values, key_pool);
|
||||
}
|
||||
}
|
||||
} else {
|
||||
// exists, so accumulate on our value
|
||||
if (op.second == op_count) {
|
||||
if (starting_from_accumulation) {
|
||||
// sum our count onto the existing count
|
||||
full_values[prefixed_attr->second] = mvt_value(mvt_value_to_long_long(full_values[prefixed_attr->second]) + mvt_value_to_long_long(val));
|
||||
} else {
|
||||
full_values[prefixed_attr->second] = mvt_value(mvt_value_to_long_long(full_values[prefixed_attr->second]) + 1);
|
||||
}
|
||||
} else {
|
||||
preserve_attribute(op.second, prefixed, val, full_keys, full_values, key_pool);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
static void handle_closepath_from_mvt(drawvec &geom) {
|
||||
// mvt geometries close polygons with a mvt_closepath operation
|
||||
// tippecanoe-internal geometries close polygons with a lineto to the initial point
|
||||
@@ -1497,9 +1310,9 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
std::set<std::string> const &exclude,
|
||||
std::vector<std::string> const &exclude_prefix,
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::string const &accumulate_numeric,
|
||||
std::string const &,
|
||||
key_pool &key_pool, int buffer, bool include_nonaggregate,
|
||||
std::vector<clipbbox> const &clipbboxes, int nz, int nx, int ny,
|
||||
std::vector<clipbbox> const &, int, int, int,
|
||||
std::set<unsigned long long> *deduplicate_ids) {
|
||||
// Add geometry to output feature
|
||||
|
||||
@@ -1507,7 +1320,7 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
int t = features[0].t;
|
||||
|
||||
bool fix_polygons = false;
|
||||
if ((buffer >= 0 || clipbboxes.size() > 0) && t == VT_POLYGON) {
|
||||
if ((buffer >= 0) && t == VT_POLYGON) {
|
||||
fix_polygons = true;
|
||||
}
|
||||
|
||||
@@ -1528,48 +1341,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
geom = remove_noop(geom, t, 0);
|
||||
}
|
||||
|
||||
if (clipbboxes.size() != 0) {
|
||||
// bounding box is in world coordinates at world scale
|
||||
// feature is in local coordinates at tile scale
|
||||
|
||||
long long dx = (long long) nx << (32 - nz);
|
||||
long long dy = (long long) ny << (32 - nz);
|
||||
double scale = (double) outlayer.extent / (1LL << (32 - nz));
|
||||
|
||||
for (auto const &c_world : clipbboxes) {
|
||||
clipbbox c = c_world;
|
||||
|
||||
c.minx = std::llround((c_world.minx - dx) * scale);
|
||||
c.miny = std::llround((c_world.miny - dy) * scale);
|
||||
c.maxx = std::llround((c_world.maxx - dx) * scale);
|
||||
c.maxy = std::llround((c_world.maxy - dy) * scale);
|
||||
|
||||
for (auto &p : c.dv) {
|
||||
p.x = std::llround((p.x - dx) * scale);
|
||||
p.y = std::llround((p.y - dy) * scale);
|
||||
}
|
||||
|
||||
if (t == VT_POLYGON) {
|
||||
geom = simple_clip_poly(geom, c.minx, c.miny, c.maxx, c.maxy, false);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_poly_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_LINE) {
|
||||
geom = clip_lines(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_lines_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_POINT) {
|
||||
geom = clip_point(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_point_poly(geom, c.dv);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
geom = remove_noop(geom, t, 0);
|
||||
}
|
||||
|
||||
if (fix_polygons) {
|
||||
geom = clean_or_clip_poly(geom, 0, 0, false, false);
|
||||
geom = close_poly(geom);
|
||||
@@ -1599,7 +1370,7 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
|
||||
outfeature.seq = features[0].seq;
|
||||
|
||||
if (attribute_accum.size() > 0 || accumulate_numeric.size() > 0) {
|
||||
if (attribute_accum.size() > 0) {
|
||||
// convert the attributes of the output feature
|
||||
// from layer references to a vector so they can have
|
||||
// attributes from the other features of the
|
||||
@@ -1617,11 +1388,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
// this attribute has an accumulator, so convert it
|
||||
full_keys.push_back(key_pool.pool(f.layer->keys[f.tags[i]]));
|
||||
full_values.push_back(f.layer->values[f.tags[i + 1]]);
|
||||
} else if (accumulate_numeric.size() > 0 && f.layer->values[f.tags[i + 1]].is_numeric()) {
|
||||
// convert numeric for accumulation
|
||||
numeric_out_field.emplace(key, full_keys.size());
|
||||
full_keys.push_back(key_pool.pool(key));
|
||||
full_values.push_back(f.layer->values[f.tags[i + 1]]);
|
||||
} else if (include_nonaggregate) {
|
||||
// otherwise just tag it directly onto the output feature
|
||||
outlayer.tag(outfeature, f.layer->keys[f.tags[i]], f.layer->values[f.tags[i + 1]]);
|
||||
@@ -1650,14 +1416,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
if (found != attribute_accum.end()) {
|
||||
mvt_value val = features[i].layer->values[features[i].tags[j + 1]];
|
||||
preserve_attribute(found->second, key, val, full_keys, full_values, key_pool);
|
||||
} else if (accumulate_numeric.size() > 0) {
|
||||
const mvt_value &val = features[i].layer->values[features[i].tags[j + 1]];
|
||||
if (val.is_numeric()) {
|
||||
preserve_numeric(key, val, full_keys, full_values,
|
||||
accumulate_numeric,
|
||||
keys, numeric_out_field, key_pool,
|
||||
keep, exclude, exclude_prefix);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1671,10 +1429,6 @@ static bool feature_out(std::vector<tile_feature> const &features, mvt_layer &ou
|
||||
outlayer.tag(outfeature, *full_keys[i], full_values[i]);
|
||||
}
|
||||
}
|
||||
|
||||
if (accumulate_numeric.size() > 0) {
|
||||
add_mean(outfeature, outlayer, accumulate_numeric, keep, exclude, exclude_prefix);
|
||||
}
|
||||
} else if (include_nonaggregate) {
|
||||
for (size_t i = 0; i + 1 < features[0].tags.size(); i += 2) {
|
||||
if (should_keep(features[0].layer->keys[features[0].tags[i]], keep, exclude, exclude_prefix)) {
|
||||
@@ -1696,316 +1450,6 @@ static struct preservecmp {
|
||||
}
|
||||
} preservecmp;
|
||||
|
||||
struct index_event {
|
||||
unsigned long long where;
|
||||
enum index_event_kind {
|
||||
ENTER = 0, // new bin in is now active
|
||||
CHECK, // point needs to be checked against active bins
|
||||
EXIT // bin has ceased to be active
|
||||
} kind;
|
||||
size_t layer;
|
||||
size_t feature;
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
|
||||
index_event(unsigned long long where_, index_event_kind kind_, size_t layer_, size_t feature_,
|
||||
long long xmin_, long long ymin_, long long xmax_, long long ymax_)
|
||||
: where(where_), kind(kind_), layer(layer_), feature(feature_), xmin(xmin_), ymin(ymin_), xmax(xmax_), ymax(ymax_) {
|
||||
}
|
||||
|
||||
bool operator<(const index_event &ie) const {
|
||||
if (where < ie.where) {
|
||||
return true;
|
||||
} else if (where == ie.where) {
|
||||
if (kind < ie.kind) {
|
||||
return true;
|
||||
} else if (kind == ie.kind) {
|
||||
if (layer < ie.layer) {
|
||||
return true;
|
||||
} else if (layer == ie.layer) {
|
||||
if (feature < ie.feature) {
|
||||
return true;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return false;
|
||||
}
|
||||
};
|
||||
|
||||
struct active_bin {
|
||||
size_t layer;
|
||||
size_t feature;
|
||||
|
||||
active_bin(size_t layer_, size_t feature_)
|
||||
: layer(layer_), feature(feature_) {
|
||||
}
|
||||
|
||||
bool operator<(const active_bin &o) const {
|
||||
if (layer < o.layer) {
|
||||
return true;
|
||||
} else if (layer == o.layer) {
|
||||
if (feature < o.feature) {
|
||||
return true;
|
||||
}
|
||||
}
|
||||
|
||||
return false;
|
||||
}
|
||||
|
||||
size_t outfeature;
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
size_t counter = 0;
|
||||
};
|
||||
|
||||
void get_quadkey_bounds(long long xmin, long long ymin, long long xmax, long long ymax,
|
||||
unsigned long long *start, unsigned long long *end) {
|
||||
if (xmin < 0 || ymin < 0 || xmax >= 1LL << 32 || ymax >= 1LL << 32) {
|
||||
*start = 0;
|
||||
*end = ULLONG_MAX;
|
||||
return;
|
||||
}
|
||||
|
||||
*start = encode_quadkey(xmin, ymin);
|
||||
*end = encode_quadkey(xmax, ymax);
|
||||
|
||||
for (ssize_t i = 62; i >= 0; i -= 2) {
|
||||
if ((*start & (3LL << i)) != (*end & (3LL << i))) {
|
||||
for (; i >= 0; i -= 2) {
|
||||
*start &= ~(3LL << i);
|
||||
*end |= 3LL << i;
|
||||
}
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
static bool bbox_intersects(long long x1min, long long y1min, long long x1max, long long y1max,
|
||||
long long x2min, long long y2min, long long x2max, long long y2max) {
|
||||
if (x1max < x2min) {
|
||||
return false;
|
||||
}
|
||||
if (x2max < x1min) {
|
||||
return false;
|
||||
}
|
||||
if (y1max < y2min) {
|
||||
return false;
|
||||
}
|
||||
if (y2max < y1min) {
|
||||
return false;
|
||||
}
|
||||
return true;
|
||||
}
|
||||
|
||||
static std::vector<size_t> parse_ids_string(mvt_value const &v) {
|
||||
std::vector<size_t> out;
|
||||
std::string s = v.toString();
|
||||
|
||||
for (size_t i = 0; i < s.size(); i++) {
|
||||
if (i == 0 || s[i - 1] == ',') {
|
||||
out.push_back(atoll(s.c_str() + i));
|
||||
}
|
||||
}
|
||||
|
||||
return out;
|
||||
}
|
||||
|
||||
mvt_tile assign_to_bins(mvt_tile &features,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
int z, int x, int y,
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::string const &accumulate_numeric,
|
||||
std::set<std::string> keep,
|
||||
std::set<std::string> exclude,
|
||||
std::vector<std::string> exclude_prefix,
|
||||
int buffer, std::vector<clipbbox> const &clipbboxes) {
|
||||
std::vector<index_event> events;
|
||||
key_pool key_pool;
|
||||
|
||||
if (bins.size() == 0) {
|
||||
return mvt_tile();
|
||||
}
|
||||
|
||||
// Index bins
|
||||
for (size_t i = 0; i < bins.size(); i++) {
|
||||
for (size_t j = 0; j < bins[i].features.size(); j++) {
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
unsigned long long start, end;
|
||||
|
||||
get_bbox(bins[i].features[j].geometry, &xmin, &ymin, &xmax, &ymax, z, x, y, bins[i].detail());
|
||||
get_quadkey_bounds(xmin, ymin, xmax, ymax, &start, &end);
|
||||
events.emplace_back(start, index_event::ENTER, i, j, xmin, ymin, xmax, ymax);
|
||||
events.emplace_back(end, index_event::EXIT, i, j, xmin, ymin, xmax, ymax);
|
||||
}
|
||||
}
|
||||
|
||||
std::map<unsigned long long, std::pair<size_t, size_t>> fid_to_feature;
|
||||
|
||||
// Index points
|
||||
for (size_t i = 0; i < features.layers.size(); i++) {
|
||||
for (size_t j = 0; j < features.layers[i].features.size(); j++) {
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
unsigned long long start, end;
|
||||
|
||||
if (features.layers[i].features[j].geometry.size() > 0) {
|
||||
if (features.layers[i].features[j].has_id) {
|
||||
fid_to_feature.emplace(features.layers[i].features[j].id, std::make_pair(i, j));
|
||||
}
|
||||
|
||||
get_bbox(features.layers[i].features[j].geometry, &xmin, &ymin, &xmax, &ymax, z, x, y, features.layers[i].detail());
|
||||
get_quadkey_bounds(xmin, ymin, xmax, ymax, &start, &end);
|
||||
events.emplace_back(start, index_event::CHECK, i, j, xmin, ymin, xmax, ymax);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
std::sort(events.begin(), events.end());
|
||||
std::set<active_bin> active;
|
||||
|
||||
mvt_layer outlayer;
|
||||
outlayer.extent = bins[0].extent;
|
||||
outlayer.version = 2;
|
||||
outlayer.name = features.layers[0].name;
|
||||
|
||||
std::vector<std::vector<tile_feature>> outfeatures;
|
||||
|
||||
for (auto &e : events) {
|
||||
if (e.kind == index_event::ENTER) {
|
||||
active_bin a(e.layer, e.feature);
|
||||
a.xmin = e.xmin;
|
||||
a.ymin = e.ymin;
|
||||
a.xmax = e.xmax;
|
||||
a.ymax = e.ymax;
|
||||
|
||||
const mvt_feature &bin = bins[e.layer].features[e.feature];
|
||||
|
||||
{
|
||||
tile_feature outfeature;
|
||||
for (auto const &g : bin.geometry) {
|
||||
outfeature.geom.emplace_back(g.op, g.x, g.y);
|
||||
}
|
||||
outfeature.t = bin.type;
|
||||
outfeature.has_id = bin.has_id;
|
||||
outfeature.id = bin.id;
|
||||
outfeature.tags = bin.tags;
|
||||
outfeature.layer = &bins[e.layer];
|
||||
outfeature.seq = e.feature;
|
||||
|
||||
a.outfeature = outfeatures.size();
|
||||
outfeatures.push_back({std::move(outfeature)});
|
||||
}
|
||||
|
||||
if (bin_by_id_list.size() > 0) {
|
||||
for (size_t k = 0; k < bin.tags.size(); k += 2) {
|
||||
if (bins[e.layer].keys[bin.tags[k]] == bin_by_id_list) {
|
||||
std::vector<size_t> ids = parse_ids_string(bins[e.layer].values[bin.tags[k + 1]]);
|
||||
for (auto &id : ids) {
|
||||
auto f = fid_to_feature.find(id);
|
||||
if (f != fid_to_feature.end()) {
|
||||
mvt_feature &feature = features.layers[f->second.first].features[f->second.second];
|
||||
if (feature.geometry.size() > 0) {
|
||||
tile_feature outfeature;
|
||||
for (auto const &g : feature.geometry) {
|
||||
outfeature.geom.emplace_back(g.op, g.x, g.y);
|
||||
}
|
||||
feature.geometry.clear();
|
||||
outfeature.t = feature.type;
|
||||
outfeature.has_id = feature.has_id;
|
||||
outfeature.id = feature.id;
|
||||
outfeature.tags = feature.tags;
|
||||
outfeature.layer = &features.layers[e.layer];
|
||||
outfeature.seq = e.feature;
|
||||
outfeatures.back().push_back(std::move(outfeature));
|
||||
}
|
||||
}
|
||||
}
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
active.insert(std::move(a));
|
||||
} else if (e.kind == index_event::CHECK) {
|
||||
if (bin_by_id_list.size() > 0) {
|
||||
continue; // only bin by id, not geometrically
|
||||
}
|
||||
|
||||
auto const &feature = features.layers[e.layer].features[e.feature];
|
||||
|
||||
if (feature.geometry.size() == 0) {
|
||||
// already assigned by ID
|
||||
continue;
|
||||
}
|
||||
|
||||
// if we can't find a real match,
|
||||
// assign points to the most nearby bin
|
||||
ssize_t which_outfeature = outfeatures.size() - 1;
|
||||
|
||||
for (auto const &a : active) {
|
||||
auto const &bin = bins[a.layer].features[a.feature];
|
||||
|
||||
if (bbox_intersects(e.xmin, e.ymin, e.xmax, e.ymax,
|
||||
a.xmin, a.ymin, a.xmax, a.ymax)) {
|
||||
if (pnpoly_mp(bin.geometry, feature.geometry[0].x, feature.geometry[0].y)) {
|
||||
which_outfeature = a.outfeature;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (which_outfeature >= 0) {
|
||||
tile_feature outfeature;
|
||||
for (auto const &g : feature.geometry) {
|
||||
outfeature.geom.emplace_back(g.op, g.x, g.y);
|
||||
}
|
||||
outfeature.t = feature.type;
|
||||
outfeature.has_id = feature.has_id;
|
||||
outfeature.id = feature.id;
|
||||
outfeature.tags = feature.tags;
|
||||
outfeature.layer = &features.layers[e.layer];
|
||||
outfeature.seq = e.feature;
|
||||
outfeatures[which_outfeature].push_back(std::move(outfeature));
|
||||
}
|
||||
} else /* EXIT */ {
|
||||
auto const &found = active.find({e.layer, e.feature});
|
||||
if (found != active.end()) {
|
||||
active.erase(found);
|
||||
} else {
|
||||
fprintf(stderr, "event mismatch: can't happen\n");
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
for (size_t i = 0; i < outfeatures.size(); i++) {
|
||||
if (outfeatures[i].size() > 1) {
|
||||
if (feature_out(outfeatures[i], outlayer,
|
||||
keep, exclude, exclude_prefix, attribute_accum,
|
||||
accumulate_numeric, key_pool, buffer, true,
|
||||
clipbboxes, z, x, y, NULL)) {
|
||||
mvt_feature &nfeature = outlayer.features.back();
|
||||
mvt_value val;
|
||||
val.type = mvt_uint;
|
||||
val.numeric_value.uint_value = outfeatures[i].size() - 1;
|
||||
|
||||
std::string attrname;
|
||||
if (accumulate_numeric.size() == 0) {
|
||||
attrname = "tippecanoe:count";
|
||||
} else {
|
||||
attrname = accumulate_numeric + ":count";
|
||||
}
|
||||
if (should_keep(attrname, keep, exclude, exclude_prefix)) {
|
||||
outlayer.tag(nfeature, attrname, val);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
mvt_tile ret;
|
||||
ret.layers.push_back(outlayer);
|
||||
return ret;
|
||||
}
|
||||
|
||||
std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int ny,
|
||||
int detail_or_unspecified, int buffer,
|
||||
std::set<std::string> const &keep,
|
||||
@@ -2017,9 +1461,9 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
std::unordered_map<std::string, attribute_op> const &attribute_accum,
|
||||
std::vector<std::string> const &unidecode_data, double simplification,
|
||||
double tiny_polygon_size,
|
||||
std::vector<mvt_layer> const &bins, std::string const &bin_by_id_list,
|
||||
std::string const &accumulate_numeric, size_t feature_limit,
|
||||
std::vector<clipbbox> const &clipbboxes,
|
||||
std::vector<mvt_layer> const &unused2, std::string const &unused3,
|
||||
std::string const &unused, size_t feature_limit,
|
||||
std::vector<clipbbox> const &unused4,
|
||||
bool deduplicate_by_id) {
|
||||
mvt_tile outtile;
|
||||
key_pool key_pool;
|
||||
@@ -2093,30 +1537,6 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
}
|
||||
}
|
||||
|
||||
// Clip to user-specified bounding boxes.
|
||||
// Bounding box clip first, to reduce complexity of the full clip.
|
||||
// But don't clip here if we are binning, because we need to bin points in the buffer
|
||||
if (bins.size() == 0) {
|
||||
for (auto &c : clipbboxes) {
|
||||
if (t == VT_POLYGON) {
|
||||
geom = simple_clip_poly(geom, c.minx, c.miny, c.maxx, c.maxy, false);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_poly_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_LINE) {
|
||||
geom = clip_lines(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_lines_poly(geom, c.dv);
|
||||
}
|
||||
} else if (t == VT_POINT) {
|
||||
geom = clip_point(geom, c.minx, c.miny, c.maxx, c.maxy);
|
||||
if (c.dv.size() > 0 && geom.size() > 0) {
|
||||
geom = clip_point_poly(geom, c.dv);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Now offset from world coordinates to output tile coordinates,
|
||||
// but retain world scale, because that is what tippecanoe zoom-oriented clipping expects
|
||||
|
||||
@@ -2126,8 +1546,7 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
g.y -= ny * outtilesize;
|
||||
}
|
||||
|
||||
// Don't clip here if we are binning, because we need to bin points in the buffer
|
||||
if (bins.size() == 0) {
|
||||
{
|
||||
// Clip to output tile
|
||||
|
||||
long long xmin = LLONG_MAX;
|
||||
@@ -2145,6 +1564,9 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
long long b = outtilesize * buffer / 256;
|
||||
if (xmax < -b || ymax < -b || xmin > outtilesize + b || ymin > outtilesize + b) {
|
||||
// quick exclusion by bounding box
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -2160,6 +1582,9 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
|
||||
if (geom.size() == 0) {
|
||||
// clipped away
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -2184,7 +1609,7 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
|
||||
if (flush_multiplier_cluster) {
|
||||
if (pending_tile_features.size() > 0) {
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, accumulate_numeric, key_pool, -1, bins.size() == 0, std::vector<clipbbox>(), nz, nx, ny, deduplicate_by_id_set);
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, unused, key_pool, -1, true, std::vector<clipbbox>(), nz, nx, ny, deduplicate_by_id_set);
|
||||
if (outlayer->features.size() >= feature_limit) {
|
||||
break;
|
||||
}
|
||||
@@ -2194,6 +1619,10 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
|
||||
std::set<std::string> exclude_attributes;
|
||||
if (filter != NULL && !evaluate(feature, layer, filter, exclude_attributes, nz, unidecode_data)) {
|
||||
// filtered away
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
@@ -2231,6 +1660,14 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
geom = close_poly(geom);
|
||||
}
|
||||
|
||||
if (geom.size() == 0) {
|
||||
// simplified away
|
||||
if (deduplicate_by_id && feature.has_id) {
|
||||
deduplicate_by_id_set->insert(feature.id);
|
||||
}
|
||||
continue;
|
||||
}
|
||||
|
||||
tile_feature tf;
|
||||
tf.geom = std::move(geom);
|
||||
tf.t = t;
|
||||
@@ -2244,7 +1681,7 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
}
|
||||
|
||||
if (pending_tile_features.size() > 0) {
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, accumulate_numeric, key_pool, -1, bins.size() == 0, std::vector<clipbbox>(), nz, nx, ny, deduplicate_by_id_set);
|
||||
feature_out(pending_tile_features, *outlayer, keep, exclude, exclude_prefix, attribute_accum, unused, key_pool, -1, true, std::vector<clipbbox>(), nz, nx, ny, deduplicate_by_id_set);
|
||||
pending_tile_features.clear();
|
||||
if (outlayer->features.size() >= feature_limit) {
|
||||
break;
|
||||
@@ -2283,8 +1720,8 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
nz + 1, nx * 2 + x, ny * 2 + y,
|
||||
detail_or_unspecified, buffer, keep, exclude, exclude_prefix, false, NULL,
|
||||
demultiply, filter, preserve_input_order, attribute_accum, unidecode_data,
|
||||
simplification, tiny_polygon_size, bins, bin_by_id_list, accumulate_numeric,
|
||||
1, clipbboxes, deduplicate_by_id);
|
||||
simplification, tiny_polygon_size, unused2, unused3, unused,
|
||||
1, unused4, deduplicate_by_id);
|
||||
if (child.size() > 0) {
|
||||
next_overzoomed_tiles->emplace_back(nx * 2 + x, ny * 2 + y);
|
||||
}
|
||||
@@ -2293,12 +1730,6 @@ std::string overzoom(std::vector<source_tile> const &tiles, int nz, int nx, int
|
||||
}
|
||||
}
|
||||
|
||||
if (bins.size() > 0) {
|
||||
outtile = assign_to_bins(outtile, bins, bin_by_id_list, nz, nx, ny,
|
||||
attribute_accum, accumulate_numeric,
|
||||
keep, exclude, exclude_prefix, buffer, clipbboxes);
|
||||
}
|
||||
|
||||
for (ssize_t i = outtile.layers.size() - 1; i >= 0; i--) {
|
||||
if (outtile.layers[i].features.size() == 0) {
|
||||
outtile.layers.erase(outtile.layers.begin() + i);
|
||||
|
||||
-321
@@ -9,170 +9,6 @@
|
||||
#include "milo/dtoa_milo.h"
|
||||
#include "text.hpp"
|
||||
|
||||
static std::string mvt_value_to_string(mvt_value const &one, bool &fail, std::vector<std::string> const &unidecode_data) {
|
||||
switch (one.type) {
|
||||
case mvt_string:
|
||||
if (unidecode_data.size() > 0) {
|
||||
return unidecode_smash(unidecode_data, one.c_str());
|
||||
} else {
|
||||
return one.get_string_value();
|
||||
}
|
||||
case mvt_float:
|
||||
return milo::dtoa_milo(one.numeric_value.float_value);
|
||||
case mvt_double:
|
||||
return milo::dtoa_milo(one.numeric_value.double_value);
|
||||
case mvt_int:
|
||||
return std::to_string(one.numeric_value.int_value);
|
||||
case mvt_uint:
|
||||
return std::to_string(one.numeric_value.uint_value);
|
||||
case mvt_sint:
|
||||
return std::to_string(one.numeric_value.sint_value);
|
||||
case mvt_bool:
|
||||
return one.numeric_value.bool_value ? "true" : "false";
|
||||
case mvt_null:
|
||||
fail = true; // null op string => null
|
||||
return "";
|
||||
case mvt_no_such_key:
|
||||
default:
|
||||
fprintf(stderr, "unhandled mvt_type %d\n", one.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
}
|
||||
|
||||
// Alter the JSON parse tree in place to replace the original match string
|
||||
// with its unidecode-smashed version.
|
||||
//
|
||||
// To avoid repeated re-smashings of the same JSON object, objects that have
|
||||
// already been smashed are marked by setting their refcon to the unidecode data.
|
||||
static void smash(std::vector<std::string> const &unidecode_data, json_object *j) {
|
||||
if (j->value.string.refcon == (void *) &unidecode_data) {
|
||||
return;
|
||||
}
|
||||
|
||||
std::string s = unidecode_smash(unidecode_data, j->value.string.string);
|
||||
j->value.string.string = (char *) realloc(j->value.string.string, s.size() + 1);
|
||||
if (j->value.string.string == NULL) {
|
||||
perror("realloc for unidecode_smash");
|
||||
exit(EXIT_MEMORY);
|
||||
}
|
||||
strcpy(j->value.string.string, s.c_str());
|
||||
j->value.string.refcon = (void *) &unidecode_data;
|
||||
}
|
||||
|
||||
int compare_fsl(mvt_value const &one, json_object *two, bool &fail, std::vector<std::string> const &unidecode_data) {
|
||||
// In FSL expressions, the attribute value is coerced to the type
|
||||
// of the JSON literal value it is being compared to.
|
||||
//
|
||||
// If it cannot be converted, the comparison returns null
|
||||
// (which is distinct from true and false but is falsy if
|
||||
// it is the final output value).
|
||||
|
||||
if (two->type == JSON_NULL) {
|
||||
fail = true; // anything op null => null
|
||||
return 0;
|
||||
}
|
||||
|
||||
if (two->type == JSON_NUMBER) {
|
||||
double lhs;
|
||||
|
||||
switch (one.type) {
|
||||
case mvt_string: {
|
||||
char *endptr = NULL;
|
||||
const char *s = one.c_str();
|
||||
lhs = strtod(s, &endptr);
|
||||
if (endptr == s) {
|
||||
fail = true; // non-numeric-string op number => null
|
||||
return 0;
|
||||
}
|
||||
} break;
|
||||
case mvt_float:
|
||||
lhs = one.numeric_value.float_value;
|
||||
break;
|
||||
case mvt_double:
|
||||
lhs = one.numeric_value.double_value;
|
||||
break;
|
||||
case mvt_int:
|
||||
lhs = one.numeric_value.int_value;
|
||||
break;
|
||||
case mvt_uint:
|
||||
lhs = one.numeric_value.uint_value;
|
||||
break;
|
||||
case mvt_sint:
|
||||
lhs = one.numeric_value.sint_value;
|
||||
break;
|
||||
case mvt_bool:
|
||||
lhs = one.numeric_value.bool_value;
|
||||
break;
|
||||
case mvt_null:
|
||||
fail = true; // null op number => null
|
||||
return 0;
|
||||
default:
|
||||
fprintf(stderr, "unhandled mvt_type %d\n", one.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
if (lhs < two->value.number.number) {
|
||||
return -1;
|
||||
} else if (lhs > two->value.number.number) {
|
||||
return 1;
|
||||
} else {
|
||||
return 0;
|
||||
}
|
||||
}
|
||||
|
||||
if (two->type == JSON_STRING) {
|
||||
std::string lhs = mvt_value_to_string(one, fail, unidecode_data);
|
||||
|
||||
if (unidecode_data.size() > 0) {
|
||||
smash(unidecode_data, two);
|
||||
}
|
||||
|
||||
return strcmp(lhs.c_str(), two->value.string.string);
|
||||
}
|
||||
|
||||
if (two->type == JSON_TRUE || two->type == JSON_FALSE) {
|
||||
bool lhs;
|
||||
|
||||
switch (one.type) {
|
||||
case mvt_string:
|
||||
lhs = one.get_string_view().size() > 0;
|
||||
break;
|
||||
case mvt_float:
|
||||
lhs = one.numeric_value.float_value != 0;
|
||||
break;
|
||||
case mvt_double:
|
||||
lhs = one.numeric_value.double_value != 0;
|
||||
break;
|
||||
case mvt_int:
|
||||
lhs = one.numeric_value.int_value != 0;
|
||||
break;
|
||||
case mvt_uint:
|
||||
lhs = one.numeric_value.uint_value != 0;
|
||||
break;
|
||||
case mvt_sint:
|
||||
lhs = one.numeric_value.sint_value != 0;
|
||||
break;
|
||||
case mvt_bool:
|
||||
lhs = one.numeric_value.bool_value;
|
||||
break;
|
||||
case mvt_null:
|
||||
fail = true; // null op bool => null
|
||||
return 0;
|
||||
|
||||
case mvt_no_such_key:
|
||||
default:
|
||||
fprintf(stderr, "unhandled mvt_type %d\n", one.type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
bool rhs = two->type == JSON_TRUE;
|
||||
return lhs - rhs;
|
||||
}
|
||||
|
||||
fprintf(stderr, "unhandled JSON type %d\n", two->type);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
int compare(mvt_value const &one, json_object *two, bool &fail) {
|
||||
switch (one.type) {
|
||||
case mvt_string:
|
||||
@@ -292,163 +128,6 @@ static int eval(std::function<mvt_value(std::string const &)> feature, json_obje
|
||||
exit(EXIT_FILTER);
|
||||
}
|
||||
|
||||
// FSL conjunctions
|
||||
if (f->value.array.length == 3 &&
|
||||
f->value.array.array[1]->type == JSON_STRING &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "or") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "and") == 0)) {
|
||||
int lhs;
|
||||
|
||||
if (f->value.array.array[0]->type == JSON_STRING) {
|
||||
// if LHS of a boolean conjunction is a string, it is an attribute reference
|
||||
mvt_value ff = feature(std::string(f->value.array.array[0]->value.string.string));
|
||||
if (ff.type != mvt_no_such_key) {
|
||||
if (ff.type == mvt_bool) {
|
||||
lhs = ff.numeric_value.bool_value;
|
||||
} else {
|
||||
lhs = -1; // not boolean: null
|
||||
}
|
||||
} else {
|
||||
lhs = -1; // not found: null
|
||||
}
|
||||
} else {
|
||||
lhs = eval(feature, f->value.array.array[0], exclude_attributes, unidecode_data);
|
||||
}
|
||||
|
||||
int rhs = eval(feature, f->value.array.array[2], exclude_attributes, unidecode_data);
|
||||
if (lhs < 0 && rhs < 0) {
|
||||
return -1; // null op null => null
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "or") == 0) {
|
||||
return (lhs > 0) || (rhs > 0);
|
||||
} else {
|
||||
return (lhs > 0) && (rhs > 0);
|
||||
}
|
||||
}
|
||||
|
||||
// FSL comparators
|
||||
if (f->value.array.length == 3 &&
|
||||
f->value.array.array[0]->type == JSON_STRING &&
|
||||
f->value.array.array[1]->type == JSON_STRING &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "lt") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "gt") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "le") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ge") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "eq") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ne") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "cn") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "nc") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "in") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ni") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "is") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "isnt") == 0 ||
|
||||
false)) {
|
||||
mvt_value lhs = feature(std::string(f->value.array.array[0]->value.string.string));
|
||||
if (lhs.type == mvt_no_such_key) {
|
||||
lhs.type = mvt_null;
|
||||
}
|
||||
|
||||
if (f->value.array.array[2]->type == JSON_NULL && strcmp(f->value.array.array[1]->value.string.string, "is") == 0) {
|
||||
return lhs.type == mvt_null; // null is null => true, anything is null => false
|
||||
}
|
||||
if (f->value.array.array[2]->type == JSON_NULL && strcmp(f->value.array.array[1]->value.string.string, "isnt") == 0) {
|
||||
return lhs.type != mvt_null; // null isnt null => false, anything isnt null => true
|
||||
}
|
||||
|
||||
bool fail = false;
|
||||
|
||||
if (f->value.array.array[2]->type == JSON_STRING &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "cn") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "nc") == 0)) {
|
||||
if (lhs.type == mvt_null) {
|
||||
return -1; // null cn/nc anything => null
|
||||
}
|
||||
|
||||
std::string s = mvt_value_to_string(lhs, fail, unidecode_data);
|
||||
if (fail) {
|
||||
return -1; // null cn anything => false
|
||||
}
|
||||
|
||||
bool contains;
|
||||
if (unidecode_data.size() > 0) {
|
||||
smash(unidecode_data, f->value.array.array[2]);
|
||||
}
|
||||
contains = strstr(s.c_str(), f->value.array.array[2]->value.string.string);
|
||||
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "cn") == 0) {
|
||||
return contains;
|
||||
} else {
|
||||
return !contains;
|
||||
}
|
||||
}
|
||||
|
||||
if (f->value.array.array[2]->type == JSON_ARRAY &&
|
||||
(strcmp(f->value.array.array[1]->value.string.string, "in") == 0 ||
|
||||
strcmp(f->value.array.array[1]->value.string.string, "ni") == 0)) {
|
||||
// no null check here, since null can be in or not in
|
||||
|
||||
bool contains = false;
|
||||
for (size_t i = 0; i < f->value.array.array[2]->value.array.length; i++) {
|
||||
if (lhs.type == mvt_null) {
|
||||
if (f->value.array.array[2]->value.array.array[i]->type == JSON_NULL) {
|
||||
contains = true; // null is null
|
||||
break;
|
||||
} else {
|
||||
contains = false; // null isnt non-null
|
||||
}
|
||||
} else {
|
||||
fail = false;
|
||||
static std::vector<std::string> no_unidecode_data;
|
||||
int cmp = compare_fsl(lhs, f->value.array.array[2]->value.array.array[i], fail, no_unidecode_data);
|
||||
|
||||
if (fail) {
|
||||
contains = false; // non-null isnt null
|
||||
} else if (cmp == 0) {
|
||||
contains = true;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "in") == 0) {
|
||||
return contains;
|
||||
} else {
|
||||
return !contains;
|
||||
}
|
||||
}
|
||||
|
||||
if (lhs.type == mvt_null) {
|
||||
return -1; // null compared to anything => null
|
||||
}
|
||||
|
||||
int cmp = compare_fsl(lhs, f->value.array.array[2], fail, unidecode_data);
|
||||
if (fail) {
|
||||
return -1; // null
|
||||
}
|
||||
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "eq") == 0) {
|
||||
return cmp == 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "ne") == 0) {
|
||||
return cmp != 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "gt") == 0) {
|
||||
return cmp > 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "ge") == 0) {
|
||||
return cmp >= 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "lt") == 0) {
|
||||
return cmp < 0;
|
||||
}
|
||||
if (strcmp(f->value.array.array[1]->value.string.string, "le") == 0) {
|
||||
return cmp <= 0;
|
||||
}
|
||||
|
||||
fprintf(stderr, "expression fsl comparison: can't happen %s\n", f->value.array.array[1]->value.string.string);
|
||||
exit(EXIT_IMPOSSIBLE);
|
||||
}
|
||||
|
||||
if (f->value.array.array[0]->type != JSON_STRING) {
|
||||
fprintf(stderr, "Filter operation is not a string: %s\n", json_stringify(f));
|
||||
exit(EXIT_FILTER);
|
||||
|
||||
+10
-10
@@ -163,13 +163,13 @@ void readFeature(const FlatGeobuf::Feature *feature, long long feature_sequence_
|
||||
|
||||
serial_val sv;
|
||||
if (col_type == FlatGeobuf::ColumnType_Byte) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int8_t byte_val;
|
||||
memcpy(&byte_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(byte_val));
|
||||
sv.s = std::to_string(byte_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(byte_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_UByte) {
|
||||
sv.type = mvt_uint;
|
||||
sv.type = mvt_double;
|
||||
uint8_t ubyte_val;
|
||||
memcpy(&ubyte_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(ubyte_val));
|
||||
sv.s = std::to_string(ubyte_val);
|
||||
@@ -185,43 +185,43 @@ void readFeature(const FlatGeobuf::Feature *feature, long long feature_sequence_
|
||||
}
|
||||
p_pos += sizeof(uint16_t) + sizeof(bool_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Short) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int16_t short_val;
|
||||
memcpy(&short_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(short_val));
|
||||
sv.s = std::to_string(short_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(short_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_UShort) {
|
||||
sv.type = mvt_uint;
|
||||
sv.type = mvt_double;
|
||||
uint16_t ushort_val;
|
||||
memcpy(&ushort_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(ushort_val));
|
||||
sv.s = std::to_string(ushort_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(ushort_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Int) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int32_t int_val;
|
||||
memcpy(&int_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(int_val));
|
||||
sv.s = std::to_string(int_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(int_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_UInt) {
|
||||
sv.type = mvt_uint;
|
||||
sv.type = mvt_double;
|
||||
uint32_t uint_val;
|
||||
memcpy(&uint_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(uint_val));
|
||||
sv.s = std::to_string(uint_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(uint_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Long) {
|
||||
sv.type = mvt_sint;
|
||||
sv.type = mvt_double;
|
||||
int64_t long_val;
|
||||
memcpy(&long_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(long_val));
|
||||
sv.s = std::to_string(long_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(long_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_ULong) {
|
||||
sv.type = mvt_uint;
|
||||
int64_t ulong_val;
|
||||
sv.type = mvt_double;
|
||||
uint64_t ulong_val;
|
||||
memcpy(&ulong_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(ulong_val));
|
||||
sv.s = std::to_string(ulong_val);
|
||||
p_pos += sizeof(uint16_t) + sizeof(ulong_val);
|
||||
} else if (col_type == FlatGeobuf::ColumnType_Float) {
|
||||
sv.type = mvt_float;
|
||||
sv.type = mvt_double;
|
||||
float float_val;
|
||||
memcpy(&float_val, feature->properties()->data() + p_pos + sizeof(uint16_t), sizeof(float_val));
|
||||
sv.s = milo::dtoa_milo(float_val);
|
||||
|
||||
@@ -1,2 +0,0 @@
|
||||
*.zip
|
||||
tmp/*
|
||||
@@ -1,34 +0,0 @@
|
||||
# Build the tippecanoe layer (binary)
|
||||
|
||||
1. On an AWS Linux 2 instance or image:
|
||||
|
||||
sudo yum update
|
||||
sudo yum install git clang sqlite-devel zlib-devel
|
||||
|
||||
2. Create a ZIP archive with the `tippecanoe` binary at `bin/tippecanoe` and upload as a Lambda layer
|
||||
3. Copy [lambda_function.py](lambda_function.py) (python 3.9 runtime)
|
||||
4. set the environment variable `OUTPUT_BUCKET` to your output bucket; give lambda IAM role access to input/output buckets
|
||||
5. Enable ACLs on the output bucket
|
||||
|
||||
```json
|
||||
{
|
||||
"Version": "2012-10-17",
|
||||
"Statement": [
|
||||
{
|
||||
"Sid": "AllowGet",
|
||||
"Effect": "Allow",
|
||||
"Action": "s3:GetObject",
|
||||
"Resource": "arn:aws:s3:::protomaps-tippecanoe-test/*"
|
||||
},
|
||||
{
|
||||
"Sid": "AllowPut",
|
||||
"Effect": "Allow",
|
||||
"Action": [
|
||||
"s3:PutObject",
|
||||
"s3:PutObjectAcl"
|
||||
],
|
||||
"Resource": "arn:aws:s3:::protomaps-tippecanoe-test-output/*"
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
@@ -1,2 +0,0 @@
|
||||
boto3==1.20.32
|
||||
botocore==1.23.32
|
||||
@@ -1,49 +0,0 @@
|
||||
import os
|
||||
import json
|
||||
import subprocess
|
||||
import sys
|
||||
import boto3
|
||||
from botocore import UNSIGNED
|
||||
from botocore.config import Config
|
||||
|
||||
# if the input bucket is publicly readable
|
||||
#s3 = boto3.client('s3',config=Config(signature_version=UNSIGNED))
|
||||
|
||||
def lambda_handler(event, context):
|
||||
bucket_name = event['Records'][0]['s3']['bucket']['name']
|
||||
input_key = event['Records'][0]['s3']['object']['key']
|
||||
tmpdir = '/tmp'
|
||||
run_tippecanoe('tippecanoe',tmpdir,bucket_name, input_key)
|
||||
return {
|
||||
'statusCode': 200,
|
||||
'body': json.dumps('Done!')
|
||||
}
|
||||
|
||||
# input formats: "geojsonseq", "fgb", "geobuf", "geojson", "csv"
|
||||
def split_key(key):
|
||||
if key.endswith(".gz"):
|
||||
root, ext = os.path.splitext(key[0:-3])
|
||||
return root, ext + ".gz"
|
||||
else:
|
||||
return os.path.splitext(key)
|
||||
|
||||
def run_tippecanoe(executable, tmpdir, bucket_name, input_key):
|
||||
s3 = boto3.client('s3')
|
||||
root, ext = split_key(input_key)
|
||||
input_path = os.path.join(tmpdir,'input' + ext)
|
||||
output_path = os.path.join(tmpdir,'output.mbtiles')
|
||||
s3.download_file(bucket_name,input_key,input_path)
|
||||
p = subprocess.Popen([executable,'-o',output_path,input_path,'--force','-u','-U','5'],stderr=subprocess.PIPE)
|
||||
for line in p.stderr:
|
||||
try:
|
||||
j = json.loads(line)
|
||||
s3.put_object(Body=json.dumps(j),Bucket=os.environ['OUTPUT_BUCKET'],Key=root + ".progress",ACL="public-read",ContentType="application/json",ContentDisposition="inline")
|
||||
except json.decoder.JSONDecodeError:
|
||||
pass
|
||||
s3.upload_file(output_path,os.environ['OUTPUT_BUCKET'],root + ".mbtiles")
|
||||
|
||||
if __name__ == "__main__":
|
||||
tmpdir = 'tmp'
|
||||
bucket_name = sys.argv[1]
|
||||
input_key = sys.argv[2]
|
||||
run_tippecanoe('../tippecanoe', tmpdir, bucket_name, input_key)
|
||||
@@ -1,26 +0,0 @@
|
||||
from tippecanoe import split_key
|
||||
import unittest
|
||||
|
||||
class TestTippecanoe(unittest.TestCase):
|
||||
def test_basic(self):
|
||||
root, ext = split_key("file.json")
|
||||
self.assertEqual(root,"file")
|
||||
self.assertEqual(ext,".json")
|
||||
|
||||
def test_basic_gz(self):
|
||||
root, ext = split_key("file.csv.gz")
|
||||
self.assertEqual(root,"file")
|
||||
self.assertEqual(ext,".csv.gz")
|
||||
|
||||
def test_nested_key(self):
|
||||
root, ext = split_key("dir/file.fgb")
|
||||
self.assertEqual(root,"dir/file")
|
||||
self.assertEqual(ext,".fgb")
|
||||
|
||||
def test_nested_key_gz(self):
|
||||
root, ext = split_key("dir/file.geojsonseq.gz")
|
||||
self.assertEqual(root,"dir/file")
|
||||
self.assertEqual(ext,".geojsonseq.gz")
|
||||
|
||||
if __name__ == '__main__':
|
||||
unittest.main()
|
||||
@@ -98,8 +98,9 @@ long long extend_zooms_max = 0;
|
||||
int retain_points_multiplier = 1;
|
||||
std::vector<std::string> unidecode_data;
|
||||
size_t maximum_string_attribute_length = 0;
|
||||
std::string accumulate_numeric;
|
||||
const char *tmpdir = "/tmp";
|
||||
std::string drop_by_attribute_as_needed_attribute;
|
||||
bool drop_by_attribute_descending = false;
|
||||
|
||||
std::vector<order_field> order_by;
|
||||
bool order_reverse;
|
||||
@@ -2020,7 +2021,7 @@ std::pair<int, metadata> read_input(std::vector<source> &sources, char *fname, i
|
||||
vertex_readers.push_back(readers[i].vertexfile);
|
||||
rewind(readers[i].vertexfile);
|
||||
}
|
||||
fqsort(vertex_readers, sizeof(vertex), vertexcmp, vertex_out, memsize / 20);
|
||||
fqsort(vertex_readers, sizeof(vertex), vertexcmp, vertex_out, memsize / 20, tmpdir);
|
||||
|
||||
for (size_t i = 0; i < CPUS; i++) {
|
||||
if (fclose(readers[i].vertexfile) != 0) {
|
||||
@@ -2089,7 +2090,7 @@ std::pair<int, metadata> read_input(std::vector<source> &sources, char *fname, i
|
||||
rewind(readers[i].nodefile);
|
||||
}
|
||||
|
||||
fqsort(node_readers, sizeof(node), nodecmp, node_out, memsize / 20);
|
||||
fqsort(node_readers, sizeof(node), nodecmp, node_out, memsize / 20, tmpdir);
|
||||
|
||||
for (size_t i = 0; i < CPUS; i++) {
|
||||
if (fclose(readers[i].nodefile) != 0) {
|
||||
@@ -2756,7 +2757,7 @@ std::pair<int, metadata> read_input(std::vector<source> &sources, char *fname, i
|
||||
std::atomic<unsigned> midx(0);
|
||||
std::atomic<unsigned> midy(0);
|
||||
std::vector<strategy> strategies;
|
||||
int written = traverse_zooms(fd, size, stringpool, &midx, &midy, maxzoom, minzoom, outdb, outdir, buffer, fname, gamma, full_detail, low_detail, min_detail, pool_off, initial_x, initial_y, simplification, maxzoom_simplification, layermaps, prefilter, postfilter, attribute_accum, filter, strategies, iz, shared_nodes_map, nodepos, shared_nodes_bloom, basezoom, droprate, unidecode_data);
|
||||
int written = traverse_zooms(fd, size, stringpool, &midx, &midy, maxzoom, minzoom, outdb, outdir, buffer, fname, gamma, full_detail, low_detail, min_detail, pool_off, initial_x, initial_y, simplification, maxzoom_simplification, layermaps, prefilter, postfilter, attribute_accum, filter, strategies, iz, shared_nodes_map, nodepos, shared_nodes_bloom, basezoom, droprate, unidecode_data, &drop_by_attribute_as_needed_attribute, drop_by_attribute_descending);
|
||||
|
||||
if (maxzoom != written) {
|
||||
if (written > minzoom) {
|
||||
@@ -3062,7 +3063,6 @@ int main(int argc, char **argv) {
|
||||
{"attribute-type", required_argument, 0, 'T'},
|
||||
{"attribute-description", required_argument, 0, 'Y'},
|
||||
{"accumulate-attribute", required_argument, 0, 'E'},
|
||||
{"accumulate-numeric-attributes", required_argument, 0, '~'},
|
||||
{"empty-csv-columns-are-null", no_argument, &prevent[P_EMPTY_CSV_COLUMNS], 1},
|
||||
{"convert-stringified-ids-to-numbers", no_argument, &additional[A_CONVERT_NUMERIC_IDS], 1},
|
||||
{"use-attribute-for-id", required_argument, 0, '~'},
|
||||
@@ -3092,6 +3092,8 @@ int main(int argc, char **argv) {
|
||||
{"drop-densest-as-needed", no_argument, &additional[A_DROP_DENSEST_AS_NEEDED], 1},
|
||||
{"drop-fraction-as-needed", no_argument, &additional[A_DROP_FRACTION_AS_NEEDED], 1},
|
||||
{"drop-smallest-as-needed", no_argument, &additional[A_DROP_SMALLEST_AS_NEEDED], 1},
|
||||
{"drop-by-attribute-as-needed", required_argument, 0, '~'},
|
||||
{"drop-by-attribute-order", required_argument, 0, '~'},
|
||||
{"coalesce-densest-as-needed", no_argument, &additional[A_COALESCE_DENSEST_AS_NEEDED], 1},
|
||||
{"coalesce-fraction-as-needed", no_argument, &additional[A_COALESCE_FRACTION_AS_NEEDED], 1},
|
||||
{"coalesce-smallest-as-needed", no_argument, &additional[A_COALESCE_SMALLEST_AS_NEEDED], 1},
|
||||
@@ -3281,6 +3283,22 @@ int main(int argc, char **argv) {
|
||||
} else if (strcmp(opt, "order-largest-first") == 0) {
|
||||
order_by.push_back(order_field(ORDER_BY_SIZE, true));
|
||||
order_by_size = true;
|
||||
} else if (strcmp(opt, "drop-by-attribute-as-needed") == 0) {
|
||||
if (optarg[0] == '\0') {
|
||||
fprintf(stderr, "%s: --drop-by-attribute-as-needed requires a non-empty attribute name\n", argv[0]);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
drop_by_attribute_as_needed_attribute = optarg;
|
||||
additional[A_DROP_BY_ATTRIBUTE_AS_NEEDED] = 1;
|
||||
} else if (strcmp(opt, "drop-by-attribute-order") == 0) {
|
||||
if (strcmp(optarg, "asc") == 0) {
|
||||
drop_by_attribute_descending = false;
|
||||
} else if (strcmp(optarg, "desc") == 0) {
|
||||
drop_by_attribute_descending = true;
|
||||
} else {
|
||||
fprintf(stderr, "%s: %s: order must be one of: asc, desc\n", argv[0], optarg);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
} else if (strcmp(opt, "simplification-at-maximum-zoom") == 0) {
|
||||
maxzoom_simplification = atof_require(optarg, "Mazoom simplification");
|
||||
if (maxzoom_simplification <= 0) {
|
||||
@@ -3310,8 +3328,6 @@ int main(int argc, char **argv) {
|
||||
unidecode_data = read_unidecode(optarg);
|
||||
} else if (strcmp(opt, "maximum-string-attribute-length") == 0) {
|
||||
maximum_string_attribute_length = atoll_require(optarg, "Maximum string attribute length");
|
||||
} else if (strcmp(opt, "accumulate-numeric-attributes") == 0) {
|
||||
accumulate_numeric = optarg;
|
||||
} else {
|
||||
fprintf(stderr, "%s: Unrecognized option --%s\n", argv[0], opt);
|
||||
exit(EXIT_ARGS);
|
||||
@@ -3804,6 +3820,11 @@ int main(int argc, char **argv) {
|
||||
check_dir(out_dir, argv, force, forcetable);
|
||||
}
|
||||
|
||||
if (additional[A_DROP_BY_ATTRIBUTE_AS_NEEDED] && drop_by_attribute_as_needed_attribute.empty()) {
|
||||
fprintf(stderr, "%s: --drop-by-attribute-as-needed requires an attribute name\n", argv[0]);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
|
||||
int ret = EXIT_SUCCESS;
|
||||
|
||||
for (i = optind; i < argc; i++) {
|
||||
|
||||
@@ -52,7 +52,6 @@ extern std::map<std::string, serial_val> set_attributes;
|
||||
extern long long extend_zooms_max;
|
||||
extern int retain_points_multiplier;
|
||||
extern size_t maximum_string_attribute_length;
|
||||
extern std::string accumulate_numeric;
|
||||
extern unsigned long long preserve_multiplier_density_threshold;
|
||||
extern const char *tmpdir;
|
||||
|
||||
|
||||
+3
-5
@@ -20,7 +20,7 @@ something that looks like "All Streets \[la]http://benfry.com/allstreets/map5.ht
|
||||
rather than something that looks like an Interstate road atlas.
|
||||
.PP
|
||||
If you give it all the building footprints in Los Angeles and zoom out
|
||||
far enough that most individual buildings are no longer discernable, you
|
||||
far enough that most individual buildings are no longer discernible, you
|
||||
should still be able to see the extent and variety of development in every neighborhood,
|
||||
not just the largest downtown buildings.
|
||||
.PP
|
||||
@@ -520,8 +520,6 @@ that are dropped, coalesced\-as\-needed, or clustered. The \fIoperation\fP may b
|
||||
to specify how the named \fIattribute\fP is accumulated onto the attribute of the same name in a feature that does survive.
|
||||
The attributes and operations may also be specified as JSON keys and values: \fB\fC\-\-accumulate\-attribute='{"attr": "operation", "attr2": "operation2"}'\fR\&.
|
||||
.IP \(bu 2
|
||||
\fB\fC\-\-accumulate\-numeric\-attributes\fR \fIprefix\fP: Accumulate sum, count, min, and max for all numeric attributes into new attributes with the specified \fIprefix\fP\&.
|
||||
.IP \(bu 2
|
||||
\fB\fC\-\-set\-attribute\fR \fIattribute\fP\fB\fC:\fR\fIvalue\fP: Set the value of the specified \fIattribute\fP in each feature to the specified \fIvalue\fP\&. This is mostly useful to give an attribute in each feature an initial value for \fB\fC\-\-accumulate\-attribute\fR\&.
|
||||
The attributes and values may also be specified as JSON keys and values: \fB\fC\-\-set\-attribute='{"attr": value, "attr2": value}'\fR\&.
|
||||
.IP \(bu 2
|
||||
@@ -607,7 +605,7 @@ preference to retaining points in sparse areas and dropping points in dense area
|
||||
.IP \(bu 2
|
||||
\fB\fC\-\-keep\-point\-cluster\-position\fR: Do not average the location of points as they are clustered.
|
||||
.IP \(bu 2
|
||||
\fB\fC\-\-preserve\-point\-density\-threshold=\fR\fIlevel\fP: At the low zoom levels, do not reduce point density below the specified \fIlevel\fP, even if the specfied drop rate would normally call for it, so that low\-density areas of the map do not appear blank. The unit is the distance between preserved points, as a fraction of the size of a tile. Values of 32 or 64 are probably appropriate for typical marker sizes.
|
||||
\fB\fC\-\-preserve\-point\-density\-threshold=\fR\fIlevel\fP: At the low zoom levels, do not reduce point density below the specified \fIlevel\fP, even if the specified drop rate would normally call for it, so that low\-density areas of the map do not appear blank. The unit is the distance between preserved points, as a fraction of the size of a tile. Values of 32 or 64 are probably appropriate for typical marker sizes.
|
||||
.IP \(bu 2
|
||||
\fB\fC\-\-preserve\-multiplier\-density\-threshold=\fR\fIlevel\fP: Preserve a minimum point density, but as \fB\fC\-\-retain\-points\-multiplier\fR features, not primary features.
|
||||
.RE
|
||||
@@ -846,7 +844,7 @@ If you have a feature like this:
|
||||
.fi
|
||||
.RE
|
||||
.PP
|
||||
with a \fB\fCtippecanoe\fR object specifiying a \fB\fCmaxzoom\fR of 9 and a \fB\fCminzoom\fR of 4, the feature
|
||||
with a \fB\fCtippecanoe\fR object specifying a \fB\fCmaxzoom\fR of 9 and a \fB\fCminzoom\fR of 4, the feature
|
||||
will only appear in the vector tiles for zoom levels 4 through 9. Note that the \fB\fCtippecanoe\fR
|
||||
object belongs to the Feature, not to its \fB\fCproperties\fR\&. If you specify a \fB\fCminzoom\fR for a feature,
|
||||
it will be preserved down to that zoom level even if dot\-dropping with \fB\fC\-r\fR would otherwise have
|
||||
|
||||
@@ -407,7 +407,8 @@ std::string mvt_tile::encode() {
|
||||
std::string feature_string;
|
||||
protozero::pbf_writer feature_writer(feature_string);
|
||||
|
||||
feature_writer.add_enum(3, layers[i].features[f].type);
|
||||
if (layers[i].features[f].type >= 0)
|
||||
feature_writer.add_enum(3, layers[i].features[f].type);
|
||||
|
||||
std::vector<unsigned> sorted_tags = layers[i].features[f].tags;
|
||||
for (size_t v = 1; v < sorted_tags.size(); v += 2) {
|
||||
|
||||
@@ -30,6 +30,7 @@
|
||||
#define A_DETECT_WRAPAROUND ((int) 'w')
|
||||
#define A_KEEP_POINT_CLUSTER_POSITION ((int) 'a')
|
||||
#define A_DISTINGUISH_DUPLICATES ((int) 'u')
|
||||
#define A_DROP_BY_ATTRIBUTE_AS_NEEDED ((int) 'A')
|
||||
|
||||
#define P_TILE_COMPRESSION ((int) 'C')
|
||||
#define P_DUPLICATION ((int) 'D')
|
||||
|
||||
+2
-99
@@ -25,13 +25,10 @@ std::string filter;
|
||||
bool preserve_input_order = false;
|
||||
std::unordered_map<std::string, attribute_op> attribute_accum;
|
||||
std::vector<std::string> unidecode_data;
|
||||
std::vector<mvt_layer> bins;
|
||||
std::string accumulate_numeric;
|
||||
|
||||
std::set<std::string> keep;
|
||||
std::set<std::string> exclude;
|
||||
std::vector<std::string> exclude_prefix;
|
||||
std::vector<clipbbox> clipbboxes;
|
||||
|
||||
void usage(char **argv) {
|
||||
fprintf(stderr, "Usage: %s -o newtile.pbf.gz tile.pbf.gz oz/ox/oy nz/nx/ny\n", argv[0]);
|
||||
@@ -67,8 +64,6 @@ int main(int argc, char **argv) {
|
||||
const char *outfile = NULL;
|
||||
double simplification = 0;
|
||||
double tiny_polygon_size = 0;
|
||||
std::string assign_to_bins;
|
||||
std::string bin_by_id_list;
|
||||
|
||||
std::vector<input_tile> sources;
|
||||
|
||||
@@ -88,13 +83,7 @@ int main(int argc, char **argv) {
|
||||
{"line-simplification", required_argument, 0, 'S'},
|
||||
{"tiny-polygon-size", required_argument, 0, 's' & 0x1F},
|
||||
{"source-tile", required_argument, 0, 't'},
|
||||
{"assign-to-bins", required_argument, 0, 'b' & 0x1F},
|
||||
{"bin-by-id-list", required_argument, 0, 'c' & 0x1F},
|
||||
{"accumulate-numeric-attributes", required_argument, 0, 'a' & 0x1F},
|
||||
{"no-tile-compression", no_argument, 0, 'd' & 0x1F},
|
||||
{"clip-bounding-box", required_argument, 0, 'k' & 0x1F},
|
||||
{"clip-polygon", required_argument, 0, 'l' & 0x1F},
|
||||
{"clip-polygon-file", required_argument, 0, 'm' & 0x1F},
|
||||
{"deduplicate-by-id", no_argument, 0, 'i' & 0x1F},
|
||||
|
||||
{0, 0, 0, 0},
|
||||
@@ -174,47 +163,10 @@ int main(int argc, char **argv) {
|
||||
simplification = atof(optarg);
|
||||
break;
|
||||
|
||||
case 'b' & 0x1F:
|
||||
assign_to_bins = optarg;
|
||||
break;
|
||||
|
||||
case 'c' & 0x1F:
|
||||
bin_by_id_list = optarg;
|
||||
break;
|
||||
|
||||
case 'a' & 0x1F:
|
||||
accumulate_numeric = optarg;
|
||||
break;
|
||||
|
||||
case 'd' & 0x1F:
|
||||
do_compress = false;
|
||||
break;
|
||||
|
||||
case 'k' & 0x1F: {
|
||||
clipbbox clip;
|
||||
if (sscanf(optarg, "%lf,%lf,%lf,%lf", &clip.lon1, &clip.lat1, &clip.lon2, &clip.lat2) == 4) {
|
||||
projection->project(clip.lon1, clip.lat1, 32, &clip.minx, &clip.maxy);
|
||||
projection->project(clip.lon2, clip.lat2, 32, &clip.maxx, &clip.miny);
|
||||
clipbboxes.push_back(clip);
|
||||
} else {
|
||||
fprintf(stderr, "%s: Can't parse bounding box --clip-bounding-box=%s\n", argv[0], optarg);
|
||||
exit(EXIT_ARGS);
|
||||
}
|
||||
break;
|
||||
}
|
||||
|
||||
case 'l' & 0x1F: {
|
||||
clipbbox clip = parse_clip_poly(optarg);
|
||||
clipbboxes.push_back(clip);
|
||||
break;
|
||||
}
|
||||
|
||||
case 'm' & 0x1F: {
|
||||
clipbbox clip = parse_clip_poly(read_json_file(optarg));
|
||||
clipbboxes.push_back(clip);
|
||||
break;
|
||||
}
|
||||
|
||||
case 'i' & 0x1F: {
|
||||
deduplicate_by_id = true;
|
||||
break;
|
||||
@@ -283,58 +235,9 @@ int main(int argc, char **argv) {
|
||||
}
|
||||
}
|
||||
|
||||
if (assign_to_bins.size() != 0) {
|
||||
FILE *f = fopen(assign_to_bins.c_str(), "r");
|
||||
if (f == NULL) {
|
||||
perror(assign_to_bins.c_str());
|
||||
exit(EXIT_OPEN);
|
||||
}
|
||||
|
||||
int det = detail;
|
||||
if (det < 0) {
|
||||
det = 12;
|
||||
}
|
||||
bins = parse_layers(f, nz, nx, ny, 1LL << det, true);
|
||||
fclose(f);
|
||||
}
|
||||
|
||||
// clip the clip polygons, if any, to the tile bounds,
|
||||
// to reduce their complexity
|
||||
|
||||
bool clipped_to_nothing = false;
|
||||
if (clipbboxes.size() > 0) {
|
||||
long long wx1 = (nx - buffer / 256.0) * (1LL << (32 - nz));
|
||||
long long wy1 = (ny - buffer / 256.0) * (1LL << (32 - nz));
|
||||
long long wx2 = (nx + 1 + buffer / 256.0) * (1LL << (32 - nz));
|
||||
long long wy2 = (ny + 1 + buffer / 256.0) * (1LL << (32 - nz));
|
||||
|
||||
drawvec tile_bounds;
|
||||
tile_bounds.emplace_back(VT_MOVETO, wx1, wy1);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx2, wy1);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx2, wy2);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx1, wy2);
|
||||
tile_bounds.emplace_back(VT_LINETO, wx1, wy1);
|
||||
|
||||
for (auto &c : clipbboxes) {
|
||||
c.minx = std::max(c.minx, wx1);
|
||||
c.miny = std::max(c.miny, wy1);
|
||||
c.maxx = std::min(c.maxx, wx2);
|
||||
c.maxy = std::min(c.maxy, wy2);
|
||||
|
||||
if (c.dv.size() > 0) {
|
||||
c.dv = clip_poly_poly(c.dv, tile_bounds);
|
||||
|
||||
if (c.dv.size() == 0) {
|
||||
clipped_to_nothing = true;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
std::string out;
|
||||
|
||||
if (!clipped_to_nothing) {
|
||||
{
|
||||
json_object *json_filter = NULL;
|
||||
if (filter.size() > 0) {
|
||||
json_filter = parse_filter(filter.c_str());
|
||||
@@ -361,7 +264,7 @@ int main(int argc, char **argv) {
|
||||
its.push_back(std::move(t));
|
||||
}
|
||||
|
||||
out = overzoom(its, nz, nx, ny, detail, buffer, keep, exclude, exclude_prefix, do_compress, NULL, demultiply, json_filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, bins, bin_by_id_list, accumulate_numeric, SIZE_MAX, clipbboxes, deduplicate_by_id);
|
||||
out = overzoom(its, nz, nx, ny, detail, buffer, keep, exclude, exclude_prefix, do_compress, NULL, demultiply, json_filter, preserve_input_order, attribute_accum, unidecode_data, simplification, tiny_polygon_size, std::vector<mvt_layer>(), "", "", SIZE_MAX, std::vector<clipbbox>(), deduplicate_by_id);
|
||||
}
|
||||
|
||||
FILE *f = fopen(outfile, "wb");
|
||||
|
||||
@@ -6,7 +6,7 @@
|
||||
|
||||
#define MAX_MEMORY (1024 * 1024 * 1024) // 1 GB
|
||||
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem) {
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem, const char *tmpdir) {
|
||||
std::string pivot;
|
||||
FILE *fp1, *fp2;
|
||||
|
||||
@@ -67,8 +67,8 @@ void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *,
|
||||
size_t pivot_off = width * (buf.size() / width / 2);
|
||||
pivot = std::string(buf, pivot_off, width);
|
||||
|
||||
std::string t1 = "/tmp/sort1.XXXXXX";
|
||||
std::string t2 = "/tmp/sort2.XXXXXX";
|
||||
std::string t1 = std::string(tmpdir) + "/sort1.XXXXXX";
|
||||
std::string t2 = std::string(tmpdir) + "/sort2.XXXXXX";
|
||||
|
||||
int fd1 = mkstemp((char *) t1.c_str());
|
||||
unlink(t1.c_str());
|
||||
@@ -117,11 +117,11 @@ void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *,
|
||||
|
||||
std::vector<FILE *> v1;
|
||||
v1.emplace_back(fp1);
|
||||
fqsort(v1, width, cmp, out, mem);
|
||||
fqsort(v1, width, cmp, out, mem, tmpdir);
|
||||
fclose(fp1);
|
||||
|
||||
std::vector<FILE *> v2;
|
||||
v2.emplace_back(fp2);
|
||||
fqsort(v2, width, cmp, out, mem);
|
||||
fqsort(v2, width, cmp, out, mem, tmpdir);
|
||||
fclose(fp2);
|
||||
}
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
#ifndef SORT_HPP
|
||||
#define SORT_HPP
|
||||
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem);
|
||||
void fqsort(std::vector<FILE *> &inputs, size_t width, int (*cmp)(const void *, const void *), FILE *out, size_t mem, const char *tmpdir);
|
||||
|
||||
#endif
|
||||
|
||||
Binary file not shown.
@@ -0,0 +1,5 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "numeric-properties", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "byte_min": -128, "ubyte_max": 255, "bool_value": true, "short_min": -32768, "ushort_max": 65535, "int_min": -2147483648, "uint_max": 4294967295, "long_min": -9223372036854775808, "ulong_max": 18446744073709551615, "float_value": 1.25, "double_value": 12345.678901234, "guid_value": "123e4567-e89b-12d3-a456-426614174000" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
] }
|
||||
] }
|
||||
@@ -0,0 +1,2 @@
|
||||
{"type":"Feature","id":1,"tippecanoe":{"minzoom":10},"properties":{"depth":10},"geometry":{"type":"Point","coordinates":[0.05,0.05]}}
|
||||
{"type":"Feature","id":2,"tippecanoe":{"minzoom":11},"properties":{"depth":11},"geometry":{"type":"Point","coordinates":[0.06,0.06]}}
|
||||
+28
@@ -0,0 +1,28 @@
|
||||
{ "type": "FeatureCollection", "properties": {
|
||||
"antimeridian_adjusted_bounds": "0.050000,0.050000,0.060000,0.060000",
|
||||
"bounds": "0.050000,0.050000,0.060000,0.060000",
|
||||
"center": "0.060000,0.060000,11",
|
||||
"description": "tests/minzoom-variable-depth/out/-Z10_-z11_--generate-variable-depth-tile-pyramid.json.check.mbtiles",
|
||||
"format": "pbf",
|
||||
"generator_options": "./tippecanoe -q -a@ -f -o tests/minzoom-variable-depth/out/-Z10_-z11_--generate-variable-depth-tile-pyramid.json.check.mbtiles -Z10 -z11 --generate-variable-depth-tile-pyramid tests/minzoom-variable-depth/in.json",
|
||||
"json": "{\"vector_layers\":[{\"id\":\"in\",\"description\":\"\",\"minzoom\":10,\"maxzoom\":11,\"fields\":{\"depth\":\"Number\"}}],\"tilestats\":{\"layerCount\":1,\"layers\":[{\"layer\":\"in\",\"count\":2,\"geometry\":\"Point\",\"attributeCount\":1,\"attributes\":[{\"attribute\":\"depth\",\"count\":2,\"type\":\"number\",\"values\":[10,11],\"min\":10,\"max\":11}]}]}}",
|
||||
"maxzoom": "11",
|
||||
"minzoom": "10",
|
||||
"name": "tests/minzoom-variable-depth/out/-Z10_-z11_--generate-variable-depth-tile-pyramid.json.check.mbtiles",
|
||||
"type": "overlay",
|
||||
"version": "2"
|
||||
}, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 10, "x": 512, "y": 511 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "id": 1, "properties": { "depth": 10 }, "geometry": { "type": "Point", "coordinates": [ 0.050039, 0.049953 ] } }
|
||||
] }
|
||||
] }
|
||||
,
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 11, "x": 1024, "y": 1023 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "id": 1, "properties": { "depth": 10 }, "geometry": { "type": "Point", "coordinates": [ 0.049996, 0.049996 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 2, "properties": { "depth": 11 }, "geometry": { "type": "Point", "coordinates": [ 0.059996, 0.059996 ] } }
|
||||
] }
|
||||
] }
|
||||
] }
|
||||
+1817
File diff suppressed because it is too large
Load Diff
-1426
File diff suppressed because one or more lines are too long
@@ -1,21 +1,15 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "in", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 4, "NAME": "Castries" }, "geometry": { "type": "Point", "coordinates": [ -60.996094, 14.008696 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Reykjavík", "LATITUDE": 64.150024 }, "geometry": { "type": "Point", "coordinates": [ -21.884766, 64.129784 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Niamey" }, "geometry": { "type": "Point", "coordinates": [ 2.109375, 13.496473 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Astana", "LATITUDE": 51.181125 }, "geometry": { "type": "Point", "coordinates": [ 71.455078, 51.179343 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Wellington" }, "geometry": { "type": "MultiPoint", "coordinates": [ [ 174.814453, -41.310824 ], [ -185.273438, -41.310824 ] ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Yerevan", "LATITUDE": 40.181151 }, "geometry": { "type": "Point", "coordinates": [ 44.560547, 40.178873 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Sucre" }, "geometry": { "type": "Point", "coordinates": [ -65.214844, -19.062118 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 2, "NAME": "Oslo", "LATITUDE": 59.91669 }, "geometry": { "type": "Point", "coordinates": [ 10.810547, 59.888937 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 3, "NAME": "Hargeysa" }, "geometry": { "type": "Point", "coordinates": [ 44.121094, 9.535749 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vancouver", "LATITUDE": 49.273417 }, "geometry": { "type": "Point", "coordinates": [ -123.134766, 49.267805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Chengdu" }, "geometry": { "type": "Point", "coordinates": [ 104.062500, 30.675715 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vancouver" }, "geometry": { "type": "Point", "coordinates": [ -123.134766, 49.267805 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vienna" }, "geometry": { "type": "Point", "coordinates": [ 16.347656, 48.166085 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 0, "NAME": "Cape Town" }, "geometry": { "type": "Point", "coordinates": [ 18.457031, -33.943360 ] } }
|
||||
{ "type": "Feature", "properties": { "SCALERANK": 1, "NAME": "Vienna", "LATITUDE": 48.200015 }, "geometry": { "type": "Point", "coordinates": [ 16.347656, 48.166085 ] } }
|
||||
] }
|
||||
] }
|
||||
|
||||
+3
-3
@@ -1,3 +1,3 @@
|
||||
{"type":"Feature","properties":{"what":"no id"},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
{"type":"Feature","id":12345,"properties":{"what":"will survive"},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
{"type":"Feature","id":12346,"properties":{"what":"will win over the duplicate"},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
{"type":"Feature","properties":{"what":"no id"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12345,"properties":{"what":"will survive"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12346,"properties":{"what":"will win over the duplicate even though it's in another tile"},"geometry":{"type":"Point","coordinates":[-1,-1]}}
|
||||
|
||||
+3
-3
@@ -1,3 +1,3 @@
|
||||
{"type":"Feature","properties":{"what":"no id again"},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
{"type":"Feature","id":12346,"properties":{"what":"will be lost as a duplicate"},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
{"type":"Feature","id":12347,"properties":{"what":"will be added"},"geometry":{"type":"Point","coordinates":[0,0]}}
|
||||
{"type":"Feature","properties":{"what":"no id again"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12346,"properties":{"what":"will be lost as a duplicate"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
{"type":"Feature","id":12347,"properties":{"what":"will be added"},"geometry":{"type":"Point","coordinates":[1,1]}}
|
||||
|
||||
@@ -1,13 +1,11 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "layer", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "what": "no id" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "properties": { "what": "no id" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12345, "properties": { "what": "will survive" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "id": 12345, "properties": { "what": "will survive" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12346, "properties": { "what": "will win over the duplicate" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "properties": { "what": "no id again" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "what": "no id again" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12347, "properties": { "what": "will be added" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "id": 12347, "properties": { "what": "will be added" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
] }
|
||||
] }
|
||||
|
||||
@@ -1,15 +1,13 @@
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 0, "x": 0, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "zoom": 1, "x": 1, "y": 0 }, "features": [
|
||||
{ "type": "FeatureCollection", "properties": { "layer": "layer", "version": 2, "extent": 4096 }, "features": [
|
||||
{ "type": "Feature", "properties": { "what": "no id" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "properties": { "what": "no id" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12345, "properties": { "what": "will survive" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "id": 12345, "properties": { "what": "will survive" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12346, "properties": { "what": "will win over the duplicate" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "properties": { "what": "no id again" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "properties": { "what": "no id again" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "id": 12346, "properties": { "what": "will be lost as a duplicate" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12346, "properties": { "what": "will be lost as a duplicate" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
,
|
||||
{ "type": "Feature", "id": 12347, "properties": { "what": "will be added" }, "geometry": { "type": "Point", "coordinates": [ 0.000000, 0.000000 ] } }
|
||||
{ "type": "Feature", "id": 12347, "properties": { "what": "will be added" }, "geometry": { "type": "Point", "coordinates": [ 0.966797, 0.966751 ] } }
|
||||
] }
|
||||
] }
|
||||
|
||||
@@ -1 +1 @@
|
||||
{"*":["SCALERANK","eq",0]}
|
||||
{"*":["==","SCALERANK",0]}
|
||||
|
||||
+42
-211
@@ -56,12 +56,8 @@ int minzoom = 0;
|
||||
std::map<std::string, std::string> renames;
|
||||
bool exclude_all = false;
|
||||
bool exclude_all_tile_attributes = false;
|
||||
bool exclude_all_tile_geometries = false;
|
||||
std::vector<std::string> unidecode_data;
|
||||
std::string join_tile_attribute;
|
||||
std::string join_table_expression;
|
||||
std::string join_table;
|
||||
size_t join_count_limit = 1;
|
||||
std::string attribute_for_id;
|
||||
|
||||
bool want_overzoom = false;
|
||||
int buffer = 5;
|
||||
@@ -79,92 +75,6 @@ struct stats {
|
||||
std::vector<struct strategy> strategies{};
|
||||
};
|
||||
|
||||
// list, per feature in the tile,
|
||||
// of lists of features in the sqlite response,
|
||||
// each of which is a mapping from keys to values
|
||||
std::vector<std::vector<std::map<std::string, mvt_value>>> get_joined_rows(sqlite3 *db, const std::vector<mvt_value> &join_keys) {
|
||||
std::vector<std::vector<std::map<std::string, mvt_value>>> ret;
|
||||
ret.resize(join_keys.size());
|
||||
|
||||
// double quotes for table and column identifiers
|
||||
const char *s = sqlite3_mprintf("select %s, * from \"%w\" where %s in (",
|
||||
join_table_expression.c_str(), join_table.c_str(), join_table_expression.c_str());
|
||||
std::string query = s;
|
||||
sqlite3_free((void *) s);
|
||||
|
||||
std::multimap<std::string, size_t> key_to_row;
|
||||
for (size_t i = 0; i < join_keys.size(); i++) {
|
||||
const mvt_value &v = join_keys[i];
|
||||
|
||||
// single quotes for literals
|
||||
if (v.type == mvt_string) {
|
||||
s = sqlite3_mprintf("'%q'", v.c_str());
|
||||
query += s;
|
||||
sqlite3_free((void *) s);
|
||||
key_to_row.emplace(v.get_string_value(), i);
|
||||
} else {
|
||||
std::string stringified = v.toString();
|
||||
key_to_row.emplace(stringified, i);
|
||||
query += stringified;
|
||||
}
|
||||
|
||||
if (i + 1 < join_keys.size()) {
|
||||
query += ", ";
|
||||
}
|
||||
}
|
||||
|
||||
// this doesn't add a LIMIT to the query because our limit
|
||||
// is per tiled feature, not a limit on the entire query response.
|
||||
query += ");";
|
||||
|
||||
sqlite3_stmt *stmt;
|
||||
if (sqlite3_prepare_v2(db, query.c_str(), -1, &stmt, NULL) != SQLITE_OK) {
|
||||
fprintf(stderr, "sqlite3 query %s failed: %s\n", query.c_str(), sqlite3_errmsg(db));
|
||||
exit(EXIT_SQLITE);
|
||||
}
|
||||
while (sqlite3_step(stmt) == SQLITE_ROW) {
|
||||
int count = sqlite3_column_count(stmt);
|
||||
std::map<std::string, mvt_value> row;
|
||||
|
||||
if (count > 0) {
|
||||
// join key is 0th column of query
|
||||
std::string key = (const char *) sqlite3_column_text(stmt, 0);
|
||||
auto f = key_to_row.equal_range(key);
|
||||
if (f.first == f.second) {
|
||||
fprintf(stderr, "Unexpected join key: %s\n", key.c_str());
|
||||
continue;
|
||||
}
|
||||
|
||||
for (auto ff = f.first; ff != f.second; ++ff) {
|
||||
if (ret[ff->second].size() < join_count_limit) {
|
||||
for (int i = 1; i < count; i++) {
|
||||
int type = sqlite3_column_type(stmt, i);
|
||||
mvt_value v;
|
||||
v.type = mvt_null;
|
||||
|
||||
if (type == SQLITE_INTEGER || type == SQLITE_FLOAT) {
|
||||
v = mvt_value(sqlite3_column_double(stmt, i));
|
||||
} else if (type == SQLITE_TEXT || type == SQLITE_BLOB) {
|
||||
v.set_string_value((const char *) sqlite3_column_text(stmt, i));
|
||||
}
|
||||
|
||||
const char *name = sqlite3_column_name(stmt, i);
|
||||
row.emplace(name, v);
|
||||
}
|
||||
|
||||
ret[ff->second].push_back(row);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
if (sqlite3_finalize(stmt) != SQLITE_OK) {
|
||||
fprintf(stderr, "sqlite3 finalize failed: %s\n", sqlite3_errmsg(db));
|
||||
exit(EXIT_SQLITE);
|
||||
}
|
||||
|
||||
return ret;
|
||||
}
|
||||
|
||||
struct arg {
|
||||
std::map<zxy, std::vector<std::string>> inputs{};
|
||||
std::map<zxy, std::string> outputs{};
|
||||
@@ -187,7 +97,7 @@ struct arg {
|
||||
double minlon2, maxlon2;
|
||||
};
|
||||
|
||||
void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<std::string, layermap_entry> &layermap, std::vector<std::string> &header, std::map<std::string, std::vector<std::string>> &mapping, sqlite3 *db, std::set<std::string> &exclude, std::set<std::string> &include, std::set<std::string> &keep_layers, std::set<std::string> &remove_layers, int ifmatched, mvt_tile &outtile, json_object *filter, struct arg *a) {
|
||||
void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<std::string, layermap_entry> &layermap, std::vector<std::string> &header, std::map<std::string, std::vector<std::string>> &mapping, sqlite3 * /* db */, std::set<std::string> &exclude, std::set<std::string> &include, std::set<std::string> &keep_layers, std::set<std::string> &remove_layers, int ifmatched, mvt_tile &outtile, json_object *filter, struct arg *a) {
|
||||
mvt_tile tile;
|
||||
int features_added = 0;
|
||||
bool was_compressed;
|
||||
@@ -253,30 +163,6 @@ void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<st
|
||||
}
|
||||
}
|
||||
|
||||
std::vector<std::vector<std::map<std::string, mvt_value>>> joined;
|
||||
if (db != NULL) {
|
||||
// collect join keys for sql query
|
||||
|
||||
std::vector<mvt_value> join_keys;
|
||||
join_keys.resize(layer.features.size());
|
||||
|
||||
for (size_t f = 0; f < layer.features.size(); f++) {
|
||||
mvt_feature &feat = layer.features[f];
|
||||
join_keys[f].type = mvt_no_such_key;
|
||||
|
||||
for (size_t t = 0; t + 1 < feat.tags.size(); t += 2) {
|
||||
const std::string &key = layer.keys[feat.tags[t]];
|
||||
if (key == join_tile_attribute) {
|
||||
const mvt_value &val = layer.values[feat.tags[t + 1]];
|
||||
join_keys[f] = val;
|
||||
break;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
joined = get_joined_rows(db, join_keys);
|
||||
}
|
||||
|
||||
auto tilestats = layermap.find(layer.name);
|
||||
|
||||
long long minx = LLONG_MAX;
|
||||
@@ -306,47 +192,6 @@ void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<st
|
||||
std::vector<match> matches;
|
||||
bool matched = false;
|
||||
|
||||
// start filling out sql matches
|
||||
|
||||
if (f < joined.size()) {
|
||||
if (joined[f].size() > 0) {
|
||||
matched = true;
|
||||
}
|
||||
|
||||
for (auto const &joined_feature : joined[f]) {
|
||||
match m;
|
||||
m.has_id = feat.has_id;
|
||||
m.id = feat.id;
|
||||
|
||||
if (!exclude_all_tile_attributes) {
|
||||
for (size_t t = 0; t + 1 < feat.tags.size(); t += 2) {
|
||||
const std::string &key = layer.keys[feat.tags[t]];
|
||||
mvt_value &val = layer.values[feat.tags[t + 1]];
|
||||
serial_val sv = mvt_value_to_serial_val(val);
|
||||
|
||||
if (include.count(key) || (!exclude_all && exclude.count(key) == 0 && exclude_attributes.count(key) == 0)) {
|
||||
m.attributes.insert(std::pair<std::string, std::pair<mvt_value, serial_val>>(key, std::pair<mvt_value, serial_val>(val, sv)));
|
||||
m.key_order.push_back(key);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
for (auto const &kv : joined_feature) {
|
||||
if (kv.first == attribute_for_id) {
|
||||
m.has_id = true;
|
||||
m.id = mvt_value_to_long_long(kv.second);
|
||||
} else if (include.count(kv.first) || (!exclude_all && exclude.count(kv.first) == 0 && exclude_attributes.count(kv.first) == 0)) {
|
||||
if (kv.second.type != mvt_null) {
|
||||
m.attributes.insert(std::pair<std::string, std::pair<mvt_value, serial_val>>(kv.first, std::pair<mvt_value, serial_val>(kv.second, mvt_value_to_serial_val(kv.second))));
|
||||
m.key_order.push_back(kv.first);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
matches.push_back(m);
|
||||
}
|
||||
}
|
||||
|
||||
// look for csv matches and start filling them out
|
||||
|
||||
if (!matched) {
|
||||
@@ -479,42 +324,46 @@ void append_tile(std::string message, int z, unsigned x, unsigned y, std::map<st
|
||||
}
|
||||
}
|
||||
|
||||
outfeature.type = feat.type;
|
||||
outfeature.geometry = feat.geometry;
|
||||
if (exclude_all_tile_geometries) {
|
||||
outfeature.type = -1;
|
||||
} else {
|
||||
outfeature.type = feat.type;
|
||||
outfeature.geometry = feat.geometry;
|
||||
|
||||
if (layer.extent != outlayer.extent) {
|
||||
for (size_t i = 0; i < outfeature.geometry.size(); i++) {
|
||||
outfeature.geometry[i].x = outfeature.geometry[i].x * outlayer.extent / layer.extent;
|
||||
outfeature.geometry[i].y = outfeature.geometry[i].y * outlayer.extent / layer.extent;
|
||||
}
|
||||
}
|
||||
|
||||
for (auto const &g : outfeature.geometry) {
|
||||
if (g.op == mvt_moveto || g.op == mvt_lineto) {
|
||||
// pin to the tile extent, since we don't want bounds bigger than the earth
|
||||
long long gx = std::min((long long) outlayer.extent, std::max(0LL, g.x));
|
||||
long long gy = std::min((long long) outlayer.extent, std::max(0LL, g.y));
|
||||
|
||||
// to world scale
|
||||
gx = gx * (1LL << (32 - z)) / outlayer.extent;
|
||||
gy = gy * (1LL << (32 - z)) / outlayer.extent;
|
||||
|
||||
// to world offset
|
||||
gx += (1LL << (32 - z)) * x;
|
||||
gy += (1LL << (32 - z)) * y;
|
||||
|
||||
minx = std::min(minx, gx);
|
||||
miny = std::min(miny, gy);
|
||||
maxx = std::max(maxx, gx);
|
||||
maxy = std::max(maxy, gy);
|
||||
|
||||
// if in the western hemisphere, try shifting to east
|
||||
if (gx < (1LL << 31)) {
|
||||
gx += 1LL << 32;
|
||||
if (layer.extent != outlayer.extent) {
|
||||
for (size_t i = 0; i < outfeature.geometry.size(); i++) {
|
||||
outfeature.geometry[i].x = outfeature.geometry[i].x * outlayer.extent / layer.extent;
|
||||
outfeature.geometry[i].y = outfeature.geometry[i].y * outlayer.extent / layer.extent;
|
||||
}
|
||||
}
|
||||
|
||||
minx2 = std::min(minx2, gx);
|
||||
maxx2 = std::max(maxx2, gx);
|
||||
for (auto const &g : outfeature.geometry) {
|
||||
if (g.op == mvt_moveto || g.op == mvt_lineto) {
|
||||
// pin to the tile extent, since we don't want bounds bigger than the earth
|
||||
long long gx = std::min((long long) outlayer.extent, std::max(0LL, g.x));
|
||||
long long gy = std::min((long long) outlayer.extent, std::max(0LL, g.y));
|
||||
|
||||
// to world scale
|
||||
gx = gx * (1LL << (32 - z)) / outlayer.extent;
|
||||
gy = gy * (1LL << (32 - z)) / outlayer.extent;
|
||||
|
||||
// to world offset
|
||||
gx += (1LL << (32 - z)) * x;
|
||||
gy += (1LL << (32 - z)) * y;
|
||||
|
||||
minx = std::min(minx, gx);
|
||||
miny = std::min(miny, gy);
|
||||
maxx = std::max(maxx, gx);
|
||||
maxy = std::max(maxy, gy);
|
||||
|
||||
// if in the western hemisphere, try shifting to east
|
||||
if (gx < (1LL << 31)) {
|
||||
gx += 1LL << 32;
|
||||
}
|
||||
|
||||
minx2 = std::min(minx2, gx);
|
||||
maxx2 = std::max(maxx2, gx);
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1465,6 +1314,7 @@ int main(int argc, char **argv) {
|
||||
{"exclude-all", no_argument, 0, 'X'},
|
||||
{"include", required_argument, 0, 'y'},
|
||||
{"exclude-all-tile-attributes", no_argument, 0, '~'},
|
||||
{"exclude-all-tile-geometries", no_argument, 0, '~'},
|
||||
{"layer", required_argument, 0, 'l'},
|
||||
{"exclude-layer", required_argument, 0, 'L'},
|
||||
{"quiet", no_argument, 0, 'q'},
|
||||
@@ -1475,11 +1325,6 @@ int main(int argc, char **argv) {
|
||||
{"rename-layer", required_argument, 0, 'R'},
|
||||
{"read-from", required_argument, 0, 'r'},
|
||||
|
||||
{"join-sqlite", required_argument, 0, '~'},
|
||||
{"join-tile-attribute", required_argument, 0, '~'},
|
||||
{"join-table-expression", required_argument, 0, '~'},
|
||||
{"join-table", required_argument, 0, '~'},
|
||||
{"join-count-limit", required_argument, 0, '~'},
|
||||
{"use-attribute-for-id", required_argument, 0, '~'},
|
||||
|
||||
{"no-tile-size-limit", no_argument, &pk, 1},
|
||||
@@ -1666,24 +1511,10 @@ int main(int argc, char **argv) {
|
||||
max_tilestats_values = atoi(optarg);
|
||||
} else if (strcmp(opt, "unidecode-data") == 0) {
|
||||
unidecode_data = read_unidecode(optarg);
|
||||
} else if (strcmp(opt, "join-sqlite") == 0) {
|
||||
join_sqlite_fname = optarg;
|
||||
if (sqlite3_open(optarg, &db) != SQLITE_OK) {
|
||||
fprintf(stderr, "%s: %s\n", optarg, sqlite3_errmsg(db));
|
||||
exit(EXIT_SQLITE);
|
||||
}
|
||||
} else if (strcmp(opt, "join-table") == 0) {
|
||||
join_table = optarg;
|
||||
} else if (strcmp(opt, "join-table-expression") == 0) {
|
||||
join_table_expression = optarg;
|
||||
} else if (strcmp(opt, "join-tile-attribute") == 0) {
|
||||
join_tile_attribute = optarg;
|
||||
} else if (strcmp(opt, "use-attribute-for-id") == 0) {
|
||||
attribute_for_id = optarg;
|
||||
} else if (strcmp(opt, "exclude-all-tile-attributes") == 0) {
|
||||
exclude_all_tile_attributes = true;
|
||||
} else if (strcmp(opt, "join-count-limit") == 0) {
|
||||
join_count_limit = atoi(optarg);
|
||||
} else if (strcmp(opt, "exclude-all-tile-geometries") == 0) {
|
||||
exclude_all_tile_geometries = true;
|
||||
} else {
|
||||
fprintf(stderr, "%s: Unrecognized option --%s\n", argv[0], opt);
|
||||
exit(EXIT_ARGS);
|
||||
|
||||
@@ -825,6 +825,45 @@ static unsigned long long choose_mindrop_sequence(std::vector<unsigned long long
|
||||
return drop_sequences[ix];
|
||||
}
|
||||
|
||||
static double choose_minattribute(std::vector<double> &attribute_values, double f, double existing_attribute, bool descending) {
|
||||
if (attribute_values.size() == 0) {
|
||||
return existing_attribute;
|
||||
}
|
||||
|
||||
std::stable_sort(attribute_values.begin(), attribute_values.end());
|
||||
|
||||
if (descending) {
|
||||
// For descending: drop features > threshold, keep features <= threshold
|
||||
// ix points at the last value to keep
|
||||
size_t ix = (size_t)((attribute_values.size() - 1) * f);
|
||||
while (ix > 0 && attribute_values[ix] >= existing_attribute) {
|
||||
ix--;
|
||||
}
|
||||
|
||||
if (attribute_values[ix] >= existing_attribute) {
|
||||
return existing_attribute;
|
||||
}
|
||||
|
||||
return attribute_values[ix];
|
||||
} else {
|
||||
// For ascending: drop features < threshold, keep features >= threshold
|
||||
// ix points at the first value to keep
|
||||
size_t ix = (size_t)ceil((double)(attribute_values.size() - 1) * (1 - f));
|
||||
if (ix >= attribute_values.size()) {
|
||||
ix = attribute_values.size() - 1;
|
||||
}
|
||||
while (ix + 1 < attribute_values.size() && attribute_values[ix] <= existing_attribute) {
|
||||
ix++;
|
||||
}
|
||||
|
||||
if (attribute_values[ix] <= existing_attribute) {
|
||||
return existing_attribute;
|
||||
}
|
||||
|
||||
return attribute_values[ix];
|
||||
}
|
||||
}
|
||||
|
||||
static unsigned long long calculate_drop_sequence(serial_feature const &sf) {
|
||||
unsigned long long zoom = std::min(std::max((unsigned long long) sf.feature_minzoom, 0ULL), 31ULL);
|
||||
unsigned long long out = zoom << (64 - 5); // top bits are the zoom level: top-priority features are those that appear in the low zooms
|
||||
@@ -890,6 +929,10 @@ struct write_tile_args {
|
||||
long long minextent_out = 0;
|
||||
unsigned long long mindrop_sequence = 0;
|
||||
unsigned long long mindrop_sequence_out = 0;
|
||||
double minattribute = 0;
|
||||
double minattribute_out = 0;
|
||||
std::string const *drop_by_attribute_as_needed_attribute = NULL;
|
||||
bool drop_by_attribute_descending = false;
|
||||
size_t tile_size_out = 0;
|
||||
size_t feature_count_out = 0;
|
||||
const char *prefilter = NULL;
|
||||
@@ -1055,6 +1098,9 @@ static bool skip_next_feature(decompressor *geoms, std::atomic<long long> *geomp
|
||||
struct next_feature_state {
|
||||
unsigned long long previndex = 0;
|
||||
unsigned long long prev_not_dropped_index = 0;
|
||||
// set when a feature excluded by tippecanoe_minzoom first appears beyond the next
|
||||
// zoom, so variable-depth pyramids don't leaf above the feature's minzoom and prune it away
|
||||
bool minzoom_feature_pending = false;
|
||||
|
||||
std::vector<FILE *> deferrals;
|
||||
size_t which_deferral = 0;
|
||||
@@ -1242,6 +1288,9 @@ static serial_feature next_feature(decompressor *geoms, std::atomic<long long> *
|
||||
}
|
||||
|
||||
if (sf.tippecanoe_minzoom != -1 && z < sf.tippecanoe_minzoom) {
|
||||
// a leaf at z carries only z-visible content, so an excluded feature at
|
||||
// any deeper minzoom (even z + 1) must block leafing here
|
||||
next_feature_state.minzoom_feature_pending = true;
|
||||
continue;
|
||||
}
|
||||
if (sf.tippecanoe_maxzoom != -1 && z > sf.tippecanoe_maxzoom) {
|
||||
@@ -1562,11 +1611,8 @@ void promote_attribute_prefix(std::string const &key, std::string const &prefixe
|
||||
|
||||
// accumulate attribute values from sf onto p
|
||||
void preserve_attributes(std::unordered_map<std::string, attribute_op> const *attribute_accum, const serial_feature &sf, serial_feature &p, key_pool &key_pool) {
|
||||
std::string accumulate_numeric_colon = accumulate_numeric + ":";
|
||||
|
||||
for (size_t i = 0; i < sf.keys.size(); i++) {
|
||||
std::string key = sf.stringpool + sf.keys[i] + 1;
|
||||
int type = sf.stringpool[sf.values[i]];
|
||||
|
||||
auto f = attribute_accum->find(key);
|
||||
if (f != attribute_accum->end()) {
|
||||
@@ -1576,21 +1622,10 @@ void preserve_attributes(std::unordered_map<std::string, attribute_op> const *at
|
||||
|
||||
promote_attribute(key, p, key_pool);
|
||||
preserve_attribute(f->second, key, sv, p.full_keys, p.full_values, key_pool);
|
||||
} else if (type == mvt_double && accumulate_numeric.size() > 0 && !starts_with(key, accumulate_numeric_colon)) {
|
||||
for (auto const &operation : numeric_operations) {
|
||||
serial_val sv;
|
||||
sv.type = sf.stringpool[sf.values[i]];
|
||||
sv.s = sf.stringpool + sf.values[i] + 1;
|
||||
|
||||
std::string prefixed_key = accumulate_numeric + ":" + operation.first + ":" + key;
|
||||
promote_attribute_prefix(key, prefixed_key, p, key_pool);
|
||||
preserve_attribute(operation.second, prefixed_key, sv, p.full_keys, p.full_values, key_pool);
|
||||
}
|
||||
}
|
||||
}
|
||||
for (size_t i = 0; i < sf.full_keys.size(); i++) {
|
||||
const std::string key = *sf.full_keys[i];
|
||||
int type = sf.full_values[i].type;
|
||||
|
||||
auto f = attribute_accum->find(key);
|
||||
if (f != attribute_accum->end()) {
|
||||
@@ -1598,12 +1633,6 @@ void preserve_attributes(std::unordered_map<std::string, attribute_op> const *at
|
||||
|
||||
promote_attribute(key, p, key_pool); // promotes it in the target feature
|
||||
preserve_attribute(f->second, key, sv, p.full_keys, p.full_values, key_pool);
|
||||
} else if (type == mvt_double && accumulate_numeric.size() > 0 && !starts_with(key, accumulate_numeric_colon)) {
|
||||
for (auto const &operation : numeric_operations) {
|
||||
std::string prefixed_key = accumulate_numeric + ":" + operation.first + ":" + key;
|
||||
promote_attribute_prefix(key, prefixed_key, p, key_pool);
|
||||
preserve_attribute(operation.second, prefixed_key, sf.full_values[i], p.full_keys, p.full_values, key_pool);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1702,11 +1731,12 @@ void skip_tile(decompressor *geoms, std::atomic<long long> *geompos_in, bool com
|
||||
}
|
||||
}
|
||||
|
||||
long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, char *global_stringpool, int z, const unsigned tx, const unsigned ty, const int detail, int min_detail, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, compressor **geomfile, std::atomic<long long> *geompos, int minzoom, int maxzoom, double todo, std::atomic<long long> *along, long long alongminus, double gamma, int child_shards, long long *pool_off, unsigned *initial_x, unsigned *initial_y, std::atomic<int> *running, double simplification, std::vector<std::map<std::string, layermap_entry>> *layermaps, std::vector<std::vector<std::string>> *layer_unmaps, size_t tiling_seg, size_t pass, unsigned long long mingap, long long minextent, unsigned long long mindrop_sequence, const char *prefilter, const char *postfilter, json_object *filter, write_tile_args *arg, atomic_strategy *strategy_out, bool compressed_input, bool first_zoom, node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, std::vector<std::string> const &unidecode_data, long long estimated_complexity, std::set<zxy> &skip_children_out) {
|
||||
long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, char *global_stringpool, int z, const unsigned tx, const unsigned ty, const int detail, int min_detail, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, compressor **geomfile, std::atomic<long long> *geompos, int minzoom, int maxzoom, double todo, std::atomic<long long> *along, long long alongminus, double gamma, int child_shards, long long *pool_off, unsigned *initial_x, unsigned *initial_y, std::atomic<int> *running, double simplification, std::vector<std::map<std::string, layermap_entry>> *layermaps, std::vector<std::vector<std::string>> *layer_unmaps, size_t tiling_seg, size_t pass, unsigned long long mingap, long long minextent, unsigned long long mindrop_sequence, double minattribute, const char *prefilter, const char *postfilter, json_object *filter, write_tile_args *arg, atomic_strategy *strategy_out, bool compressed_input, bool first_zoom, node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, std::vector<std::string> const &unidecode_data, long long estimated_complexity, std::set<zxy> &skip_children_out) {
|
||||
double merge_fraction = 1;
|
||||
double mingap_fraction = 1;
|
||||
double minextent_fraction = 1;
|
||||
double mindrop_sequence_fraction = 1;
|
||||
double minattribute_fraction = 1;
|
||||
|
||||
static std::atomic<double> oprogress(0);
|
||||
long long og = *geompos_in;
|
||||
@@ -1780,6 +1810,8 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
size_t extents_increment = 1;
|
||||
std::vector<unsigned long long> drop_sequences;
|
||||
size_t drop_sequences_increment = 1;
|
||||
std::vector<double> attribute_values;
|
||||
size_t attribute_values_increment = 1;
|
||||
|
||||
double coalesced_area = 0;
|
||||
drawvec shared_nodes;
|
||||
@@ -2144,6 +2176,40 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
can_stop_early = false;
|
||||
continue;
|
||||
}
|
||||
} else if (additional[A_DROP_BY_ATTRIBUTE_AS_NEEDED]) {
|
||||
mvt_value attr_val = find_attribute_value(&sf, *arg->drop_by_attribute_as_needed_attribute);
|
||||
double attr_numeric = 0;
|
||||
bool attr_valid = false;
|
||||
|
||||
if (attr_val.type == mvt_double) {
|
||||
attr_numeric = attr_val.numeric_value.double_value;
|
||||
attr_valid = std::isfinite(attr_numeric);
|
||||
} else if (attr_val.type == mvt_float) {
|
||||
attr_numeric = attr_val.numeric_value.float_value;
|
||||
attr_valid = std::isfinite(attr_numeric);
|
||||
} else if (attr_val.type == mvt_int) {
|
||||
attr_numeric = attr_val.numeric_value.int_value;
|
||||
attr_valid = true;
|
||||
} else if (attr_val.type == mvt_uint) {
|
||||
attr_numeric = attr_val.numeric_value.uint_value;
|
||||
attr_valid = true;
|
||||
} else if (attr_val.type == mvt_sint) {
|
||||
attr_numeric = attr_val.numeric_value.sint_value;
|
||||
attr_valid = true;
|
||||
}
|
||||
|
||||
if (attr_valid) {
|
||||
add_sample_to(attribute_values, attr_numeric, attribute_values_increment, seq);
|
||||
bool should_drop = arg->drop_by_attribute_descending
|
||||
? (minattribute != HUGE_VAL && attr_numeric > minattribute)
|
||||
: (minattribute != -HUGE_VAL && attr_numeric < minattribute);
|
||||
if (should_drop) {
|
||||
can_stop_early = false;
|
||||
if (drop_feature_unless_it_can_be_added_to_a_multiplier_cluster(layer, sf, layer_unmaps, strategy, drop_rest, arg->attribute_accum, key_pool)) {
|
||||
continue;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
@@ -2340,7 +2406,7 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
if (within[j]) {
|
||||
long long estimated_complexity_out = geompos[j] - start_geompos[j];
|
||||
|
||||
if (dropping_by_rate) {
|
||||
if (dropping_by_rate || next_feature_state.minzoom_feature_pending) {
|
||||
// large enough to make it not try to stop early
|
||||
estimated_complexity_out = 1LL << 32;
|
||||
}
|
||||
@@ -2703,7 +2769,7 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
oprogress = progress;
|
||||
}
|
||||
|
||||
if (trying_to_stop_early && line_detail == first_detail && !can_stop_early) {
|
||||
if (trying_to_stop_early && line_detail == first_detail && (!can_stop_early || next_feature_state.minzoom_feature_pending)) {
|
||||
// didn't work, try a lower detail
|
||||
continue;
|
||||
}
|
||||
@@ -2797,6 +2863,45 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
fprintf(stderr, "Can't increase feature area threshold further\n");
|
||||
exit(EXIT_INCOMPLETE);
|
||||
}
|
||||
} else if (additional[A_DROP_BY_ATTRIBUTE_AS_NEEDED]) {
|
||||
minattribute_fraction = minattribute_fraction *
|
||||
adjusted_max_tile_features / adjusted_feature_count * 0.75;
|
||||
if (minattribute_fraction > 0.80) {
|
||||
if (!quiet) {
|
||||
fprintf(stderr,
|
||||
"Need to drop features, but calculated that we should keep %.1f%% of features\n",
|
||||
minattribute_fraction * 100.0);
|
||||
}
|
||||
minattribute_fraction = 0.80;
|
||||
}
|
||||
|
||||
bool desc = arg->drop_by_attribute_descending;
|
||||
if (attribute_values.empty() && !quiet) {
|
||||
fprintf(stderr, "Warning: no features had a numeric value for attribute '%s'\n",
|
||||
arg->drop_by_attribute_as_needed_attribute->c_str());
|
||||
}
|
||||
double m = choose_minattribute(attribute_values, minattribute_fraction, minattribute, desc);
|
||||
bool better = desc ? m < minattribute : m > minattribute;
|
||||
if (better) {
|
||||
minattribute = m;
|
||||
bool propagate = desc ? minattribute < arg->minattribute_out : minattribute > arg->minattribute_out;
|
||||
if (propagate) {
|
||||
arg->minattribute_out = minattribute;
|
||||
arg->still_dropping = true;
|
||||
}
|
||||
if (!quiet) {
|
||||
fprintf(stderr,
|
||||
"Trying to keep features with '%s' %s %.6f to make it fit\n",
|
||||
arg->drop_by_attribute_as_needed_attribute->c_str(),
|
||||
desc ? "<=" : ">=",
|
||||
minattribute);
|
||||
}
|
||||
line_detail++;
|
||||
continue;
|
||||
} else {
|
||||
fprintf(stderr, "Can't increase attribute threshold further\n");
|
||||
exit(EXIT_INCOMPLETE);
|
||||
}
|
||||
} else if (feature_count > layers.size() && (additional[A_DROP_FRACTION_AS_NEEDED] || additional[A_COALESCE_FRACTION_AS_NEEDED] || prevent[P_DYNAMIC_DROP])) {
|
||||
// The 95% is a guess to avoid too many retries
|
||||
// and probably actually varies based on how much duplicated metadata there is
|
||||
@@ -2934,6 +3039,37 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
fprintf(stderr, "Can't increase feature area threshold further\n");
|
||||
exit(EXIT_INCOMPLETE);
|
||||
}
|
||||
} else if (additional[A_DROP_BY_ATTRIBUTE_AS_NEEDED]) {
|
||||
minattribute_fraction = minattribute_fraction * adjusted_max_tile_size / adjusted_tile_size * 0.75;
|
||||
if (minattribute_fraction > 0.80) {
|
||||
if (!quiet) {
|
||||
fprintf(stderr, "Need to drop features, but calculated that we should keep %.1f%% of features\n", minattribute_fraction * 100.0);
|
||||
}
|
||||
minattribute_fraction = 0.80;
|
||||
}
|
||||
bool desc2 = arg->drop_by_attribute_descending;
|
||||
if (attribute_values.empty() && !quiet) {
|
||||
fprintf(stderr, "Warning: no features had a numeric value for attribute '%s'\n",
|
||||
arg->drop_by_attribute_as_needed_attribute->c_str());
|
||||
}
|
||||
double m = choose_minattribute(attribute_values, minattribute_fraction, minattribute, desc2);
|
||||
bool better2 = desc2 ? m < minattribute : m > minattribute;
|
||||
if (better2) {
|
||||
minattribute = m;
|
||||
bool propagate2 = desc2 ? minattribute < arg->minattribute_out : minattribute > arg->minattribute_out;
|
||||
if (propagate2) {
|
||||
arg->minattribute_out = minattribute;
|
||||
arg->still_dropping = true;
|
||||
}
|
||||
if (!quiet) {
|
||||
fprintf(stderr, "Going to try keeping features with attribute '%s' %s %0.6f to make it fit\n", arg->drop_by_attribute_as_needed_attribute->c_str(), desc2 ? "<=" : ">=", minattribute);
|
||||
}
|
||||
line_detail++;
|
||||
continue;
|
||||
} else {
|
||||
fprintf(stderr, "Can't increase attribute threshold further\n");
|
||||
exit(EXIT_INCOMPLETE);
|
||||
}
|
||||
} else if (feature_count > layers.size() && (additional[A_DROP_FRACTION_AS_NEEDED] || additional[A_COALESCE_FRACTION_AS_NEEDED] || prevent[P_DYNAMIC_DROP])) {
|
||||
mindrop_sequence_fraction = mindrop_sequence_fraction * adjusted_max_tile_size / adjusted_tile_size * 0.75;
|
||||
if (mindrop_sequence_fraction > 0.80) {
|
||||
@@ -2985,9 +3121,10 @@ long long write_tile(decompressor *geoms, std::atomic<long long> *geompos_in, ch
|
||||
exit(EXIT_PTHREAD);
|
||||
}
|
||||
|
||||
if (trying_to_stop_early && line_detail == first_detail) {
|
||||
// We succeeded in stopping early.
|
||||
// Prune the child tiles.
|
||||
if (trying_to_stop_early && line_detail == first_detail &&
|
||||
!next_feature_state.minzoom_feature_pending) {
|
||||
// We succeeded in stopping early (and no excluded feature is
|
||||
// waiting for a deeper zoom). Prune the child tiles.
|
||||
|
||||
strategy.truncated_zooms++;
|
||||
skip_children_out.insert(zxy(z, tx, ty));
|
||||
@@ -3102,7 +3239,7 @@ exit(EXIT_IMPOSSIBLE);
|
||||
len = 1;
|
||||
} else {
|
||||
arg->wrote_zoom = z;
|
||||
len = write_tile(&dc, &geompos, arg->global_stringpool, z, x, y, z == arg->maxzoom ? arg->full_detail : arg->low_detail, arg->min_detail, arg->outdb, arg->outdir, arg->buffer, arg->fname, arg->geomfile, arg->geompos, arg->minzoom, arg->maxzoom, arg->todo, arg->along, geompos, arg->gamma, arg->child_shards, arg->pool_off, arg->initial_x, arg->initial_y, arg->running, arg->simplification, arg->layermaps, arg->layer_unmaps, arg->tiling_seg, arg->pass, arg->mingap, arg->minextent, arg->mindrop_sequence, arg->prefilter, arg->postfilter, arg->filter, arg, arg->strategy, arg->compressed, arg->first_zoom, arg->shared_nodes_map, arg->nodepos, *(arg->shared_nodes_bloom), (*arg->unidecode_data), estimated_complexity, arg->skip_children_out);
|
||||
len = write_tile(&dc, &geompos, arg->global_stringpool, z, x, y, z == arg->maxzoom ? arg->full_detail : arg->low_detail, arg->min_detail, arg->outdb, arg->outdir, arg->buffer, arg->fname, arg->geomfile, arg->geompos, arg->minzoom, arg->maxzoom, arg->todo, arg->along, geompos, arg->gamma, arg->child_shards, arg->pool_off, arg->initial_x, arg->initial_y, arg->running, arg->simplification, arg->layermaps, arg->layer_unmaps, arg->tiling_seg, arg->pass, arg->mingap, arg->minextent, arg->mindrop_sequence, arg->minattribute, arg->prefilter, arg->postfilter, arg->filter, arg, arg->strategy, arg->compressed, arg->first_zoom, arg->shared_nodes_map, arg->nodepos, *(arg->shared_nodes_bloom), (*arg->unidecode_data), estimated_complexity, arg->skip_children_out);
|
||||
}
|
||||
|
||||
if (pthread_mutex_lock(&var_lock) != 0) {
|
||||
@@ -3168,7 +3305,7 @@ exit(EXIT_IMPOSSIBLE);
|
||||
return err_or_null;
|
||||
}
|
||||
|
||||
int traverse_zooms(int *geomfd, off_t *geom_size, char *global_stringpool, std::atomic<unsigned> *midx, std::atomic<unsigned> *midy, int &maxzoom, int minzoom, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, double gamma, int full_detail, int low_detail, int min_detail, long long *pool_off, unsigned *initial_x, unsigned *initial_y, double simplification, double maxzoom_simplification, std::vector<std::map<std::string, layermap_entry>> &layermaps, const char *prefilter, const char *postfilter, std::unordered_map<std::string, attribute_op> const *attribute_accum, json_object *filter, std::vector<strategy> &strategies, int iz, node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, int basezoom, double droprate, std::vector<std::string> const &unidecode_data) {
|
||||
int traverse_zooms(int *geomfd, off_t *geom_size, char *global_stringpool, std::atomic<unsigned> *midx, std::atomic<unsigned> *midy, int &maxzoom, int minzoom, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, double gamma, int full_detail, int low_detail, int min_detail, long long *pool_off, unsigned *initial_x, unsigned *initial_y, double simplification, double maxzoom_simplification, std::vector<std::map<std::string, layermap_entry>> &layermaps, const char *prefilter, const char *postfilter, std::unordered_map<std::string, attribute_op> const *attribute_accum, json_object *filter, std::vector<strategy> &strategies, int iz, node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, int basezoom, double droprate, std::vector<std::string> const &unidecode_data, std::string const *drop_by_attribute_as_needed_attribute, bool drop_by_attribute_descending) {
|
||||
last_progress = 0;
|
||||
|
||||
// The existing layermaps are one table per input thread.
|
||||
@@ -3283,6 +3420,7 @@ int traverse_zooms(int *geomfd, off_t *geom_size, char *global_stringpool, std::
|
||||
unsigned long long zoom_mingap = 0;
|
||||
long long zoom_minextent = 0;
|
||||
unsigned long long zoom_mindrop_sequence = 0;
|
||||
double zoom_minattribute = drop_by_attribute_descending ? HUGE_VAL : -HUGE_VAL;
|
||||
size_t zoom_tile_size = 0;
|
||||
size_t zoom_feature_count = 0;
|
||||
std::set<zxy> skip_children_out;
|
||||
@@ -3319,6 +3457,10 @@ int traverse_zooms(int *geomfd, off_t *geom_size, char *global_stringpool, std::
|
||||
args[thread].minextent_out = zoom_minextent;
|
||||
args[thread].mindrop_sequence = zoom_mindrop_sequence;
|
||||
args[thread].mindrop_sequence_out = zoom_mindrop_sequence;
|
||||
args[thread].minattribute = zoom_minattribute;
|
||||
args[thread].minattribute_out = zoom_minattribute;
|
||||
args[thread].drop_by_attribute_as_needed_attribute = drop_by_attribute_as_needed_attribute;
|
||||
args[thread].drop_by_attribute_descending = drop_by_attribute_descending;
|
||||
args[thread].tile_size_out = 0;
|
||||
args[thread].feature_count_out = 0;
|
||||
args[thread].child_shards = TEMP_FILES / threads;
|
||||
@@ -3406,6 +3548,13 @@ int traverse_zooms(int *geomfd, off_t *geom_size, char *global_stringpool, std::
|
||||
zoom_mindrop_sequence = args[thread].mindrop_sequence_out;
|
||||
again = true;
|
||||
}
|
||||
bool attr_propagate = drop_by_attribute_descending
|
||||
? args[thread].minattribute_out < zoom_minattribute
|
||||
: args[thread].minattribute_out > zoom_minattribute;
|
||||
if (attr_propagate) {
|
||||
zoom_minattribute = args[thread].minattribute_out;
|
||||
again = true;
|
||||
}
|
||||
if (args[thread].tile_size_out > zoom_tile_size) {
|
||||
zoom_tile_size = args[thread].tile_size_out;
|
||||
}
|
||||
|
||||
@@ -62,7 +62,7 @@ struct strategy {
|
||||
|
||||
// long long write_tile(char **geom, char *stringpool, unsigned *file_bbox, int z, unsigned x, unsigned y, int detail, int min_detail, int basezoom, sqlite3 *outdb, const char *outdir, double droprate, int buffer, const char *fname, FILE **geomfile, int file_minzoom, int file_maxzoom, double todo, char *geomstart, long long along, double gamma, int nlayers, std::atomic<strategy> *strategy);
|
||||
|
||||
int traverse_zooms(int *geomfd, off_t *geom_size, char *stringpool, std::atomic<unsigned> *midx, std::atomic<unsigned> *midy, int &maxzoom, int minzoom, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, double gamma, int full_detail, int low_detail, int min_detail, long long *pool_off, unsigned *initial_x, unsigned *initial_y, double simplification, double maxzoom_simplification, std::vector<std::map<std::string, layermap_entry> > &layermap, const char *prefilter, const char *postfilter, std::unordered_map<std::string, attribute_op> const *attribute_accum, struct json_object *filter, std::vector<strategy> &strategies, int iz, struct node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, int basezoom, double droprate, std::vector<std::string> const &unidecode_data);
|
||||
int traverse_zooms(int *geomfd, off_t *geom_size, char *stringpool, std::atomic<unsigned> *midx, std::atomic<unsigned> *midy, int &maxzoom, int minzoom, sqlite3 *outdb, const char *outdir, int buffer, const char *fname, double gamma, int full_detail, int low_detail, int min_detail, long long *pool_off, unsigned *initial_x, unsigned *initial_y, double simplification, double maxzoom_simplification, std::vector<std::map<std::string, layermap_entry> > &layermap, const char *prefilter, const char *postfilter, std::unordered_map<std::string, attribute_op> const *attribute_accum, struct json_object *filter, std::vector<strategy> &strategies, int iz, struct node *shared_nodes_map, size_t nodepos, std::string const &shared_nodes_bloom, int basezoom, double droprate, std::vector<std::string> const &unidecode_data, std::string const *drop_by_attribute_as_needed_attribute, bool drop_by_attribute_descending);
|
||||
|
||||
int manage_gap(unsigned long long index, unsigned long long *previndex, double scale, double gamma, double *gap);
|
||||
|
||||
|
||||
@@ -73,7 +73,7 @@ TEST_CASE("External quicksort", "fqsort") {
|
||||
unlink(tmpname.c_str());
|
||||
FILE *f = fdopen(fd, "w+b");
|
||||
|
||||
fqsort(inputs, sizeof(int), intcmp, f, 256);
|
||||
fqsort(inputs, sizeof(int), intcmp, f, 256, "/tmp");
|
||||
rewind(f);
|
||||
|
||||
int prev = INT_MIN;
|
||||
@@ -128,31 +128,6 @@ TEST_CASE("Bit reversal", "bit reversal") {
|
||||
REQUIRE(bit_reverse(0xF3D912481E6A2C48) == 0x1234567812489BCF);
|
||||
}
|
||||
|
||||
TEST_CASE("mvt_geometry bbox") {
|
||||
std::vector<mvt_geometry> geom;
|
||||
|
||||
geom.emplace_back(mvt_moveto, 128, 128);
|
||||
geom.emplace_back(mvt_lineto, 256, 256);
|
||||
|
||||
long long xmin, ymin, xmax, ymax;
|
||||
get_bbox(geom, &xmin, &ymin, &xmax, &ymax, 11, 327, 791, 9);
|
||||
|
||||
double lon, lat;
|
||||
tile2lonlat(xmin, ymin, 32, &lon, &lat);
|
||||
REQUIRE(std::to_string(lon) == "-122.475586");
|
||||
REQUIRE(std::to_string(lat) == "37.822802");
|
||||
|
||||
tile2lonlat(xmax, ymax, 32, &lon, &lat);
|
||||
REQUIRE(std::to_string(lon) == "-122.431641");
|
||||
REQUIRE(std::to_string(lat) == "37.788081");
|
||||
|
||||
unsigned long long start, end;
|
||||
get_quadkey_bounds(xmin, ymin, xmax, ymax, &start, &end);
|
||||
// 22 bits in common, for z11
|
||||
REQUIRE(start == 0x1c84fc0000000000);
|
||||
REQUIRE(end == 0x1c84ffffffffffff);
|
||||
}
|
||||
|
||||
TEST_CASE("line_is_too_small") {
|
||||
drawvec dv;
|
||||
dv.emplace_back(VT_MOVETO, 4243099709, 2683872952);
|
||||
|
||||
+1
-1
@@ -1,6 +1,6 @@
|
||||
#ifndef VERSION_HPP
|
||||
#define VERSION_HPP
|
||||
|
||||
#define VERSION "v2.79.0"
|
||||
#define VERSION "v2.81.0"
|
||||
|
||||
#endif
|
||||
|
||||
Reference in New Issue
Block a user